En 30 secondes
In this May 2023 video, Matthew Berman discusses research by Yu Takagi and Shinji Nishimoto using the Natural Scenes Dataset and Stable Diffusion to reconstruct images presented to people during fMRI scanning. He explains the visual and semantic components and compares examples in the paper. The researchers trained participant-specific linear mappings and evaluated reconstructions using similarity measures and human raters. Results are approximate, depend on the study’s data and methods, and do not establish general mind reading or prove that brains and diffusion models operate identically.
- 1A controlled visual taskParticipants viewed images during 7-tesla fMRI sessions; the method reconstructed approximate images from measured brain activity.
- 2Brain and model representationsThe researchers investigated statistical links between model features and visual cortex activity, not a demonstrated identity of the two systems.
- 3Four participants and trained mappingsThe study analyzed four participants who completed all scans and fitted separate linear models for each.
- 4How accuracy was assessedThe paper used perceptual-similarity metrics and six human raters in two-way identification tests.
- 5Visual, semantic and combined outputsThe paper contrasts reconstructions using visual representation z, text-related representation c and the combination; displayed examples have selection limits.
À retenir
- The study reconstructed approximations of viewed photographs from fMRI data, not arbitrary private thoughts.
- The analysis used four of eight dataset participants who completed all sessions, with separate trained mappings for each person.
- A pretrained Stable Diffusion model was reused, but linear regressions linking brain signals to model representations still required training.
- The combined visual and semantic representations generally improved reconstruction relative to either component alone in the paper’s evaluations.
- Some displayed examples were selected from five generated candidates using similarity to the original, so they are not an unbiased random sample.
- Links between model representations and brain activity do not establish that the two systems work the same way.
Lire le texte remanié, chapitre par chapitre
The reconstruction study
Berman introduces the paper and its examples. The controlled experiment reconstructs approximations of viewed images rather than reading unrestricted thoughts.
Matthew Berman introduces a study by Yu Takagi and Shinji Nishimoto that uses Stable Diffusion with functional MRI data to reconstruct images people viewed. He calls it mind reading, but the tested task is narrower: participants looked at photographs during controlled scans, and the system generated approximations from the resulting measurements. The work does not show that it can read arbitrary thoughts, memories or dreams.
Berman shows the paper’s examples, comparing original pictures with generated images such as a teddy bear. Some outputs preserve a recognizable subject or composition, while details and colors can differ substantially. These are generated reconstructions, not direct photographs taken from the brain; the diffusion model contributes prior knowledge learned during its own training.
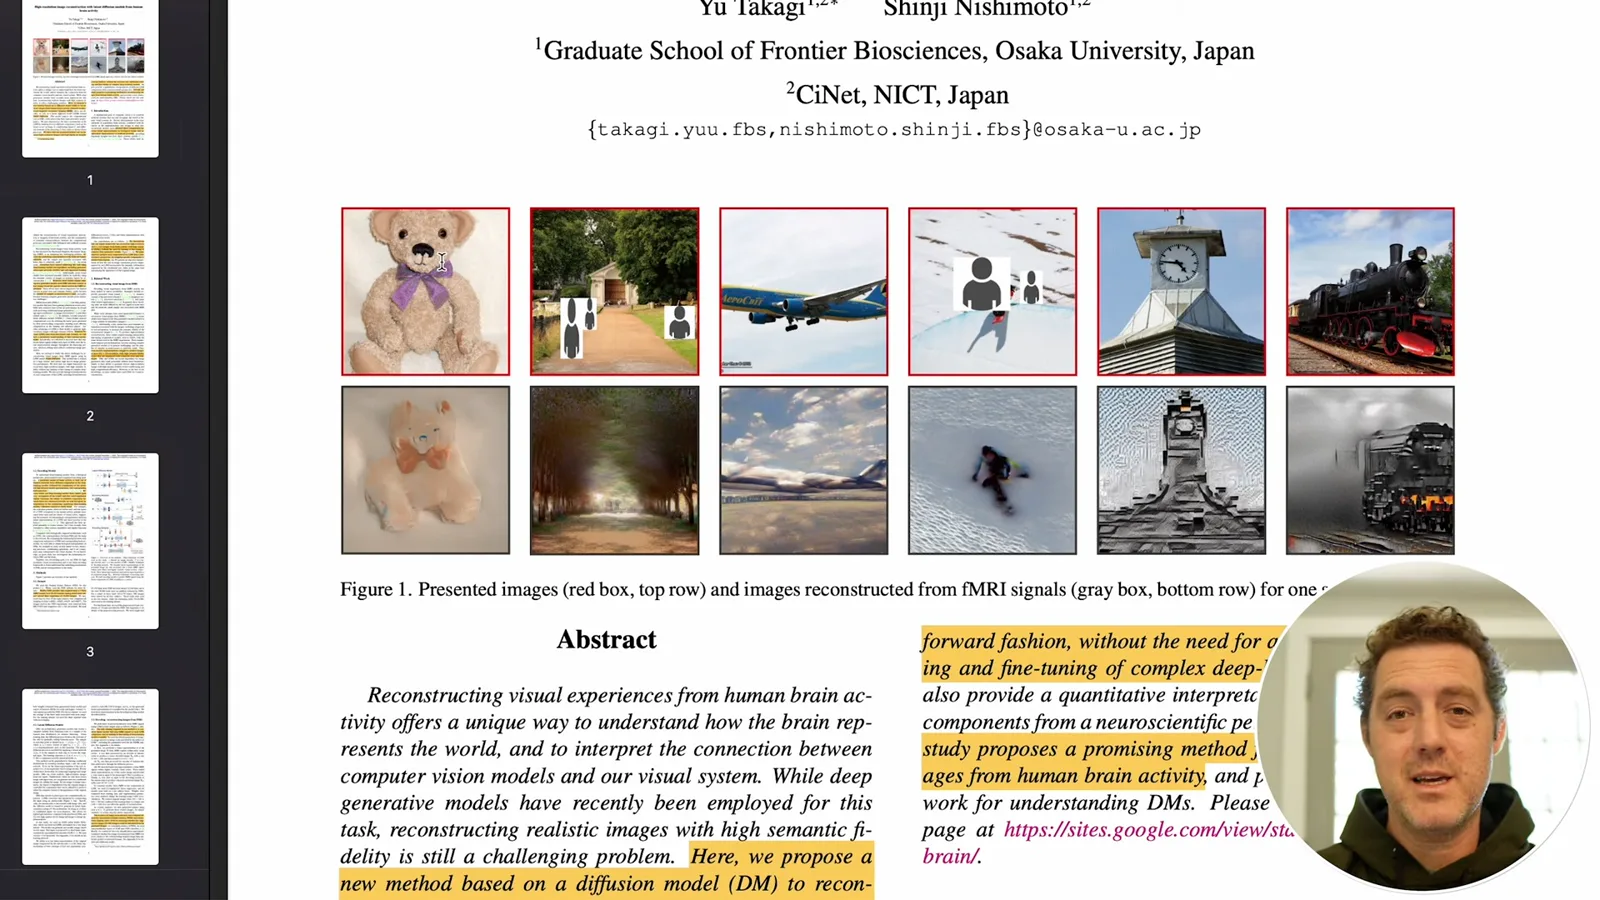
The [paper](https://openaccess.thecvf.com/content/CVPR2023/papers/Takagi_High-Resolution_Image_Reconstruction_With_Latent_Diffusion_Models_From_Human_Brain_CVPR_2023_paper.pdf) uses a pretrained Stable Diffusion latent diffusion model. The authors emphasize that they did not train or fine-tune a large generative network on the fMRI data. They did, however, train separate linear regression models to map each participant’s brain signals into model representations; the method was not training-free.
From brain activity to model representations
The paper links fMRI measurements to components of a pretrained diffusion model. Berman discusses possible correspondences, which are associations rather than proof of identical mechanisms.
Berman notes that visual representations in the brain and internal representations in deep models are difficult to interpret. Earlier image-reconstruction approaches often involved training or fine-tuning complex generators on limited neural datasets. The authors’ approach instead reuses a pretrained model and learns simpler mappings from scans, while still relying on extensive prior image-model training and a large, carefully collected brain dataset.
The paper also compares model features with brain activity to investigate possible relationships between the representations. Berman describes the brain and artificial networks as working similarly, but the study’s measured statistical correspondences do not establish that their mechanisms are the same. Such associations can provide hypotheses about visual processing without fully explaining either system.
Data and evaluation
The researchers use scans from four participants and fit participant-specific linear models. They compare outputs through perceptual measures and human two-way identification.
The researchers used the Natural Scenes Dataset, collected with a 7-tesla fMRI scanner over 30–40 sessions while participants repeatedly viewed thousands of natural images. The paper analyzed four of the eight participants who completed all sessions. For each participant it used 24,980 training trials and a shared test set of 982 images across 2,770 trials, averaging repeated test responses. These individualized data requirements limit conclusions about use with a new person.
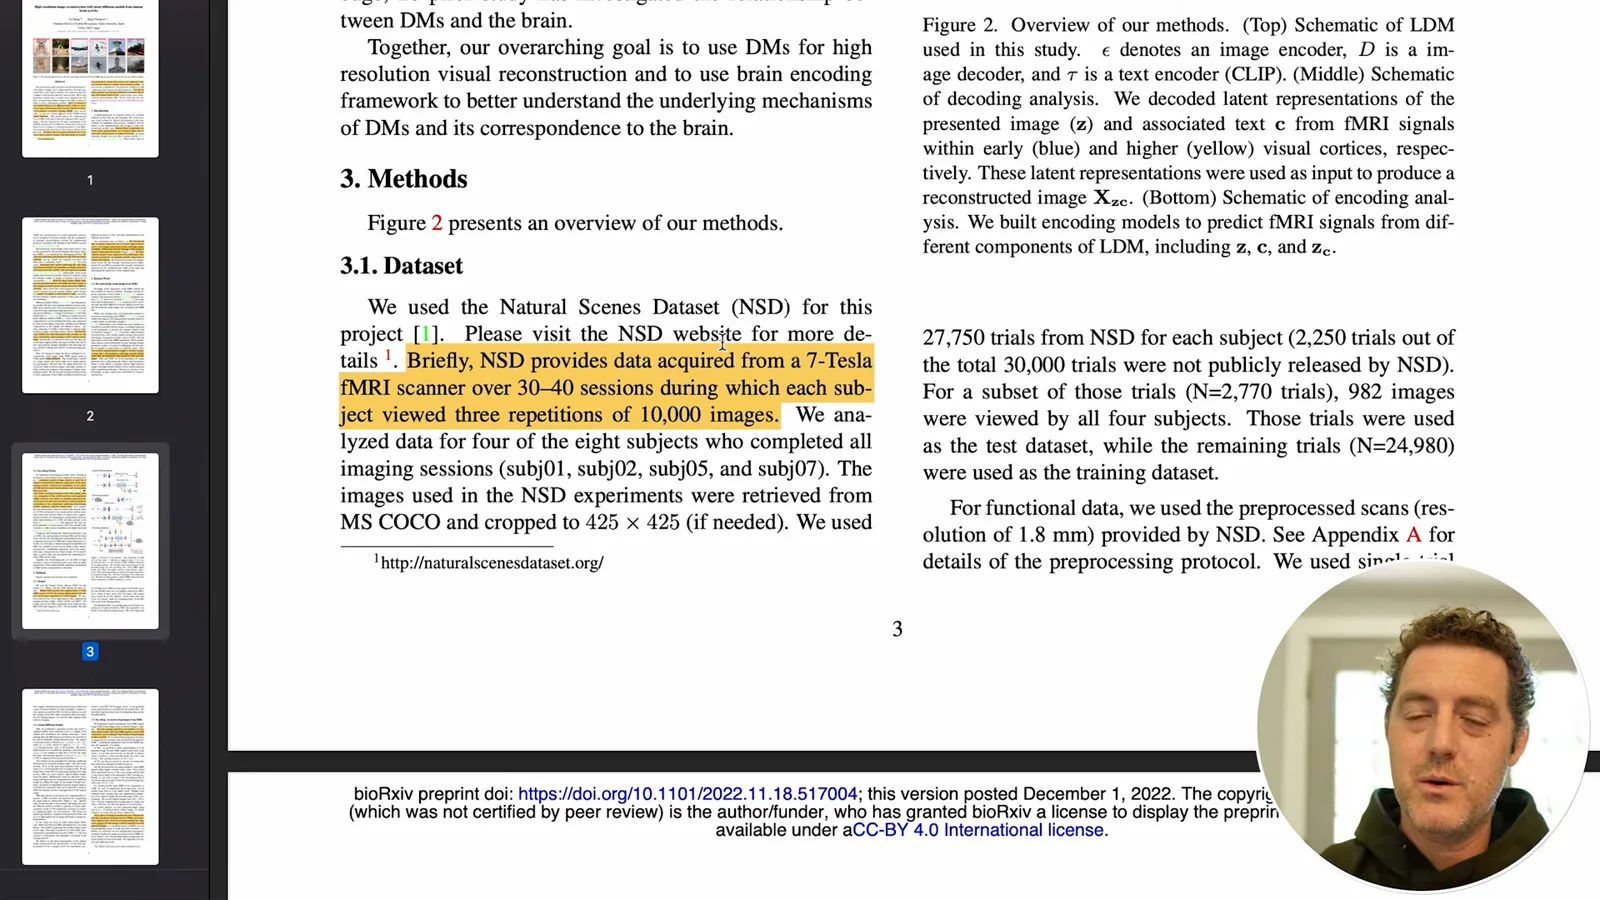
The authors fitted regularized linear models separately for each participant. One maps early visual-cortex signals to an image-related latent representation, z; another maps higher visual-cortex signals to a text-related semantic representation, c, learned using image annotations during training. The decoded representations guide the pretrained generator to produce a 512-by-512 image. No original test caption is directly supplied as the reconstruction prompt in this described decoding pipeline.
The researchers evaluated the 982 test images with perceptual-similarity metrics and six human raters. Their two-way identification tests ask whether a reconstruction matches the correct original more closely than a randomly selected alternative. Such a score is specific to that identification setup, not the percentage of all pixels recovered or the probability of reading an arbitrary thought.
Comparing reconstruction components
Examples contrast visual-only, semantic-only and combined reconstructions. The images show imperfect recoveries, and some displayed results were selected from multiple candidates.
Berman compares three columns of examples: z alone tends to preserve coarse visual layout but can miss the object’s identity; c alone often suggests the right subject while differing in appearance; the combined z-and-c result can capture more of both. A train, teddy bear, clock tower and skier illustrate the trade-off, but the generated details are not exact copies.
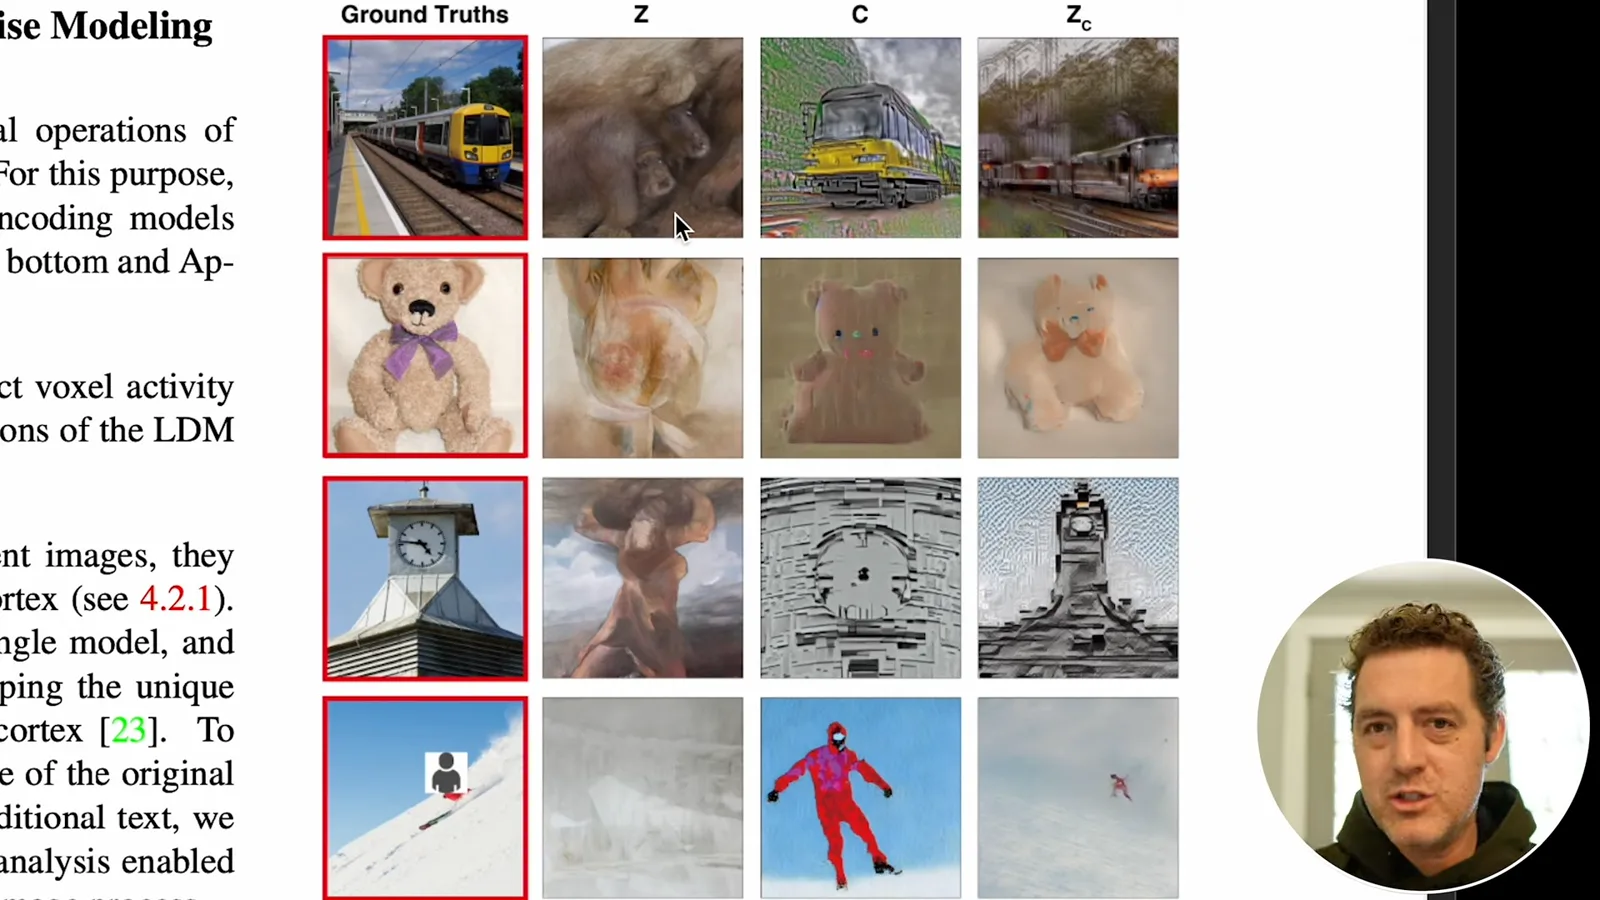
The paper also shows reconstructions for multiple participants, with quality varying between people and images. For the highlighted figure comparing components, the researchers generated five candidates per test image and selected those with the highest perceptual similarity, so those examples should not be interpreted as randomly selected or typical single-run outputs. Berman views the work as a step toward interpreting fMRI signals; the evidence supports reconstruction in this controlled setting, not unrestricted access to a person’s mind.
Sur la même chaîne
 34:21EN
 Matthew Berman· 27 oct. 2026Matthew Berman Examines Anthropic’s IPO Filing, AI Growth and GovernanceMatthew Berman, Sam Altman · Forward FutureThe presenter reviews the S-1’s financial metrics, compute strategy and voting structure while questioning the tension between rapid AI development and safety.
 0:26ENMatthew Berman· 25 oct. 2026Sam Altman on Human Values and Problem-Solving in an AI WorldSam Altman · OpenAIIn a short interview excerpt, Altman considers the enjoyment of solving hard problems and the human role in interpreting results.
 0:36ENMatthew Berman· 25 oct. 2026Kimi K3.1 and a Rubik’s Cube Solver DemonstrationMatthew Berman · Forward FutureMatthew Berman shows a scrambled virtual cube being solved and gives the Kimi K3.1 test a favorable assessment.
 0:21ENMatthew Berman· 24 oct. 2026An AI-Generated Kimi Benchmark Chart Used Invented ScoresMatthew Berman · Forward FutureMatthew Berman asks for a graph of Kimi K3.1 Pro benchmarks, then discovers that the displayed figures are illustrative placeholders.
 25:50ENMatthew Berman· 24 oct. 2026Kimi K3.1 Pro Tested: Strong 3D Demos, Uneven Results and Competitive PricingMatthew Berman · Forward FutureMatthew Berman tests the open-weight model on coding, 3D rendering and visual explanations, then compares benchmark results and prices.
 32:20ENMatthew Berman· 23 oct. 2026Who Is Local AI For? The Costs, Trade-offs and a Hybrid FutureMatthew Berman · Forward FutureMatthew Berman weighs data control and independence against hardware cost, setup complexity and inference speed.