En 30 secondes
In this 2023 tutorial, Matthew Berman demonstrates the Dalai tool for running early LLaMA and Stanford Alpaca models locally. He covers installation, starting a local server and changing generation settings. The commands and model availability are historical and may no longer work as shown. Stanford's reported sub-$600 cost covered generating instruction data and fine-tuning an existing LLaMA 7B model, not pretraining it from scratch. Its preliminary comparison with text-davinci-003 was limited in scope and did not establish parity with ChatGPT or GPT-4.
- 1A small instruction-tuned modelBerman introduces Stanford Alpaca as a derivative of Meta's LLaMA 7B. Stanford's reported cost covers data generation and fine-tuning, not the original pretraining.
- 2Historical local setupHe installs Dalai and model files, then starts a local server. Tools, downloads and license terms may differ today.
- 3Output lengthA response stops at the n_predict limit, so Berman raises it to allow a longer answer.
- 4Cost comparison needs contextBerman compares Alpaca's reported cost with GPT-3 training. The numbers cover different stages and do not establish equal capability or equivalent total training cost.
À retenir
- Alpaca 7B was fine-tuned from LLaMA 7B using 52,000 instruction examples generated with text-davinci-003.
- The reported sub-$600 reproduction cost excluded the cost of pretraining LLaMA and should not be compared as a like-for-like full training cost.
- The video demonstrates a historical Dalai setup with Node.js, model downloads and a local server on a MacBook Air.
- The n_predict setting limits output tokens; increasing it can prevent a response from stopping at that limit.
- The original LLaMA and Alpaca releases carried non-commercial research restrictions and the setup is a historical example.
Lire le texte remanié, chapitre par chapitre
Alpaca and its training recipe
Berman introduces Stanford's instruction-tuned model and its relation to LLaMA. The reported cost and model comparison require the scope of Stanford's preliminary experiment.
Stanford's Alpaca is an instruction-tuned model based on Meta's LLaMA 7B. In this 2023 demonstration, I run LLaMA and Alpaca locally on a MacBook Air using a tool called Dalai. The original models had research and non-commercial restrictions, and today's installation experience may be different.
Stanford reported that Alpaca behaved qualitatively similarly to text-davinci-003 in a preliminary single-turn instruction evaluation. Berman is impressed by the model's size and cost, while saying his own tests did not put it on par with GPT-4. That limited comparison does not establish broad equivalence to ChatGPT or GPT-4.
The often-cited cost below $600 is not the price of training the whole model from scratch. Stanford reported spending less than $500 on API-generated examples and under $100 on the initial fine-tuning run, using an already pretrained LLaMA 7B model. Its base-model pretraining cost is not included.
Stanford started with 175 human-written instruction-output pairs from the Self-Instruct seed set and used text-davinci-003 to generate roughly 52,000 examples. Those examples were used to fine-tune LLaMA 7B. Berman points viewers to the Stanford announcement and notes that its public demo was no longer available when he recorded the video.
Installing and running Dalai
He demonstrates a historical Node.js and Dalai installation, model downloads and a local server. The software and availability may have changed.
The tutorial uses the Dalai repository by cocktailpeanut. Berman says Node.js 18 or later is needed and demonstrates installing the package, then downloading LLaMA 7B and 13B and Alpaca 7B. He already has the models and cancels repeated downloads; one need not install both LLaMA sizes to follow the example.
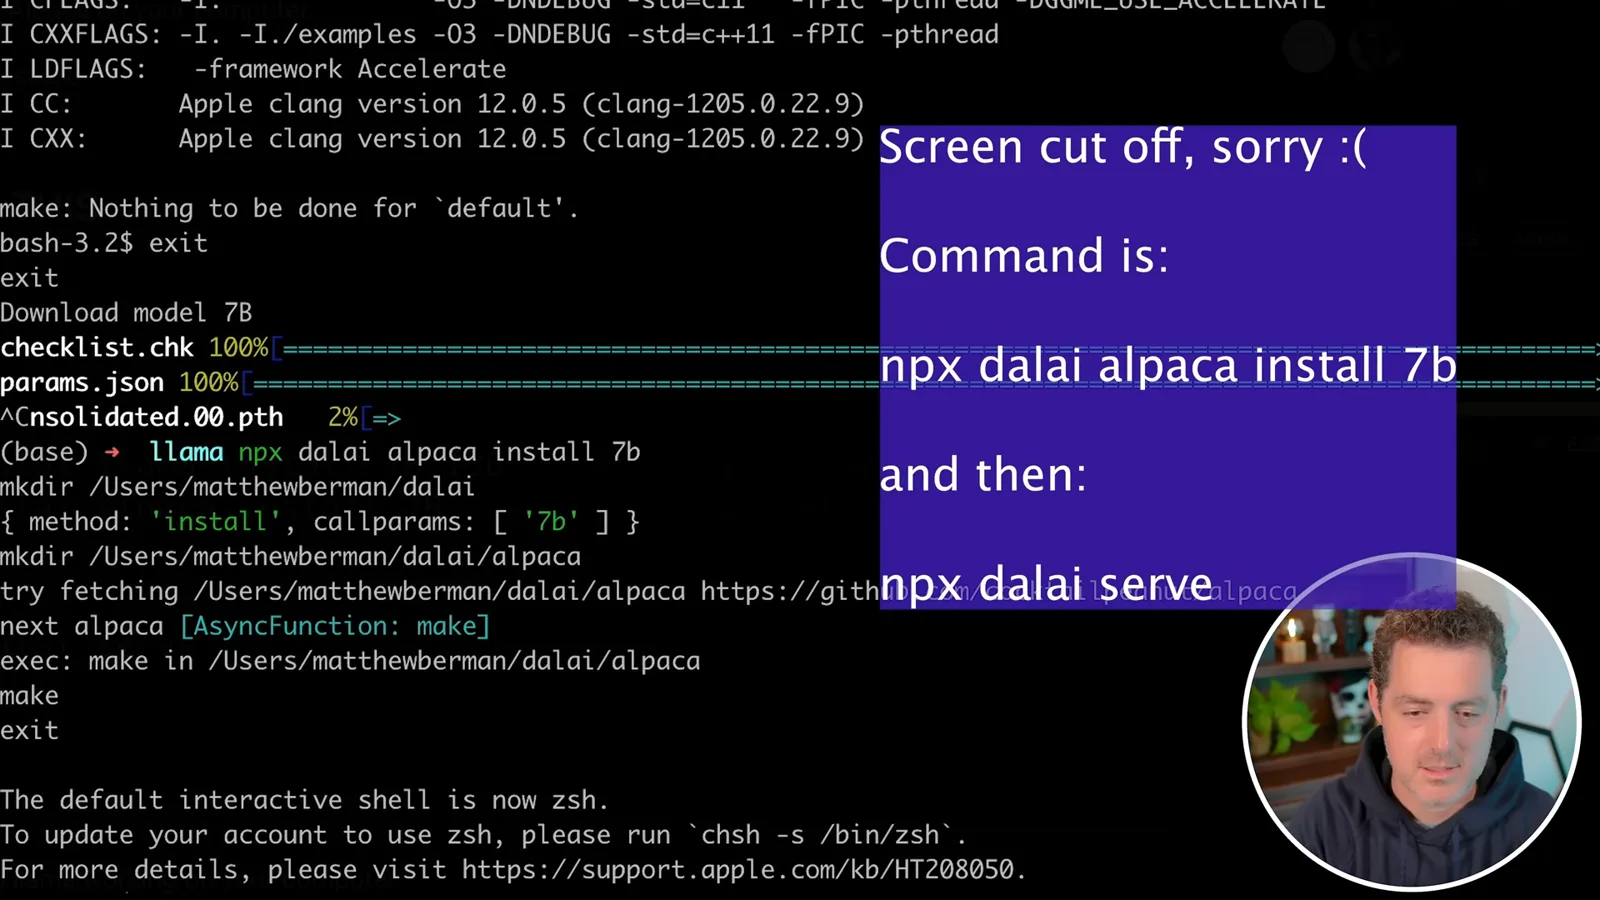
Once the model files are in place, Berman starts the local server with `npx dalai serve` and opens its local interface. He selects a model and asks how llamas and alpacas are related. These are the commands and interfaces shown in the 2023 video, not a guarantee of a currently supported setup.
Generation settings and cost claims
Berman adjusts the output length, describes other settings and discusses the falling cost of models. His cost comparison omits the base model's pretraining.
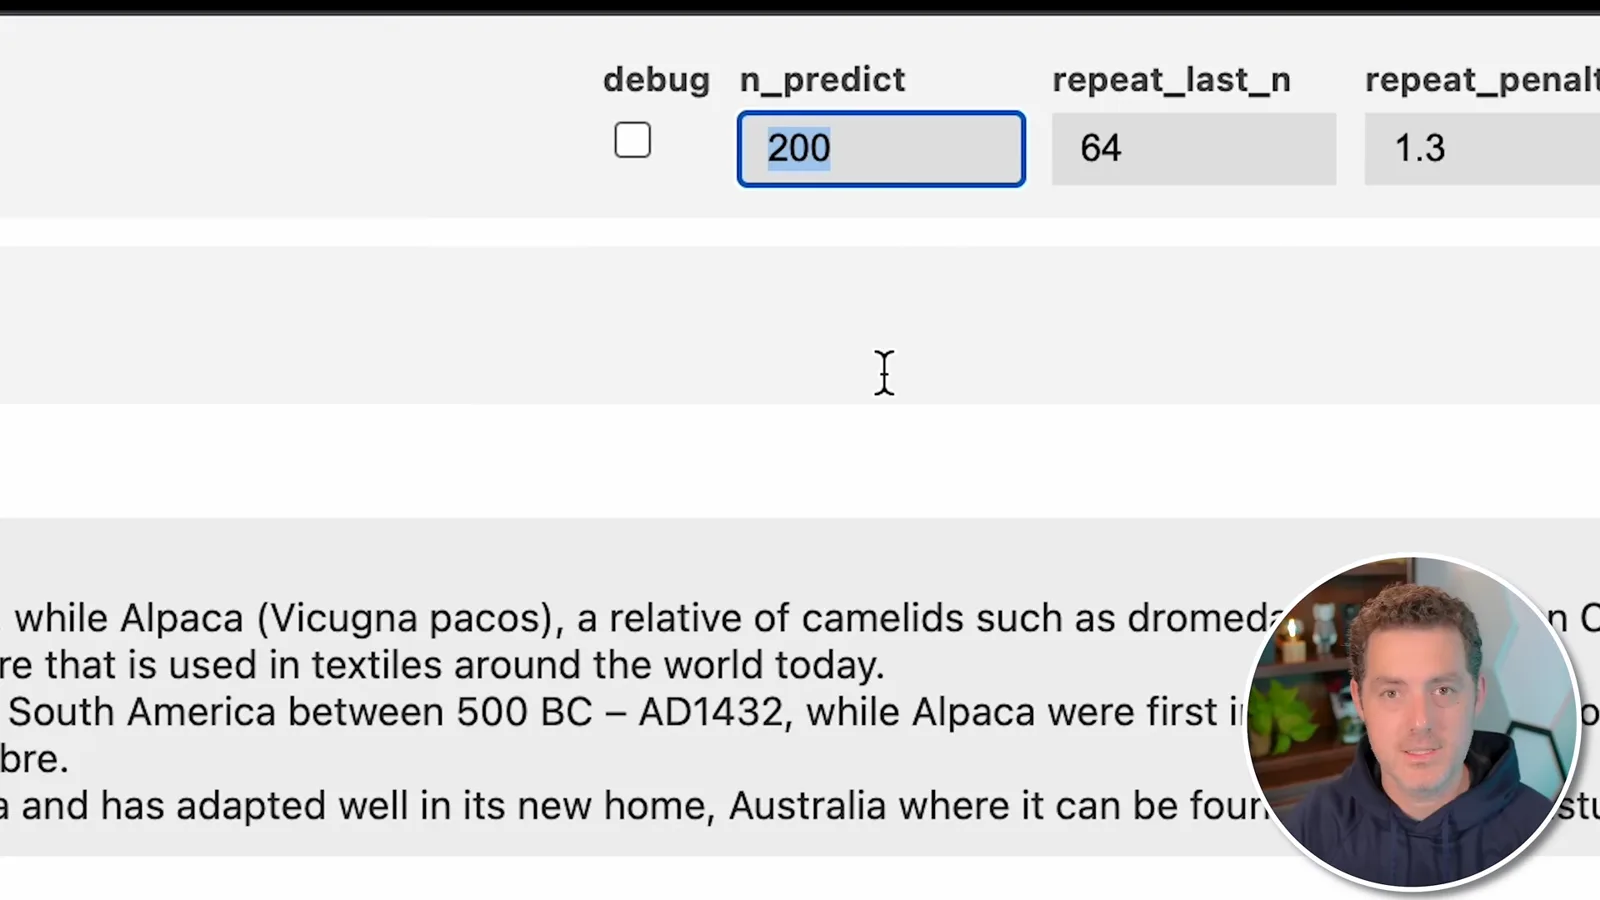
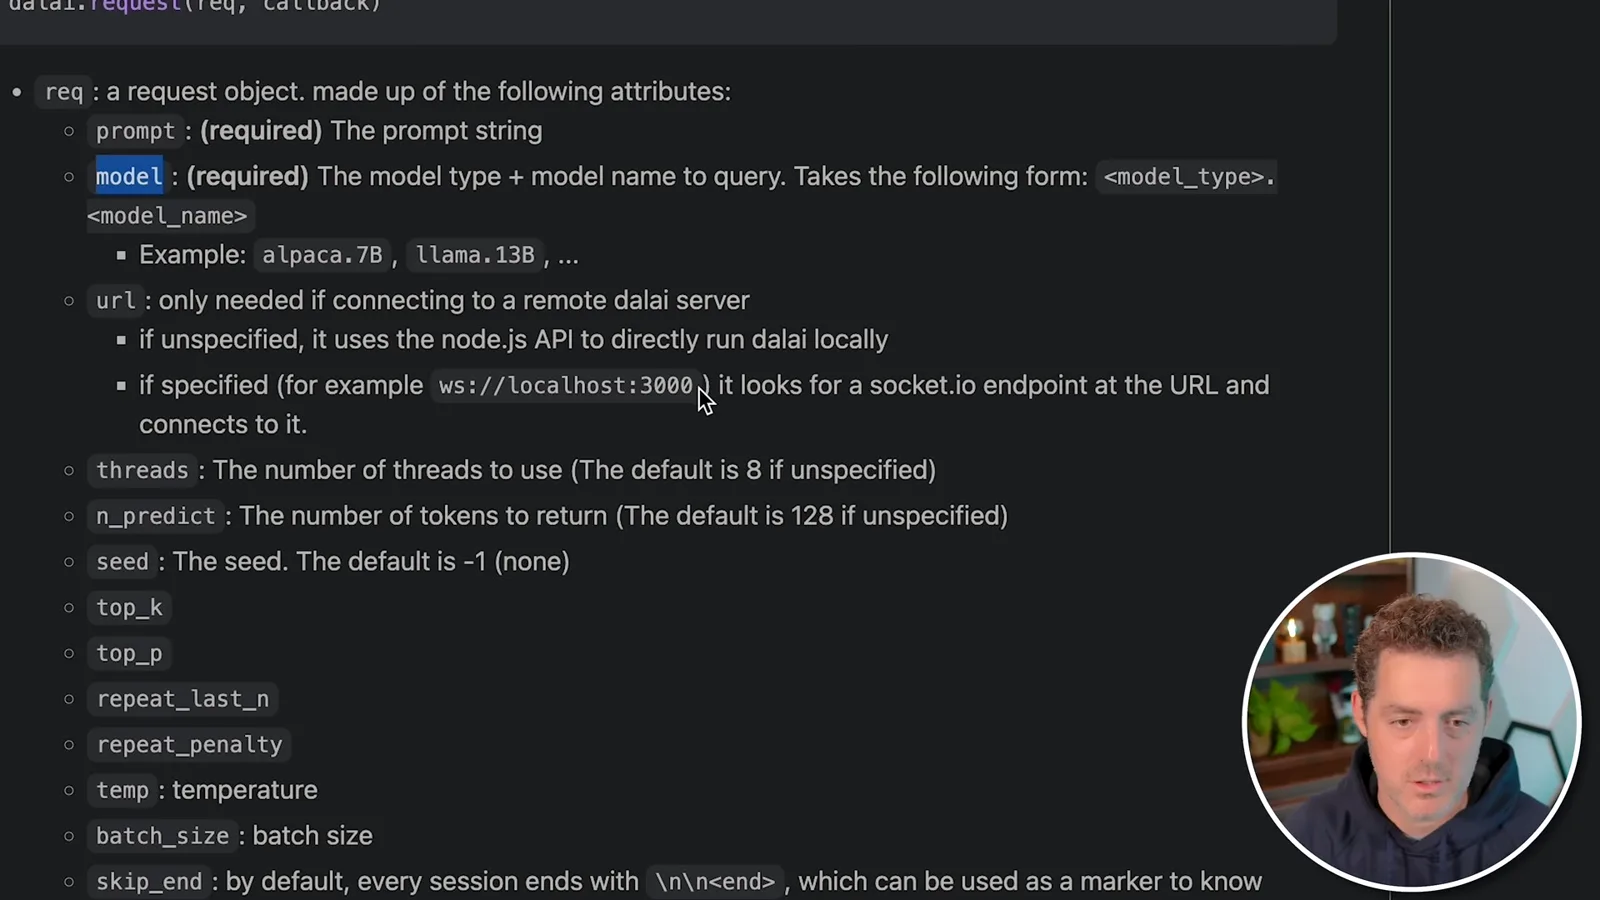
The answer stops when it reaches the `n_predict` limit of 200 tokens. Increasing the setting allows a longer response. The interface also offers a model selector, an optional remote server URL, a thread count, a seed and a temperature setting that affects variation in the output.
Berman cites a prediction that AI training costs would fall rapidly and compares the cost of GPT-3 with Alpaca's reported cost. Those figures are not directly comparable: Alpaca's number covers data generation and fine-tuning on an existing pretrained model, and the preliminary evaluation does not prove equivalent performance. He closes excited about trying more models locally and comparing their strengths.
Sur la même chaîne
 14:45EN
 Matthew Berman· 29 oct. 2026Matthew Berman Examines Google’s Gemini 4 Carbon AnnouncementMatthew Berman · Forward FutureMatthew Berman reviews Google’s reported benchmark results, staged rollout and pricing for Gemini 4 Carbon, while noting he has not yet used the model.
 21:11ENMatthew Berman· 28 oct. 2026Matthew Berman tests DeepSeek V4.1 Flash: coding, vision and local appsMatthew Berman · Forward FutureA hands-on tour of visual coding, image reasoning, local applications and provider economics reveals both impressive results and visible flaws.
 34:21ENMatthew Berman· 27 oct. 2026Matthew Berman Examines Anthropic’s IPO Filing, AI Growth and GovernanceMatthew Berman, Sam Altman · Forward FutureThe presenter reviews the S-1’s financial metrics, compute strategy and voting structure while questioning the tension between rapid AI development and safety.
 0:26ENMatthew Berman· 25 oct. 2026Sam Altman on Human Values and Problem-Solving in an AI WorldSam Altman · OpenAIIn a short interview excerpt, Altman considers the enjoyment of solving hard problems and the human role in interpreting results.
 0:36ENMatthew Berman· 25 oct. 2026Kimi K3.1 and a Rubik’s Cube Solver DemonstrationMatthew Berman · Forward FutureMatthew Berman shows a scrambled virtual cube being solved and gives the Kimi K3.1 test a favorable assessment.
 0:21ENMatthew Berman· 24 oct. 2026An AI-Generated Kimi Benchmark Chart Used Invented ScoresMatthew Berman · Forward FutureMatthew Berman asks for a graph of Kimi K3.1 Pro benchmarks, then discovers that the displayed figures are illustrative placeholders.