En 30 secondes
In this November 2023 video, Matthew Berman tests DeepSeek Coder through its website. He finds it useful for several coding exercises, including a playable Snake game, but it fails his bug-finding challenge; the contact form also requires follow-up fixes before it works. The benchmark comparisons and model availability he discusses describe that historical release, not a current ranking.
- 1A historical model comparisonBerman introduces DeepSeek Coder and shows the developer's benchmark chart, which compares it with contemporary open and closed models. These are reported benchmark results, not independent proof of a current ranking.
- 2A form needs repairsThe generated Flask form eventually saves a submission to SQLite, but only after Berman addresses a missing table and other setup errors.
- 3Bug finding failsOn a separate exercise, the model says it sees no obvious bugs and repeats suggestions; Berman marks the result a failure.
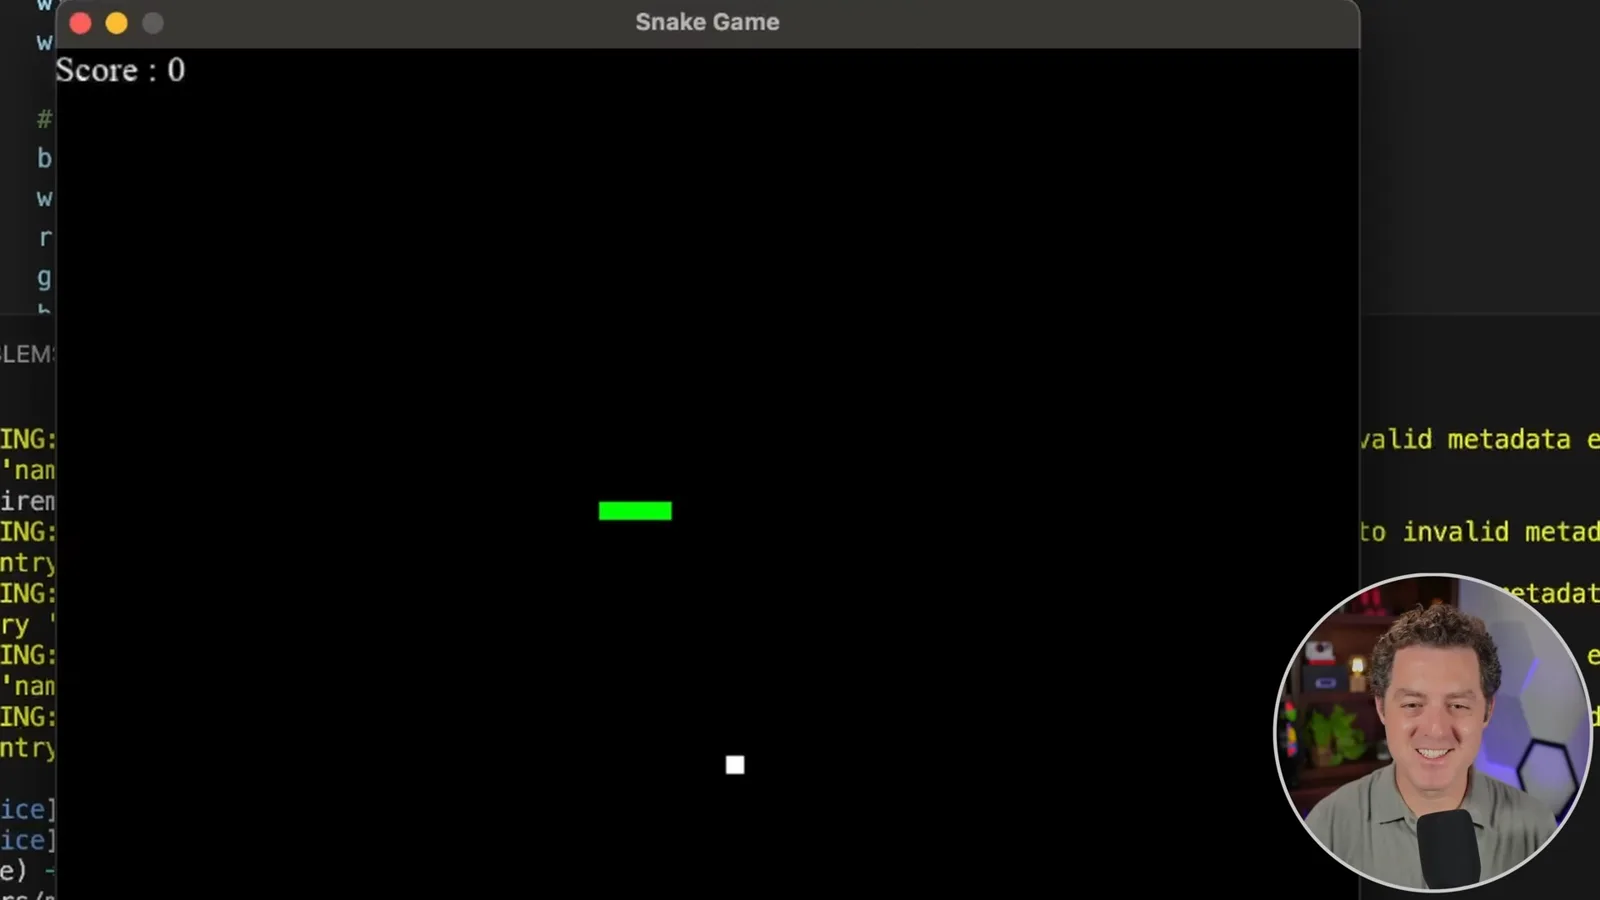
- 4Snake works on the first attemptAfter installing Pygame, Berman runs the generated game and reports working controls, scoring and game-over behavior.
À retenir
- The model produced the requested JSON and a working Snake game in Berman's demonstrations.
- The Flask contact form needed database initialization and troubleshooting before it saved a submission.
- The unit-test exercise required follow-up prompts to create an implementation and connect the tests to it.
- The model failed Berman's bug-finding exercise, although it passed the Set-game challenge after a JavaScript clarification.
- A small, informal rubric provides useful examples but cannot establish overall model superiority.
Lire le texte remanié, chapitre par chapitre
The model and the rubric
Berman introduces a coding-specific rubric and the model's reported training and benchmark results. He tests it through its website.
DeepSeek Coder's developers present it as a strong open coding model, with reported benchmark performance close to GPT-4. I want to see how it does on a new coding rubric. This is an informal set of exercises I plan to evolve, not a comprehensive ranking.
The model was trained from scratch on two trillion tokens, with the project describing the training mix as 87% code and 13% English and Chinese natural language. It comes in sizes from 1 billion to 33 billion parameters and has a 16K context window. Berman notes the possibility of running open models locally as coding assistants; this demonstration uses the hosted website.
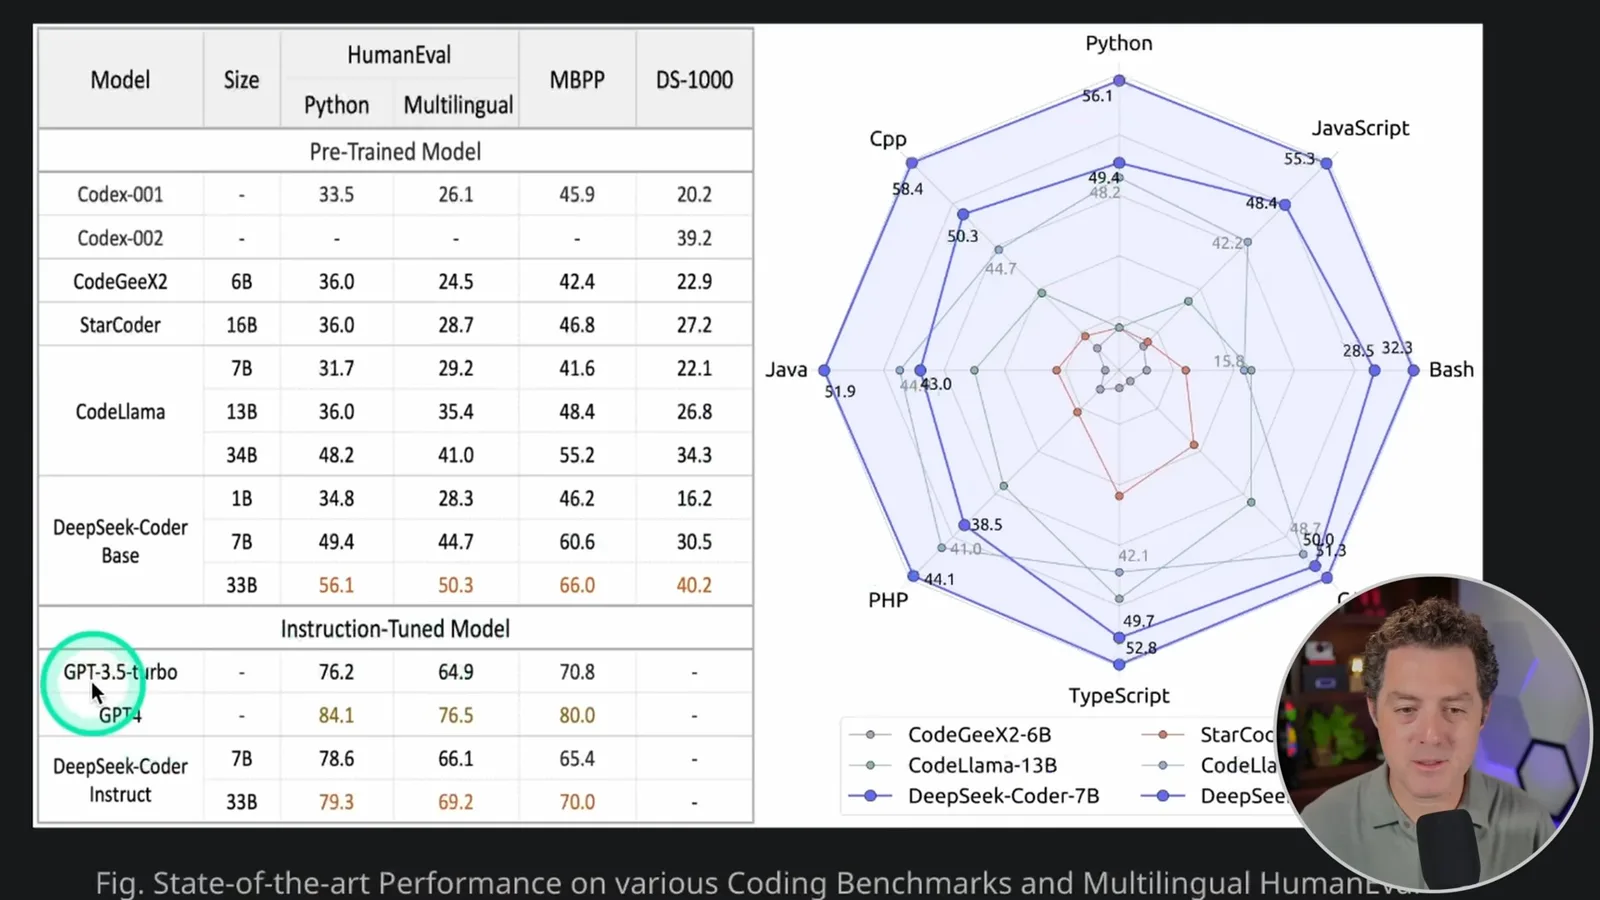
The project's chart compares base models and instruction-tuned models on several coding benchmarks. Berman reads it as showing DeepSeek Coder ahead of some open alternatives and close to GPT-4 on the displayed tests, while noting that another model he wants to test is absent. The chart is a snapshot of reported results for the models and tests shown.
JSON and contact form
The model produces the requested structured data. A Flask and SQLite form works after missing database setup and naming issues are corrected.
First, I ask for JSON describing three people: Mark and Joe are men aged 19, and Sam is a woman aged 30. The response puts their names, genders and ages into the requested structure, so I give it a pass. I start a fresh conversation for each exercise so earlier answers do not influence later tests.
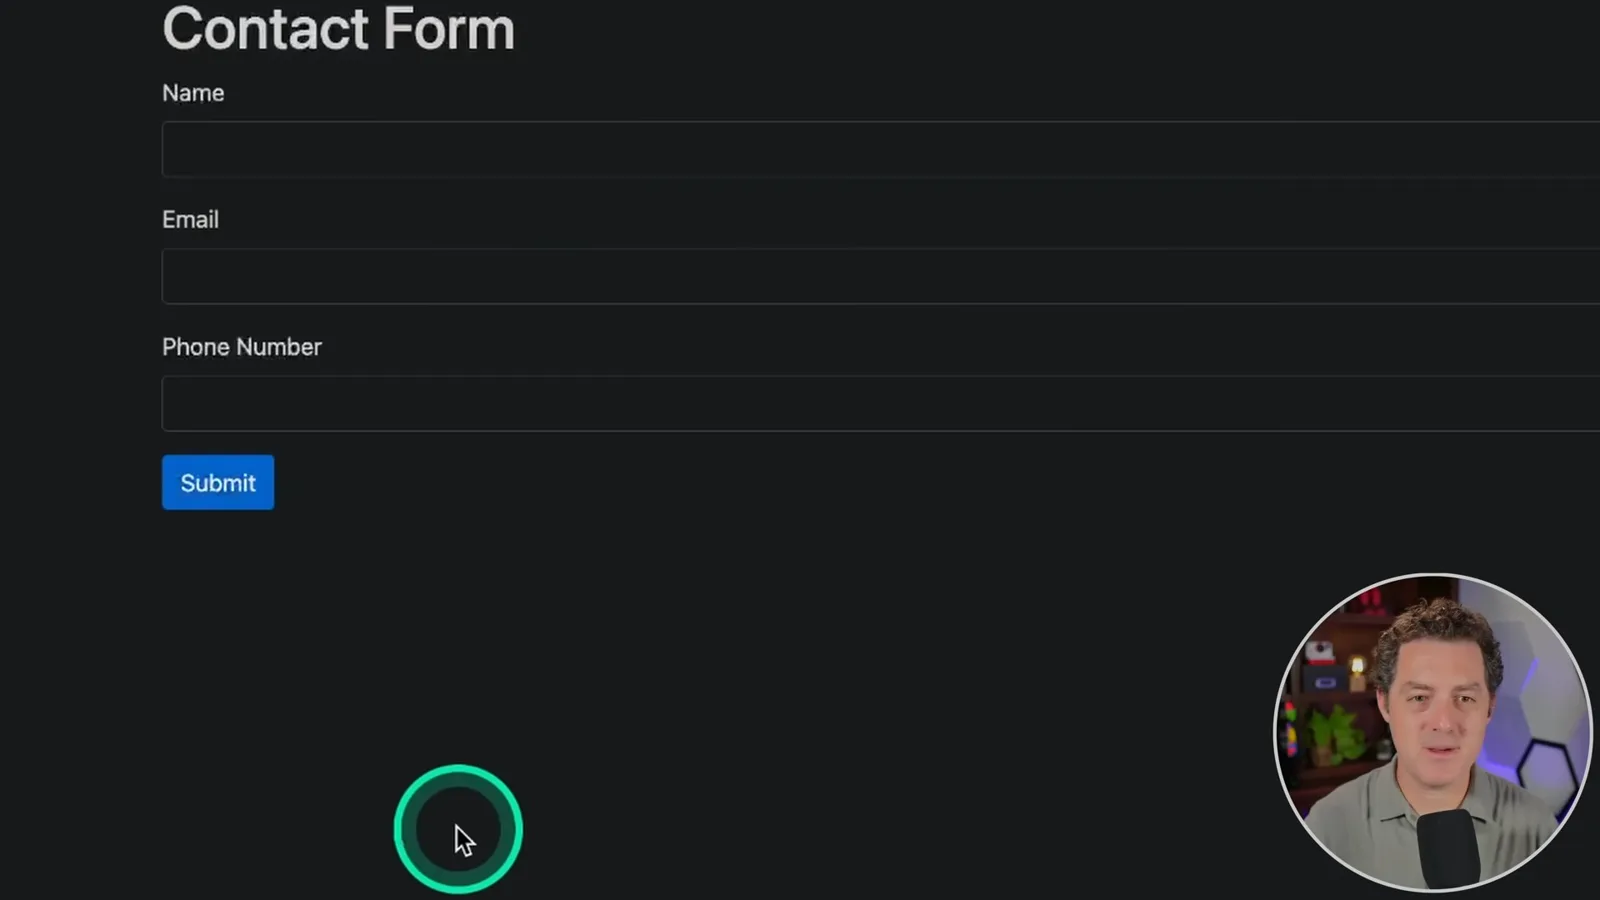
Next I request a Python contact form with name, email and phone fields that saves to a database. The model generates a Flask application with an HTML template and SQLite. I copy the code into Visual Studio Code, correct the file and template names, install the dependencies and launch the form.
The first submission fails because the contact table does not exist. I paste the error back into the model and follow its suggested database setup, also fixing an import caused by my filename. Another error needs a further prompt, but after the adjustments I submit again and verify the saved record in a SQLite browser. I count the exercise as a pass with those caveats.
Tests, bugs and a card game
Berman prompts for unit tests and their implementation, then tries a bug-finding exercise and a Set-game challenge. The bug-finding result fails his test.
For the next exercise I ask for Python unit tests for a program that checks a name contains only alphanumeric characters and then reverses it. The model writes tests, but I also need an implementation to run them against. I ask it to write that code and then explicitly connect the test file to the implementation.
The resulting three tests pass, and when I run the program with my name it returns the reversed string. I count both the code and the testing exercise as a pass, while noting the extra prompts needed to put the pieces together.
I then paste a bug-finding exercise into a new conversation and ask the model to find all the bugs. It says there are no obvious bugs, gives efficiency suggestions and starts repeating itself. The exercise's reference lists errors, so I mark this a definite failure.
For a Set card-game challenge, I paste the rules and examples and ask for a function that determines whether three cards form a valid set. The first answer is in the wrong language for the site's checker, so I ask for JavaScript. After that clarification, the submitted code passes the site's test.
Quicksort and Snake
The model recognizes an obfuscated quicksort function and generates a playable Python Snake game. Berman gives his overall assessment.
I also give the model a piece of code with renamed variables and ask it to explain what it does. It identifies a recursive quicksort implementation and breaks down the code. I find that result impressive and mark it a pass.
Finally, I ask it to write Snake in Python, an example also shown on DeepSeek Coder's own homepage. The response uses Pygame. After I install the library and run the code, the game works on the first attempt: the controls and score work, and the game stops and shows the score when I hit the edge. Overall, I find the model impressive in these tests.
Sur la même chaîne
 34:21EN
 Matthew Berman· 27 oct. 2026Matthew Berman Examines Anthropic’s IPO Filing, AI Growth and GovernanceMatthew Berman, Sam Altman · Forward FutureThe presenter reviews the S-1’s financial metrics, compute strategy and voting structure while questioning the tension between rapid AI development and safety.
 0:26ENMatthew Berman· 25 oct. 2026Sam Altman on Human Values and Problem-Solving in an AI WorldSam Altman · OpenAIIn a short interview excerpt, Altman considers the enjoyment of solving hard problems and the human role in interpreting results.
 0:36ENMatthew Berman· 25 oct. 2026Kimi K3.1 and a Rubik’s Cube Solver DemonstrationMatthew Berman · Forward FutureMatthew Berman shows a scrambled virtual cube being solved and gives the Kimi K3.1 test a favorable assessment.
 0:21ENMatthew Berman· 24 oct. 2026An AI-Generated Kimi Benchmark Chart Used Invented ScoresMatthew Berman · Forward FutureMatthew Berman asks for a graph of Kimi K3.1 Pro benchmarks, then discovers that the displayed figures are illustrative placeholders.
 25:50ENMatthew Berman· 24 oct. 2026Kimi K3.1 Pro Tested: Strong 3D Demos, Uneven Results and Competitive PricingMatthew Berman · Forward FutureMatthew Berman tests the open-weight model on coding, 3D rendering and visual explanations, then compares benchmark results and prices.
 32:20ENMatthew Berman· 23 oct. 2026Who Is Local AI For? The Costs, Trade-offs and a Hybrid FutureMatthew Berman · Forward FutureMatthew Berman weighs data control and independence against hardware cost, setup complexity and inference speed.