En 30 secondes
David Abitbol, who leads AI operations at Revolut, presents the bank’s experience serving open-weight coding models to roughly 2,000 engineers. He reports delivery and cost improvements, describes GPU and latency trade-offs, and outlines the organization’s approach to oversight and data handling.
- 1Self-hosting becomes the defaultAbitbol reports large delivery improvements and says the company moved toward open models to make costs predictable.
- 2Serving 2,000 engineersHe describes GLM 5.3 on 56 B200 GPUs and a target of under three seconds to first token.
- 3Tune before scalingHis chart compares a migration point with a stable setup on the same GPUs, showing higher request volume and lower latency.
- 4Controls for a regulated bankAbitbol describes human oversight, sandboxing, data privacy and logging as parts of Revolut’s approach.
À retenir
- Revolut reports substantial delivery improvements during AI adoption, although the chart is not a controlled causal study.
- The company uses open models by default while retaining frontier models for selected tasks.
- Time to first token, throughput and cost must be evaluated against the actual workload.
- Tuning can change serving performance without adding GPUs.
- Sandbox permissions, oversight and audit logs are part of the bank’s stated operating approach.
Lire le texte remanié, chapitre par chapitre
Engineering adoption and delivery
Abitbol introduces Revolut and shares a chart of engineering lead time and coding time. He describes the progression from early AI tools to self-hosted models.
I’m David Abitbol, and I lead AI operations at Revolut. I want to share how we use dedicated GPUs to serve open-weight models for engineering, and what we learned about speed, cost and operating in a regulated bank. These are measurements from our setup, not universal guarantees.
Revolut is a European digital bank. At the time of this talk, I describe it as serving 80 million customers across 45 markets. Our emphasis on shipping products makes engineering culture and delivery speed important to the company.
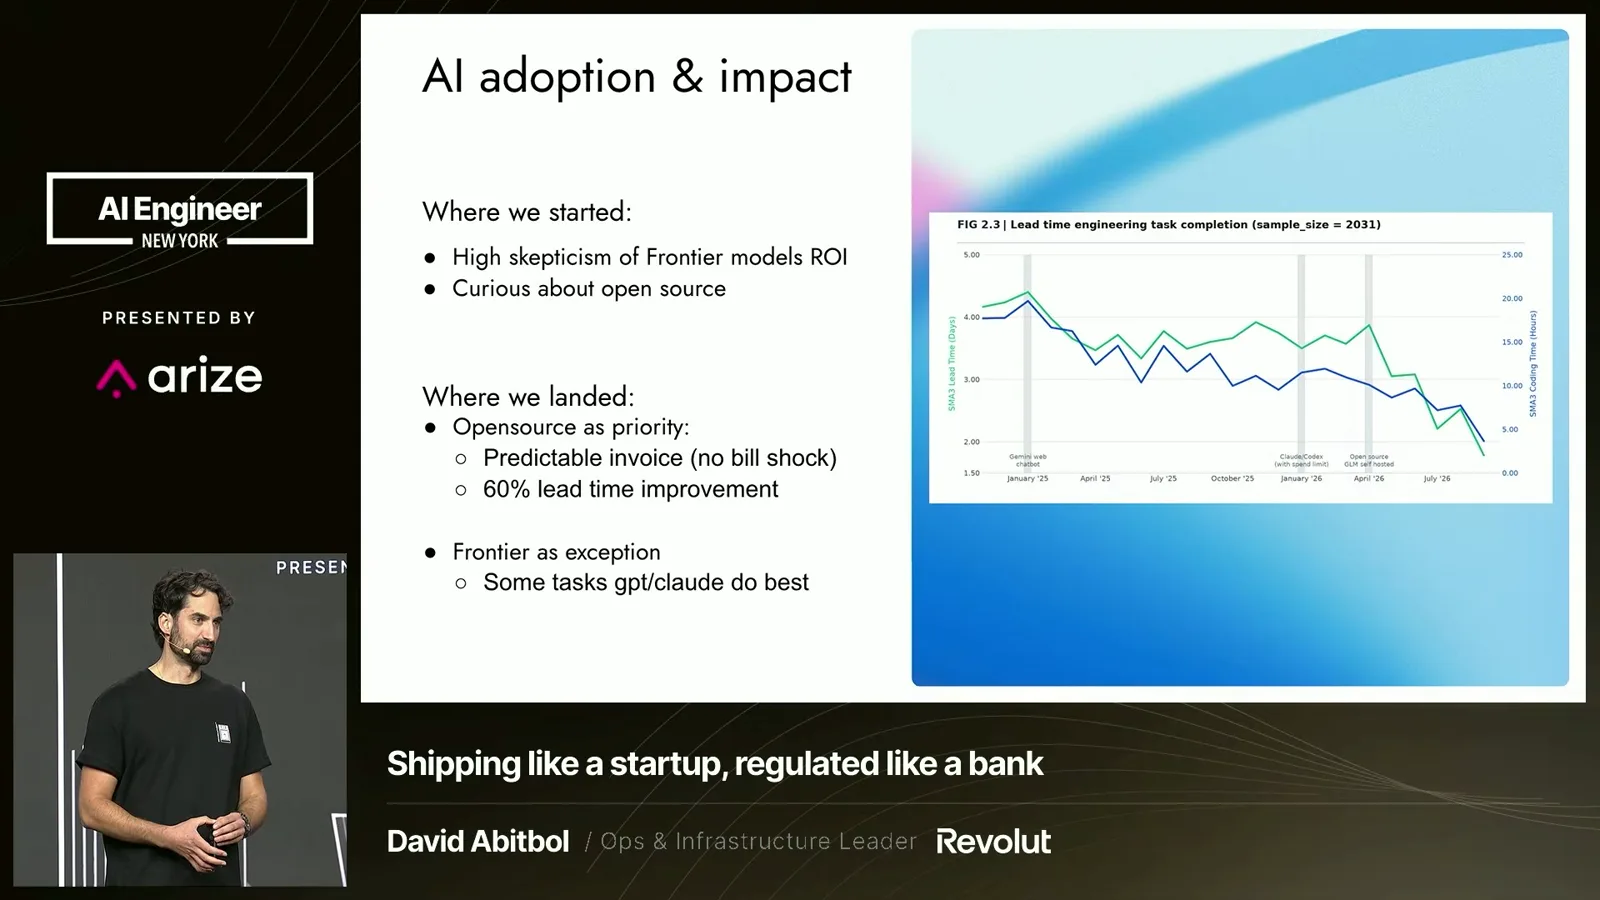
A chart of engineering work covers a sample of roughly 2,000 engineers. It tracks lead time from picking up a feature until it is merged and ready to deploy, as well as coding time. These trends show what happened during adoption; the talk does not establish a controlled causal comparison.
The timeline starts with Gemini in January 2025, followed by experimentation with Claude Code and a broader Claude/Codex rollout with spending limits in January 2026. I report initial improvements with Gemini, but we were skeptical about the return from expensive frontier-model usage and imposed strict budgets.
We wanted engineers to use tokens freely without worrying about the end-of-month bill. Around April 2026 we began self-hosting GLM models. I report substantial reductions in coding and lead time; the accompanying slide summarizes a 60% lead-time improvement, while my spoken account gives 60% for coding and 70% for lead time.
The larger lesson for me is that coding itself is not the only bottleneck. Engineers also spend time finding information and working through tools such as Jira and Confluence. With fewer concerns about token budgets, they can use AI across more of that workflow instead of reserving it only for the hardest tasks.
Capacity, latency and cost
He discusses GPU capacity, user-facing latency and reported token economics. The figures reflect Revolut’s workload.
Open models became our default because a relatively predictable bill makes usage easier to plan. We still use frontier models where they work best. Our setup serves approximately 2,000 engineers with GLM 5.3 on 56 B200 GPUs, and the slide credits Together for the deployment.
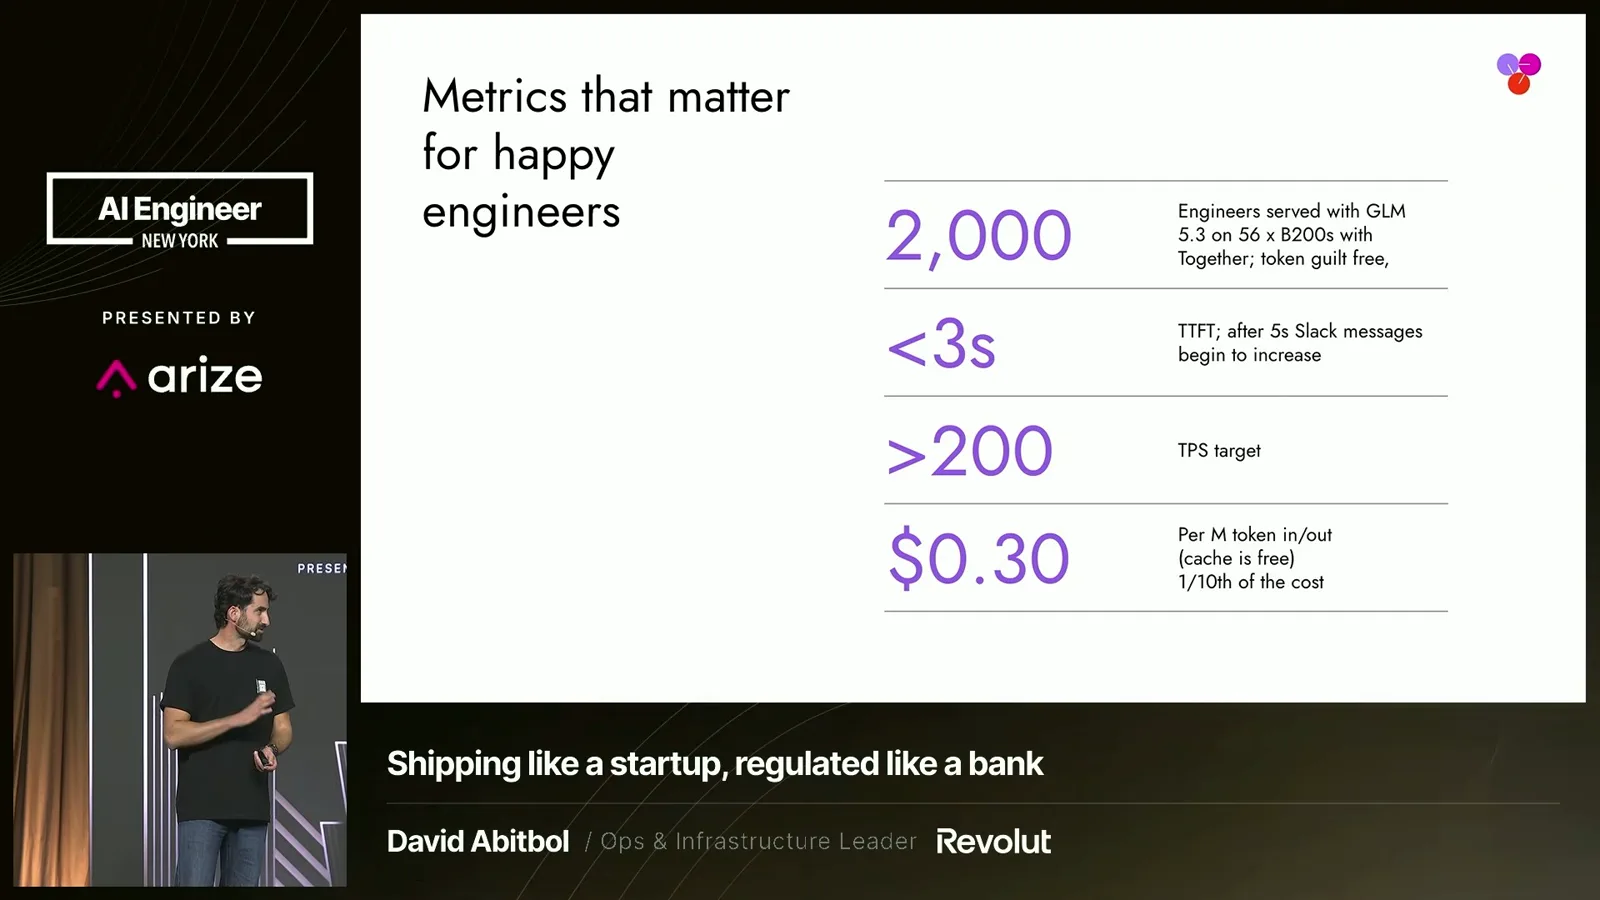
The user-facing metric I watch is time to first token. We aim for less than three seconds; in my experience, once it exceeds five seconds, complaints in Slack rise. Around 200 output tokens per second is sufficient for our interactive use, especially as engineers increasingly run tasks in parallel.
I report a blended cost of about $0.30 per million input and output tokens in our setup, with cache treated separately on the slide. I say the invoice is around one tenth of our earlier spending on Anthropic and OpenAI. The comparison is specific to our workload and billing, not a general price quote.
Tuning the serving stack
The same GPU fleet handled more requests after tuning. Abitbol discusses context, quantization, parallelism and caching.
Simply placing model weights on GPUs can yield poor performance without tuning. In our data, the same 56 GPUs ultimately handled higher request volume with lower time to first token. The chart compares a migration point with a stable setup: 76% more requests per second and an 88% reduction in that latency measure.
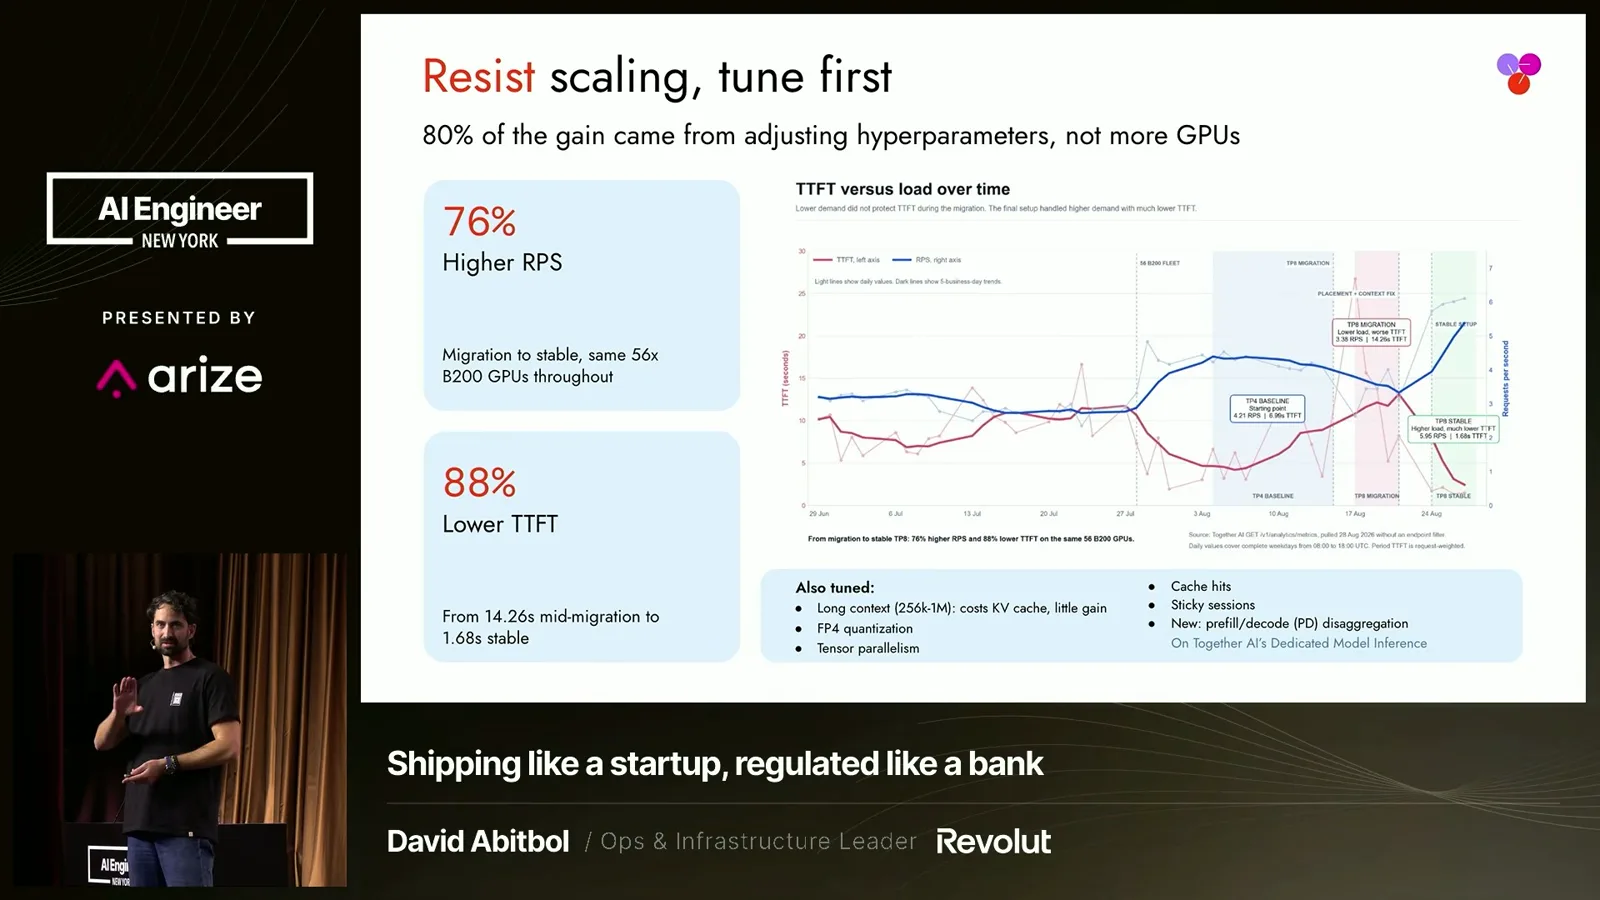
There is no secret recipe: context length, quantization, tensor parallelism and cache behavior all matter. I argue that one million tokens of context is often not worth its cache cost for our workload, and discuss FP4 and cache-hit rates. These choices should be tested against the actual workload and quality requirements.
Production setup and oversight
He describes routing vision work to other models and using compatible interfaces. He closes with the bank’s stated approach to permissions, privacy and audit logs.
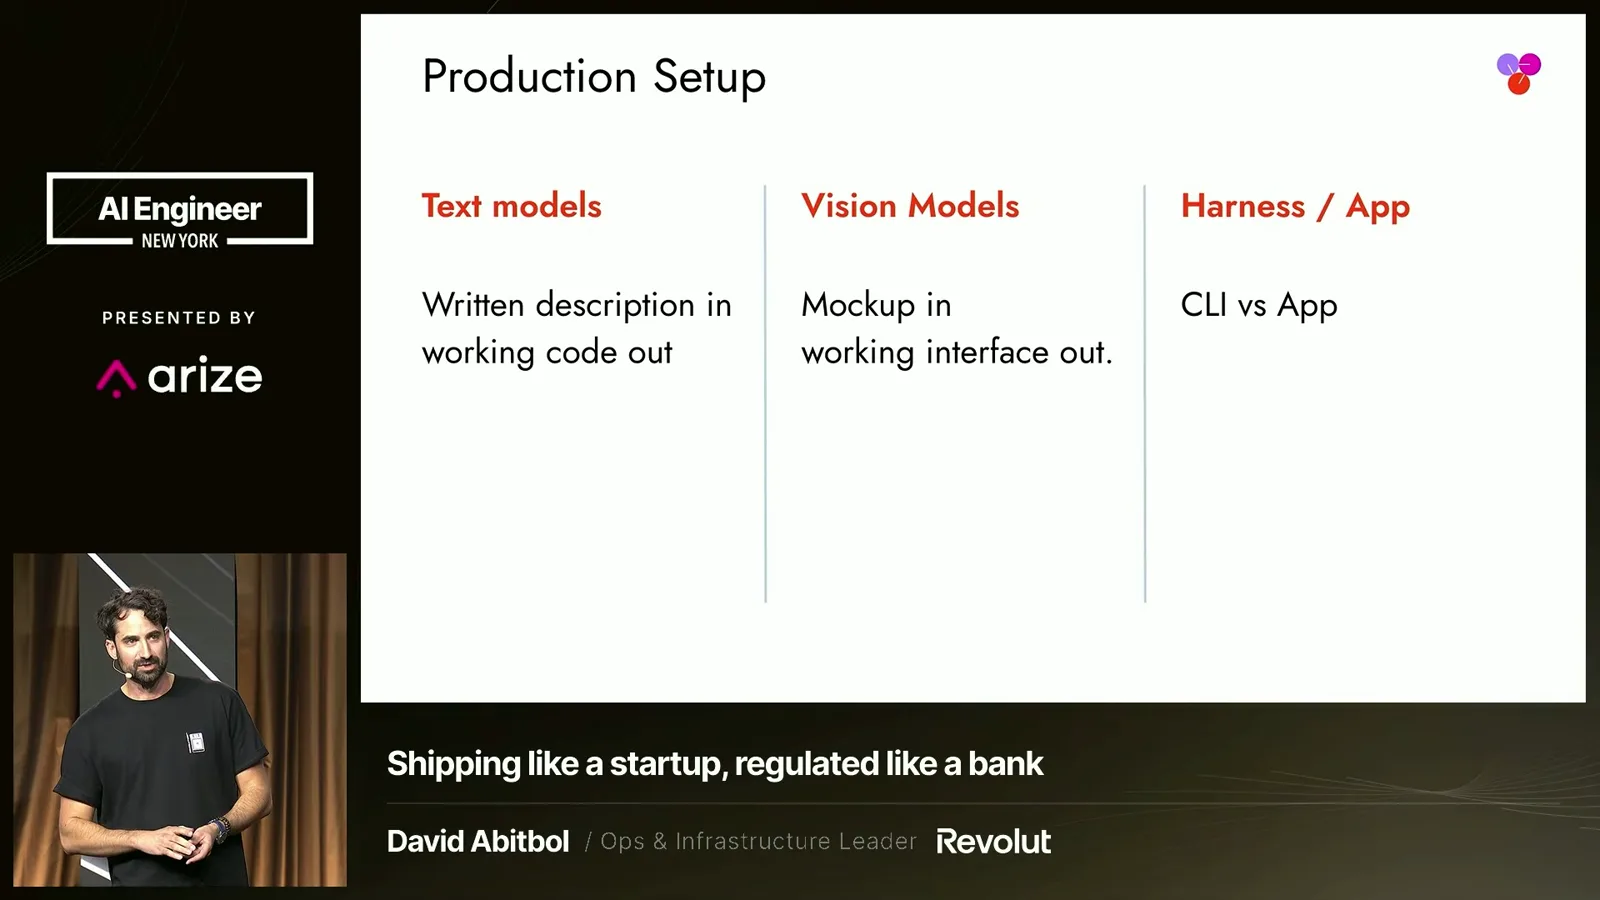
Our text model does not handle images, so we can route vision work to another model while keeping the main coding task on the text model. The endpoints expose compatible APIs and can be used with different coding harnesses or applications. The division lets teams choose the right tool for each input.
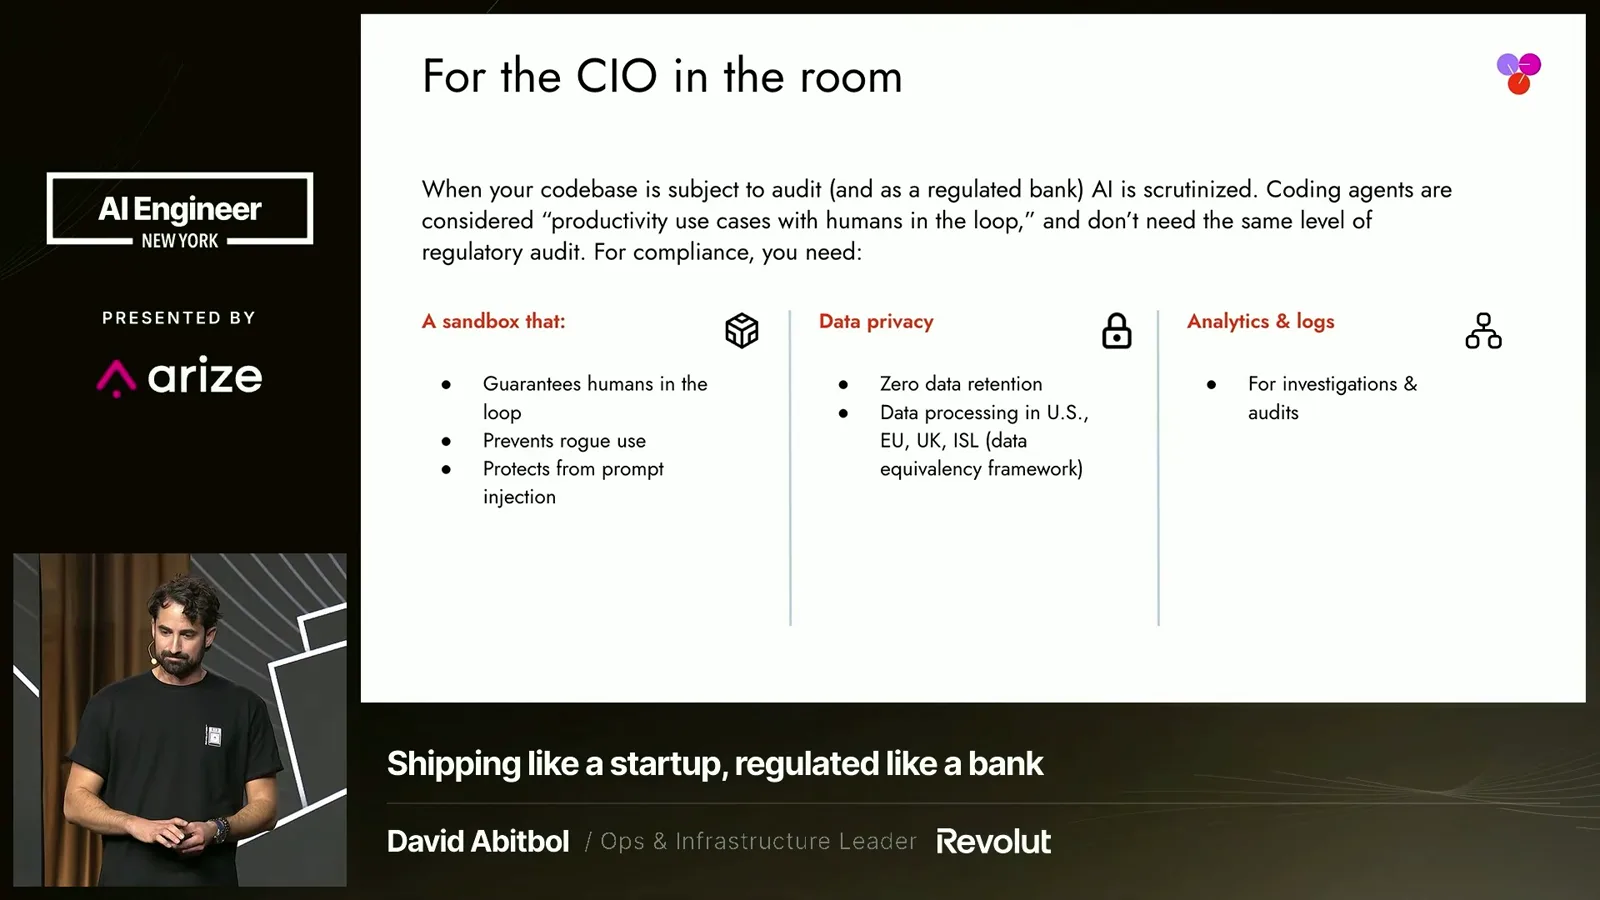
For a regulated bank, I describe controls around human oversight, sandbox permissions, data privacy and telemetry. Hosting model weights on infrastructure in an approved location changes where inference occurs, but location alone does not establish compliance or eliminate security risks.
Our approach uses permission boundaries and human approval for actions we do not want an agent to perform freely. I also mention insider misuse and prompt injection as risks, and emphasize logs for investigating incidents and auditing use. My comments about regulation and data retention describe our approach and should not be read as a blanket legal determination.
Sur la même chaîne
 21:32EN
 AI Engineer· 29 oct. 2026Shy Ruparel on AI agent reliability and recovery after failuresShy Ruparel · TemporalTemporal’s survey finds a gap between frequent agent use and dependable deployment. Ruparel demonstrates a synthetic payout workflow that resumes after workers stop.
 14:50ENAI Engineer· 29 oct. 2026Cole Gannaway on code review, cross-repository risk and AI software factoriesCole Gannaway · QodoA one-line rename can pass local checks while affecting distant clients. Qodo’s Cole Gannaway explains how review context, shared rules and independent agents can expose those risks.
 21:47ENAI Engineer· 28 oct. 2026Patrick Smyth on Open-Source Supply Chain Security in the AI EraPatrick Smyth · ChainguardChainguard’s Patrick Smyth discusses faster exploitation, malware in dependencies, zero-days and the expanding attack surface around developer workflows.
 14:09ENAI Engineer· 28 oct. 2026Taylor Luttrell-Williams on Finding Logic Vulnerabilities with SonarQube Hunter AgentTaylor Luttrell-Williams · SonarSonar’s Taylor Luttrell-Williams explains how a security agent maps a codebase, investigates logic flaws and presents validated findings alongside conventional scans.
 16:29ENAI Engineer· 28 oct. 2026Chris Vela on Benchmarking vLLM Configurations with Runpod BenchPodChris Vela · RunpodRunpod’s Chris Vela demonstrates a dashboard for comparing LLM serving configurations and choosing performance settings with workload-specific data.
 18:52ENAI Engineer· 28 oct. 2026Manish Kapur and Addy Osmani on Verifying AI Software FactoriesManish Kapur, Addy Osmani · SonarSonar’s Manish Kapur and Anthropic’s Addy Osmani discuss code review, evidence and layered checks as coding agents increase the pace of software changes.