En 30 secondes
Matthew Berman describes Gorilla, a model from UC Berkeley and Microsoft Research trained to generate API calls. He imagines applications such as shopping and booking, and contrasts its approach with the ChatGPT plugins of 2023. The paper evaluates a defined set of machine-learning APIs and documentation changes. Generating a call does not by itself demonstrate that the system can execute arbitrary actions on any website.
- 1A model for tool callsBerman introduces Gorilla as a language model designed to use external tools through API calls.
- 2Plugins and external servicesHe contrasts the 2023 ChatGPT plugin model with the research goal of interpreting tool documentation.
- 3Adapting to documentationGorilla’s retriever can supply relevant API documentation; its demonstrated scope is not every possible online action.
- 4A bounded evaluationThe paper reports API-call comparisons on APIBench, comprising Hugging Face, TorchHub and TensorHub APIs.
À retenir
- Gorilla is a fine-tuned language model designed to generate API calls from user requests.
- A document retriever can supply API documentation at inference time, helping the model adapt to tested documentation changes.
- The paper’s APIBench uses APIs from Hugging Face, TorchHub and TensorHub, not every internet service.
- Berman’s shopping and travel examples are imagined applications rather than results demonstrated in this clip.
- The paper reports stronger API-call results than selected models in its evaluation; that does not establish universal superiority or autonomous access.
Lire le texte remanié, chapitre par chapitre
Why tool use matters
Berman introduces Gorilla and gives examples of tasks he imagines an assistant could perform. He compares this with ChatGPT’s 2023 plugin approach.
Gorilla is a research project from UC Berkeley and Microsoft Research aimed at helping a language model generate calls to external tools. I imagine uses such as booking travel or ordering food. Those are illustrations of potential applications, not evidence that this research system can perform anything on the internet or that it has the necessary access to those services.
At the time of the video, ChatGPT plugins connected the assistant to external services through APIs. Gorilla pursues a related problem: turning a user’s request into an appropriate API call and using documentation to understand available interfaces. A generated call still needs a real integration, permissions and execution environment to perform an action.
Documentation and API-call evaluation
He describes adapting to new or changed tools. The paper evaluates API-call generation in a defined benchmark, not unrestricted use of every website.
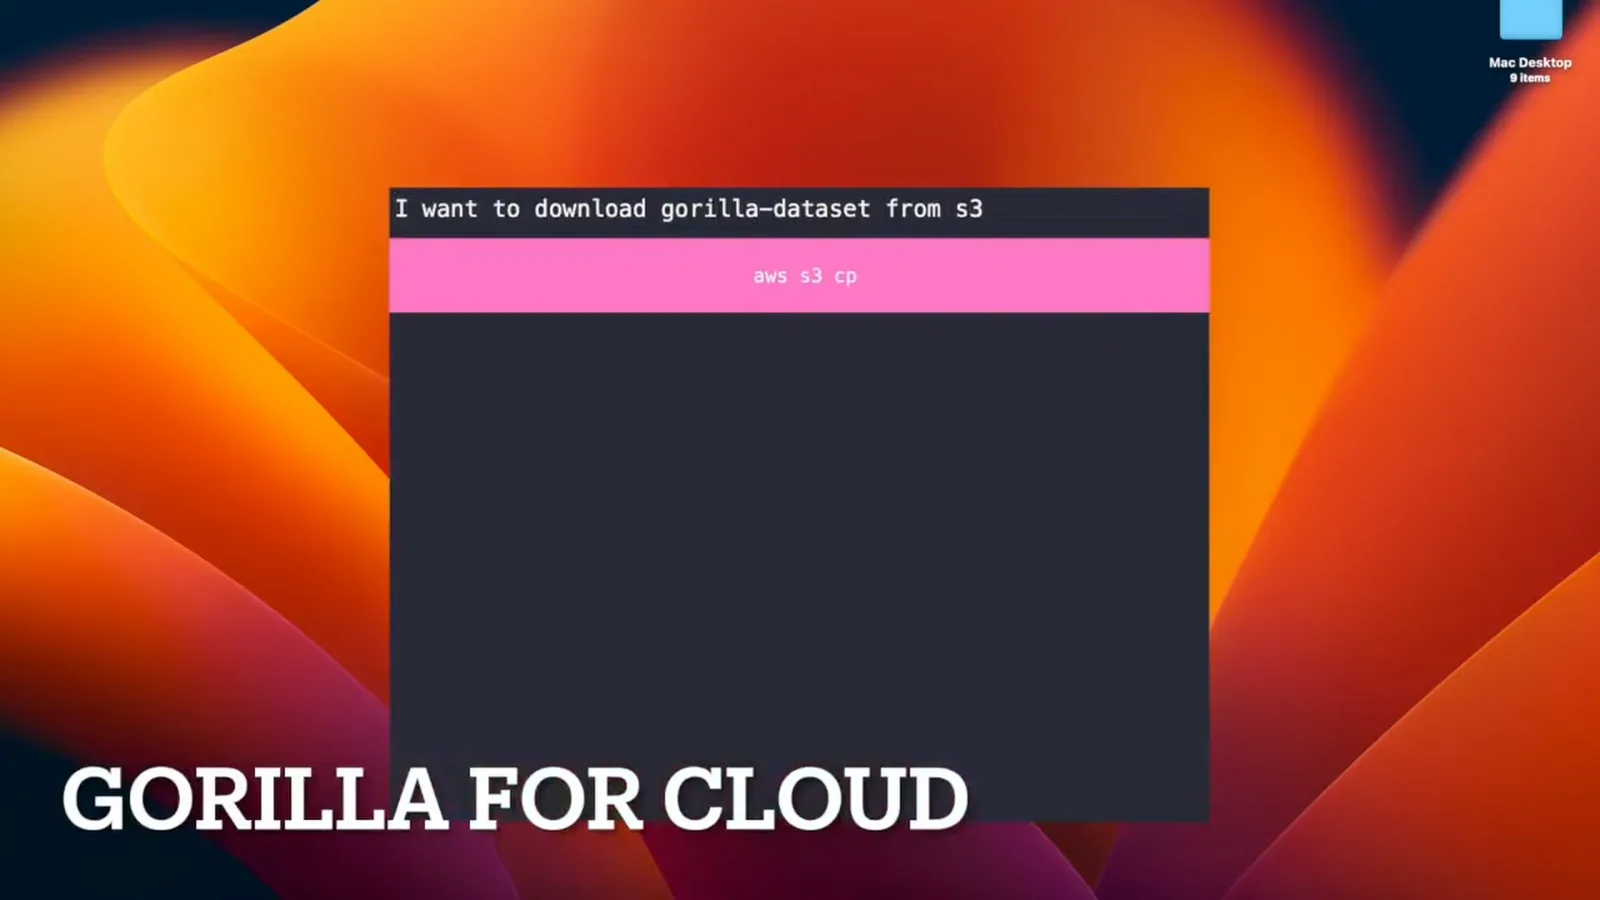
I find it exciting that a retriever can provide documentation at inference time, including changes to a tool’s interface. This does not mean the model automatically learns every possible tool or has unrestricted access. The paper tests its behavior on a defined set of machine-learning APIs and altered documentation, rather than demonstrating arbitrary shopping on Amazon.
The authors report that their fine-tuned LLaMA-based model performs well at generating API calls in their APIBench evaluation, including comparisons with selected general-purpose models. APIBench covers Hugging Face, TorchHub and TensorHub APIs. The code, model and demo were released with the research, but the results do not guarantee correct or safe tool use in every setting.
Sur la même chaîne
 34:21EN
 Matthew Berman· 27 oct. 2026Matthew Berman Examines Anthropic’s IPO Filing, AI Growth and GovernanceMatthew Berman, Sam Altman · Forward FutureThe presenter reviews the S-1’s financial metrics, compute strategy and voting structure while questioning the tension between rapid AI development and safety.
 0:26ENMatthew Berman· 25 oct. 2026Sam Altman on Human Values and Problem-Solving in an AI WorldSam Altman · OpenAIIn a short interview excerpt, Altman considers the enjoyment of solving hard problems and the human role in interpreting results.
 0:36ENMatthew Berman· 25 oct. 2026Kimi K3.1 and a Rubik’s Cube Solver DemonstrationMatthew Berman · Forward FutureMatthew Berman shows a scrambled virtual cube being solved and gives the Kimi K3.1 test a favorable assessment.
 0:21ENMatthew Berman· 24 oct. 2026An AI-Generated Kimi Benchmark Chart Used Invented ScoresMatthew Berman · Forward FutureMatthew Berman asks for a graph of Kimi K3.1 Pro benchmarks, then discovers that the displayed figures are illustrative placeholders.
 25:50ENMatthew Berman· 24 oct. 2026Kimi K3.1 Pro Tested: Strong 3D Demos, Uneven Results and Competitive PricingMatthew Berman · Forward FutureMatthew Berman tests the open-weight model on coding, 3D rendering and visual explanations, then compares benchmark results and prices.
 32:20ENMatthew Berman· 23 oct. 2026Who Is Local AI For? The Costs, Trade-offs and a Hybrid FutureMatthew Berman · Forward FutureMatthew Berman weighs data control and independence against hardware cost, setup complexity and inference speed.