En 30 secondes
Cisco’s Al Chen describes three challenges in deploying AI observability software into bank production: CVE remediation, disaster recovery and preventing sensitive-data leakage. He argues that evidence and organizational readiness are central to faster compliance.
- 1A matrix of CVEsImages, versions, scanners and bank policies multiply the work.
- 2Evidence beyond versionsTests can provide evidence for a specific exploit, without proving total security.
- 3Check recovered dataSuccessful jobs alone do not prove data correctness.
- 4Watch judge explanationsEvaluation traces can expose data hidden in the UI.
- 5Readiness changes timelinesApprovals and infrastructure shape the path to production.
À retenir
- Bank production deployments require evidence tailored to the customer’s environment.
- A package update or scan alone does not establish that an exploit is gone.
- Backup success should be accompanied by data correctness and residency checks.
- LLM judge explanations and traces can expose sensitive information.
- Deployment schedules depend on organizational readiness as well as technical work.
Lire le texte remanié, chapitre par chapitre
Show your work
Bank production requires evidence and coordination.
My tenth-grade math teacher required answers to four decimal places, but most credit came from the proof. Bank risk and compliance teams ask for the same thing at a much larger scale: show the work, not just the answer.
Deploying AI into bank production takes time. I mean applications used by millions of customers, not just prototypes or internal productivity tools. Our team helps large banks deploy software and engineering processes; I will share techniques we have used to shorten some deployments from a year to weeks.
A conventional SaaS deployment with outbound internet access may conflict with the bank’s sensitive-data boundaries. I organize the problem into three pillars: vulnerability handling in the build pipeline, disaster recovery, and preventing sensitive information from escaping through unexpected paths.
CVE remediation
Multiple versions and dependencies complicate vulnerability management.
A single CVE can be researched in public databases, but real platforms have many images and dependencies across banks. Each bank may run a different version, use a different scanner, and apply its own severity policies and remediation deadlines.
Some issues sit in transitive open-source dependencies and cannot be fixed directly by our engineering team. We track upstream releases and explain the dependency to bank security teams. Where we can remediate, we may update a package or rebuild against a new base image, while checking that the application still works.
Different banks may also require different package versions. A skill can help research and report the CVEs, identify work the team can fix, and explain why other issues depend on upstream maintainers.
A scanner’s package-version check does not by itself prove whether an exploit still works in the application. Chen describes a Harbor task with instructions, application container images and tests, in which an agent attempts to reproduce the older exploit against a supposedly remediated version.
The trials can run in separate containers or sandboxes. The point is to produce evidence about the particular issue, not merely say that a version number changed. A failed test is evidence for that test, not proof that the application has no vulnerabilities.
Disaster recovery
Backups must be checked for data correctness and residency.
Disaster recovery is a core requirement for banks. Chen describes the cross-region recovery challenge for ClickHouse deployments in his customers’ environments and a pattern using a primary region, object-store backup and restoration into a disaster-recovery region.
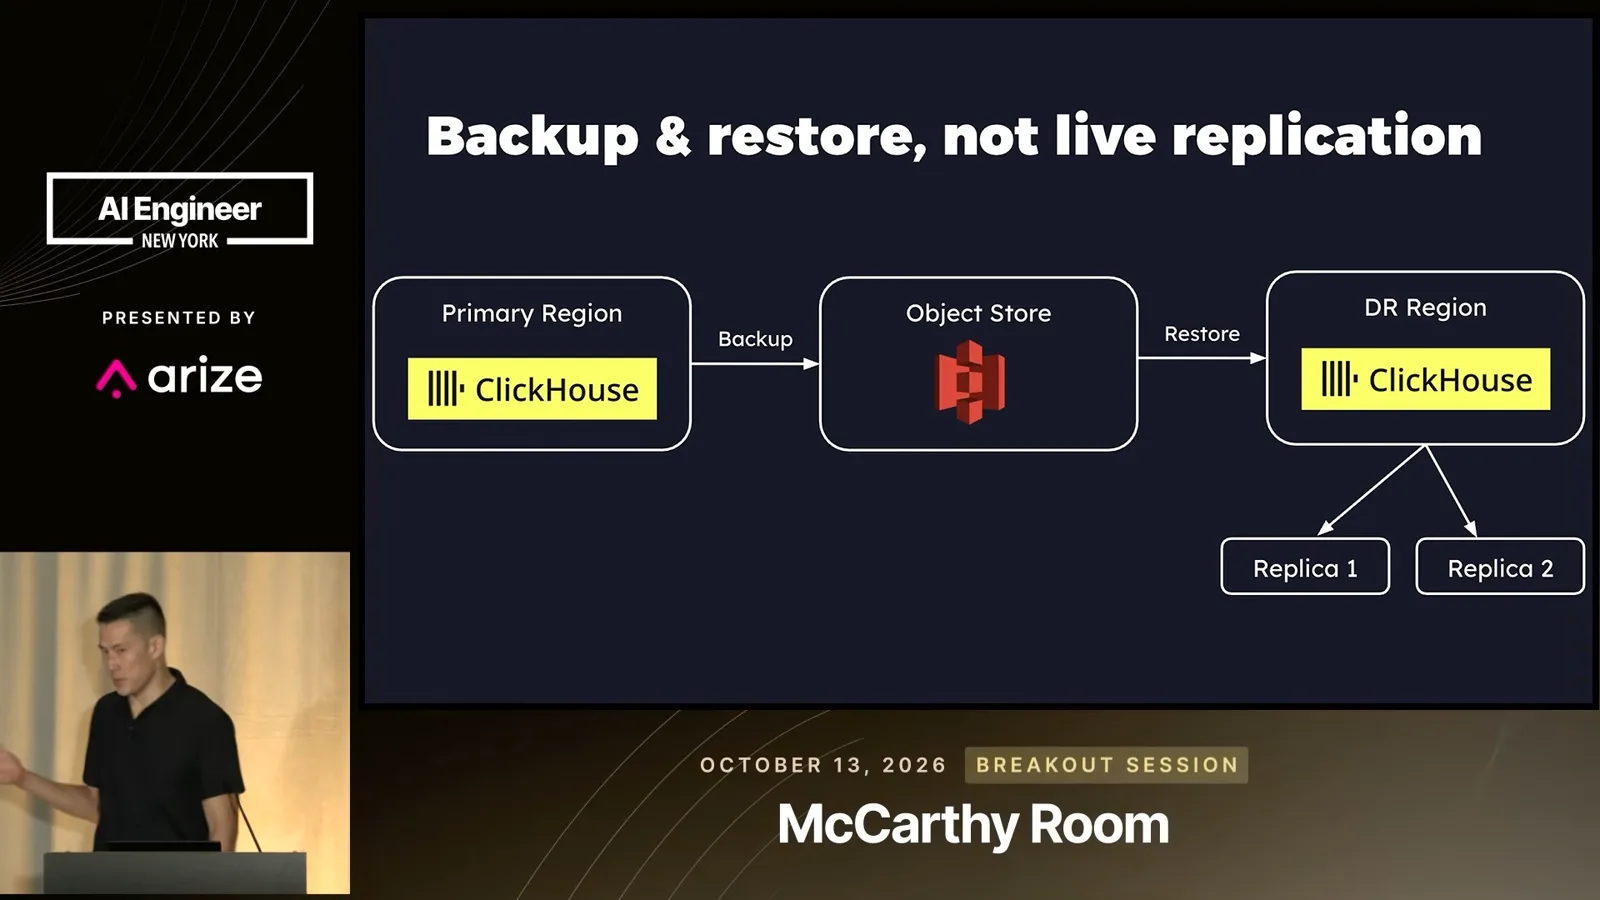
The example uses the open-source ClickHouse backup project and may restore replicas in the recovery region. A successful backup or restore log alone does not establish that the recovered data is current and correct: disk faults, migrations or replication lag can affect it.
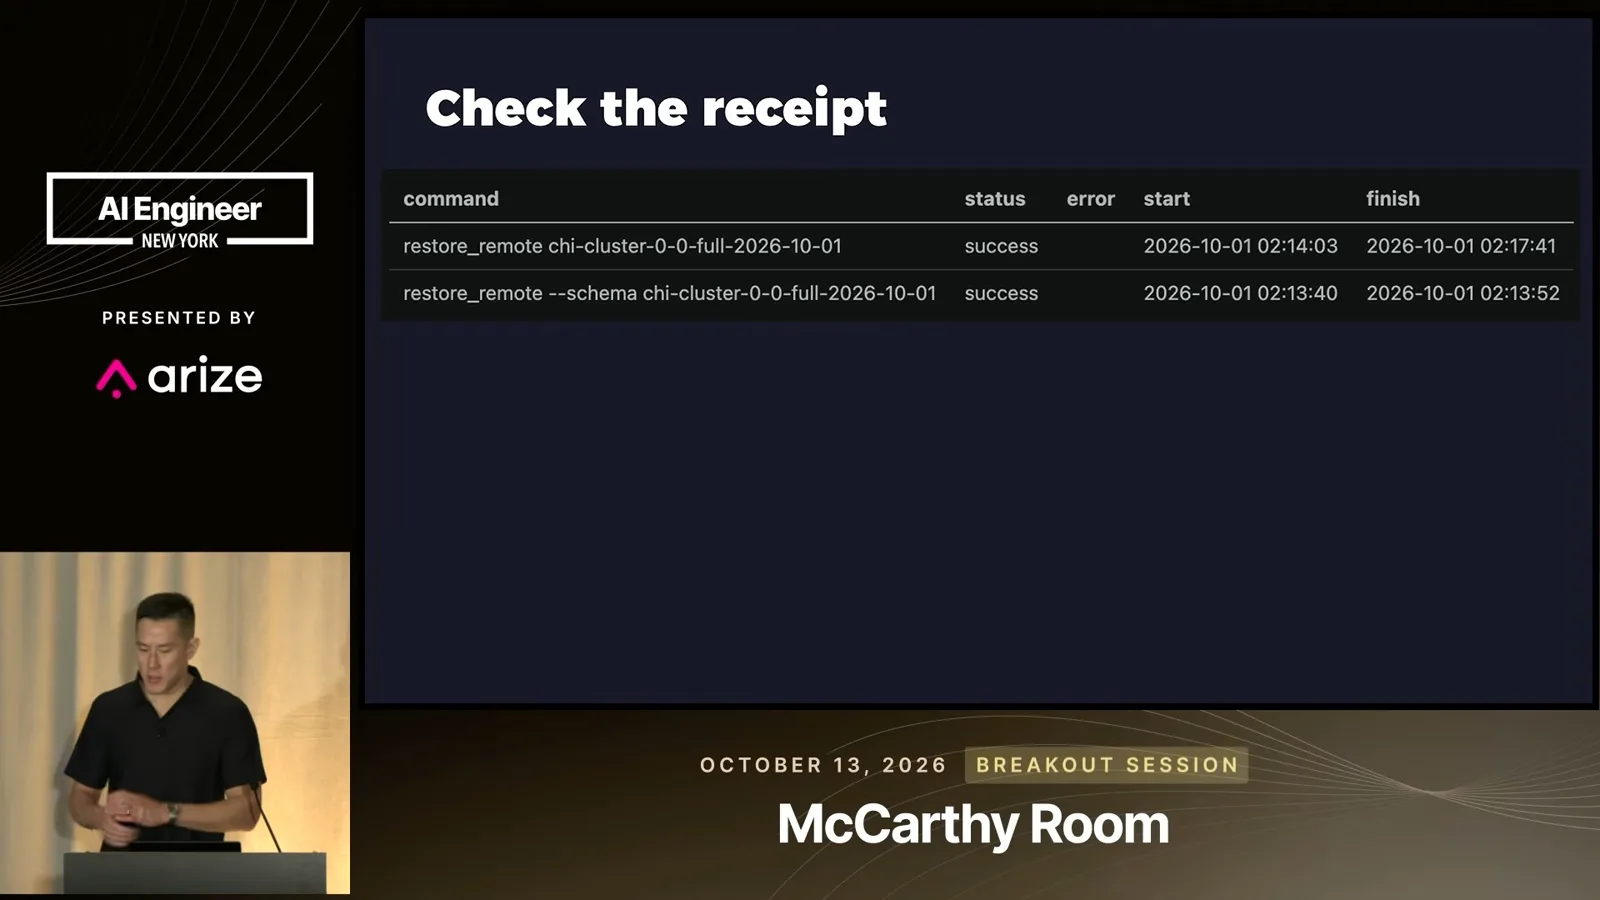
Additional checks can compare table row counts and whether replicas have converged. These checks support a data-correctness assessment, though they are not a complete guarantee. Disaster recovery architecture also has to respect data-residency requirements.
For example, a design might replicate IDs and trace metadata across regions while keeping the underlying trace data in its permitted region. Whether that is appropriate depends on the data, applicable requirements and the bank’s own controls.
Sensitive-data leakage
Judge explanations can create another exposure path.
The third pillar is sensitive-data leakage. Redaction can occur in an SDK, gateway or middleware, yet an application with a properly redacted user interface may still have another path exposing personal or material nonpublic information.
One example is an LLM judge used to evaluate an agent. A prompt requesting an explanation for a score can lead the judge’s reasoning or traces to reproduce sensitive details, even though the front-end record appears redacted.
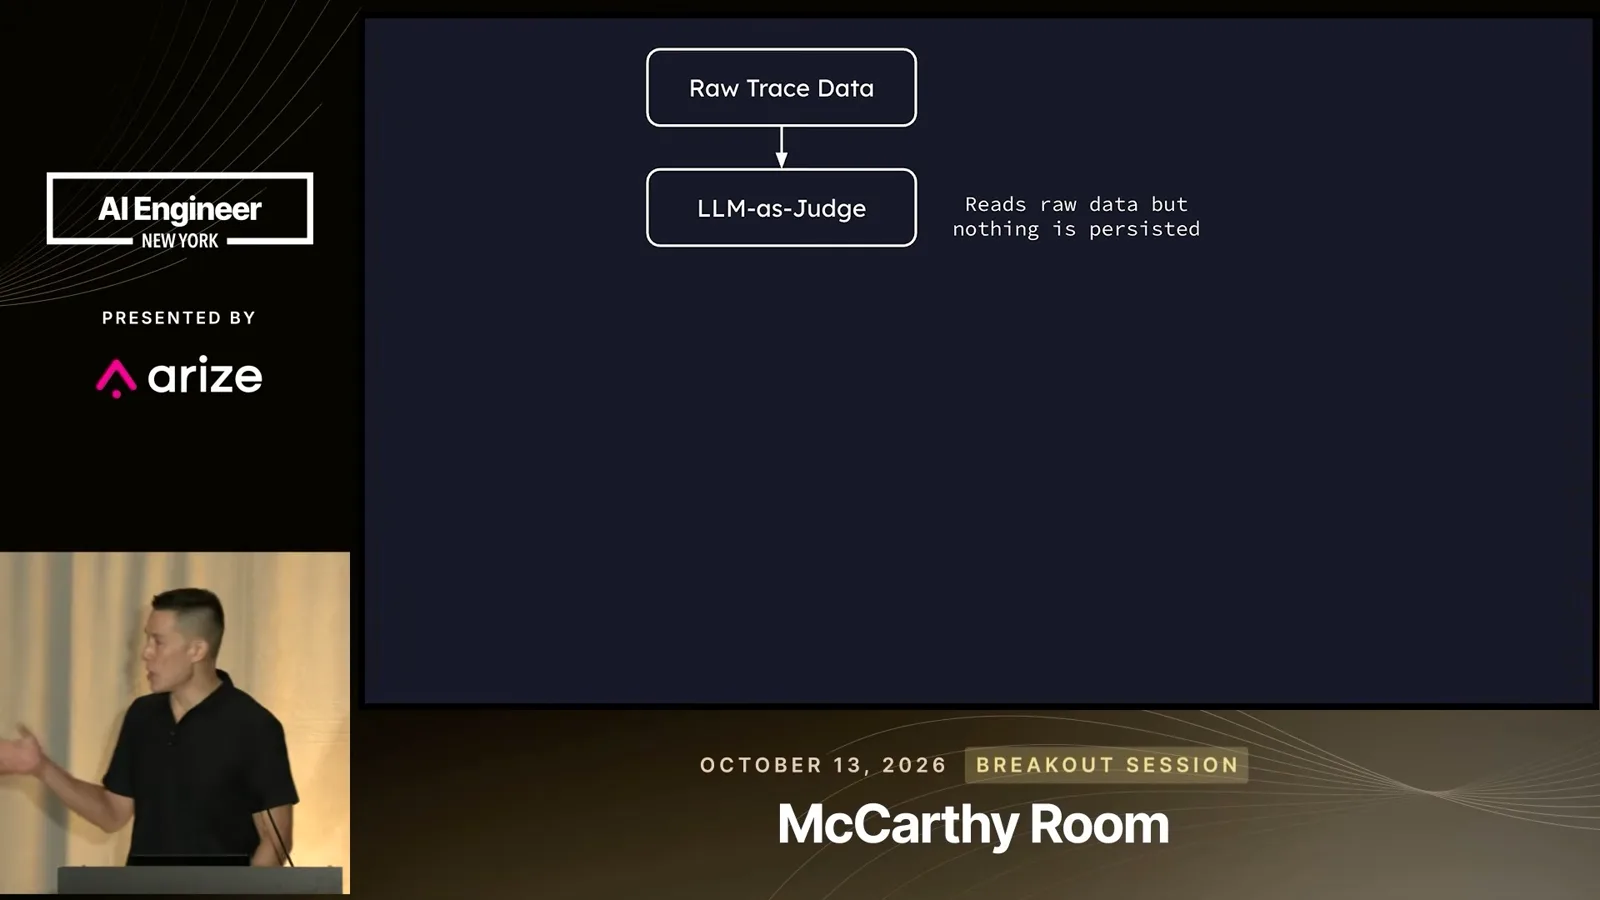
Chen proposes allowing a judge to read a raw trace without persisting its reasoning, while retaining the score. A check can determine whether an explanation may be displayed; if sensitive information is detected, the explanation is suppressed.
For teams that need an explanation, he describes a second judge given redacted input. This adds another model call and cost. Redaction and checks reduce exposure but should be validated for the actual system; they do not establish a guarantee of zero leakage.
Shortening deployment time
Infrastructure readiness and organizational alignment affect timing.
Trust comes from showing evidence to security and compliance teams. A vendor’s promise of deployment in a few weeks needs to be checked against the particular bank’s infrastructure, security posture and cluster configuration.
Existing processes for pulling approved images and access to GPUs can accelerate a deployment. Formal reviews, a custom model gateway or role-based access configuration can extend it; missing image-approval or GPU-procurement processes may delay it further.
Many schedule risks are organizational rather than purely technical. Chen’s team divides customer problems into engineering, workflow and human coordination, then automates what it can. The aim is to solve the bank’s actual problem and demonstrate how the answer was reached.
The stakes include checking accounts, mortgages and credit cards, which explains why careful processes persist. Chen closes by inviting practitioners to share how they approach these difficult customer problems, just as classmates once compared their math solutions after a test.
Sur la même chaîne
 14:50EN
 AI Engineer· 29 oct. 2026Cole Gannaway on code review, cross-repository risk and AI software factoriesCole Gannaway · QodoA one-line rename can pass local checks while affecting distant clients. Qodo’s Cole Gannaway explains how review context, shared rules and independent agents can expose those risks.
 21:47ENAI Engineer· 28 oct. 2026Patrick Smyth on Open-Source Supply Chain Security in the AI EraPatrick Smyth · ChainguardChainguard’s Patrick Smyth discusses faster exploitation, malware in dependencies, zero-days and the expanding attack surface around developer workflows.
 14:09ENAI Engineer· 28 oct. 2026Taylor Luttrell-Williams on Finding Logic Vulnerabilities with SonarQube Hunter AgentTaylor Luttrell-Williams · SonarSonar’s Taylor Luttrell-Williams explains how a security agent maps a codebase, investigates logic flaws and presents validated findings alongside conventional scans.
 16:29ENAI Engineer· 28 oct. 2026Chris Vela on Benchmarking vLLM Configurations with Runpod BenchPodChris Vela · RunpodRunpod’s Chris Vela demonstrates a dashboard for comparing LLM serving configurations and choosing performance settings with workload-specific data.
 18:52ENAI Engineer· 28 oct. 2026Manish Kapur and Addy Osmani on Verifying AI Software FactoriesManish Kapur, Addy Osmani · SonarSonar’s Manish Kapur and Anthropic’s Addy Osmani discuss code review, evidence and layered checks as coding agents increase the pace of software changes.
 18:35ENAI Engineer· 28 oct. 2026Kamil Potrec on Agent Authentication, Delegation and Gateway ControlsKamil Potrec · KeycardKeycard’s Kamil Potrec explains why agents need distinct identities, scoped credentials and auditable authorization, and where gateways can help.