En 30 secondes
In a sponsored 2024 video, Matthew Berman runs Llama 3.1 8B through an informal prompt rubric. He reports fast responses and some correct answers but is disappointed by coding and reasoning errors, while noting that his setup might merit further investigation.
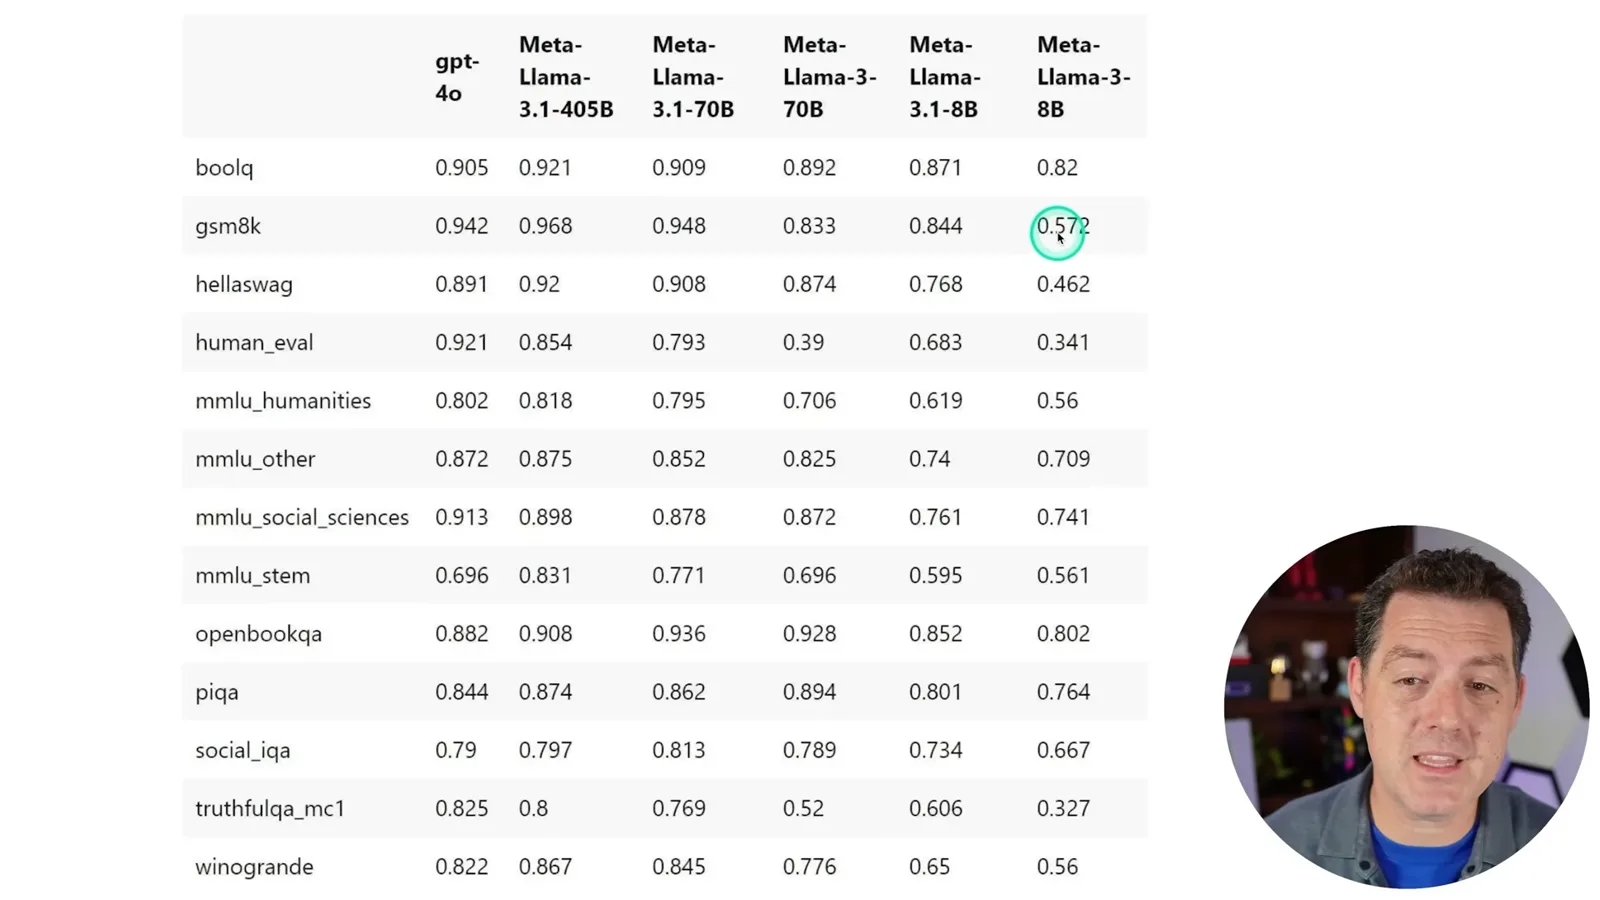
- 1Reported benchmark gainsThe displayed table reports large gains for the 8B model on GSM8K and HumanEval.
- 2Snake game failsMultiple revisions still leave functional or syntax problems.
- 3A missing assumptionThe shirt-drying answer changes depending on available space.
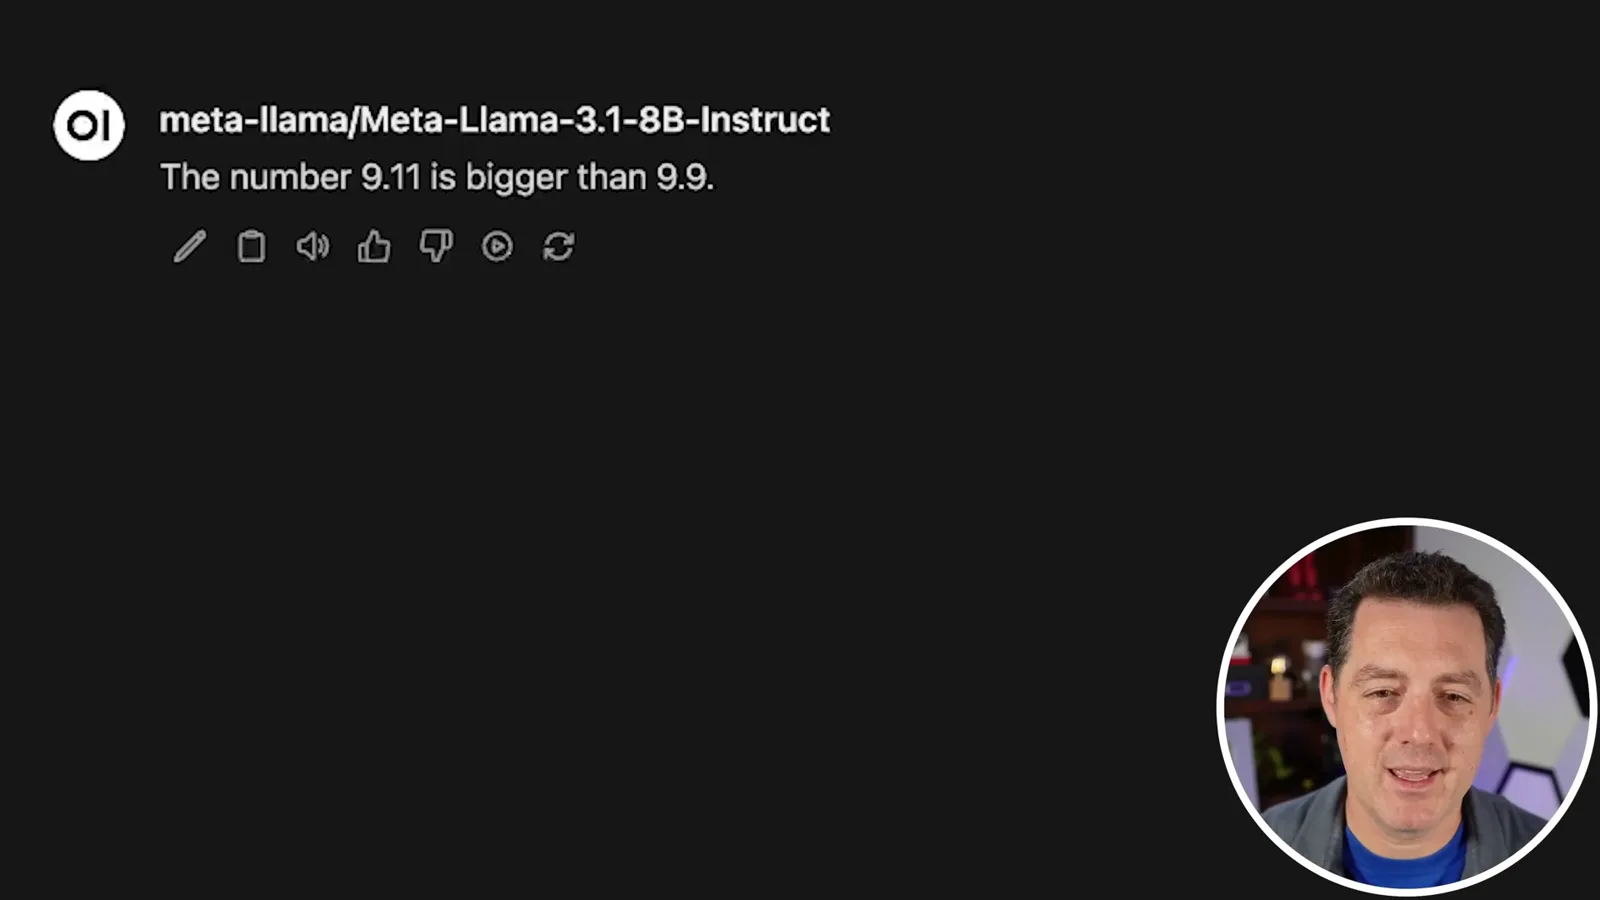
- 4Decimal errorThe model incorrectly ranks 9.11 above 9.9 in this test.
À retenir
- Reported benchmark gains do not guarantee success on every practical prompt.
- The model passed a simple coding task but failed to produce a working Snake game in this test.
- The drying puzzle depended on an unstated space constraint.
- Several reasoning and decimal-comparison answers were wrong in this run.
- The test was informal and the model was hosted by video sponsor Vultr.
Lire le texte remanié, chapitre par chapitre
Setup and benchmarks
Berman introduces the sponsored hosting arrangement and the reported benchmark improvements.
Llama 3.1’s 405B model is attracting attention, but I want to test the smaller 8B version after seeing large benchmark gains over its predecessor. Vultr sponsored the video and hosts the model for my tests.
I use Open WebUI locally and connect it to the remotely hosted model through an API-compatible connection. The interface can also work with local models; here the model runs on Vultr’s infrastructure.
The benchmark table compares Llama 3.1 8B with Llama 3 8B. It reports GSM8K rising from about 0.57 to 0.84 and HumanEval from about 0.34 to 0.68; those numbers describe the reported benchmark setup, not every real-world task.
Coding tests
A simple script passes, but a Snake game remains broken after revisions.
The first coding prompt asks for numbers from one to 100 in Python. The model supplies several correct versions quickly, so I count that as a pass.
A harder prompt asks for a Python Snake game. The first program runs, but the snake appears to grow without moving properly and the game is too fast.
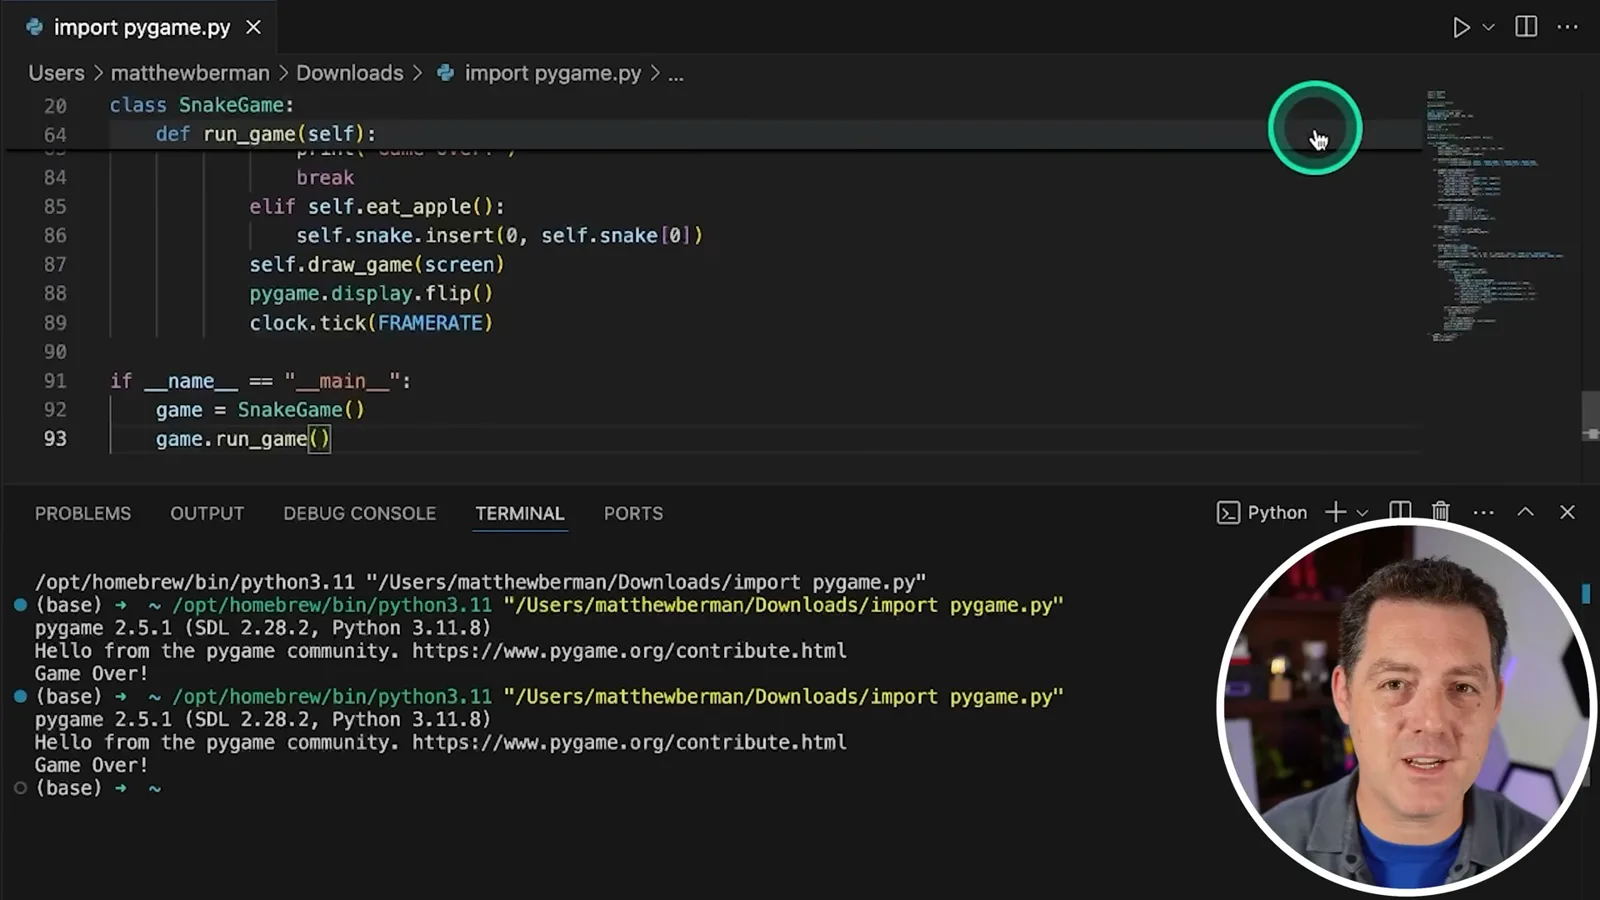
I ask it to correct the problems. One revision has a syntax error; after another attempt from scratch the game improves but leaves a trail that causes an error when crossed. I score the task as a failure.
Refusals and reasoning
He tests refusal behavior and a shirt-drying puzzle.
I probe the model’s refusal behavior with harmful requests and find that its responses vary with framing. I regard the refusals as censorship for my rubric, though the outcome is specific to these informal prompts.
For the shirt-drying puzzle, the model gives 16 hours by implicitly treating drying as batches. I wanted it to identify that, with enough space, all shirts can dry simultaneously; it gives the batch answer correctly once I specify the space constraint.
Math, logic and moral questions
The model answers some arithmetic correctly but fails several other prompts.
The model correctly applies arithmetic order of operations and solves the hotel bill with an 8% room tax and a separate untaxed fee. These simple successes do not establish broader reliability.
Asked to count the words in its response, it gives an answer I cannot reconcile with the text, so I mark it wrong. It also answers the room-of-killers puzzle incorrectly in my test.
In the inverted-glass puzzle, the model says the marble stays inside the glass after the glass is lifted, ignoring gravity. I mark that answer wrong.
It also fails my request for ten sentences ending in “apple” and says 9.11 is greater than 9.9. Rephrasing the decimal comparison does not fix the answer in this run.
I pose a moral hypothetical about gently pushing someone to save humanity. The model initially discusses how to think about the question and, after repeated pressure for yes or no, answers no; I disagree with that answer and question how such a test should be scored.
I decide to count its initial reluctance to make the judgment as a pass, while inviting viewers to consider whether AI should answer moral questions at all. This is my subjective scoring choice, not an objective measure of moral competence.
Conclusion
Berman is disappointed and says the setup may need further investigation.
Overall, I am disappointed by this set of results despite the benchmark gains. I say I will investigate whether my setup affected the outcome; the model responded quickly on the sponsor’s infrastructure, but speed did not resolve the observed quality problems.
Sur la même chaîne
 25:50EN
 32:20EN
 0:22EN
 45:08EN
 0:32EN
 1:02EN