








Résultats
6 articlesTrier
 1:43:51EN
 Matthew Berman· 8 août 2025GPT-5, Cline and SWE-bench: How to Judge AI Coding AgentsMatthew Berman, Matt Wolfe, Ray Fernando, Saoud Razwan, Nick, Ofir, Carlos, John, Kilian · Forward FutureMatthew Berman and guests discuss early GPT-5 impressions, the economics of Cline, and why coding benchmark results depend on the evaluation setup.
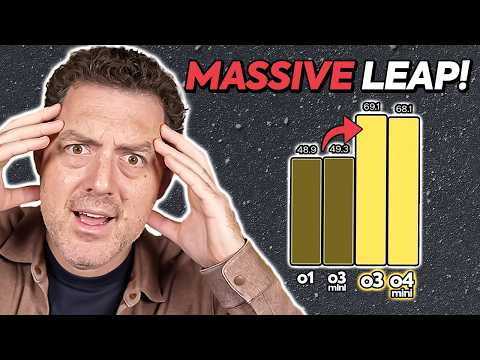 15:46ENMatthew Berman· 16 avr. 2025OpenAI o3 and o4-mini: Tool Use, Benchmarks and the First Codex CLIMatthew Berman · Forward FutureMatthew Berman reviews OpenAI’s April 2025 reasoning-model release, a scientific image-analysis demonstration and the debut of its terminal coding agent.
 21:16ENMatthew Berman· 14 avr. 2025GPT-4.1, Mini and Nano: Coding, Long Context and 2025 API PricingMatthew Berman · Forward FutureMatthew Berman reviews OpenAI’s April 2025 model launch, selected coding benchmarks and demonstrations, and a sponsored Box evaluation.
 19:32ENMatthew Berman· 28 févr. 2025GPT-4.5’s Launch: Conversational Style, Benchmarks and CostMatthew Berman · Forward FutureMatthew Berman examines OpenAI’s February 2025 research preview, its selected demonstrations, reported evaluations and high launch pricing.
 13:24ENMatthew Berman· 18 févr. 2025Grok 3’s 2025 Launch: Benchmarks, Reasoning and DeepSearchMatthew Berman, Elon Musk · Forward FutureMatthew Berman reviews xAI’s launch charts, a historical user-preference leaderboard and an early product demonstration.
 37:58ENMatthew Berman· 23 janv. 2025OpenAI Operator’s 2025 Launch: Browser Tasks, Human Control and LimitsMatthew Berman, Sam Altman · Forward FutureMatthew Berman watches the early Operator demonstration, from restaurant bookings and groceries to safety controls and benchmark results.