En 30 segundos
SemiAnalysis analyst Oliver Kennon explains why the same GPU can produce different amounts of useful work depending on its operator. He distinguishes rental price from full production cost and describes how service grades and price references might support compute futures.
- 1A 50% output gapThe measured configurations use the same GPU and workload, but differ in several operating choices.
- 2Security is part of usefulnessFast responses are insufficient if access boundaries fail.
- 3Count full spendingDivide all relevant costs by acceptable output over the same period.
- 4Position is relativeYour cost can improve while a competitor improves faster.
- 5Hedging has limitsA rental-price hedge does not guarantee operational performance or payment.
Conclusiones
- Hardware is an input; useful output depends on the whole serving system.
- A particular B200 comparison showed about 50% more throughput with a different complete configuration.
- Quality, latency, reliability and security all matter to usable output.
- Full cost per acceptable output includes the cost of better operations.
- A rental-price hedge addresses price exposure, not operational failures.
Lee el texto editado por capítulos
Compute as a commodity
Kennon introduces cost curves and useful output.
I am Oliver Kennon, a research analyst at SemiAnalysis. A GPU delivers only as much as its operator can make of it: buying hardware provides potential, while operating capability determines the useful work delivered and its cost.
In a commodity market, producers compete to deliver comparable output. A cost curve orders them by the cost of doing so. At the same selling price, a lower-cost producer retains more margin and has more room to compete if prices fall.
For AI, the desired output is useful intelligence. Ideally we would measure cost per successfully completed task at the required quality. That is difficult to standardize today, so price per token can be a practical proxy when workloads and quality requirements are comparable.
GPU hours measure an input, not the output a customer receives. Hardware and electricity provide the inputs; software and operations affect how effectively those inputs become usable responses. Operators choose the serving software and keep requests flowing.
Same GPU, different output
A B200 example compares two complete serving configurations.
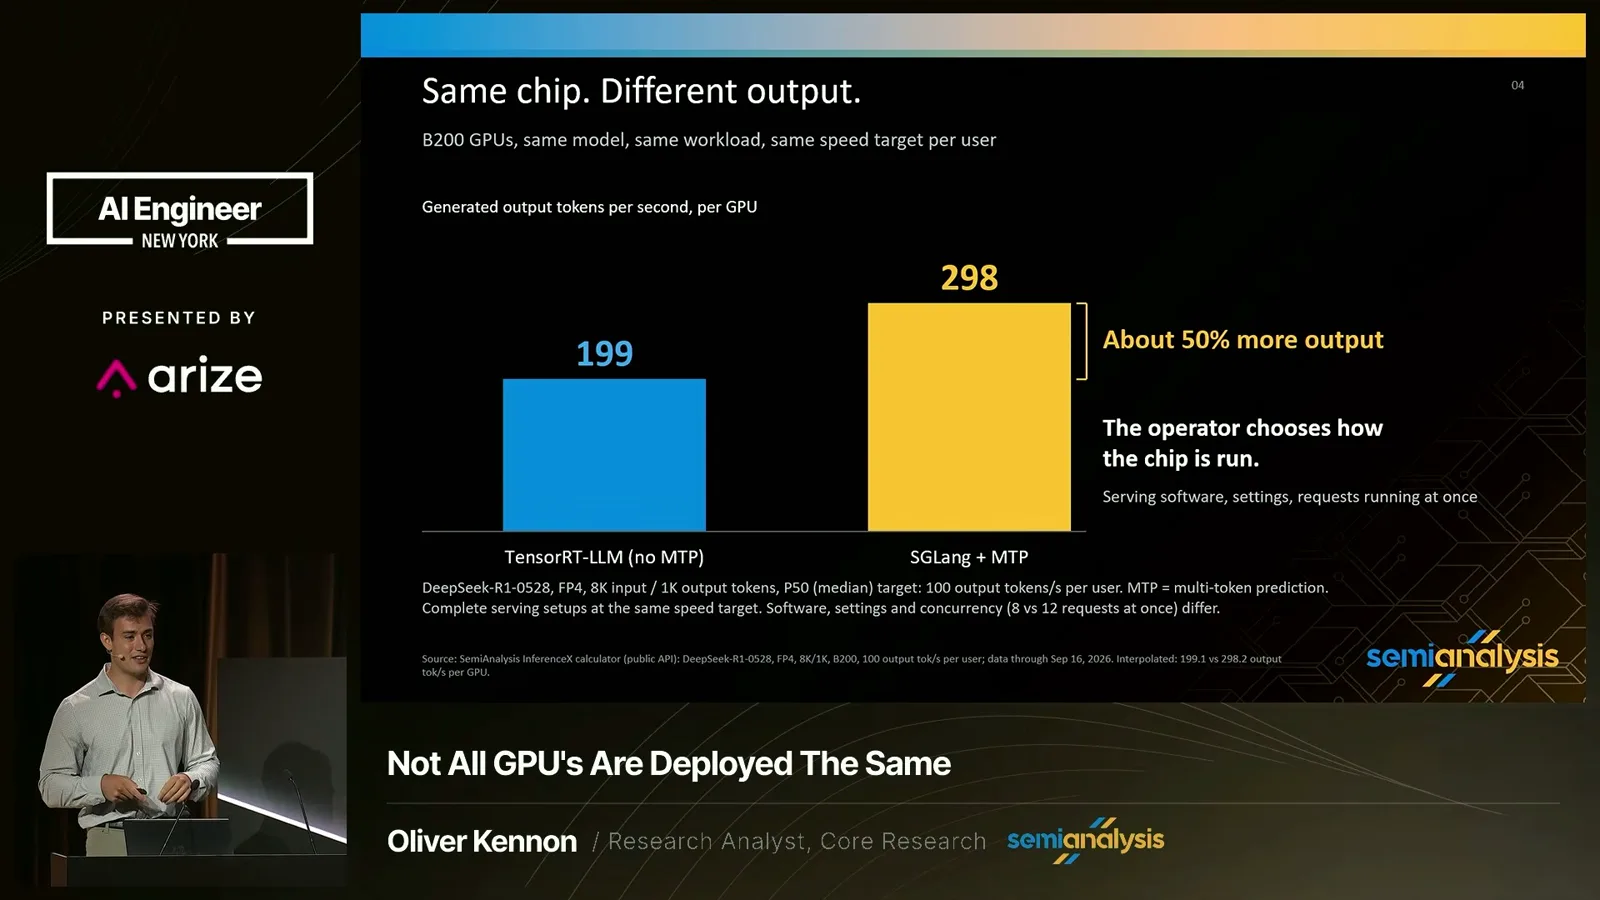
A SemiAnalysis InferenceX example uses B200 GPUs, DeepSeek-R1-0528, about 8,000 input and 1,000 output tokens, and a median per-user target of 100 output tokens per second. Two complete serving setups produce approximately 199 and 298 output tokens per second per GPU, respectively.
The comparison changes serving software, settings and concurrency together; it is not an isolated software-only experiment. Under these specified conditions, one setup produces roughly 50% more output at the same interactivity target. If hourly rental and requirements are equal, that lowers rental spending per acceptable token.
Quality, security and operation
Usable output requires reliability, security and ongoing operational work.
Useful output must meet the task’s quality requirements, arrive quickly enough, be available when needed and keep information within agreed access boundaries. Kennon says security is essential even though chip benchmarks do not capture it.
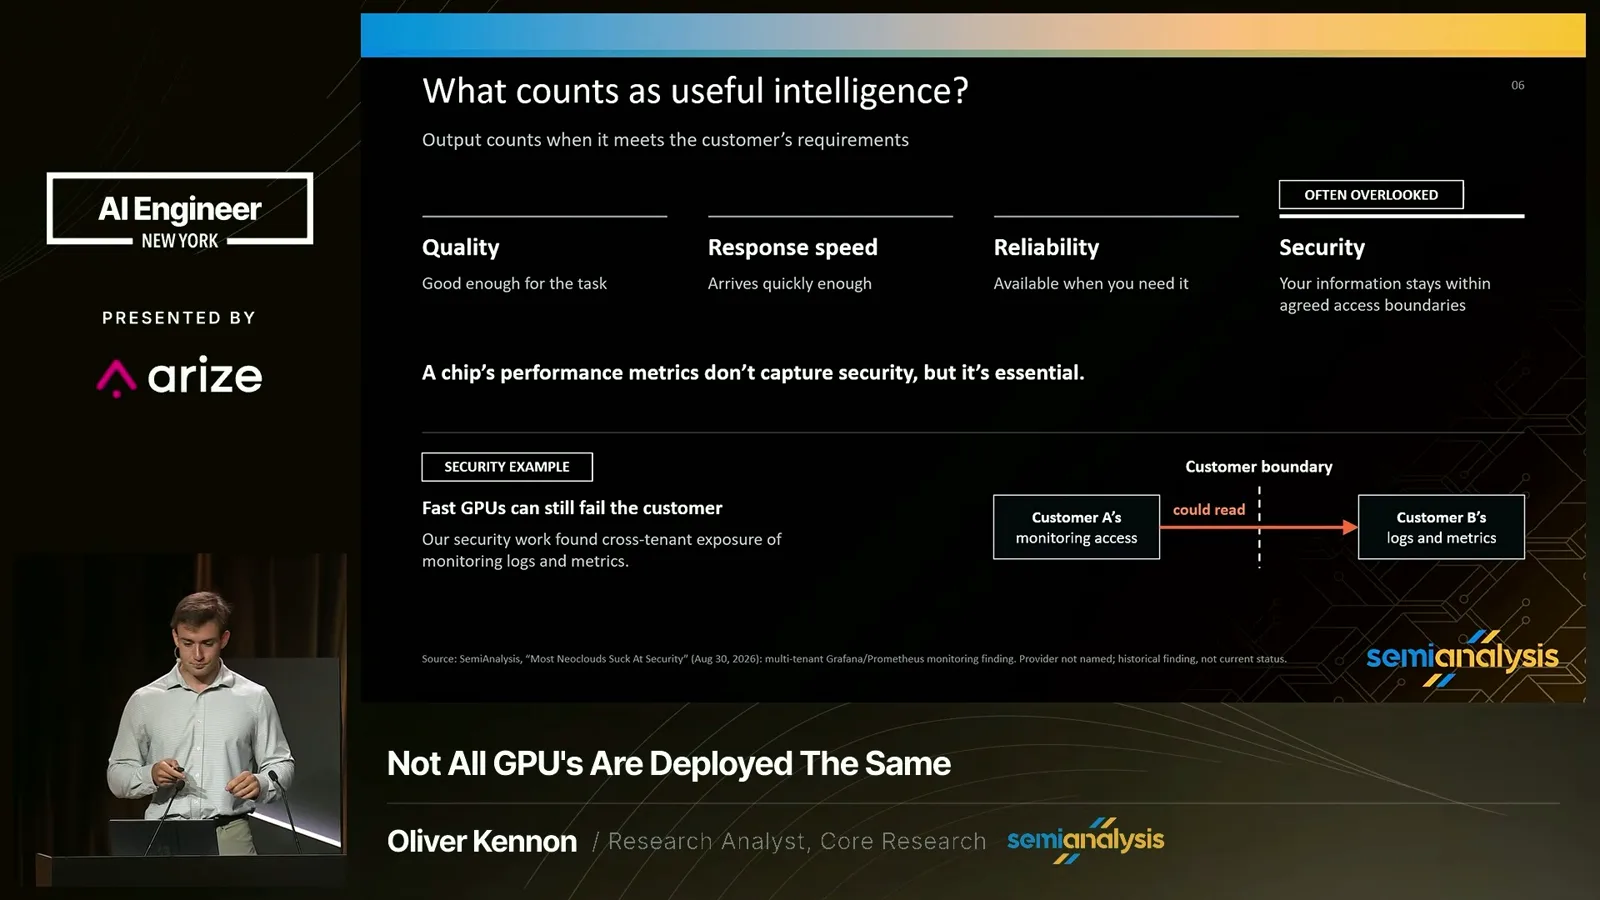
In a historical finding from SemiAnalysis security work, monitoring access exposed another customer’s logs and metrics. The example illustrates how a fast cluster can still fail a customer; the slide does not name the provider or establish its current status.
A faster serving update still requires someone to test real responses and load, check quality, deploy safely, keep a rollback path and maintain the service. These responsibilities may lie with the provider, the customer or both; the buyer needs to know who owns them.
SemiAnalysis’s ClusterMAX evaluates managed GPU-cluster operators on provisioning, reliability, monitoring and security, using hands-on tests, documentation and customer feedback. Kennon emphasizes that its relative ratings apply to managed clusters and cannot automatically be transferred to a provider’s bare-metal products.
Full costs and competition
Rental, production and competitive position must be distinguished.
Rental price and production cost describe different things. A GPU owner pays for equipment, power, space and support. An inference producer renting those GPUs has rent as an input cost, plus the software, staff and other services needed to deliver responses.
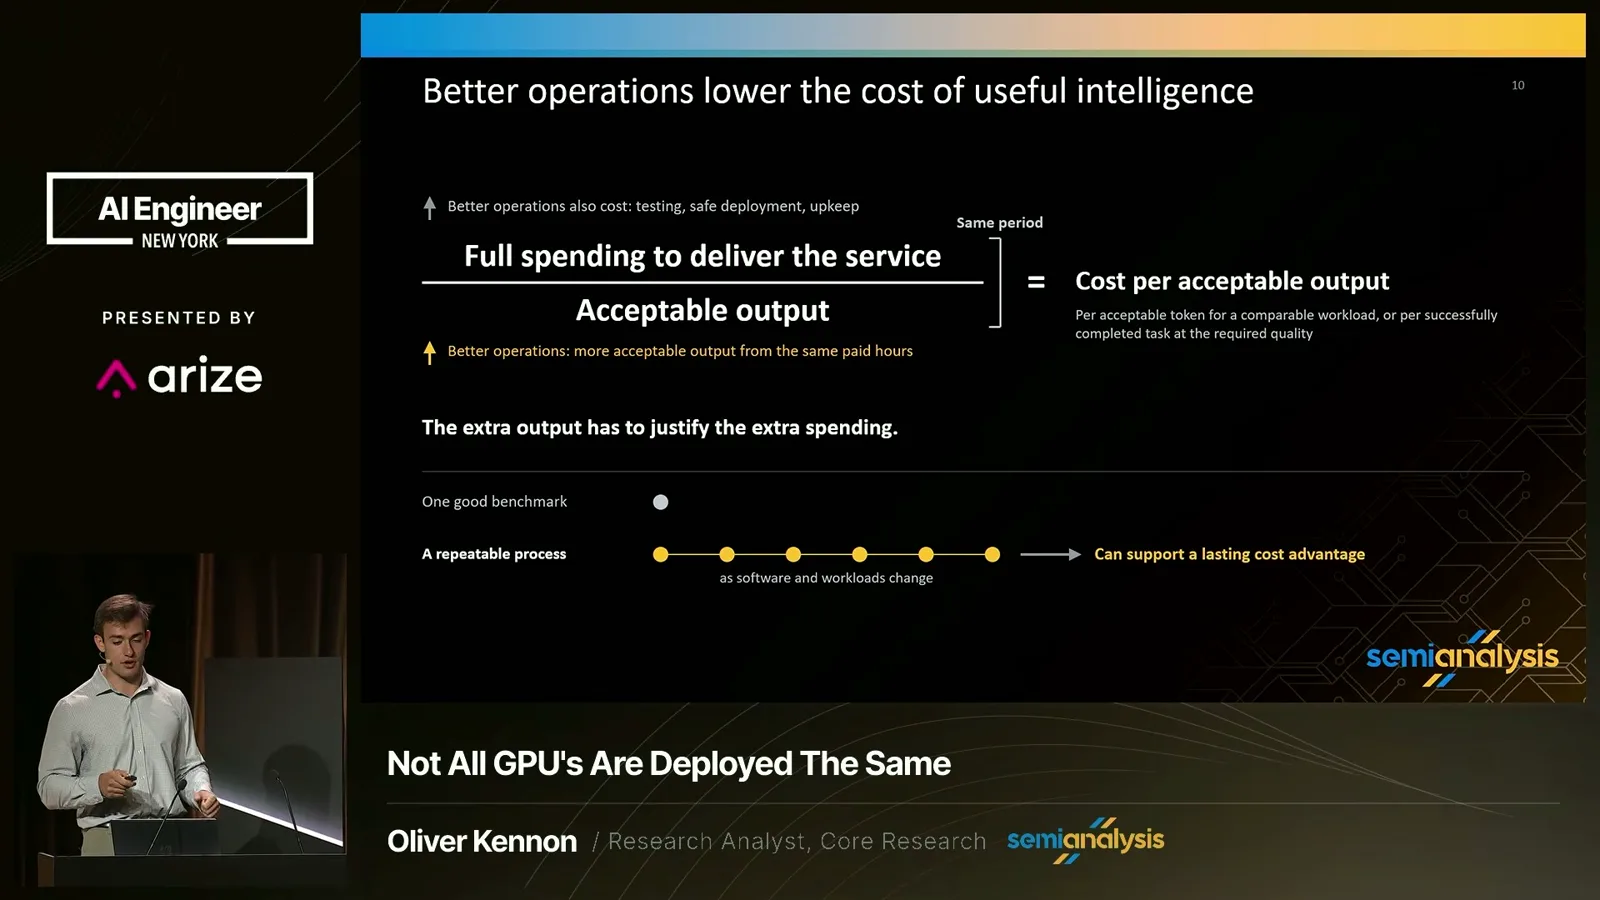
An owner-operated producer spreads equipment investment over its useful life and adds operating costs. In either case, full spending over a period must be divided by the acceptable output produced in that same period to compare the cost of useful work.
Better operations cost money too: testing, safe deployment and upkeep require staff and investment. Extra output must justify that expense. One good benchmark does not establish a durable advantage; teams have to repeat the process as workloads and software change.
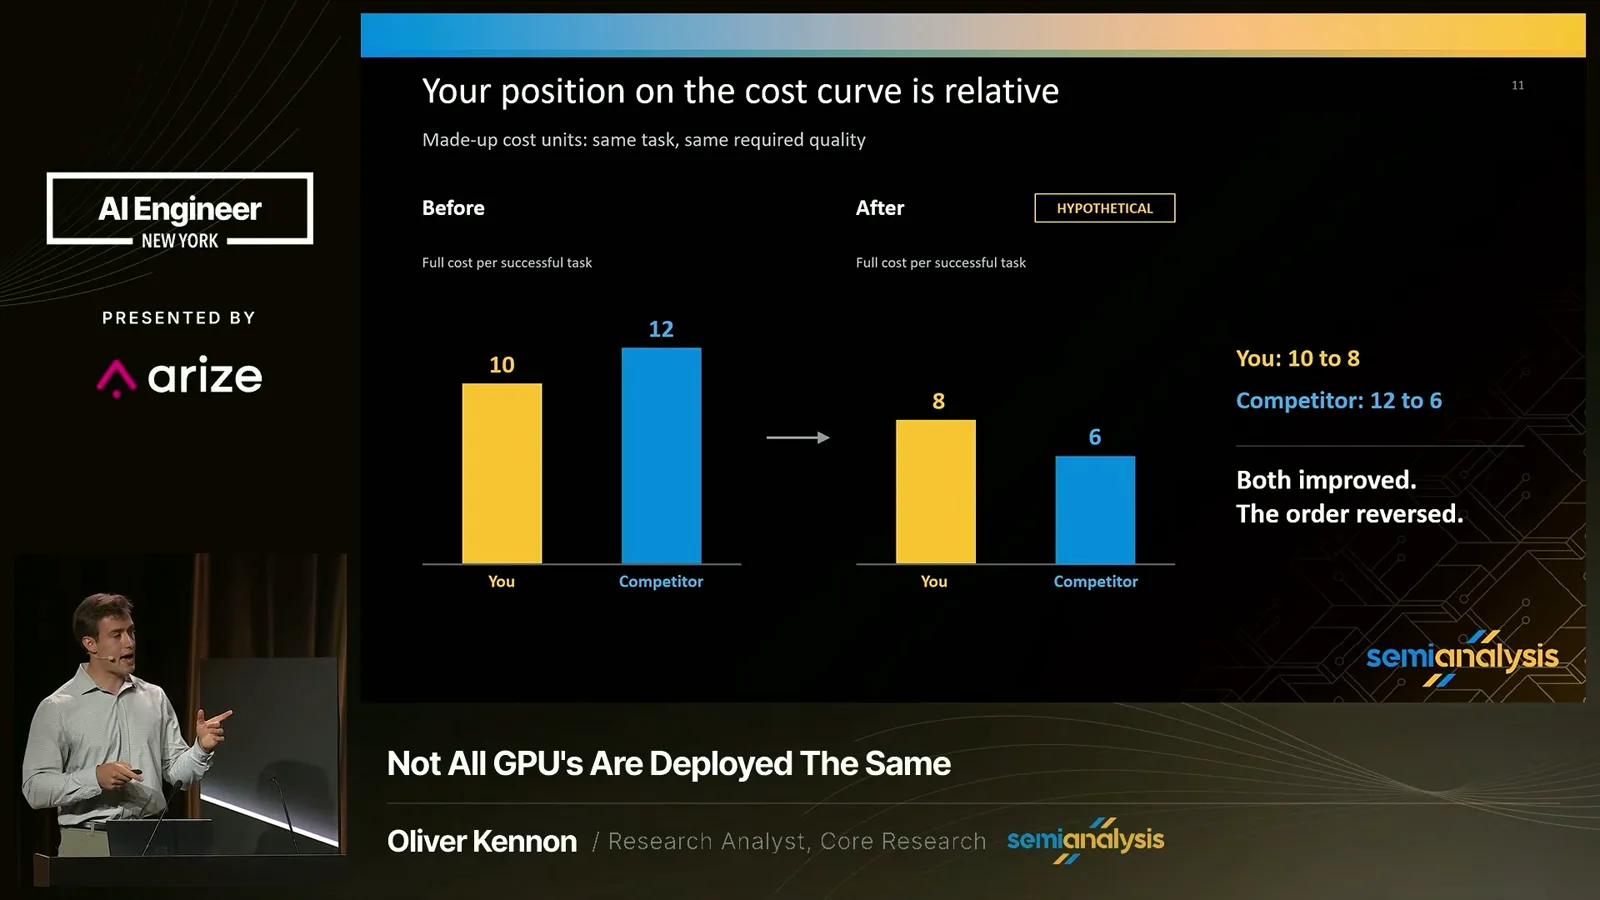
Cost-curve position is relative. In the slide’s hypothetical example, your cost per successful task falls from 10 to 8 while a competitor’s falls from 12 to 6. Both improved, but the competitor moved from more expensive to cheaper.
When demand exceeds supply, producers with different costs may all find customers, obscuring the difference. Kennon argues that companies, especially those with leverage, should build operating and cost advantages before price pressure intensifies; his view about the market cycle is a forecast.
Grades, benchmarks and futures
Kennon discusses comparable services and limits of rental-price hedging.
For compute to be compared like a commodity, buyers need a clear grade describing the service they receive. Two B200 rental offers may include different services and leave different operating work to the buyer. A grade does not make every form of intelligence interchangeable.
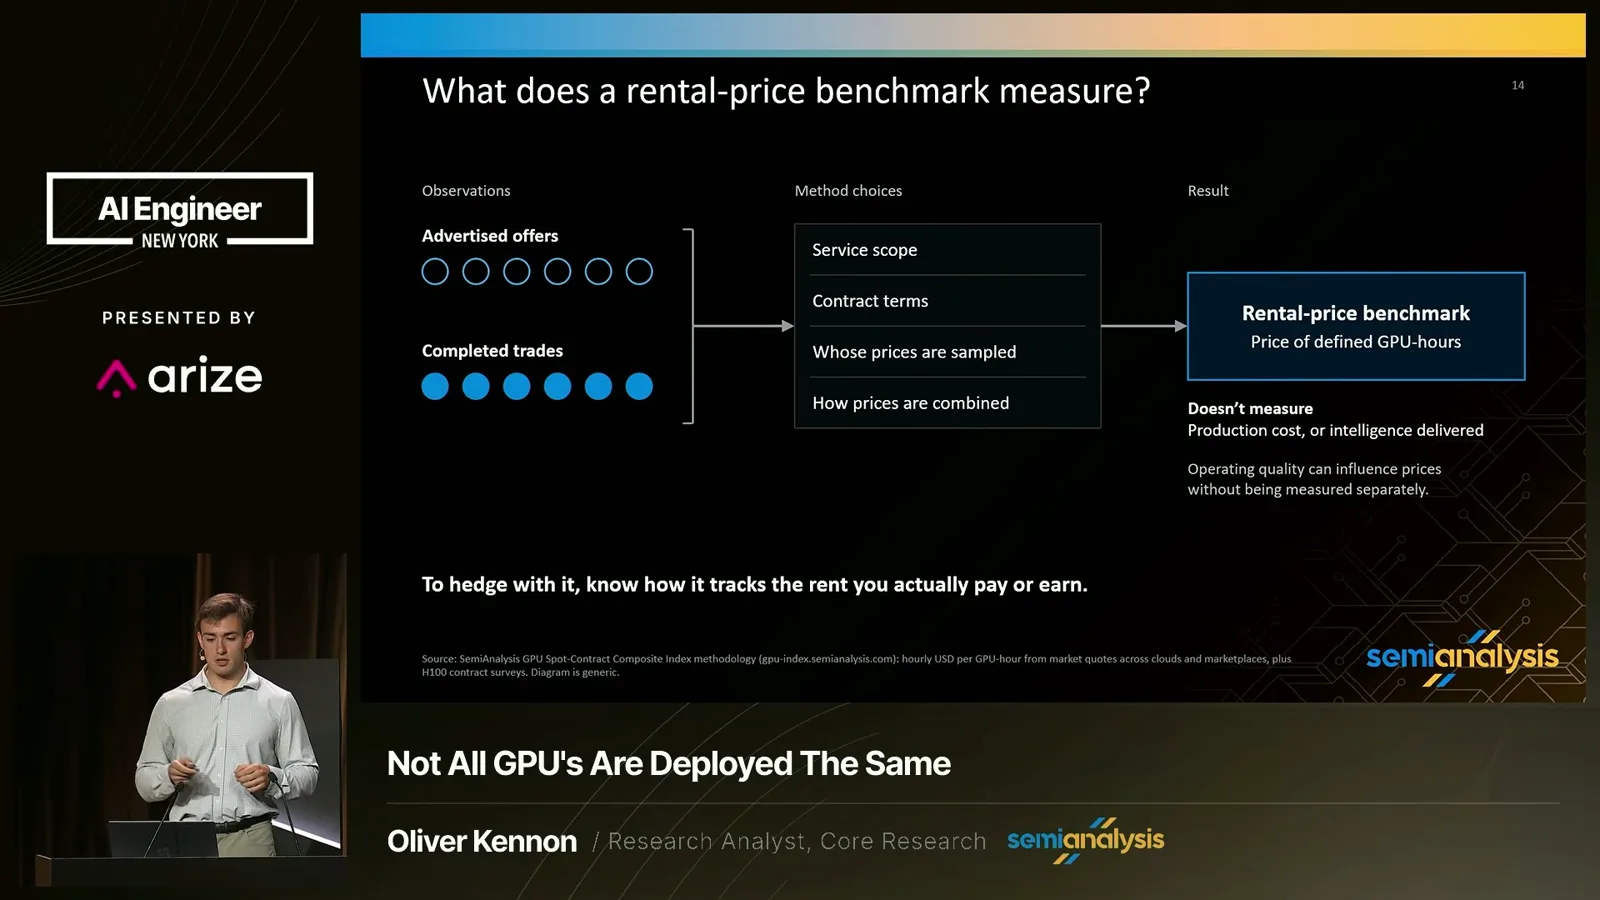
A rental-price benchmark summarizes GPU-hour prices in a defined market; it does not itself measure production cost or delivered intelligence. Its meaning depends on service scope, contract terms, the prices sampled and how those prices are combined. Advertised offers and completed trades are different observations.
A futures contract standardizes terms for future delivery or cash settlement against a reference price. Kennon argues operator assessment can inform a comparable service grade and a relevant rental-price benchmark, both useful building blocks for a credible compute futures market.
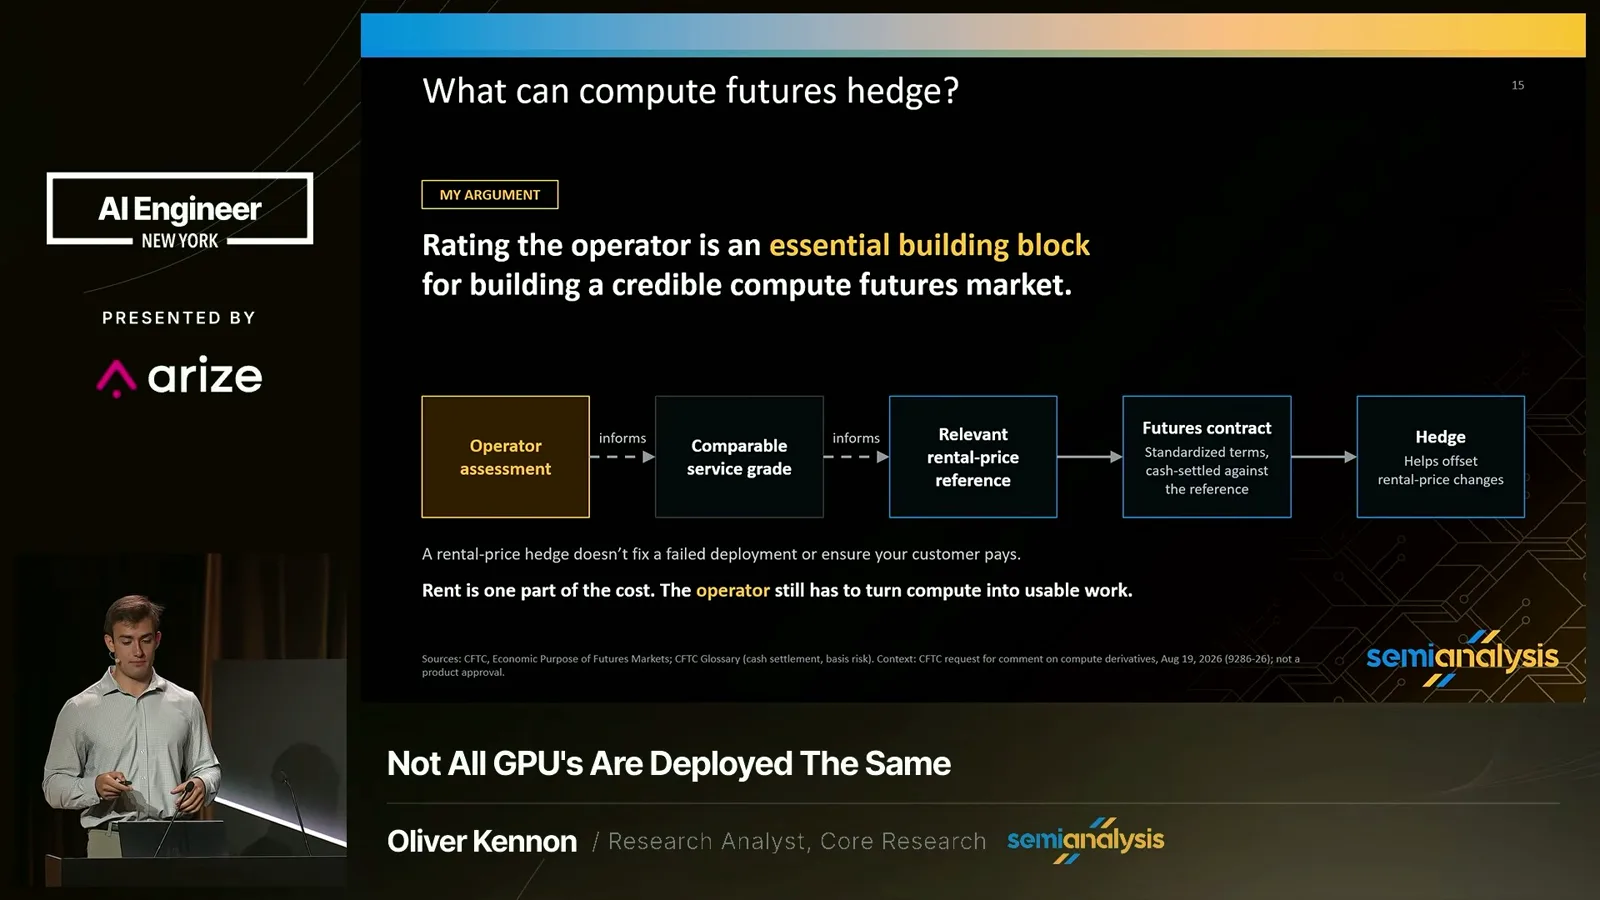
A rating alone does not define the grade, guarantee a sound benchmark or create liquidity. A rent-price hedge may offset rental price changes, but cannot repair a failed deployment or ensure a customer pays. Its effectiveness depends on how the reference moves relative to the actual rent.
The final measure is full spending per successfully completed task at the required quality. Operating capability changes both spending and useful output, and competitive position depends on whether rivals improve faster. Kennon urges buyers and producers to assess operators throughout the cycle.
Más de este canal
 21:32EN
 AI Engineer· 29 oct 2026Shy Ruparel on AI agent reliability and recovery after failuresShy Ruparel · TemporalTemporal’s survey finds a gap between frequent agent use and dependable deployment. Ruparel demonstrates a synthetic payout workflow that resumes after workers stop.
 14:50ENAI Engineer· 29 oct 2026Cole Gannaway on code review, cross-repository risk and AI software factoriesCole Gannaway · QodoA one-line rename can pass local checks while affecting distant clients. Qodo’s Cole Gannaway explains how review context, shared rules and independent agents can expose those risks.
 11:47ENAI Engineer· 29 oct 2026Revolut’s David Abitbol on self-hosting AI coding models at scaleDavid Abitbol · RevolutAbitbol shares engineering delivery trends, GPU-serving costs and latency tuning, then describes controls for operating the tools in a regulated bank.
 21:47ENAI Engineer· 28 oct 2026Patrick Smyth on Open-Source Supply Chain Security in the AI EraPatrick Smyth · ChainguardChainguard’s Patrick Smyth discusses faster exploitation, malware in dependencies, zero-days and the expanding attack surface around developer workflows.
 14:09ENAI Engineer· 28 oct 2026Taylor Luttrell-Williams on Finding Logic Vulnerabilities with SonarQube Hunter AgentTaylor Luttrell-Williams · SonarSonar’s Taylor Luttrell-Williams explains how a security agent maps a codebase, investigates logic flaws and presents validated findings alongside conventional scans.
 16:29ENAI Engineer· 28 oct 2026Chris Vela on Benchmarking vLLM Configurations with Runpod BenchPodChris Vela · RunpodRunpod’s Chris Vela demonstrates a dashboard for comparing LLM serving configurations and choosing performance settings with workload-specific data.