Gemini 3's Launch: Benchmarks, Antigravity, and Agents

Matthew Berman summarizes Google's November 2025 model launch and its developer and assistant demos.

MBMatthew BermanPonente · Forward Future
Canal
Matthew Berman
Publicado
18 nov 2025
Vídeo
1:11
Lectura
1 min
Diapositivas
2
Original
inglés
Abrir en YouTube
Al desplazarte, el vídeo se reduce a la esquina inferior derecha y sigue reproduciéndose. Los subtítulos siguen tu idioma de lectura.
Idioma de lecturaDisponible en 2 idiomas
Este artículo aún no está en español, así que se muestra el original en inglés.
RESUMEN

En 30 segundos

Matthew Berman reviews Gemini 3's launch-era benchmark claims, Google Antigravity, and an assistant demonstration for organizing email. The short video describes initial features and availability; rankings, access, pricing, and limits can change, and benchmark scores depend on test conditions.

  1. 1Launch benchmarksBerman cites strong results including a perfect AIME 2025 score; such a number requires the exact model and evaluation conditions and is not a universal capability claim.
  2. 2AntigravityGoogle's development platform lets users coordinate coding agents; its free preview and quotas were launch-time details.
  3. 3Assistant workflowsA demo shows an agent proposing ways to organize an inbox for the user to review.

Conclusiones

  1. Gemini 3's launch included benchmark results and a multimodal context window.
  2. Google introduced Antigravity as an agent-oriented development environment.
  3. A Gemini Agent demo showed proposed email organization for user review.
  4. Launch-era scores and availability should not be assumed to describe current products.
TEXTO COMPLETO

Lee el texto editado por capítulos

Solo la transcripción
01

Gemini 3 and benchmarks

Berman summarizes model performance reported at launch.
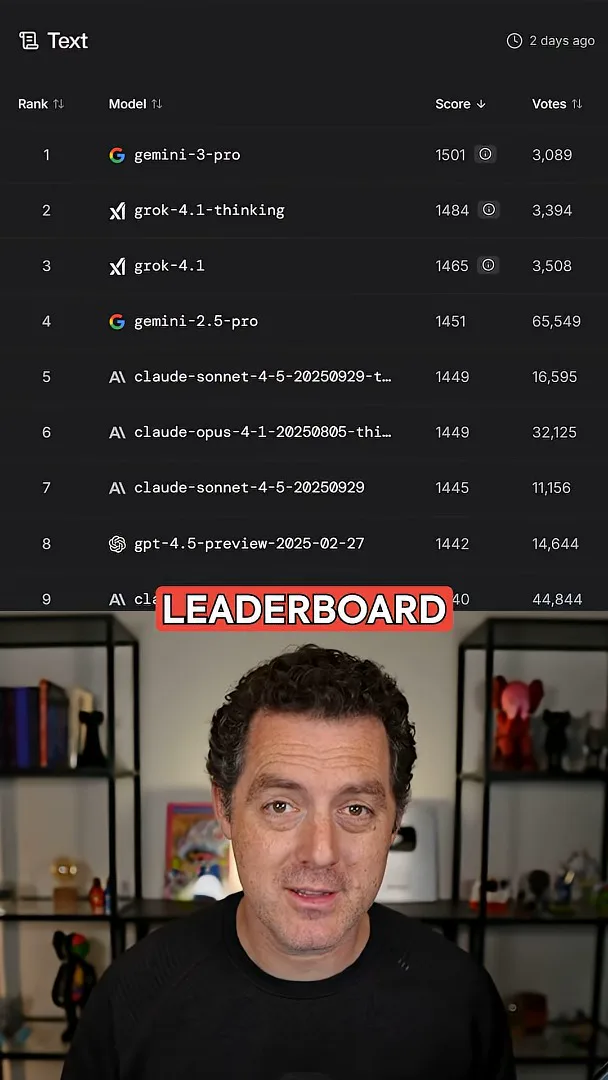
Launch-era model leaderboard
DIAPOSITIVA 1 / 2Launch-era model leaderboardThe displayed ranking reflects a particular leaderboard snapshot, not a permanent ordering.

In November 2025, Matthew Berman introduces Google's Gemini 3 and points to launch-era leaderboard and math benchmark results. He cites a perfect AIME 2025 score; benchmark results depend on the model variant, settings, and tools, and do not establish that a model is best at every task. Google's later comparison lists Gemini 3 Pro at 95.0% on AIME 2025 without tools.

02

Antigravity and agents

He describes Google's development platform and an email organization demo.
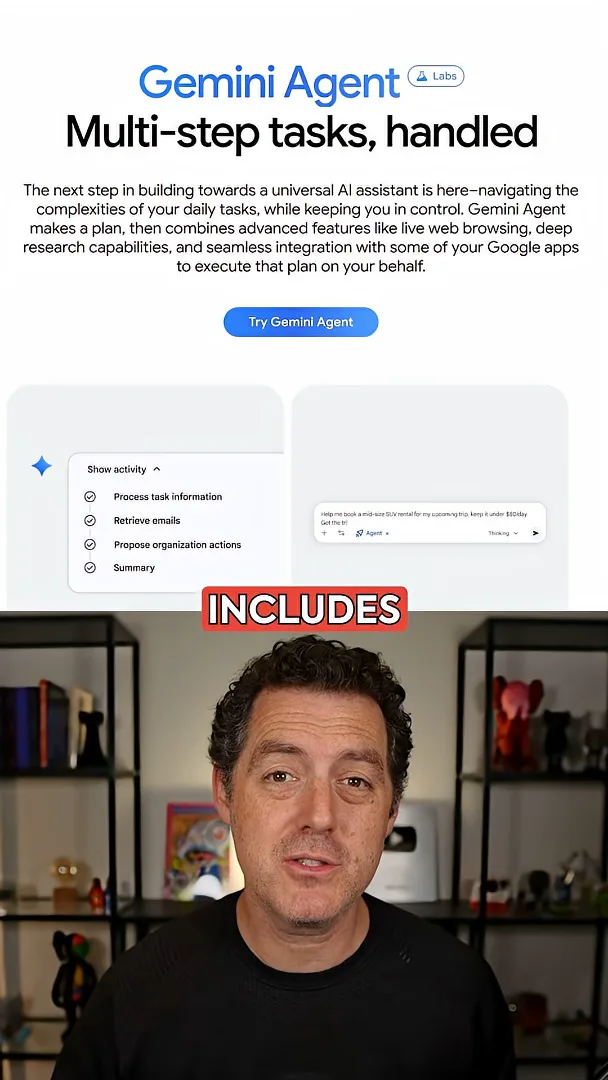
Gemini Agent demonstration
DIAPOSITIVA 2 / 2Gemini Agent demonstrationThe launch page describes an assistant that plans multi-step tasks with user control.

Berman also highlights Google Antigravity, a development environment designed around coding agents. He says Gemini 3 Pro was available in its free preview at the time. Pricing, quotas, and availability can change, so this historical description is not a current offer.

A Gemini Agent example shows an assistant proposing ways to organize an email inbox, with the user reviewing suggested actions. Berman also cites a one-million-token input context and 64,000-token output limit for the launch model, plus text, image, video, code, and audio inputs. Actual capabilities and limits depend on the specific product and model version.

Más de este canal

6 diapositivas25:50EN
MBMatthew Berman· 24 oct 2026Kimi K3.1 Pro Tested: Strong 3D Demos, Uneven Results and Competitive PricingMatthew Berman · Forward FutureMatthew Berman tests the open-weight model on coding, 3D rendering and visual explanations, then compares benchmark results and prices.Open-weight modelsBenchmarksAI cost & performance+1
2 diapositivas32:20EN
MBMatthew Berman· 23 oct 2026Who Is Local AI For? The Costs, Trade-offs and a Hybrid FutureMatthew Berman · Forward FutureMatthew Berman weighs data control and independence against hardware cost, setup complexity and inference speed.Local inferenceOpen-weight modelsAI cost & performance+1
45:08EN
MBMatthew Berman· 21 oct 2026Sam Altman on AI Discovery, Consciousness, Compute and a Human-Centered FutureMatthew Berman, Sam Altman · Forward FutureIn a conversation with Matthew Berman, Altman discusses scientific progress, personal assistants, recursive self-improvement and the importance of human agency.AI for sciencePersonal agentsConsciousness+2
0:32EN
MBMatthew Berman· 21 oct 2026Sam Altman on the Continuing Demand for Software WorkSam Altman, Matthew Berman · OpenAIIn a short interview excerpt, Altman says demand for software may be larger than expected even as AI changes how it is made.Future of WorkSoftware engineeringAgentes de programación
5 diapositivas12:14EN
MBMatthew Berman· 14 oct 2026Gemini 4 Argon Tested: 3D Demos, a Spreadsheet Prototype and Benchmark ResultsMatthew Berman · Forward FutureMatthew Berman tests Google’s model on games and visual projects, then compares reported coding and agent benchmarks.GeminiBenchmarksAgentes de programación+1
5 diapositivas10:36EN
MBMatthew Berman· 13 oct 2026Meta Muse Wonder Tested: Strong Benchmarks, Mixed Demos and Quota FrictionMatthew Berman · Forward FutureMatthew Berman tests Meta’s models on browser demos and reviews their published benchmark scores, availability and cost.Modelos y entrenamientoBenchmarksAI cost & performance+1