In 30 seconds
Bridgewater’s Sam Green and Aaron Linsky describe the Vault, a shared platform for internal and external research. They explain how a small relevance benchmark, fast metadata filtering, and familiar workflows helped serve both investors and AI agents. They also show research assistants and an investor workbench designed to surface material proactively. Their performance and productivity figures are examples from Bridgewater’s own work, not independent evidence of investment returns.
- 1A shared research corpusThe Vault contains roughly 100 million documents from 135 external sources and internal research, indexed with concepts, countries, markets and time.
- 2Measure search qualityBridgewater assembled about 200 human-judged examples. Linsky says improvements raised precision at ten from roughly 60% to 90–95% on that internal benchmark.
- 3Filter without losing speedThe team compared post-filtering and pre-filtering, then used native filtering to search relevant clusters while applying metadata constraints.
- 4Fit existing habitsEmail subscriptions became saved searches and folders became collections, giving researchers familiar ways into the shared corpus.
- 5From reactive to proactiveThe investor workbench surfaces topics and supporting evidence so people can investigate what might deserve attention.
Takeaways
- Organizing unstructured research with consistent metadata gives both people and agents a usable shared corpus.
- Human search needs high precision; agents also need high throughput and access to appropriately permissioned sources.
- A small, manually judged benchmark can make vague complaints about search quality measurable.
- Bring existing user habits into a new system before asking people to adopt unfamiliar workflows.
- Proactive agents can surface evidence for investors while leaving decisions to people.
Read the edited text by chapter
Why Bridgewater built the Vault
Green introduces three lessons and the firm’s long-standing research process. The Vault applies similar discipline to unstructured information.
Sam Green introduces three lessons from building the Vault: people and agents need different things from data; a shared tool can serve both; and agents can move beyond answering questions to bringing investors material that deserves attention.
Green says Bridgewater has spent roughly 50 years developing and recording its understanding of markets. Researchers try to make the reasoning behind decisions explicit as if-then rules, so that ideas can be tested, discussed and carried forward rather than remaining in one person’s head.
The firm has long treated structured economic and market data as a carefully managed asset. Its artificial investment associate, AiA, creates a need to apply comparable discipline to unstructured information: research notes, documents, conversations and external analysis.
Simply giving a model access to documents is not enough. Green describes cleaning, organizing, securing and indexing the material so that researchers and agents can find the relevant evidence and understand when it was available.
A time-aware research corpus
Green describes the documents and metadata in the Vault and compares an open-web answer with a time-filtered internal search.
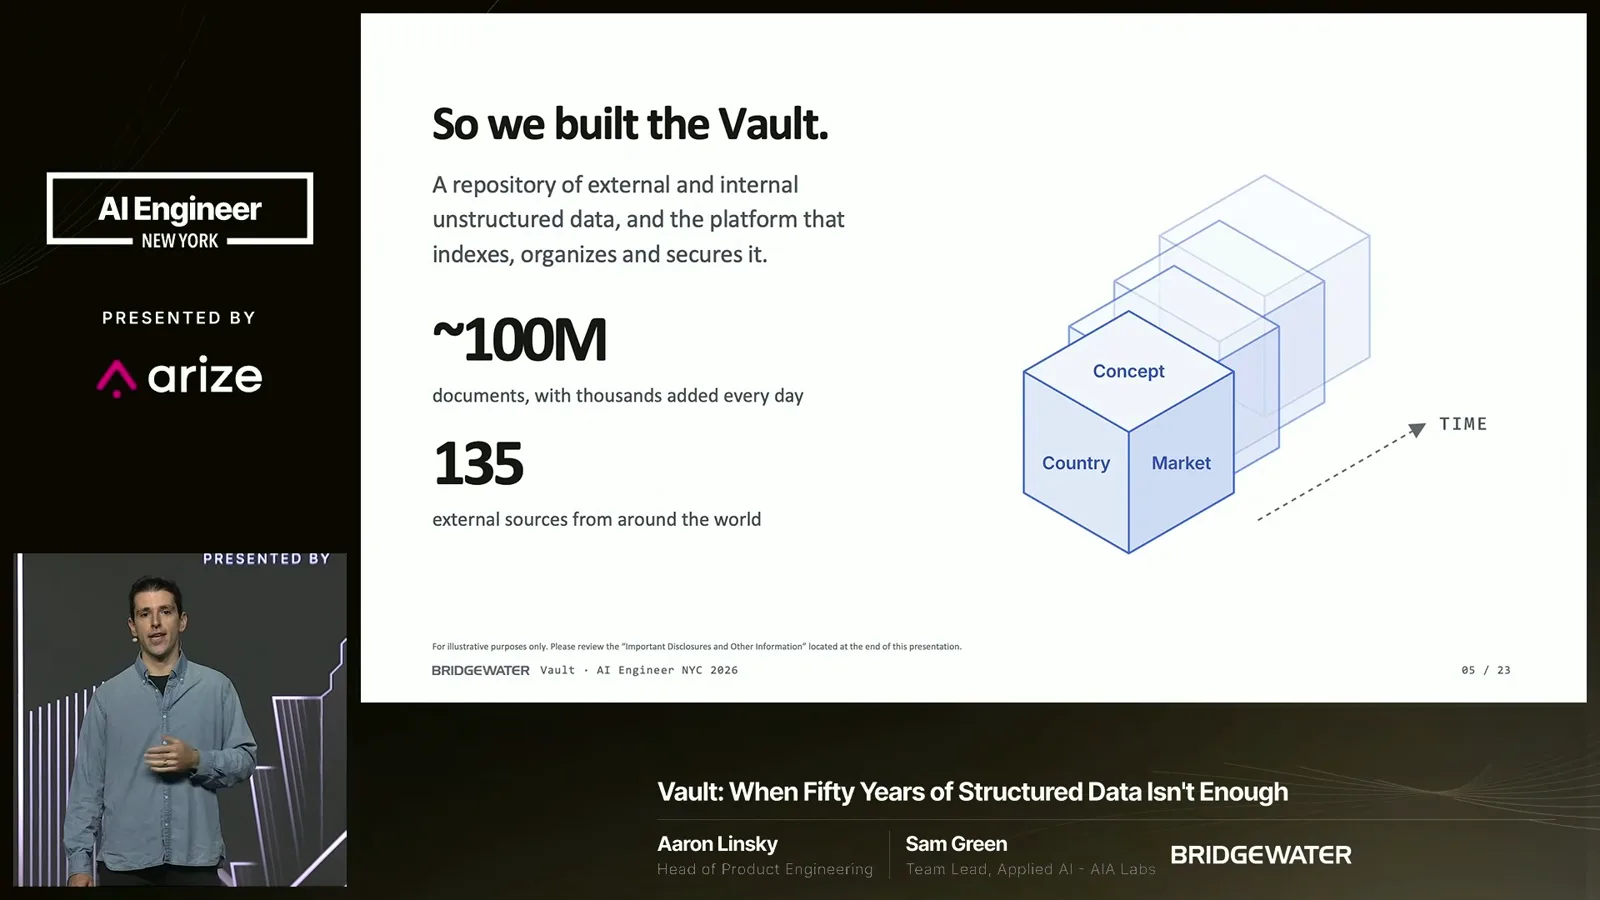
The resulting Vault holds about 100 million documents, with thousands more added daily, from 135 external sources as well as Bridgewater’s own work. It organizes material by concepts, countries, markets and time, making a large collection searchable within a common framework.
Green illustrates the difference with a question about AI infrastructure investment and the Korean won. An open-web search finds a collection of sources, but only a small number are used in the resulting answer, and the timing of the information matters to the investment question.
The same question against the Vault can include a specific window, October 1 through 8. Green says the system found 52 candidates and used seven, enabling an answer grounded in the relevant period. This is an example of the team’s workflow, not a controlled demonstration of superior investment returns.
Search for people and agents
Linsky explains precision, a human-labeled benchmark, filtering tradeoffs, and the greater throughput demanded by agents.
Aaron Linsky takes up the first lesson: people and agents use the same data differently. A human wants a short list with highly relevant results, while an agent may run many searches rapidly, examine more material and combine the results into an answer.
When users complained that Vault search was bad, the team needed a way to turn that judgment into something actionable. Linsky says they collected real questions and manually identified good and bad documents, producing roughly 200 examples in less than a week.
On that internal benchmark, Linsky says precision at ten was initially around 60%. By measuring and improving the search system, the team brought it to roughly 90–95%. The benchmark made it possible to compare changes against a concrete set of user needs.
Metadata filtering introduces a speed and recall tradeoff. Searching first and filtering afterward is fast but can discard many of the top results; filtering first can preserve eligible results but make the search slower. Time constraints make this particularly relevant to investment research.
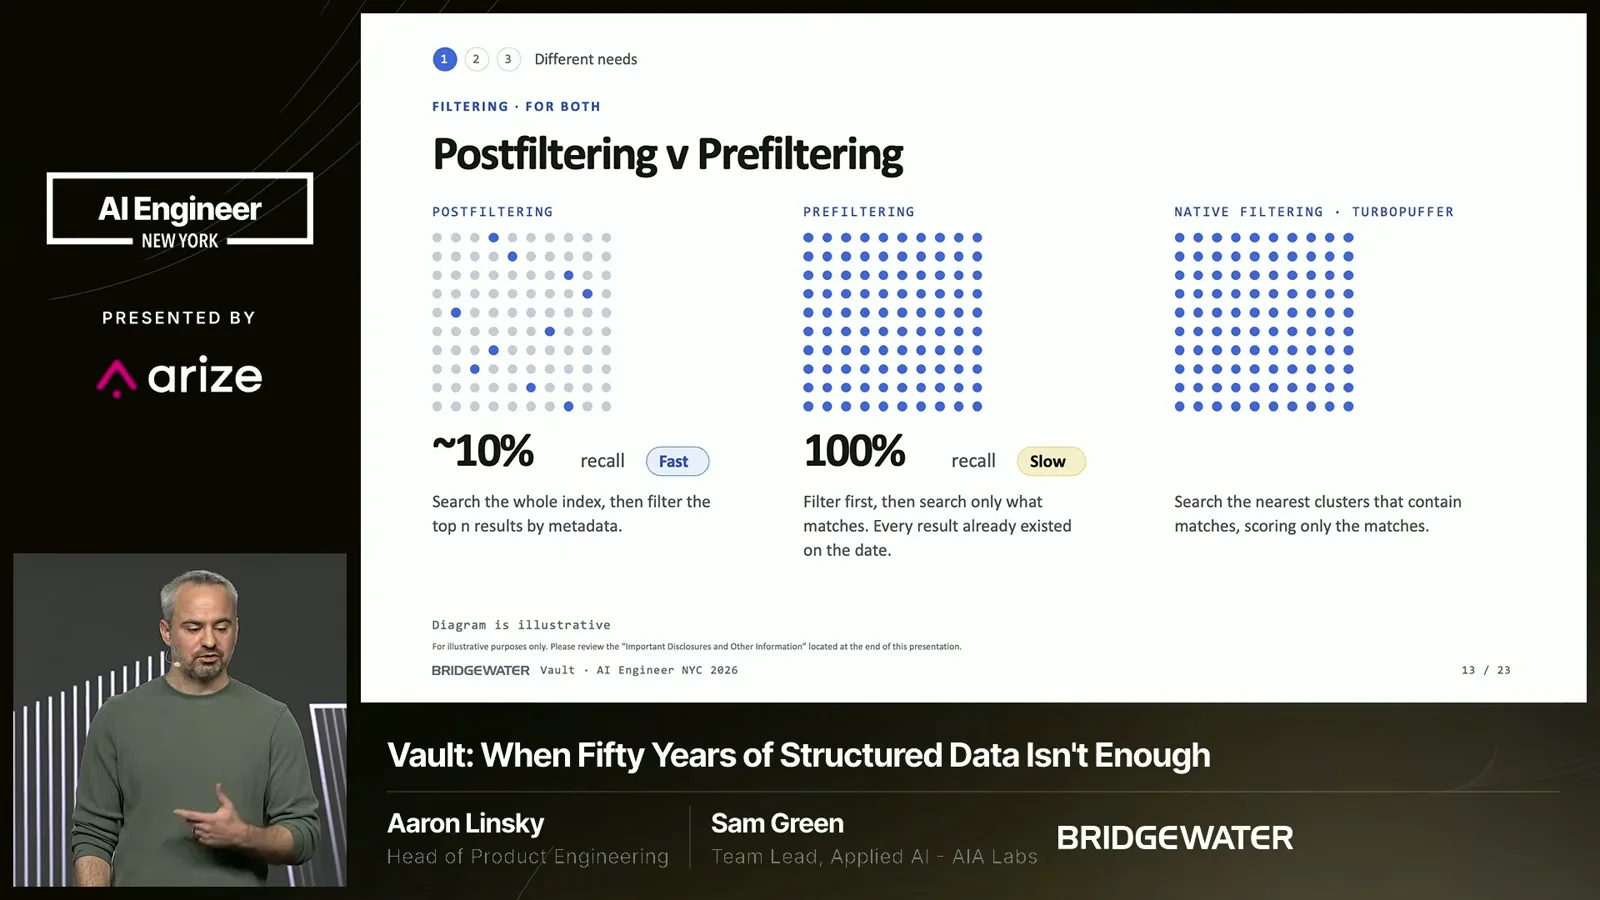
Linsky says the team moved to Turbopuffer’s native filtering, which searches nearby clusters containing eligible matches and scores those matches. The aim is to retain useful recall without making every constrained query prohibitively slow.
Scale also changes with the user. Linsky contrasts roughly 100 searches an hour by 300 human users with agents potentially issuing hundreds of searches a second. Access control remains part of the problem: an agent should work with the information its user is entitled to see.
One tool for both audiences
The team ported familiar email habits into the Vault and integrated it into the places people and agents work.
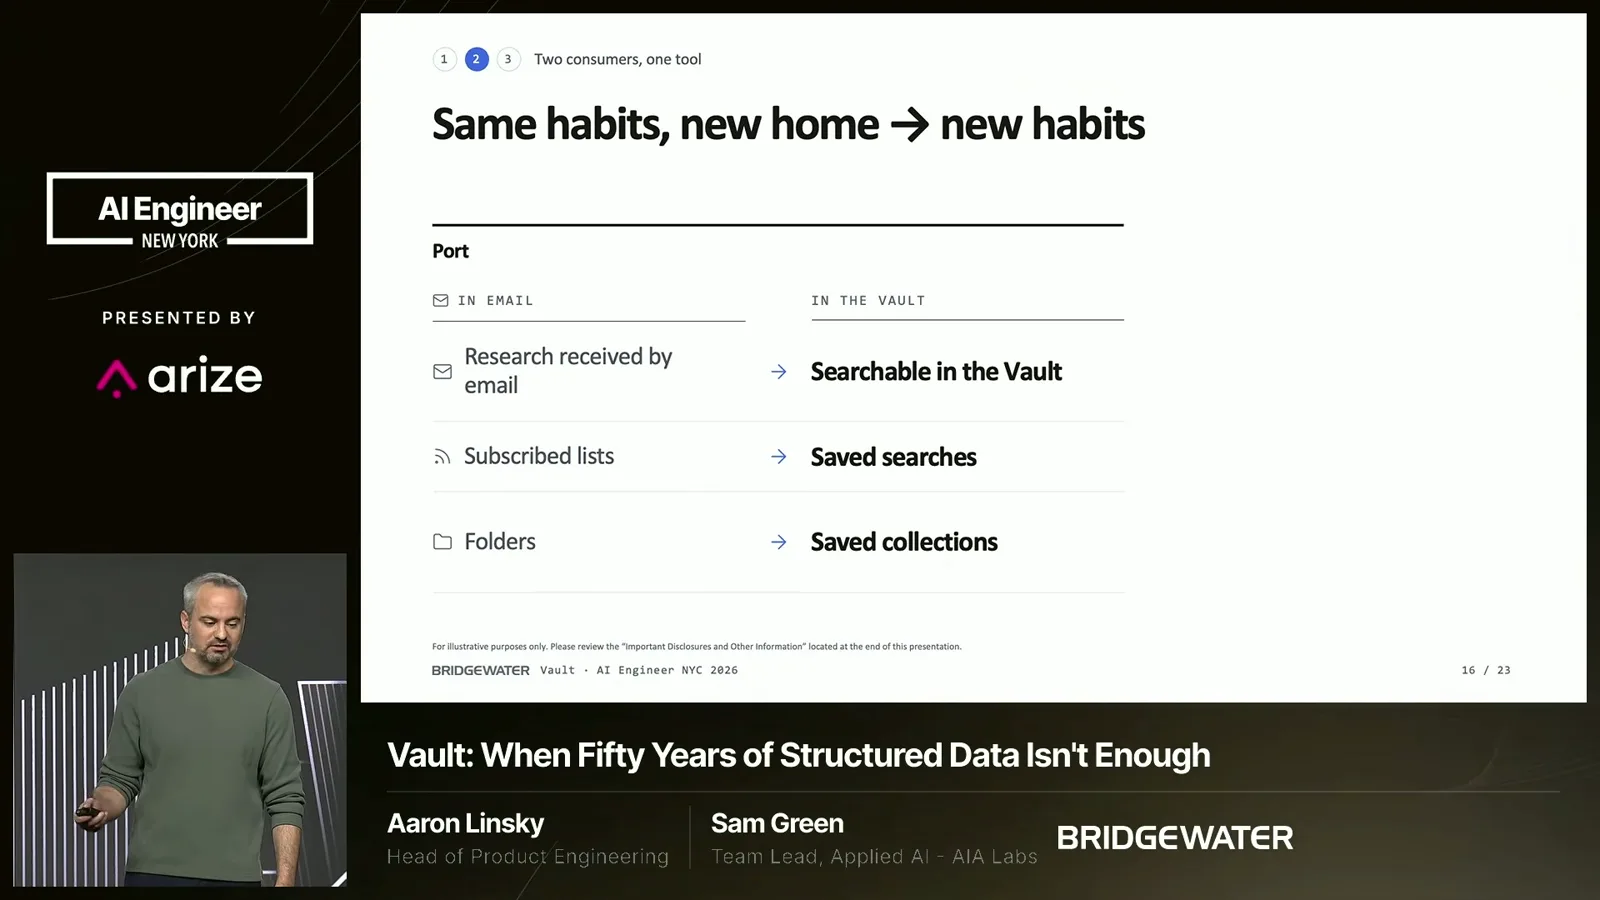
A good backend does not automatically change habits. Researchers were accustomed to receiving reports in email, subscribing to lists and keeping folders. The team mirrored those habits in the Vault with searchable research, saved searches and saved collections.
Once people had a familiar place to work, the team could add feeds and make the same corpus available through other tools. Linsky describes connections to chat, mobile, Slack, IDEs and the command line, so both people and agents could use it in their existing workflows.
Research assistants and proactive work
The speakers describe analysts, forecasting, signals and an investor workbench. They close with the way new research can feed back into the corpus.
Linsky describes a pocket analyst that can assemble research in minutes for a few dollars, according to the firm’s experience, and a researcher that works across days or weeks. The same foundation also supports forecasting and signal-related work. These are the speakers’ examples, not a guarantee of future results.
Green returns to the third lesson: agents can be proactive. Instead of waiting for an investor to formulate every question, the investor workbench looks for themes that might matter, presents a synthesis and supplies the underlying evidence for further investigation.
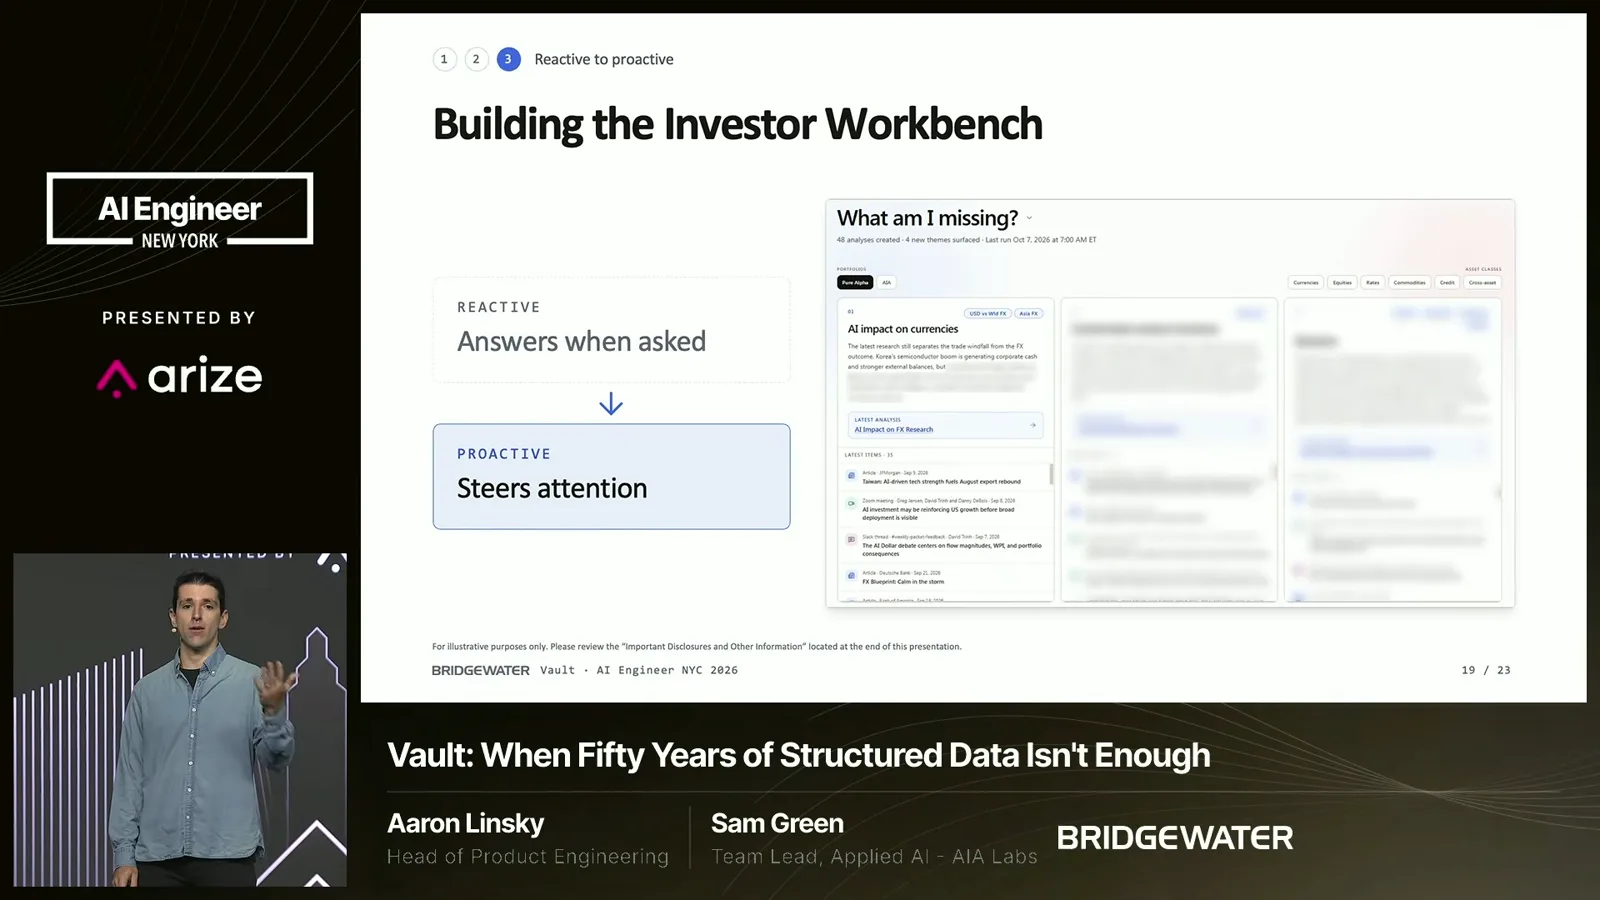
The workbench is meant to help answer “What am I missing?” Green shows how a topic can be connected to recent research, meetings and other source material. The investor can inspect the supporting documents and decide what deserves more attention.
Green closes with a feedback loop: research and syntheses created using the Vault can become part of the corpus themselves. As the firm adds and organizes what it learns, subsequent people and agents can build on that accumulated institutional knowledge.
More from this channel
 21:32EN
 AI Engineer· Oct 29, 2026Shy Ruparel on AI agent reliability and recovery after failuresShy Ruparel · TemporalTemporal’s survey finds a gap between frequent agent use and dependable deployment. Ruparel demonstrates a synthetic payout workflow that resumes after workers stop.
 14:50ENAI Engineer· Oct 29, 2026Cole Gannaway on code review, cross-repository risk and AI software factoriesCole Gannaway · QodoA one-line rename can pass local checks while affecting distant clients. Qodo’s Cole Gannaway explains how review context, shared rules and independent agents can expose those risks.
 11:47ENAI Engineer· Oct 29, 2026Revolut’s David Abitbol on self-hosting AI coding models at scaleDavid Abitbol · RevolutAbitbol shares engineering delivery trends, GPU-serving costs and latency tuning, then describes controls for operating the tools in a regulated bank.
 21:47ENAI Engineer· Oct 28, 2026Patrick Smyth on Open-Source Supply Chain Security in the AI EraPatrick Smyth · ChainguardChainguard’s Patrick Smyth discusses faster exploitation, malware in dependencies, zero-days and the expanding attack surface around developer workflows.
 14:09ENAI Engineer· Oct 28, 2026Taylor Luttrell-Williams on Finding Logic Vulnerabilities with SonarQube Hunter AgentTaylor Luttrell-Williams · SonarSonar’s Taylor Luttrell-Williams explains how a security agent maps a codebase, investigates logic flaws and presents validated findings alongside conventional scans.
 16:29ENAI Engineer· Oct 28, 2026Chris Vela on Benchmarking vLLM Configurations with Runpod BenchPodChris Vela · RunpodRunpod’s Chris Vela demonstrates a dashboard for comparing LLM serving configurations and choosing performance settings with workload-specific data.