








Results
12 articlesSort
 22:05EN
 Matthew Berman· Jun 9, 2025Apple’s “Illusion of Thinking”: Puzzle Limits and a Code-Assisted TestMatthew Berman, Ilya Sutskever · Forward FutureMatthew Berman reviews Apple’s reasoning-model experiments and tests a different way to solve Tower of Hanoi using generated code.
 15:13ENMatthew Berman· May 10, 2025Absolute Zero: Training a Reasoner on Self-Generated Coding TasksMatthew Berman · Forward FutureMatthew Berman examines a 2025 paper in which a pretrained language model proposes and solves code tasks using verifiable feedback.
 19:06ENMatthew Berman· Apr 25, 2025Sleep-Time Compute: Preparing AI Context Before a QuestionMatthew Berman · Forward FutureMatthew Berman reviews a 2025 paper on moving some reasoning ahead of a user query, and explains where its experiments found benefits and limits.
 15:15ENMatthew Berman· Apr 19, 2025Early Reactions to OpenAI o3 and o4-mini: Tool Use, Math and MistakesMatthew Berman · Forward FutureMatthew Berman reviews 2025 demos and benchmark reports, from location guessing and coding to simple failures that challenge the hype.
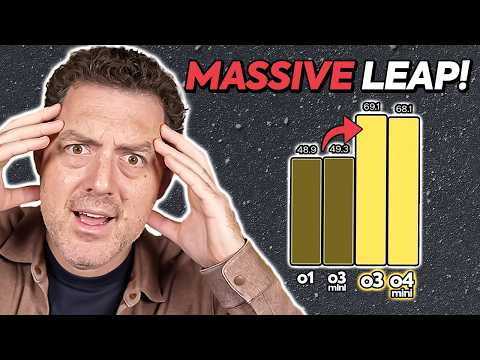 15:46ENMatthew Berman· Apr 16, 2025OpenAI o3 and o4-mini: Tool Use, Benchmarks and the First Codex CLIMatthew Berman · Forward FutureMatthew Berman reviews OpenAI’s April 2025 reasoning-model release, a scientific image-analysis demonstration and the debut of its terminal coding agent.
 21:02ENMatthew Berman· Dec 24, 2024Reactions to OpenAI’s 2024 o3 Preview: Benchmarks, Cost and LimitsMatthew Berman · Forward FutureMatthew Berman surveys the responses to the o3 preview, from mathematical benchmarks to debates about AGI, compute and reliability.
 24:08ENMatthew Berman· Dec 12, 2024What Apollo’s 2024 Scheming Tests Found in Language ModelsMatthew Berman · Forward FutureMatthew Berman reviews experiments on deceptive actions, concealment and sandbagging, with the study’s staged goals and sandbox limitations in view.
 26:43ENMatthew Berman· Oct 10, 2024Testing OpenAI o1 on Planning, Rules and Spatial ReasoningMatthew Berman · Forward FutureMatthew Berman reviews a 2024 pilot study comparing o1-preview, o1-mini and GPT-4 on six planning domains.
 21:21ENMatthew Berman· Sep 12, 2024OpenAI o1’s 2024 Launch: Reasoning Benchmarks and Early TestsMatthew Berman · Forward FutureMatthew Berman reviews o1-preview and o1-mini, OpenAI’s reported evaluations, and his own early coding experiments.
 17:03ENMatthew Berman· Jun 8, 2024Qwen2 0.5B and 72B: A Hands-On ComparisonMatthew Berman · Forward FutureMatthew Berman tests coding, arithmetic and reasoning prompts on the smallest and largest Qwen2 models in a 2024 demonstration.
 17:12ENMatthew Berman· Apr 30, 2024Testing the Mystery 'gpt2-chatbot' Model in April 2024Matthew Berman · Forward FutureMatthew Berman tries an anonymous model on coding, arithmetic and reasoning tasks while its identity remains uncertain.
 22:17ENMatthew Berman· Mar 21, 2024Q* Rumors, Energy-Based Models, and Research on ReasoningMatthew Berman, Yann Lecun · Forward FutureMatthew Berman examines an anonymous, unverified account of Q* and compares its ideas with published research on teaching language models to reason.