In 30 Sekunden
Nathan Lambert answers course questions about prerequisites, synthetic teachers, reward models and PPO. He distinguishes outcome rewards from token-level loss aggregation and explains why a minimized PPO loss uses a maximum.
- 1Choosing a teacherLambert reports that Qwen-era teachers have been difficult to beat in some recipes.
- 2Reward versus loss granularityAn outcome reward and a per-token training loss are compatible.
- 3PPO ratio shapeThe selected-token ratio is typically organized by batch and sequence position.
- 4Minimum versus maximumNegating a maximized objective changes the implementation to a maximum of losses.
Das Wichtigste
- A stronger teacher model does not automatically produce better fine-tuning data.
- Teacher and base-model compatibility remains an open research question.
- Sequence-level rewards can be used with token-level losses.
- GAE is useful but not the only possible advantage estimator.
- PPO’s min objective becomes a max when written as a negative loss.
Den bearbeiteten Text nach Kapiteln lesen
Course prerequisites and synthetic data
Lambert discusses mathematical preparation, teacher selection and balancing supervised data.
This first Q&A addresses questions from the opening four lectures, from course prerequisites to teacher models and PPO implementation. Lambert recorded it in May 2026 and frames the answers as practical guidance and open research questions.
I designed the book for people with graduate-level or early-career machine-learning background. Linear algebra, basic deep learning and experience implementing models help. AI tools make study more accessible, but mathematical maturity still matters; I recommend Sebastian Raschka’s books and the linked RL courses.
Does the strongest model make the best teacher for synthetic supervised data? Not necessarily. Lambert says OpenThoughts 3 and OLMo 3 found 32B Qwen-era teachers unusually strong, and that newer, larger teacher models have been difficult to beat those baselines with.
One possible explanation is compatibility between the teacher’s distribution and the base model, especially when open recipes have co-evolved around Qwen. Lambert presents this as a hypothesis, not a settled result, and wants research into which base models are most teachable.
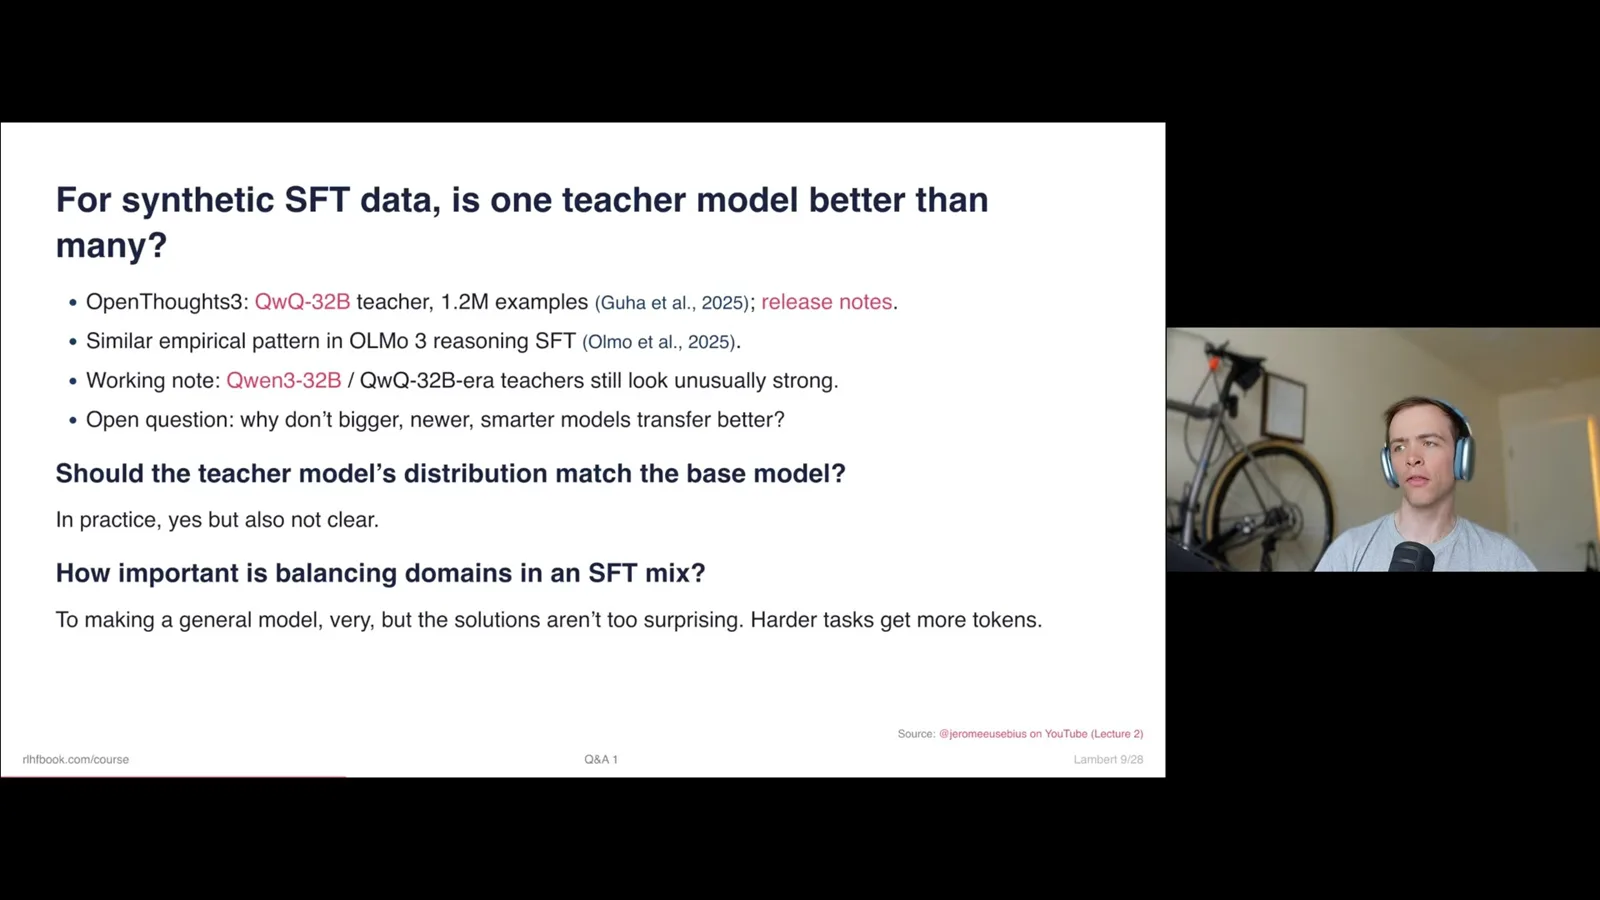
Balancing domains in an SFT mix matters, but mixing good datasets often works without elaborate machinery. Conflicting styles between domains can require adjustments. Harder math and coding tasks may contribute more tokens, so compute or token balance can differ from prompt counts.
Reward models and loss granularity
Different reward models fit different tasks. Sequence rewards and token-level losses are distinct choices.
Reward-model types serve different purposes and data formats. Lambert finds it hard to compare pairwise, outcome, process and generative models under a single benchmark. He sees rubric-guided generative judges as an increasingly general way to supply feedback.
A question about token-level versus sequence-level rewards mixes two kinds of granularity. The reward can still be an outcome at the end of a sequence while the training loss is calculated or normalized per token. Those aggregation choices introduce different biases in training.
Token-level normalization became common in reasoning-model RL because it can provide a more predictable foundation in which individual tokens contribute more evenly. This is a choice about implementation and loss aggregation, not necessarily a more detailed reward for every token.
PPO notation and implementation
The answers cover advantage estimation, ratio tensor shapes and the sign change from objective to loss.
Generalized advantage estimation is not the only way to compute an advantage in PPO-family methods. Lambert groups PPO and GRPO as related approaches, while noting that GAE remains a useful default when a value model is available.
The PPO ratio compares the current policy with the policy at the start of the batch. In a language-model implementation, after selecting the sampled token probabilities, the ratio typically has batch-by-sequence shape, with a value for each prompt and generated token.
An outcome reward can be broadcast over tokens while clipping and loss calculations operate on per-token ratios. Some newer algorithms change the level at which the ratio or clipping is computed; the tensor shapes help explain the implementation.
A reader asks why PPO code uses torch.max when the mathematical objective contains a minimum. The objective is maximized, whereas the implementation minimizes its negative loss. Taking the maximum of the two negative losses therefore preserves the conservative choice.
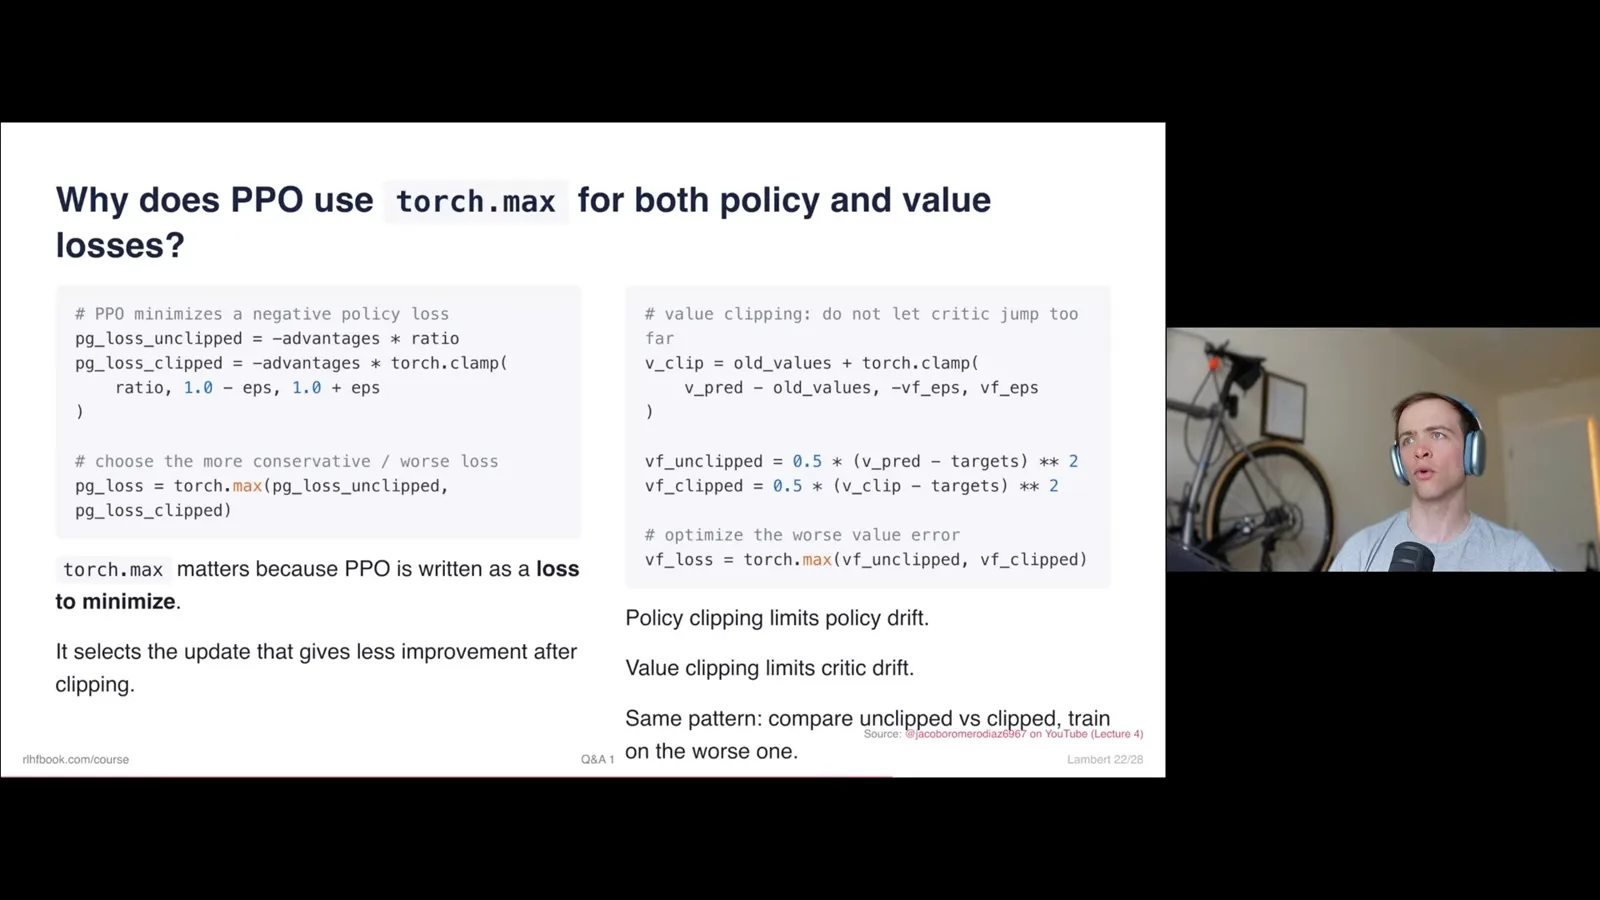
A similar clipped-versus-unclipped comparison may appear in the value loss, which uses regression error. Lambert says value losses can take multiple forms; this particular structure is a practical implementation choice.
The annotation market
Lambert shares his view of a shift toward expert-generated data and closes with upcoming course topics.
Asked how data annotation firms stay valuable as synthetic data improves, Lambert describes a shift toward recruiting specialists such as doctors, finance professionals and consultants to generate high-value data. He presents this as his reading of the market at the time.
The questions wrap up the first four lectures. Lambert plans subsequent lessons on the history of reasoning models and the DPO derivation, and invites readers to keep sending technical questions.
Mehr aus diesem Kanal
 16:48EN
 Nathan Lambert· 2. Nov. 2026Nathan Lambert on How Open Models Can Compete With Frontier LabsNathan Lambert · Allen Institute for AIOpen models are gaining use and closing capability gaps, but their builders need a sustainable economy and advantages beyond price.
 48:04ENNathan Lambert· 26. Okt. 2026Nathan Lambert on Open Language Models: History, Competition and RiskNathan Lambert · Allen Institute for AIA tour of open weights, research infrastructure, distillation, adoption and the choices facing model developers.
 46:42ENNathan Lambert· 25. Okt. 2026Nathan Lambert and Florian Brand on Kimi K3.1, Cyber Risk and AI AgentsNathan Lambert, Florian Brand · Allen Institute for AIThe Interconnects hosts discuss mixed model evaluations, a wave of security disclosures, and what a personal agent can do in everyday life.
 5:42ENNathan Lambert· 12. Aug. 2026Why the Shoggoth Became a Mascot for AI Post-TrainingNathan Lambert · Allen Institute for AINathan Lambert traces a creature from Lovecraft to a visual metaphor for language models, fine-tuning, and RLHF.
 32:56ENNathan Lambert· 6. Aug. 2026Nathan Lambert: An Introduction to AI Character TrainingNathan Lambert · Allen Institute for AIHow post-training shapes a model’s behavior, from constitutions and model specs to experiments with personality and activation steering.
 32:11ENNathan Lambert· 5. Aug. 2026Nathan Lambert on How Language Model Evaluation Has EvolvedNathan Lambert · Allen Institute for AIFrom few-shot prompts and pass@k to agent sandboxes, noisy scores and benchmark contamination.