In 30 Sekunden
Nathan Lambert corrects details in his post-training course, from on-policy distillation and Bradley–Terry losses to trajectory sampling and PPO notation. He also recommends hands-on code examples and a library for comparing model outputs.
- 1Distillation correctionA token-level KL estimate equals the divergence only in expectation.
- 2KL is not a distanceIts asymmetry violates a defining property of mathematical distance.
- 3Dataset-level lossA Bradley–Terry training objective needs an expectation over samples.
- 4Trajectory samplingA policy alone does not specify a complete trajectory without its environment and starting distribution.
- 5PPO objective and gradientClipping makes the objective more readable than the piecewise derivative.
Das Wichtigste
- A single sampled token estimates KL divergence; it is not the full expectation.
- KL divergence is asymmetric and therefore not a mathematical distance.
- Reward-model objectives must account for the training dataset.
- Consistent reward indexing and trajectory distributions prevent notation errors.
- PPO is often presented as an objective because its gradient is less readable.
Den bearbeiteten Text nach Kapiteln lesen
Corrections to derivations
Lambert fixes the KL estimate in on-policy distillation and a reward-model loss. He explains why KL is not a mathematical distance.
In this question roundup I correct derivations and notation in the course and point to ways to practice. Reader comments and GitHub issues have exposed small mistakes that matter when trying to understand post-training mathematics completely.
A slide on on-policy distillation incorrectly equated a token-level quantity with a full KL divergence. KL is an expectation over a distribution. A sampled token gives an estimate, and the advantage is the negative of that estimate; it is equal to the full KL expression only in expectation.
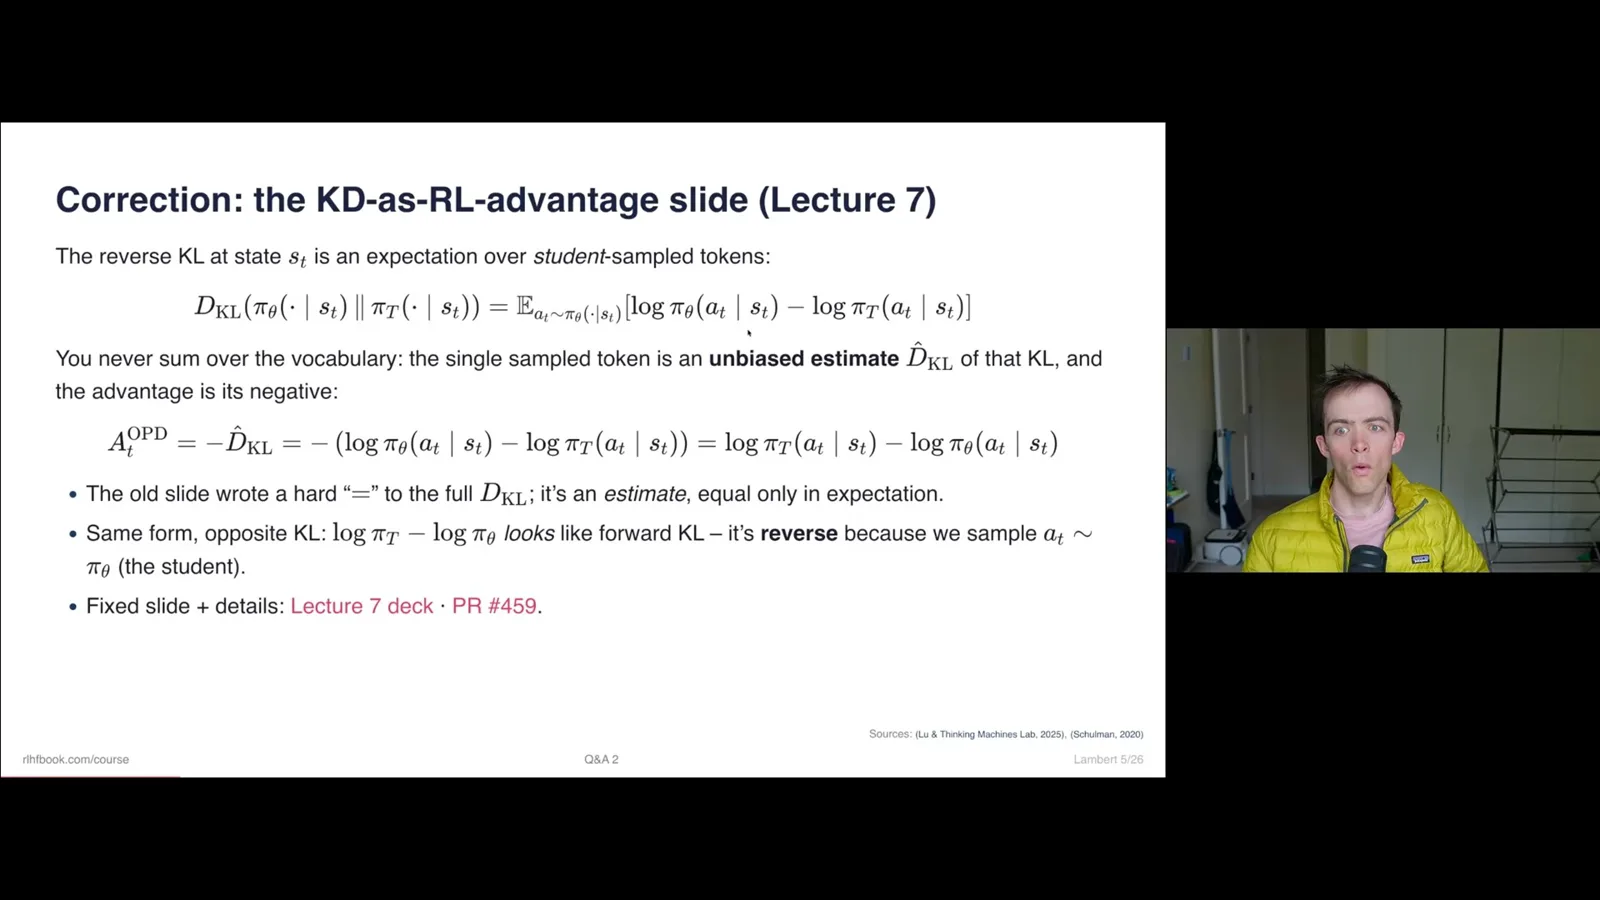
The resulting log-probability difference can look like forward KL after the sign change, but the direction depends on the sampling distribution: the token is sampled from the student. This is a small example of how easy it is to make a derivation look plausible while missing an essential detail.
I have sometimes called KL divergence a distance, but it is not a mathematical distance: KL is asymmetric. Practitioners often use the word informally to convey how far a policy moved during training, even though a precise discussion needs to specify its direction and approximation.
In practice KL is estimated using samples. I recommend John Schulman’s note on approximating KL, including the estimators commonly called k1, k2 and k3. Implementations may switch between estimators for stability.
A reward-model lecture also had a Bradley–Terry derivation that started by maximizing a single-example probability. Real training uses a sampled dataset. The corrected objective needs an expectation or average over examples rather than treating that single probability as the whole training problem.
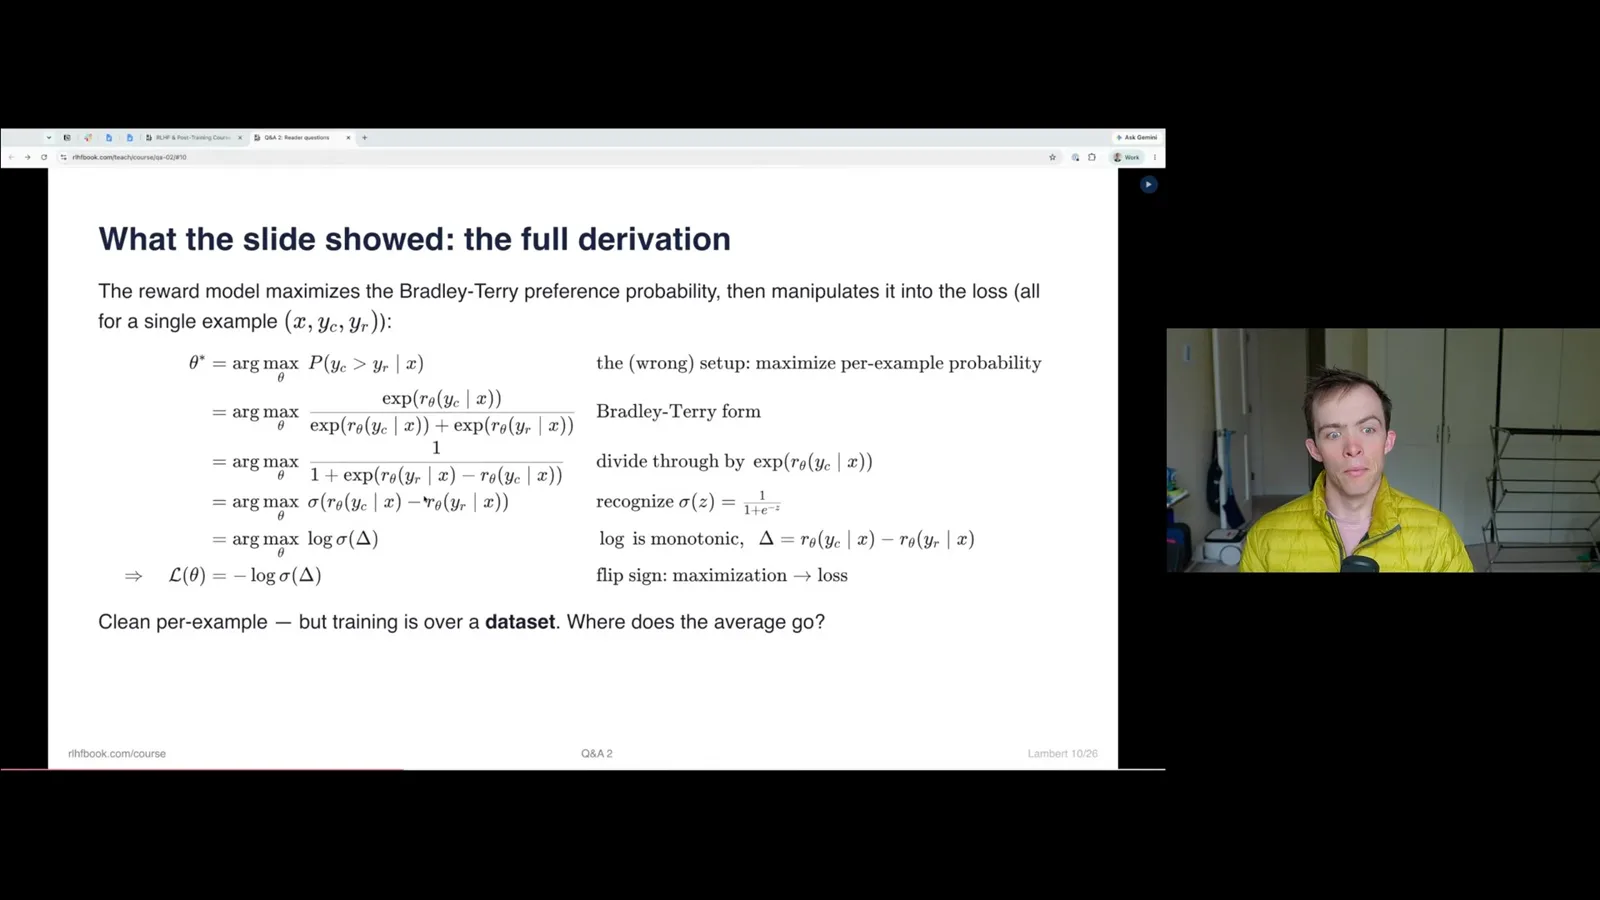
I thank Chris for spotting several issues. These theory-to-practice details are easy to miss. For people asking for assignments, the web chapters have suggested experiments tied to examples in the code repository.
Code and learning resources
Suggested experiments and a model-completion library support hands-on exploration. Contributions to exercises are welcome.
Try running the examples on rented GPU capacity or local hardware, inspect the logs, change parameters and see what breaks. I welcome contributions, including ideas for math exercises that remain educational when language models can readily solve them.
The model-completion library offers another way to explore: it shows outputs from different models and post-training stages on the same prompts. Many examples predate reasoning models, but they make historical comparisons possible without running old models yourself.
Reinforcement-learning notation
Consistent indexing, explicit trajectory distributions and clear gradients help avoid errors. PPO is often easier to understand through its objective.
Readers also found inconsistent notation in the reinforcement-learning chapter. Some mistakes may have reached the printed edition; the web version has been corrected, and I plan to fix them in reprints.
Reward indexing has two conventions: Sutton and Barto use a reward indexed at t+1, while some other work uses a t-based convention. The book now uses the latter consistently. Mixing conventions can create factual errors even when each convention is valid on its own.
Lowercase r denotes a reward associated with an individual transition, while uppercase R can denote return over the rest of a trajectory, possibly discounted. Writing R of a trajectory helps distinguish a trajectory-level return from a step reward.
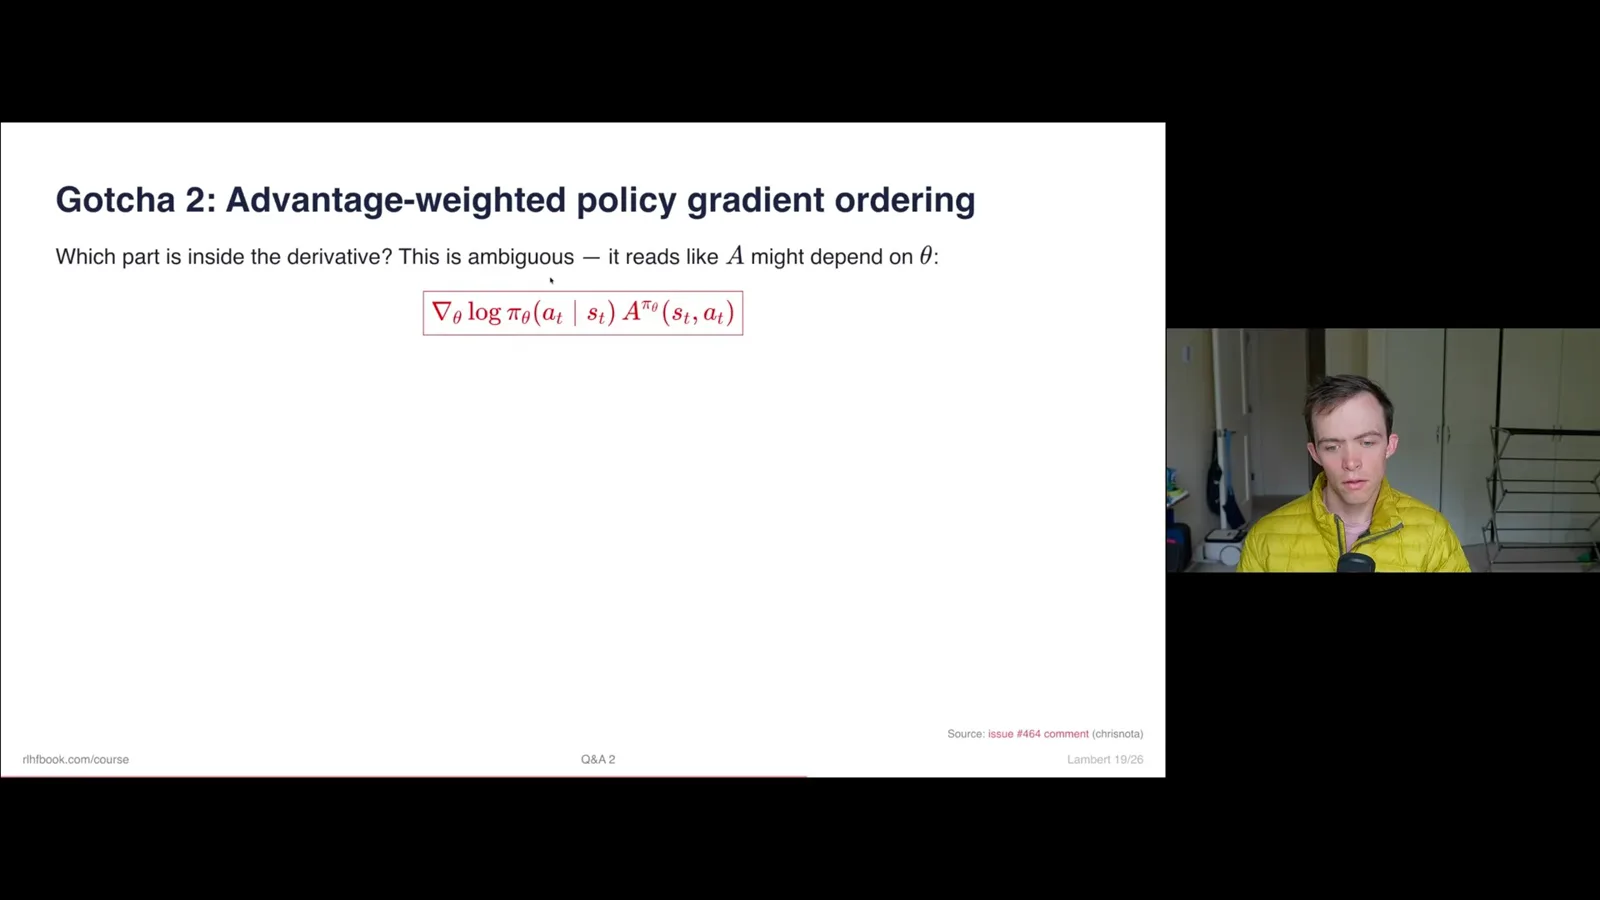
For the advantage-weighted REINFORCE gradient, the older notation made it unclear what was differentiated. The advantage is treated as a scalar in this estimator, so the revised expression places it in front of the log-policy gradient. In code, the model’s log probabilities and automatic differentiation provide the gradient.
Another correction concerns sampling trajectories. A policy maps a state to an action; it does not by itself generate an entire sequence of states and actions. A trajectory must be sampled from a distribution determined by the policy together with the initial state distribution and environment.
Why does the book write an analytical gradient for REINFORCE but an objective for PPO and TRPO? PPO’s clipped objective is easier to interpret than its piecewise derivative. In implementations the objective becomes a loss, and automatic differentiation computes parameter gradients.
A book maintainer also improved the chapter’s explanation and illustration of the PPO objective. The corrections show how detailed reader feedback can make the course clearer. The next lecture returns to preferences and preference data.
Mehr aus diesem Kanal
 16:48EN
 Nathan Lambert· 2. Nov. 2026Nathan Lambert on How Open Models Can Compete With Frontier LabsNathan Lambert · Allen Institute for AIOpen models are gaining use and closing capability gaps, but their builders need a sustainable economy and advantages beyond price.
 48:04ENNathan Lambert· 26. Okt. 2026Nathan Lambert on Open Language Models: History, Competition and RiskNathan Lambert · Allen Institute for AIA tour of open weights, research infrastructure, distillation, adoption and the choices facing model developers.
 46:42ENNathan Lambert· 25. Okt. 2026Nathan Lambert and Florian Brand on Kimi K3.1, Cyber Risk and AI AgentsNathan Lambert, Florian Brand · Allen Institute for AIThe Interconnects hosts discuss mixed model evaluations, a wave of security disclosures, and what a personal agent can do in everyday life.
 5:42ENNathan Lambert· 12. Aug. 2026Why the Shoggoth Became a Mascot for AI Post-TrainingNathan Lambert · Allen Institute for AINathan Lambert traces a creature from Lovecraft to a visual metaphor for language models, fine-tuning, and RLHF.
 32:56ENNathan Lambert· 6. Aug. 2026Nathan Lambert: An Introduction to AI Character TrainingNathan Lambert · Allen Institute for AIHow post-training shapes a model’s behavior, from constitutions and model specs to experiments with personality and activation steering.
 32:11ENNathan Lambert· 5. Aug. 2026Nathan Lambert on How Language Model Evaluation Has EvolvedNathan Lambert · Allen Institute for AIFrom few-shot prompts and pass@k to agent sandboxes, noisy scores and benchmark contamination.