In 30 Sekunden
Matthew Berman discusses the economics of open-weight AI, the role of Chinese developers, Nvidia’s hardware incentives and possible US policy responses. He warns of dependence and concentrated power, while acknowledging a hypothetical AGI counterargument. His market, geopolitical and hard-takeoff claims are predictions and interpretations rather than established outcomes.
- 1Open weights and disclosureWeights can be downloaded and adapted under their terms, but a release need not include the data and full recipe needed to reproduce training.
- 2Financing open modelsBerman argues that developers bear training costs while other providers can serve released weights; multiple commercial models remain possible.
- 3Nvidia’s incentiveHe sees a hardware supplier as able to benefit when other organizations run its models on its chips.
- 4Dependence and choiceHe worries that widespread adoption of models developed in China could influence standards and hardware markets, a scenario rather than a demonstrated inevitability.
- 5Policy and business proposalsHe suggests grants, compute access, procurement, hardware investment, specialist models and common standards.
Das Wichtigste
- Open weights enable local use and adaptation but do not necessarily include the full training recipe or carry identical licenses.
- Developers of released models must finance training while competing with other providers that can serve the weights.
- Model cost, security and suitability depend on specific workloads, infrastructure and licenses.
- Nvidia may benefit from model adoption through hardware demand, although its reported multi-year AI investment covers more than model weights.
- Berman’s proposals include public compute support, procurement, hardware-backed models, specialization and standards.
- Claims about AGI takeoff and geopolitical control remain speculative.
Den bearbeiteten Text nach Kapiteln lesen
The financing problem for open models
Berman sets out his concern about US AI competition and distinguishes his proposed business problem. Open-weight availability and full reproducibility are separate questions.
I worry that the United States faces a difficult choice in AI: dependence on a handful of proprietary frontier labs or on powerful open-weight models developed in China. The issue involves model developers, chip suppliers, government policy and enterprises. My stark framing is a warning about possible outcomes, not a demonstration that only two futures are possible.
I argue that US technology companies and the wider market have substantial exposure to AI’s success. The video’s claim that seven companies make up 40% of the stock market is not supported here and depends on the index, date and calculation. My broader concern is that US developers need a sustainable way to produce and distribute open models.
An open-weight model makes trained parameters available for others to download, run or adapt under its license. That is not necessarily the same as releasing the full training data, code and recipe needed to reproduce the model. Llama, Qwen, Gemma and DeepSeek have differing licenses and levels of disclosure; each version’s terms matter.
I value open models because researchers and developers can inspect behavior, adapt deployments and improve efficiency. Greater access can help security review and local control, but openness or local hosting alone does not guarantee security. Model provenance, software, infrastructure and operational practices also matter.
The business challenge is that training a capable model requires research, compute and money, while others can download and serve released weights without bearing the same development costs. Those providers may compete for customers. This creates a real funding question, although open-model developers can pursue hosting, services, enterprise products and other business models.
China, enterprise choices and cost
He offers an explanation for Chinese model releases and argues that many businesses may not need the highest frontier scores. The claims depend on funding, tasks and deployment choices.
I argue that Chinese government support and commercial incentives help explain why Chinese developers release competitive models. State support is one factor to investigate, not a complete account of every company’s funding or motivation. Likewise, US industrial policy and subsidies exist, so the contrast between government-directed China and a US free-for-all is simplified.
Enterprises are choosing AI strategies, and I think many will weigh local control and cost against the capabilities of proprietary offerings. Open-weight models can be self-hosted or fine-tuned where resources and licenses allow, while hosted models offer other deployment choices. Cost and performance depend on the task, hardware, provider and workload.
I argue that many business tasks do not require the highest available scores on frontier science or math. A cheaper model may be sufficient for spreadsheets, coding or scheduling, but that needs testing for the actual task. My figures of 99% and 99.9% are illustrative claims, not measured estimates of business use or model equivalence.
The video is sponsored by Zapier, which promotes its MCP integration for connecting AI agents to external tools. That sponsorship is separate from my argument about model economics. Whether any integration fits a business depends on its permissions, cost and deployment needs.
US model developers and Nvidia
Berman surveys Meta, OpenAI, Anthropic, Google and Nvidia. He sees Nvidia’s chip business as a potential source of incentives to fund open models.
Looking at US developers, I describe Meta’s shift in emphasis after earlier Llama releases and argue that OpenAI’s gpt-oss is not its primary frontier business. Meta’s future release choices should not be treated as proof that it will never release another open-weight model. OpenAI’s gpt-oss weights are available under Apache 2.0 and its usage policy.
I describe Anthropic as focused on proprietary models, while Google also releases open-weight Gemma models for a range of use cases. In the video I say “Gemini” when discussing local open models; Gemma is the relevant Google open-weight family. Availability, deployment requirements and license terms vary by version.
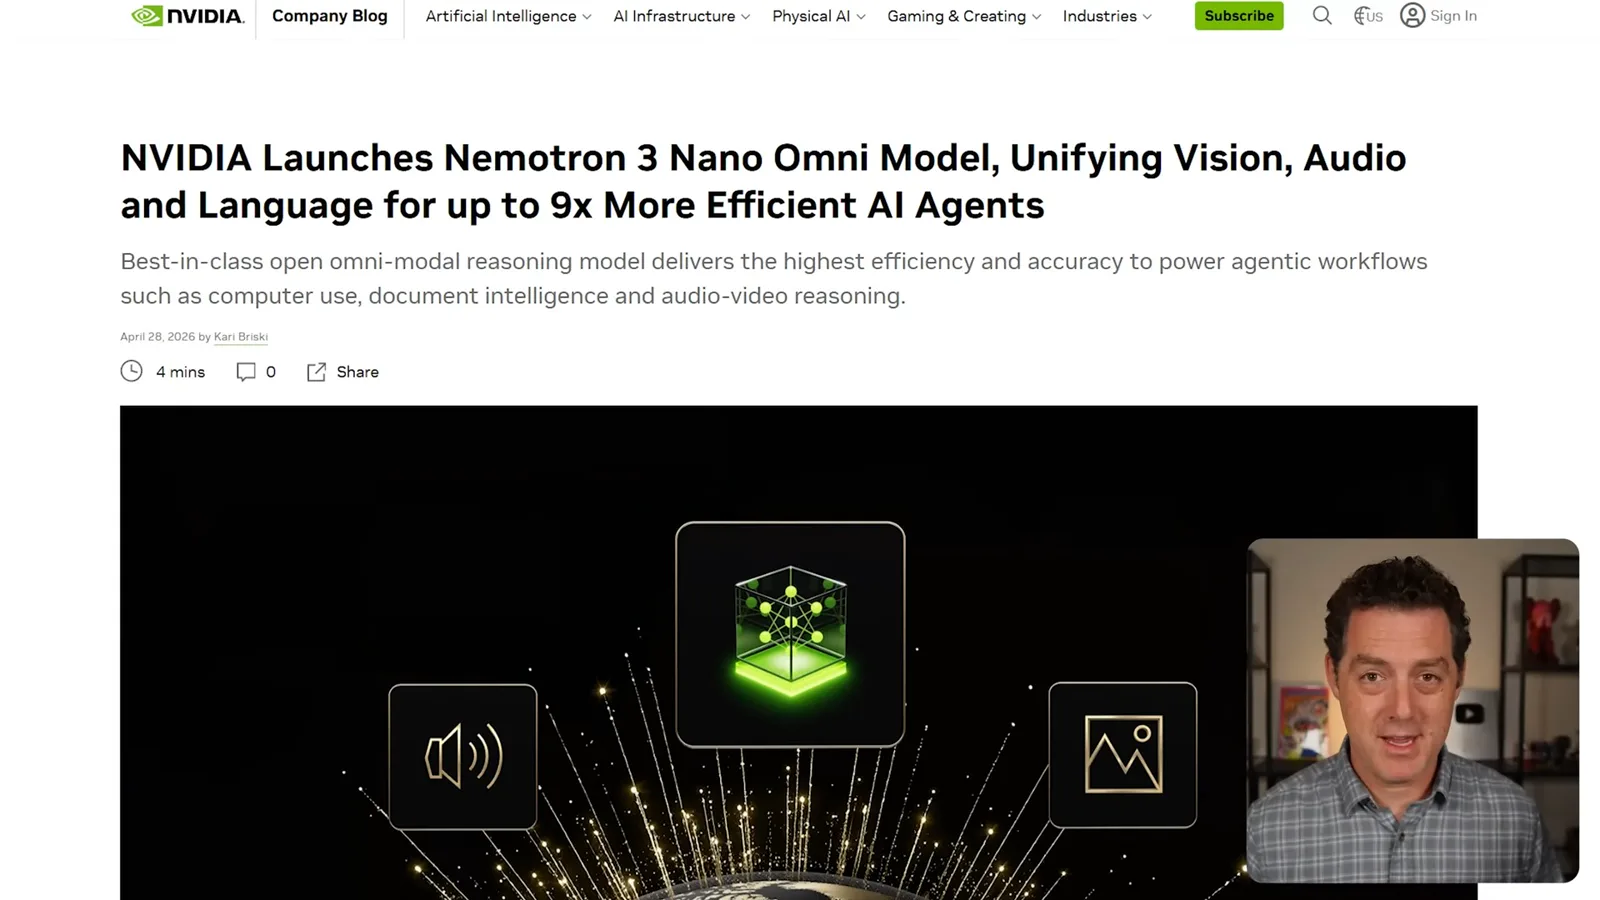
Nvidia is my leading example of an alternative incentive. Its Nemotron models can support an ecosystem that uses Nvidia hardware, so the company may benefit from hardware demand even when others serve the weights. This is my assessment of its strategic incentives, not proof that Nvidia is the only firm with a viable open-model business.
I cite a $26 billion Nvidia investment. Reporting based on a filing and executive interviews described spending over five years, with most intended for open models but some covering infrastructure, autonomous-vehicle software and other AI research. It should not be read as $26 billion spent already or as exclusively devoted to open model weights.
The hardware-funded model differs from a startup relying solely on model-serving revenue: cloud providers that serve a released model may also be Nvidia chip customers. I think that upstream position can support continued investment in models. Other chipmakers, cloud firms and independent labs may have different incentives and financing options.
Standards, chips and geopolitical concerns
He considers local hosting, hardware optimization and possible cultural bias. These are risks to evaluate rather than predetermined consequences.
Why worry if a US business can run a Chinese model locally without sending its data to the developer? I argue that widespread adoption could still shape technical standards, hardware demand and bargaining power. Self-hosting can reduce some data-transfer concerns, but the consequences depend on actual software compatibility, supply chains and purchasing decisions.
I speculate that Chinese developers may increasingly optimize models for chips available in China under US export controls, and that the resulting ecosystem could influence hardware choices elsewhere. It does not follow that users must buy Chinese chips: model portability, software support and economics all affect the outcome.
I also worry about cultural biases or restrictions embedded in a model’s training and tuning. Open weights can be modified and tested, but not every behavior is easy to characterize or remove. These concerns should be assessed through specific evaluations, not treated as proof that a model or its users are controlled by a government.
I argue that low-cost open models may also pressure proprietary labs’ revenue, potentially affecting investment in US AI. That is a competitive scenario, not a quantified prediction. Users may select different models for different tasks, and firms can earn revenue from more than inference alone.
The AGI counterargument and proposed solutions
He considers a hypothetical AGI-driven winner and then proposes policies and business models for the interim. His projections about takeoff and future capabilities are speculative.
There is a counterargument: perhaps reaching AGI first matters more than the open-model market. I describe a possible feedback loop in which a company earns money from a coding model and uses its resources to develop the next generation. My claims about an inevitable hard takeoff, exclusive control and solving any problem are speculative, not established capabilities or company commitments.
I cite a $30 billion Anthropic annualized revenue figure as part of that argument, but the video does not establish the underlying calculation. Annualized revenue is a run-rate measure rather than profit or verified annual cash receipts. Whether AI progress becomes recursively self-improving, and on what timescale, remains unknown.
My concern is that even if a future AGI breakthrough changes the market, the transition may take an uncertain amount of time. During that interval, I believe access to domestic open models and a diverse hardware ecosystem could matter for US organizations. The scenario is a policy argument, not proof of a specific geopolitical outcome.
Nvidia’s Nemotron family may help, but I do not want the US ecosystem to depend on one company. I propose federal grants or access to compute for open-model developers, treating some of this work as a public good. That would involve choices about eligibility, cost and oversight.
I also suggest tax credits, accelerated depreciation and procurement commitments for US open models in areas such as defense, health, finance and energy. In my view, procurement can help create demand. The costs and effectiveness of such measures would need to be evaluated rather than assumed.
Another option is for hardware companies such as AMD and Intel to support open models optimized for their platforms. Model developers might also focus on smaller, efficient models for specific fields such as law, biotech, coding or defense instead of competing on every frontier benchmark. The best approach depends on the use case and economics.
Finally, I propose common standards to reduce duplicated engineering and make it easier for startups to build and reach customers. It may still be early to settle every standard. A recent DeepSeek release prompted this discussion; its performance and cost should be evaluated on specific tasks rather than taken as proof of every outcome I have described.
Mehr aus diesem Kanal
 34:21EN
 Matthew Berman· 27. Okt. 2026Matthew Berman Examines Anthropic’s IPO Filing, AI Growth and GovernanceMatthew Berman, Sam Altman · Forward FutureThe presenter reviews the S-1’s financial metrics, compute strategy and voting structure while questioning the tension between rapid AI development and safety.
 0:26ENMatthew Berman· 25. Okt. 2026Sam Altman on Human Values and Problem-Solving in an AI WorldSam Altman · OpenAIIn a short interview excerpt, Altman considers the enjoyment of solving hard problems and the human role in interpreting results.
 0:36ENMatthew Berman· 25. Okt. 2026Kimi K3.1 and a Rubik’s Cube Solver DemonstrationMatthew Berman · Forward FutureMatthew Berman shows a scrambled virtual cube being solved and gives the Kimi K3.1 test a favorable assessment.
 0:21ENMatthew Berman· 24. Okt. 2026An AI-Generated Kimi Benchmark Chart Used Invented ScoresMatthew Berman · Forward FutureMatthew Berman asks for a graph of Kimi K3.1 Pro benchmarks, then discovers that the displayed figures are illustrative placeholders.
 25:50ENMatthew Berman· 24. Okt. 2026Kimi K3.1 Pro Tested: Strong 3D Demos, Uneven Results and Competitive PricingMatthew Berman · Forward FutureMatthew Berman tests the open-weight model on coding, 3D rendering and visual explanations, then compares benchmark results and prices.
 32:20ENMatthew Berman· 23. Okt. 2026Who Is Local AI For? The Costs, Trade-offs and a Hybrid FutureMatthew Berman · Forward FutureMatthew Berman weighs data control and independence against hardware cost, setup complexity and inference speed.