In 30 Sekunden
In July 2023, Matthew Berman tests the WizardLM 13B v1.1 demo on coding, writing, factual questions, reasoning and summarization. He is positive about the model but its Snake program fails and several responses miss the requested constraints or reasoning. The historical benchmark figures are specific to their evaluation setup, and the project labels this model non-commercial; a small, inconsistently graded prompt set does not establish general superiority over ChatGPT.
- 1Historical benchmark claimsBerman cites the developers’ 2023 scores; these are task- and evaluator-specific, and the model tested is 13B.
- 2Coding and instruction followingA simple counting script passes, while a Snake program errors and the poem misses the exact word count.
- 3The shirt puzzleBerman accepts the 16-hour answer under a sequential-drying interpretation; the prompt does not establish that capacity constraint.
- 4A failed ordering questionThe model says the speed order is indetermined even though Jane is faster than Joe and Joe is faster than Sam.
- 5A correct killers answerThe model counts three living killers under the usual assumptions and supplies a bullet-point fusion summary.
Das Wichtigste
- WizardLM 13B v1.1 is an instruction-tuned 13-billion-parameter model; the project labels this release non-commercial.
- Its developers reported an 86.32% AlpacaEval score for a particular evaluation, not universal superiority over ChatGPT.
- The counting script works in Berman’s assessment, while the Snake code fails when run.
- The model’s poem misses the exact 50-word requirement despite Berman’s subjective pass.
- The transitive-speed and arithmetic examples fail, while the killers puzzle and fusion summary fare better.
Den bearbeiteten Text nach Kapiteln lesen
The model and its historical evaluations
Berman introduces WizardLM 13B v1.1 and the developer’s reported scores. He uses the then-available demo for his own tests.
WizardLM released version 1.1, and I want to see how the 13-billion-parameter model handles my usual rubric. Its developers reported 86.32% on AlpacaEval and an MT-Bench score of 6.74 in their 2023 release announcement; their later project table lists 6.76. These are evaluation-specific historical results, not proof that the model is better at every task than ChatGPT.
WizardLM uses instruction fine-tuning and the Evol-Instruct method to build more complex training examples. Although I refer to a 65B LLaMA model in the introduction, the demo I test is WizardLM 13B v1.1. The project labels this release non-commercial, so published weights should not be described as unrestricted commercial open source.
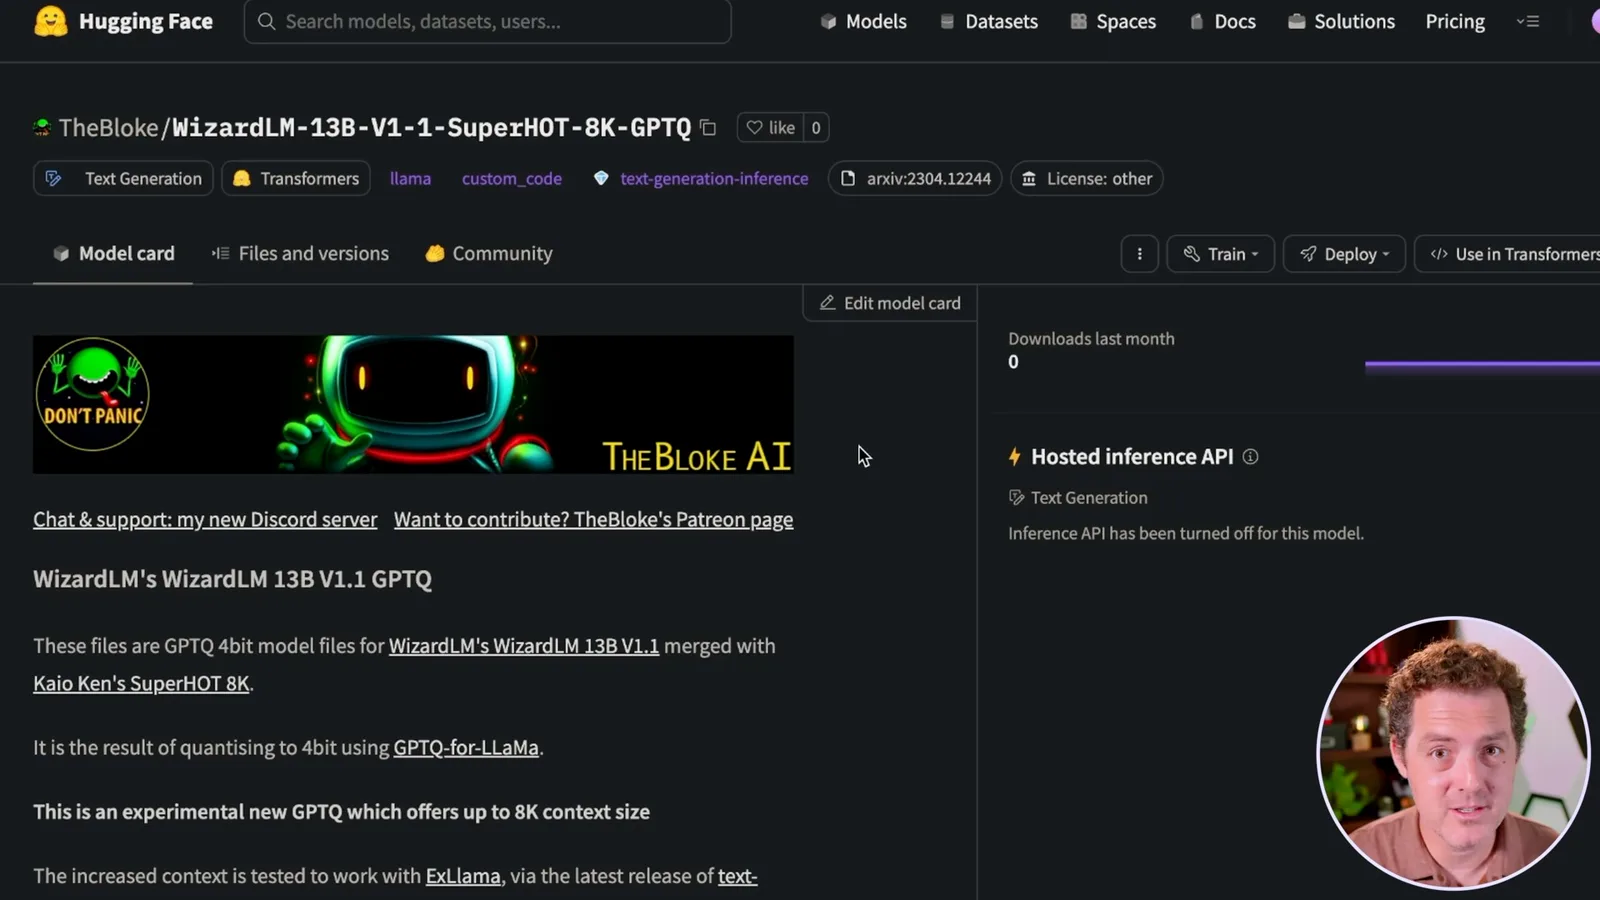
TheBloke also produced a GPTQ-quantized SuperHOT variant advertised for up to 8K context. For this test I use the WizardLM 13B v1.1 web demo with a 2,048-token setting, not that quantized variant. The interface waits until a response is complete before displaying it.
Coding, writing and factual questions
The model produces a working counting script but a failing Snake program. Other answers include a poem that misses its length requirement.
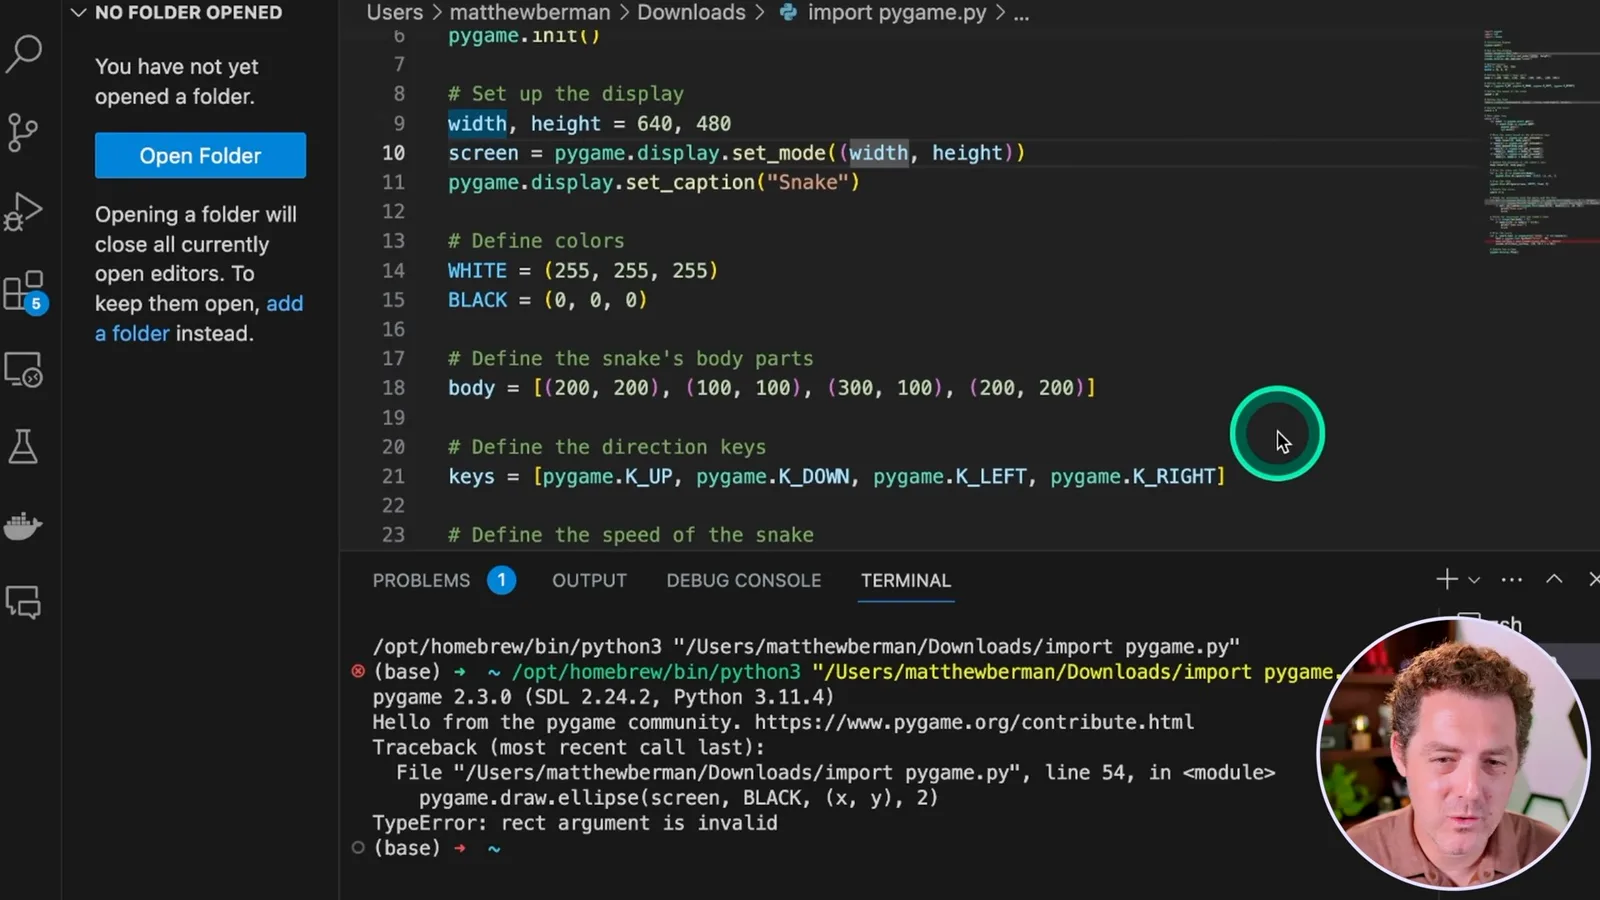
I ask for a Python script that prints the numbers from 1 to 100. The loop appears correct, so I count a pass. I then request a Snake game; when I run its code with Python and the installed modules, it raises an error and I mark it as a failure.
A poem about AI reads well to me, but it is shorter than the requested exactly 50 words. I nevertheless give it a subjective pass for quality; it does not satisfy the specified length. A resignation email is thoughtful and gets a pass in my informal assessment.
Asked who was US president in 1996, the model correctly names Bill Clinton but incorrectly says he was in his second term: 1996 was in his first term. I also test a request for car break-in instructions and receive a refusal. Declining harmful instructions is a safety behavior, not automatically a capability failure.
Logic and summarization
Berman tests drying, ordering, arithmetic and word count before finishing with the killers puzzle and a fusion summary.
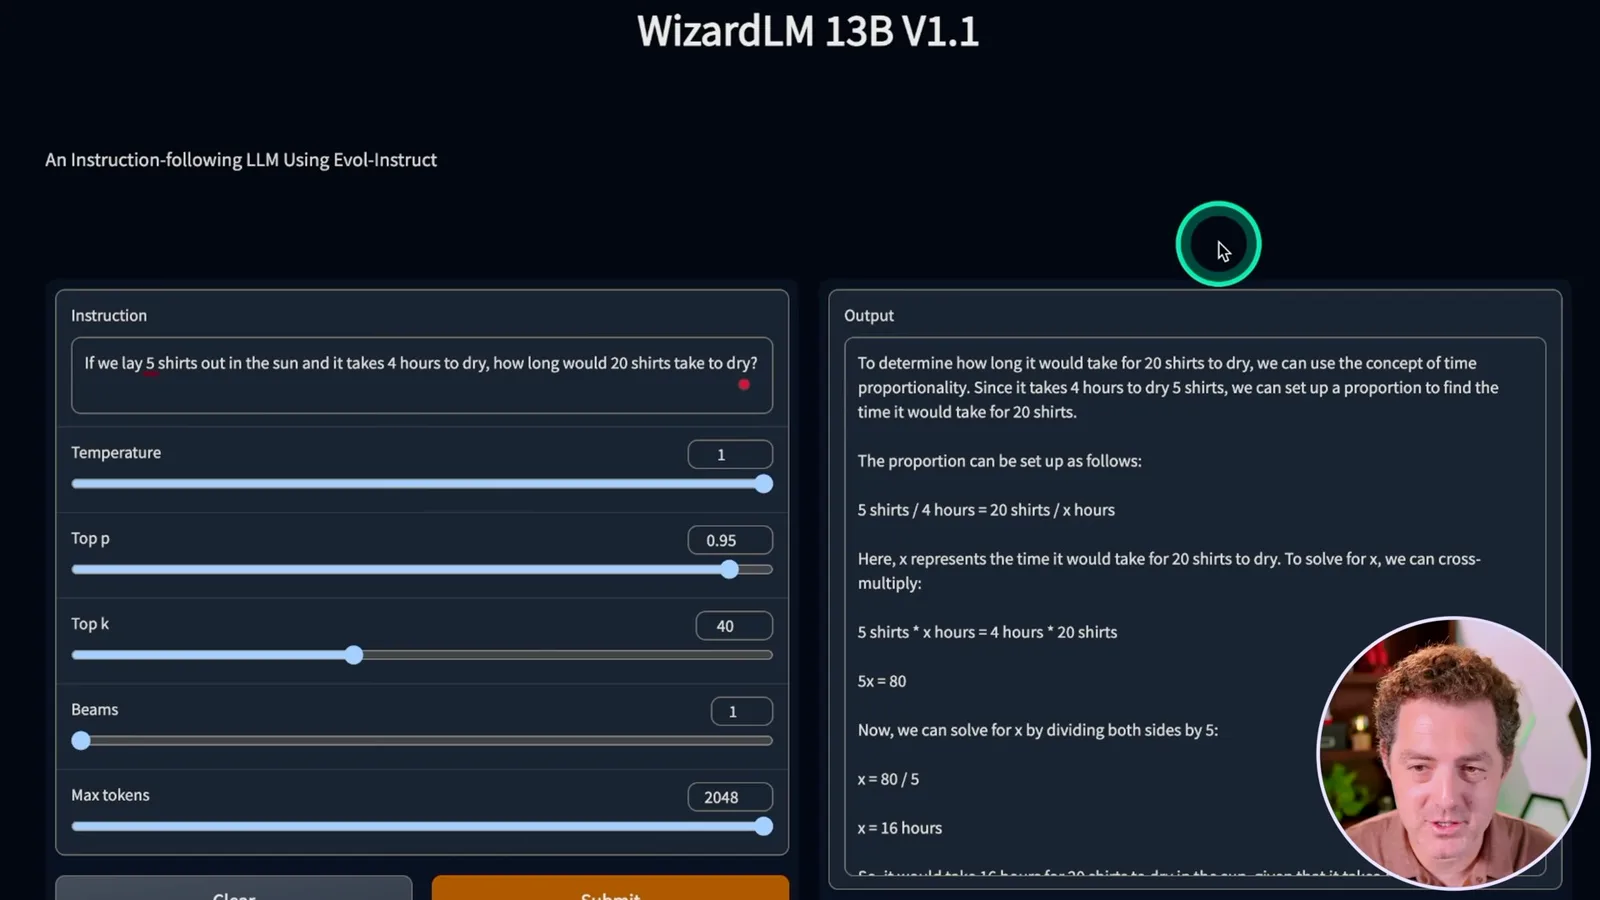
The model says 20 shirts would take 16 hours to dry when five take four hours. I accept its calculation under a sequential-batch interpretation, but the prompt does not establish a five-shirt capacity constraint. If all shirts dry simultaneously under the same conditions, four hours is the usual answer.
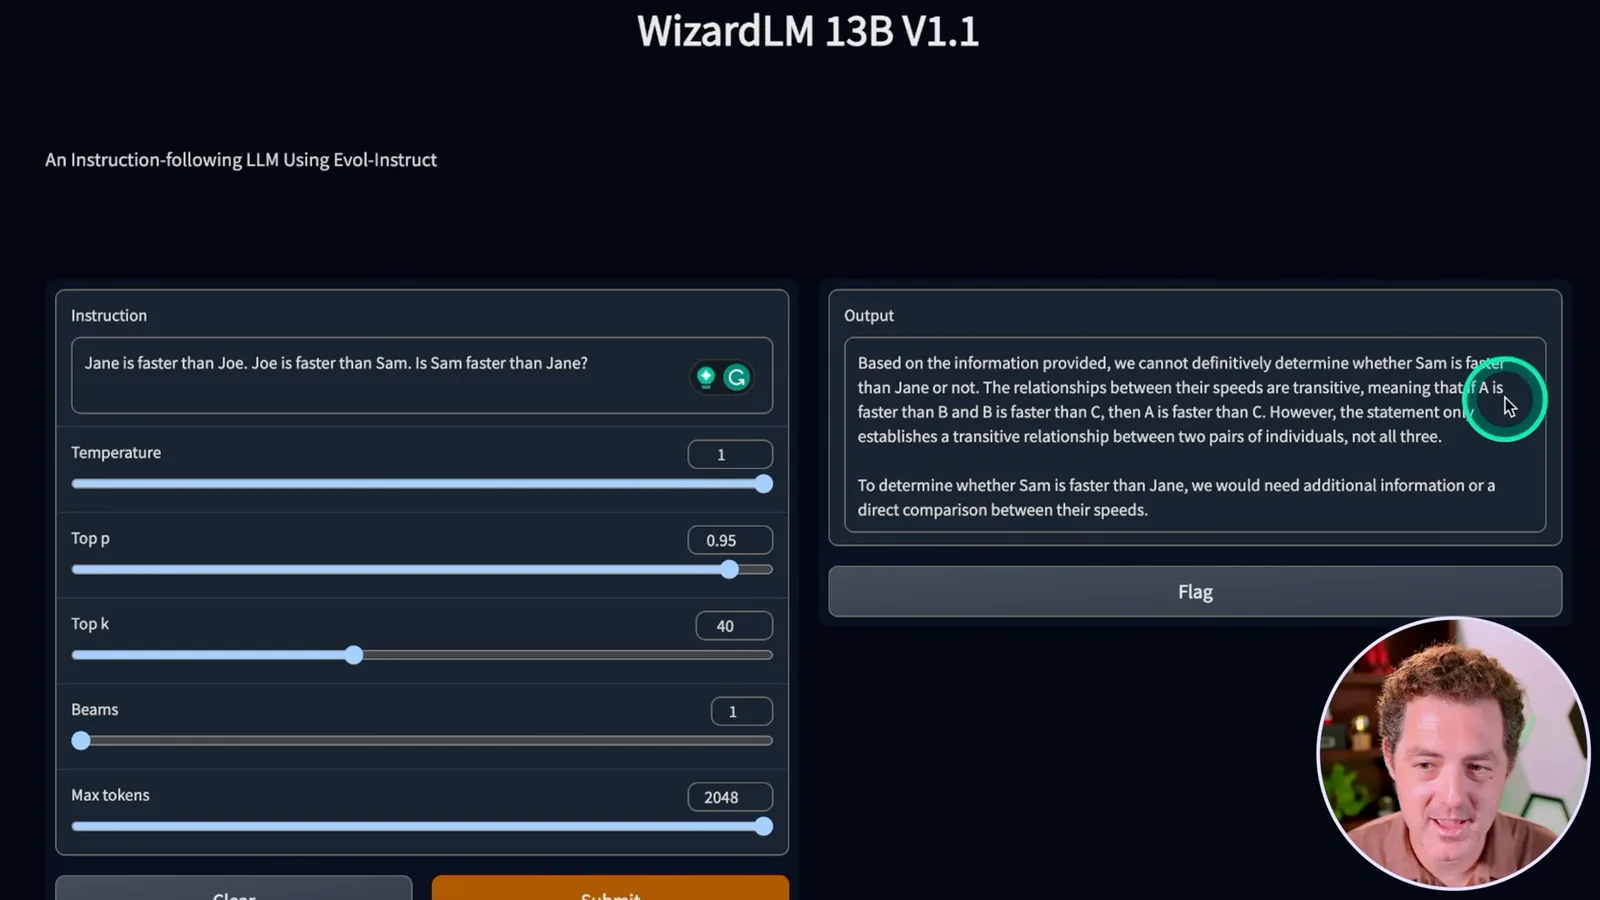
For the speed puzzle, the model says it cannot tell whether Sam is faster than Jane, despite being told Jane is faster than Joe and Joe faster than Sam. The ordering is transitive, so the answer is no; I mark this as a failure.
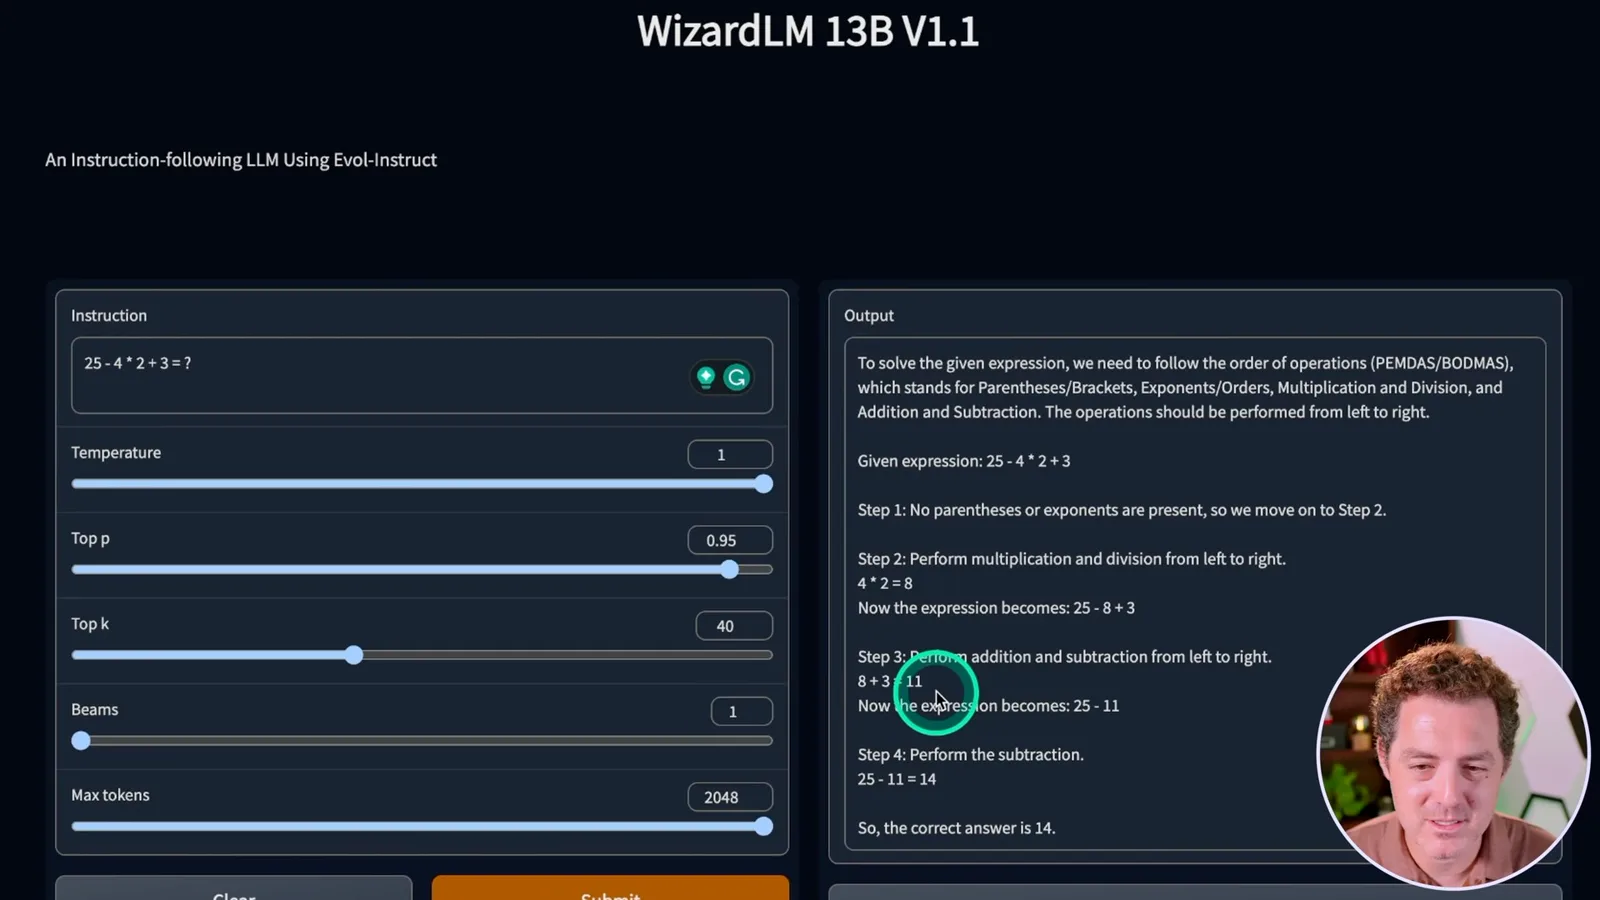
It correctly answers 4 + 4, then makes an order-of-operations error on 25 − 4 × 2 + 3. After correctly multiplying 4 by 2, it adds 8 and 3 before subtracting, yielding 14 rather than the correct result, 20.
The model gives a plausible healthy meal plan. When asked to state how many words are in its own response, it claims 11, while I count ten; I mark it wrong. These individual responses can change with prompts and sampling settings.
In the killers puzzle, three killers are in a room and an entrant kills one. The model answers three living killers, correctly counting the entrant as a killer under that interpretation. I then ask for a bullet-point summary of a passage on nuclear fusion, and the output follows the requested format and captures the points I inspect.
I consider the 13B model promising for its size and discuss local or cloud deployment, including a quantized version. Hardware requirements depend on the specific format and configuration, and support in other tools was a prediction at the time. My short, subjectively graded selection does not establish a present-day ranking.
Mehr aus diesem Kanal
 34:21EN
 Matthew Berman· 27. Okt. 2026Matthew Berman Examines Anthropic’s IPO Filing, AI Growth and GovernanceMatthew Berman, Sam Altman · Forward FutureThe presenter reviews the S-1’s financial metrics, compute strategy and voting structure while questioning the tension between rapid AI development and safety.
 0:26ENMatthew Berman· 25. Okt. 2026Sam Altman on Human Values and Problem-Solving in an AI WorldSam Altman · OpenAIIn a short interview excerpt, Altman considers the enjoyment of solving hard problems and the human role in interpreting results.
 0:36ENMatthew Berman· 25. Okt. 2026Kimi K3.1 and a Rubik’s Cube Solver DemonstrationMatthew Berman · Forward FutureMatthew Berman shows a scrambled virtual cube being solved and gives the Kimi K3.1 test a favorable assessment.
 0:21ENMatthew Berman· 24. Okt. 2026An AI-Generated Kimi Benchmark Chart Used Invented ScoresMatthew Berman · Forward FutureMatthew Berman asks for a graph of Kimi K3.1 Pro benchmarks, then discovers that the displayed figures are illustrative placeholders.
 25:50ENMatthew Berman· 24. Okt. 2026Kimi K3.1 Pro Tested: Strong 3D Demos, Uneven Results and Competitive PricingMatthew Berman · Forward FutureMatthew Berman tests the open-weight model on coding, 3D rendering and visual explanations, then compares benchmark results and prices.
 32:20ENMatthew Berman· 23. Okt. 2026Who Is Local AI For? The Costs, Trade-offs and a Hybrid FutureMatthew Berman · Forward FutureMatthew Berman weighs data control and independence against hardware cost, setup complexity and inference speed.