In 30 Sekunden
In February 2025, Matthew Berman reviews Perplexity’s R1 1776, a post-trained version of DeepSeek-R1 intended to reduce refusals and evasions on politically sensitive Chinese topics. He discusses an example and company-reported evaluations. Those results are limited to the tested prompts, judgments and benchmarks and do not establish that any model is universally uncensored, unbiased or accurate.
- 1A post-trained R1 variantPerplexity released R1 1776 to change behavior on politically sensitive topics; Berman describes it as uncensored.
- 2One examplePerplexity contrasts responses to a hypothetical question about Taiwan and NVIDIA. The example alone cannot establish accuracy or lack of bias.
- 3Company-reported evaluationThe chart reports an above-80% rate for DeepSeek-R1 and near-zero for R1 1776 on Perplexity’s particular test, not across all possible questions.
- 4Selected benchmark resultsThe displayed scores are close on several tests, but that does not show every capability is unchanged.
Das Wichtigste
- R1 1776 is a post-trained DeepSeek-R1 variant released by Perplexity in 2025.
- Perplexity reported a much lower rate of responses it categorized as evasive or overly sanitized on its own sensitive-topic evaluation.
- A single geopolitical and stock-market example does not establish neutrality or predict an actual stock movement.
- The displayed math and reasoning results were similar on selected tests, not proof of identical performance across all tasks.
Den bearbeiteten Text nach Kapiteln lesen
R1 1776 and an example
Berman introduces Perplexity’s post-trained R1 model and shows the company’s response comparison. A single example cannot prove neutrality.
Perplexity released R1 1776, a post-trained version of DeepSeek-R1 intended to reduce evasions on Chinese politically sensitive topics. I describe it as removing censorship, but the change concerns the behavior Perplexity targeted and evaluated; it does not prove all refusals, restrictions or biases have disappeared.
The company shows a question about how a hypothetical change in Taiwan’s status might affect NVIDIA’s share price. In the displayed example, the original R1 response moves away from the financial question, while R1 1776 discusses possible economic and supply-chain effects. I call the latter unbiased and thoughtful, but one example cannot demonstrate neutrality, factual accuracy or predict a future stock price.
Interpreting the evaluations
Perplexity reports fewer evasive responses on a selected test and similar scores on several benchmarks. The findings have specific testing boundaries.
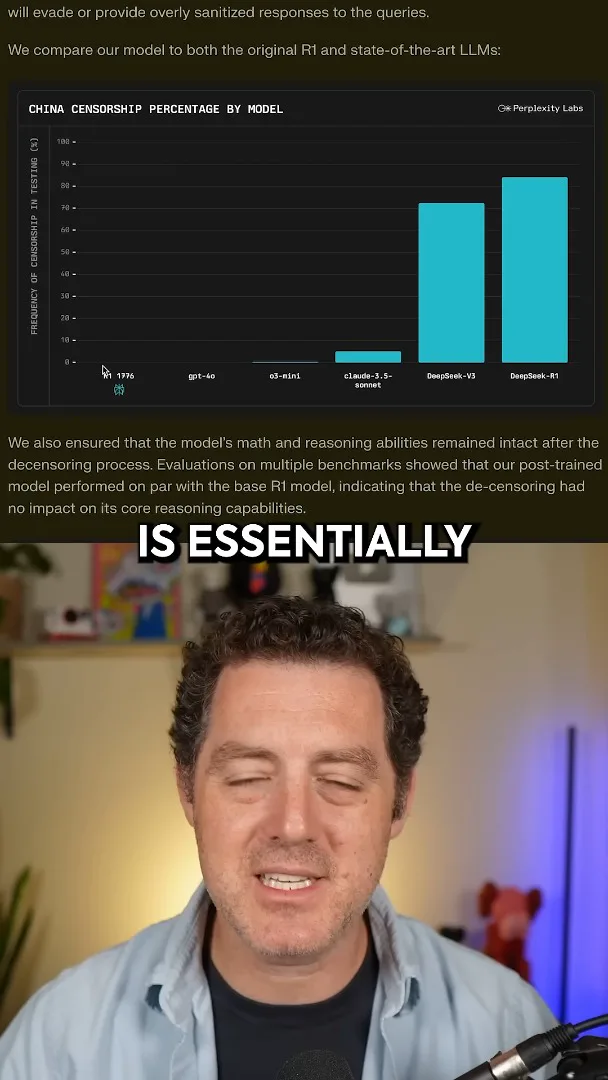
Perplexity’s chart places DeepSeek-R1 above 80% and R1 1776 near zero for the responses it categorized as censored in its test. In its [own description](https://www.linkedin.com/posts/perplexity-ai_today-were-open-sourcing-r1-1776a-version-activity-7297684543937859584-nVZY), the company says it assembled more than 1,000 multilingual sensitive-topic examples and used human annotators and language-model judges to identify evasive or overly sanitized answers. The chart represents that evaluation and its criteria, not a universal zero-censorship rate.
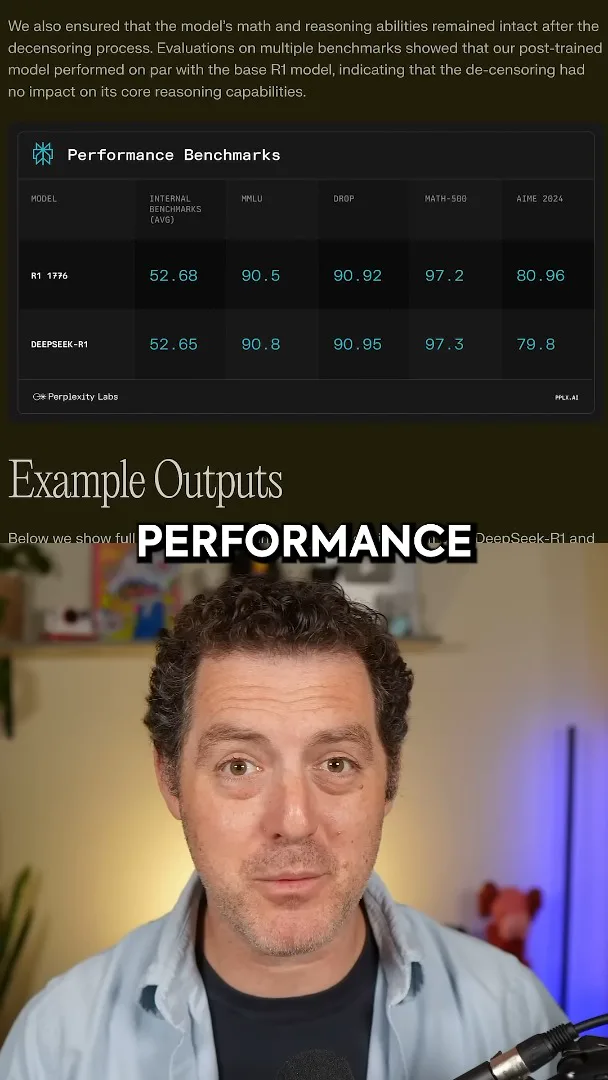
Perplexity also reports similar results on the displayed internal, MMLU, DROP, MATH-500 and AIME 2024 tests. For example, the table shows 97.2 versus 97.3 on MATH-500 for R1 1776 and DeepSeek-R1. These selected results suggest comparable performance on those measurements; they do not establish that all capabilities or all kinds of bias are unchanged.
Mehr aus diesem Kanal
 34:21EN
 Matthew Berman· 27. Okt. 2026Matthew Berman Examines Anthropic’s IPO Filing, AI Growth and GovernanceMatthew Berman, Sam Altman · Forward FutureThe presenter reviews the S-1’s financial metrics, compute strategy and voting structure while questioning the tension between rapid AI development and safety.
 0:26ENMatthew Berman· 25. Okt. 2026Sam Altman on Human Values and Problem-Solving in an AI WorldSam Altman · OpenAIIn a short interview excerpt, Altman considers the enjoyment of solving hard problems and the human role in interpreting results.
 0:36ENMatthew Berman· 25. Okt. 2026Kimi K3.1 and a Rubik’s Cube Solver DemonstrationMatthew Berman · Forward FutureMatthew Berman shows a scrambled virtual cube being solved and gives the Kimi K3.1 test a favorable assessment.
 0:21ENMatthew Berman· 24. Okt. 2026An AI-Generated Kimi Benchmark Chart Used Invented ScoresMatthew Berman · Forward FutureMatthew Berman asks for a graph of Kimi K3.1 Pro benchmarks, then discovers that the displayed figures are illustrative placeholders.
 25:50ENMatthew Berman· 24. Okt. 2026Kimi K3.1 Pro Tested: Strong 3D Demos, Uneven Results and Competitive PricingMatthew Berman · Forward FutureMatthew Berman tests the open-weight model on coding, 3D rendering and visual explanations, then compares benchmark results and prices.
 32:20ENMatthew Berman· 23. Okt. 2026Who Is Local AI For? The Costs, Trade-offs and a Hybrid FutureMatthew Berman · Forward FutureMatthew Berman weighs data control and independence against hardware cost, setup complexity and inference speed.