In 30 Sekunden
Theo Browne reviews Grok 4.5 after using it for coding and game experiments. He highlights its cost and responsiveness, discusses CursorBench training-data overlap and compares its practical strengths and limitations with other models.
- 1Coding benchmarksThe displayed DeepSWE chart places Grok 4.5 behind Fable and GPT-5.5 in those particular settings.
- 2CursorBench caveatAn earlier Cursor codebase snapshot was unintentionally included in training; the score impact is unknown.
- 3Historical pricingThe video shows different token rates above and below a 200,000-token context threshold.
- 4Practical codingTheo describes an audit, multiple pull requests and review follow-ups in Lakebed.
- 53D experimentThe generated game had interesting assets but significant layout and control problems.
Das Wichtigste
- The shown coding results are strong but depend on benchmark settings and harnesses.
- Cursor disclosed training overlap with its codebase, making the effect on CursorBench scores uncertain.
- The video’s API prices and promotional terms are historical snapshots.
- Theo found the model useful for interactive code review and follow-up work, while still reviewing its output.
- His 3D demo had promising assets but broken controls and was not ready to ship.
- His assessment of subagent orchestration is based on limited testing.
Den bearbeiteten Text nach Kapiteln lesen
A surprise early test
Theo describes using Grok 4.5 before knowing its identity. He introduces its reported coding performance.
I spent about a day using a model in Cursor that I assumed was a new Composer. It turned out to be Grok 4.5, and I was impressed before I knew its identity. Its coding scores look strong and the quoted cost is low, though my experience does not make every benchmark ranking a universal result.
Training and benchmarks
He examines launch material and Cursor’s evaluations. CursorBench includes a disclosed training-data overlap.
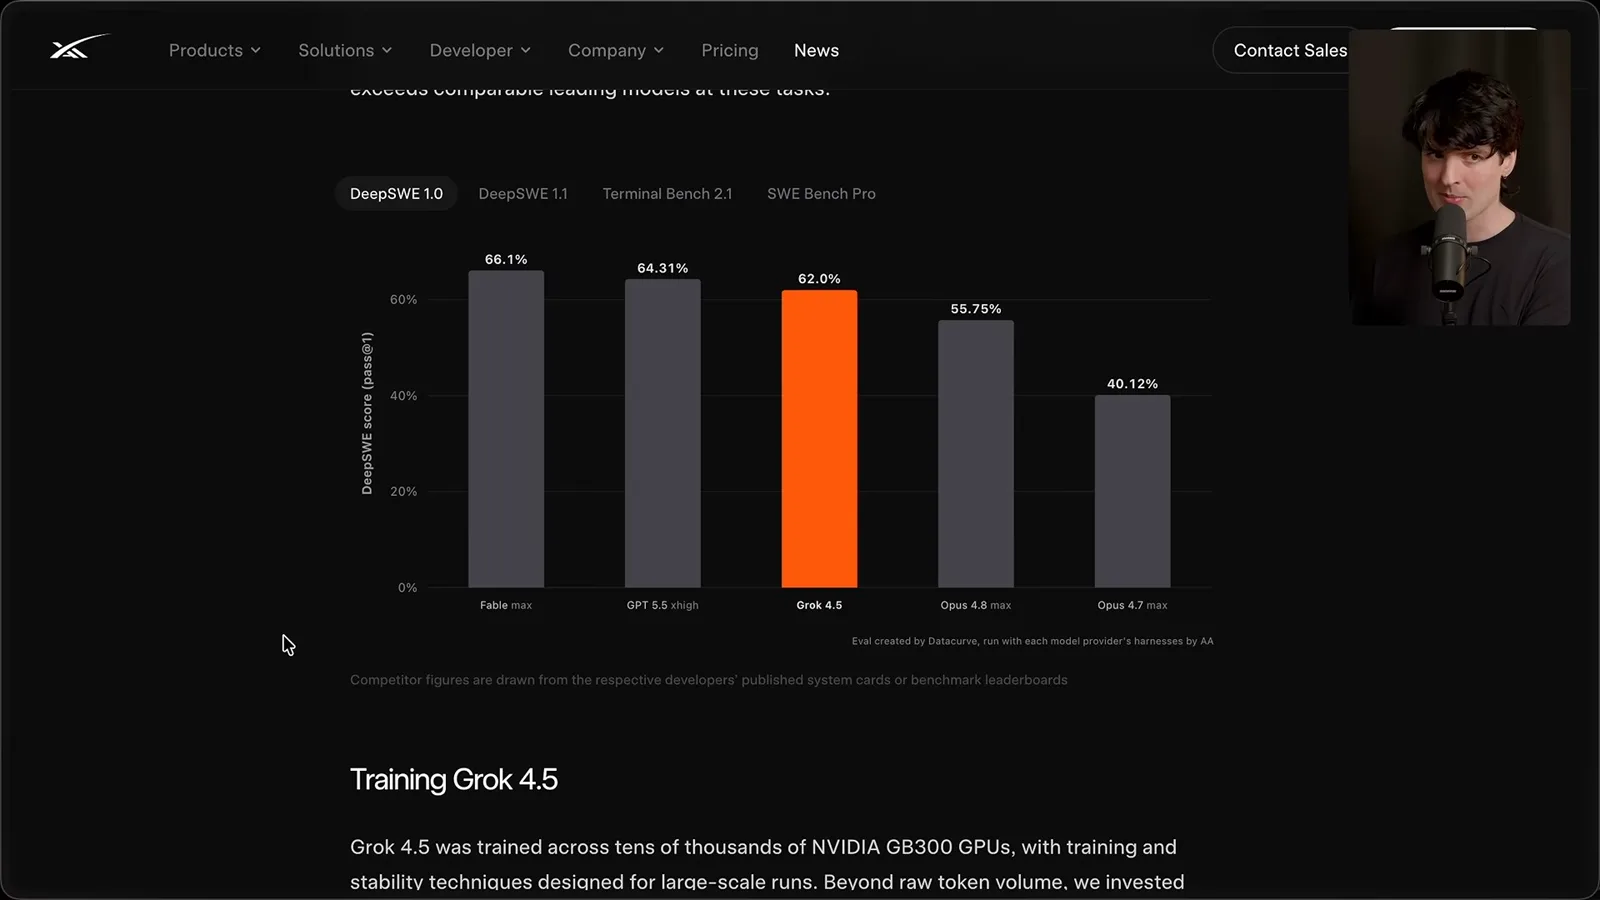
The launch materials emphasize coding, agentic tasks and engineering. On the displayed DeepSWE 1.0 chart, Grok 4.5 scores 62%, behind Fable max at 66.1% and GPT-5.5 xhigh at 64.31%, but ahead of the shown Opus result. These are particular model settings and a snapshot of one evaluation.
The creators describe a large mixture-of-experts model trained using significant compute, curated data and reinforcement learning on multi-step engineering tasks. I infer that it is a substantial new base model, but that inference is mine. They also show one-shot examples, including 3D work, and report a relatively fast serving speed.
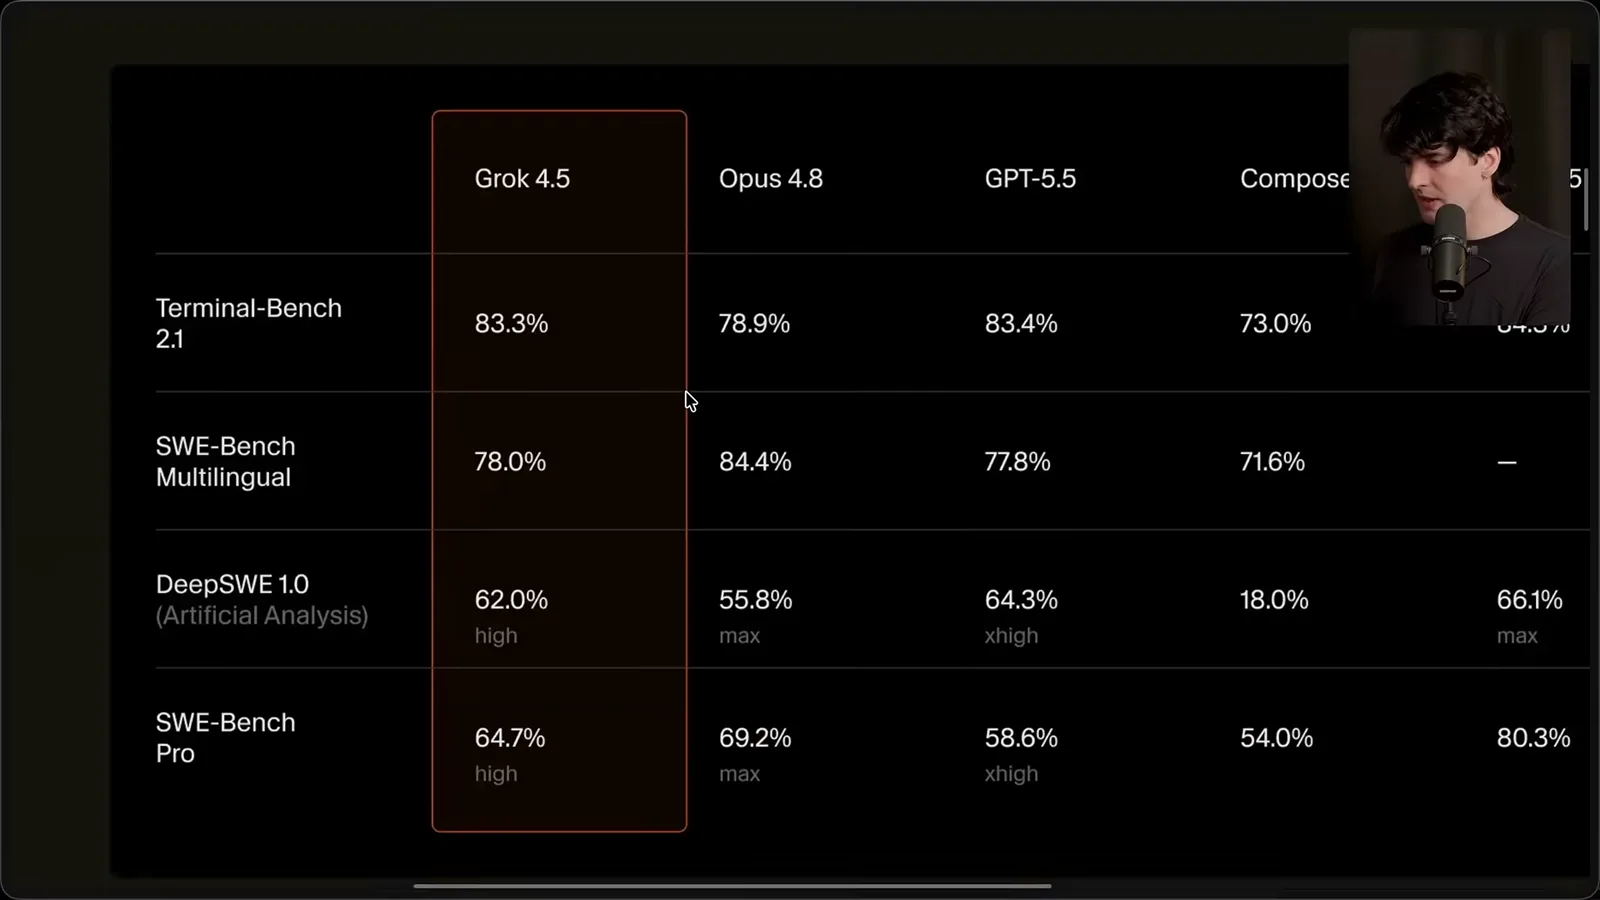
Cursor reports 83.3% on Terminal-Bench 2.1, close to the displayed 83.4% for GPT-5.5 and 84.3% for Fable. It also describes a joint training process using Cursor interaction data alongside broader technical material. Benchmark results depend on the harness and settings as well as the model.
At the time, Cursor advertised substantial included usage and an introductory promotion. My view is that a lower-cost model could help a tool provider offer a more attractive individual subscription, though plans, limits and prices can change and should be checked independently.
Cursor says the model was trained jointly using coding interactions and a broader mix of science, research and knowledge-work data. Its reinforcement-learning tasks were designed to be difficult and multi-step. I suspect that combination contributes to the results, but the precise contribution of each part is not established here.
CursorBench initially looks especially favorable: the graph shows a similar score to Fable high at a much lower per-task cost. But the chart has an essential caveat, so this comparison should not be treated as an independent clean measurement.
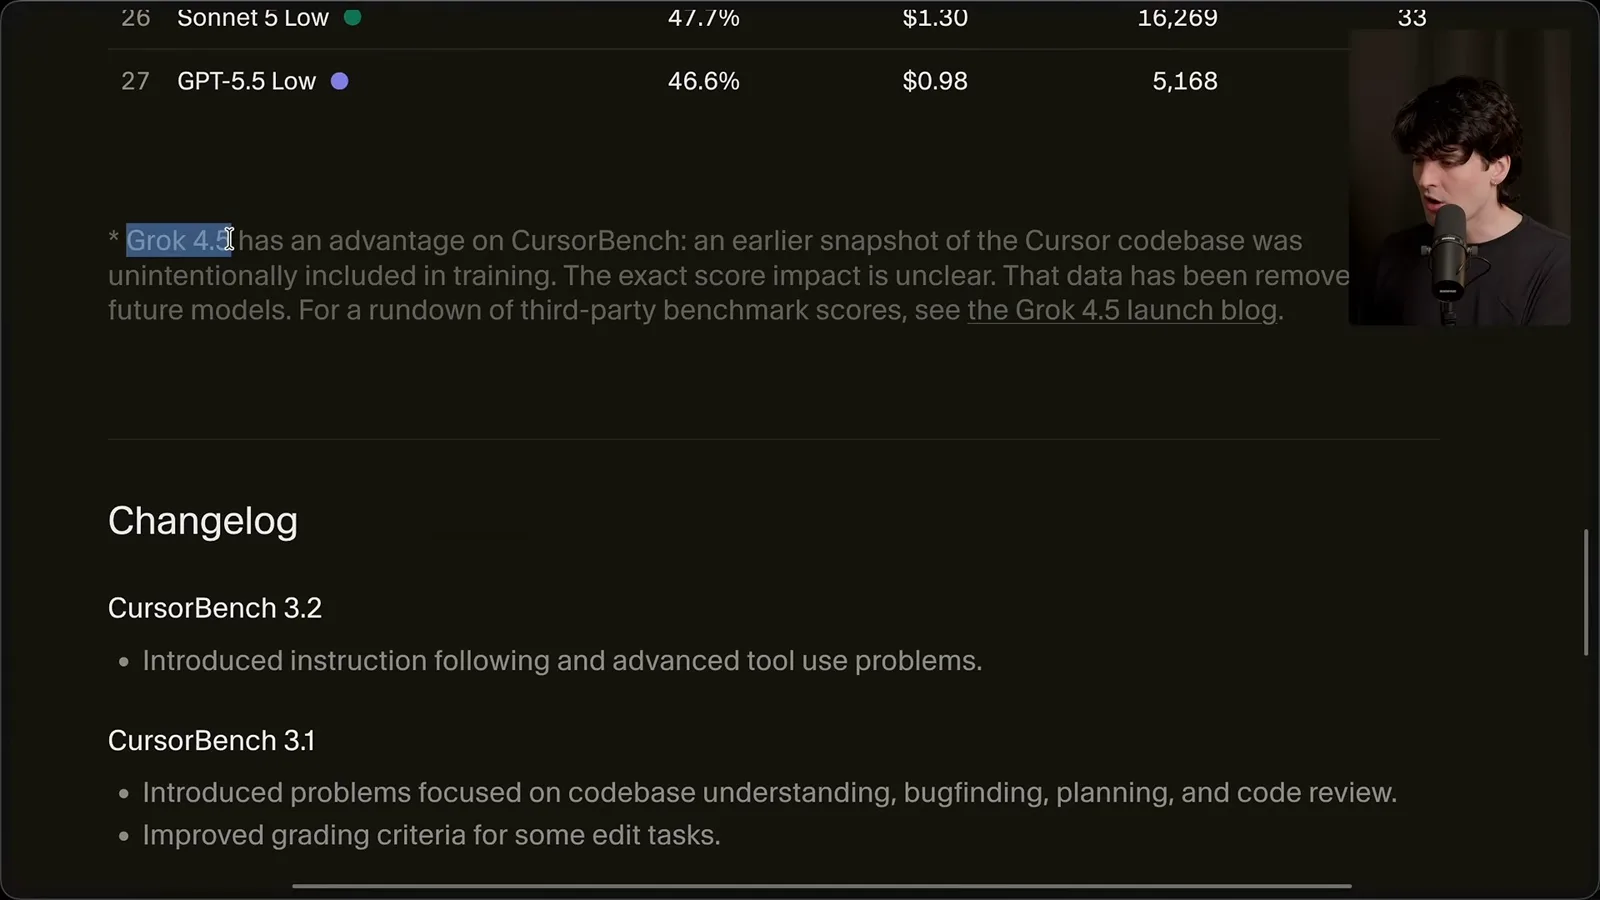
Cursor disclosed that an earlier snapshot of its own codebase was unintentionally included in Grok 4.5 training. Since CursorBench uses tasks from that codebase, the model has an advantage whose exact effect is unknown. The company says the data was removed from future models; I appreciate the disclosure, but the score needs that context.
Pricing and efficiency
He reviews historical token rates and benchmark costs. He also notes a weaker result on his own test.
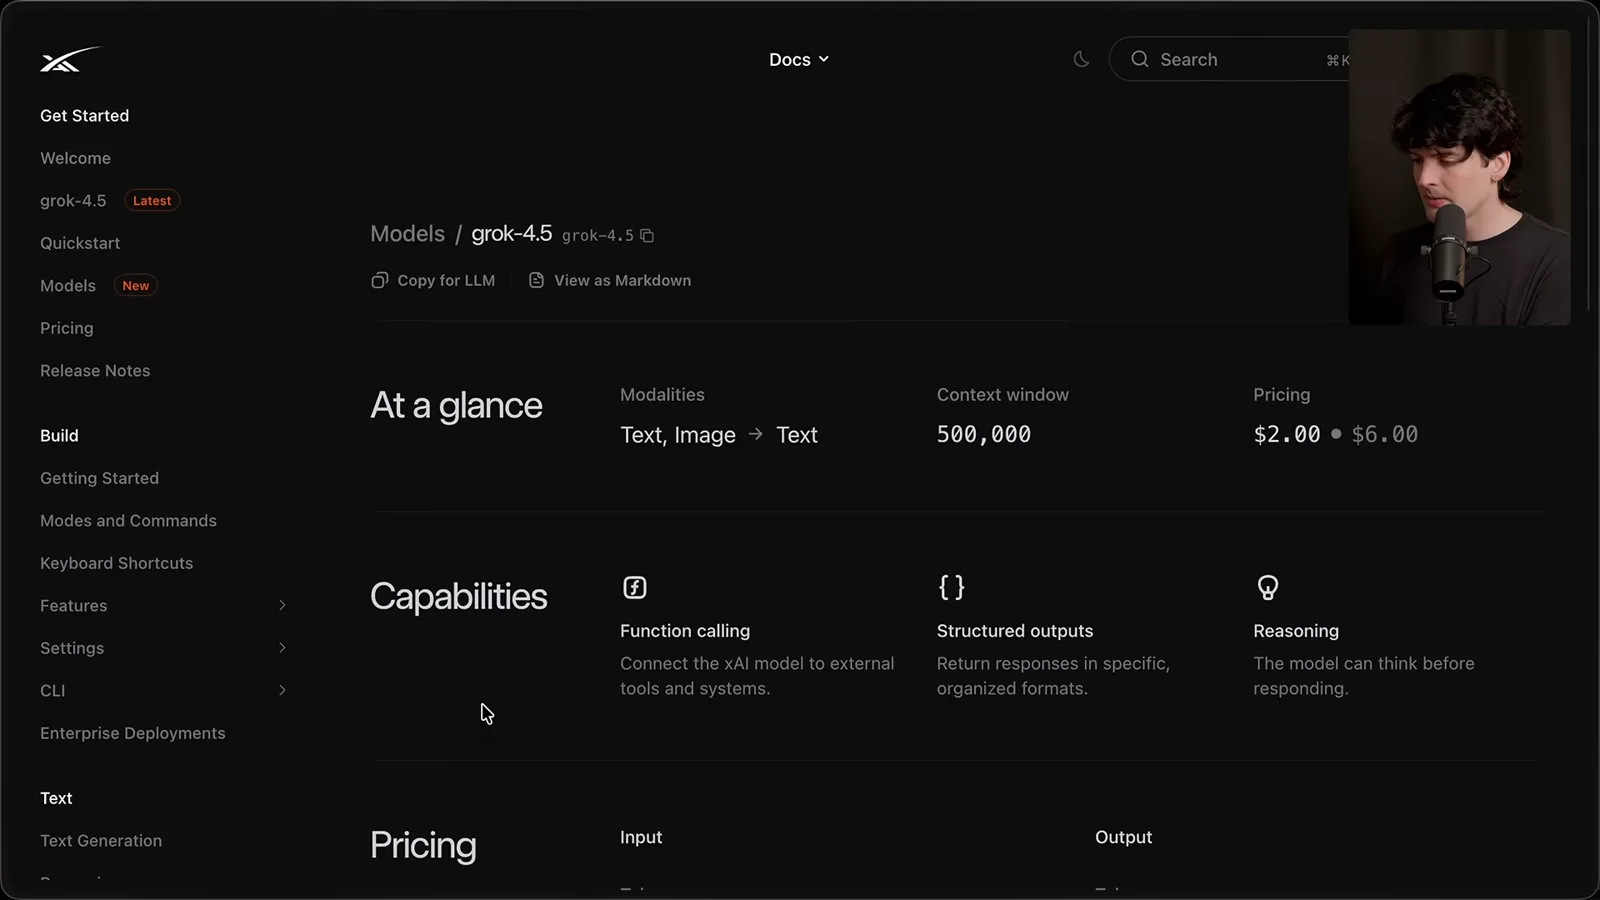
The API prices shown in the video were $2 per million input tokens and $6 per million output tokens for contexts under 200,000 tokens. Above that threshold the displayed rates doubled to $4 and $12, with a 500,000-token window. These are historical figures, not a current price quote.
I find the higher long-context rate awkward, particularly the increase on output tokens. My explanation about pricing incentives and GPU economics is speculation. Cost also depends on how many tokens a task consumes, so comparing the per-token rate alone is not enough.
Artificial Analysis placed Grok 4.5 at 54 on its Intelligence Index in the snapshot I show. In that suite it reported an average cost of about $0.31 per task, compared with about $2.75 for Fable in the displayed comparison. Those figures describe that evaluation, not the cost of arbitrary work.
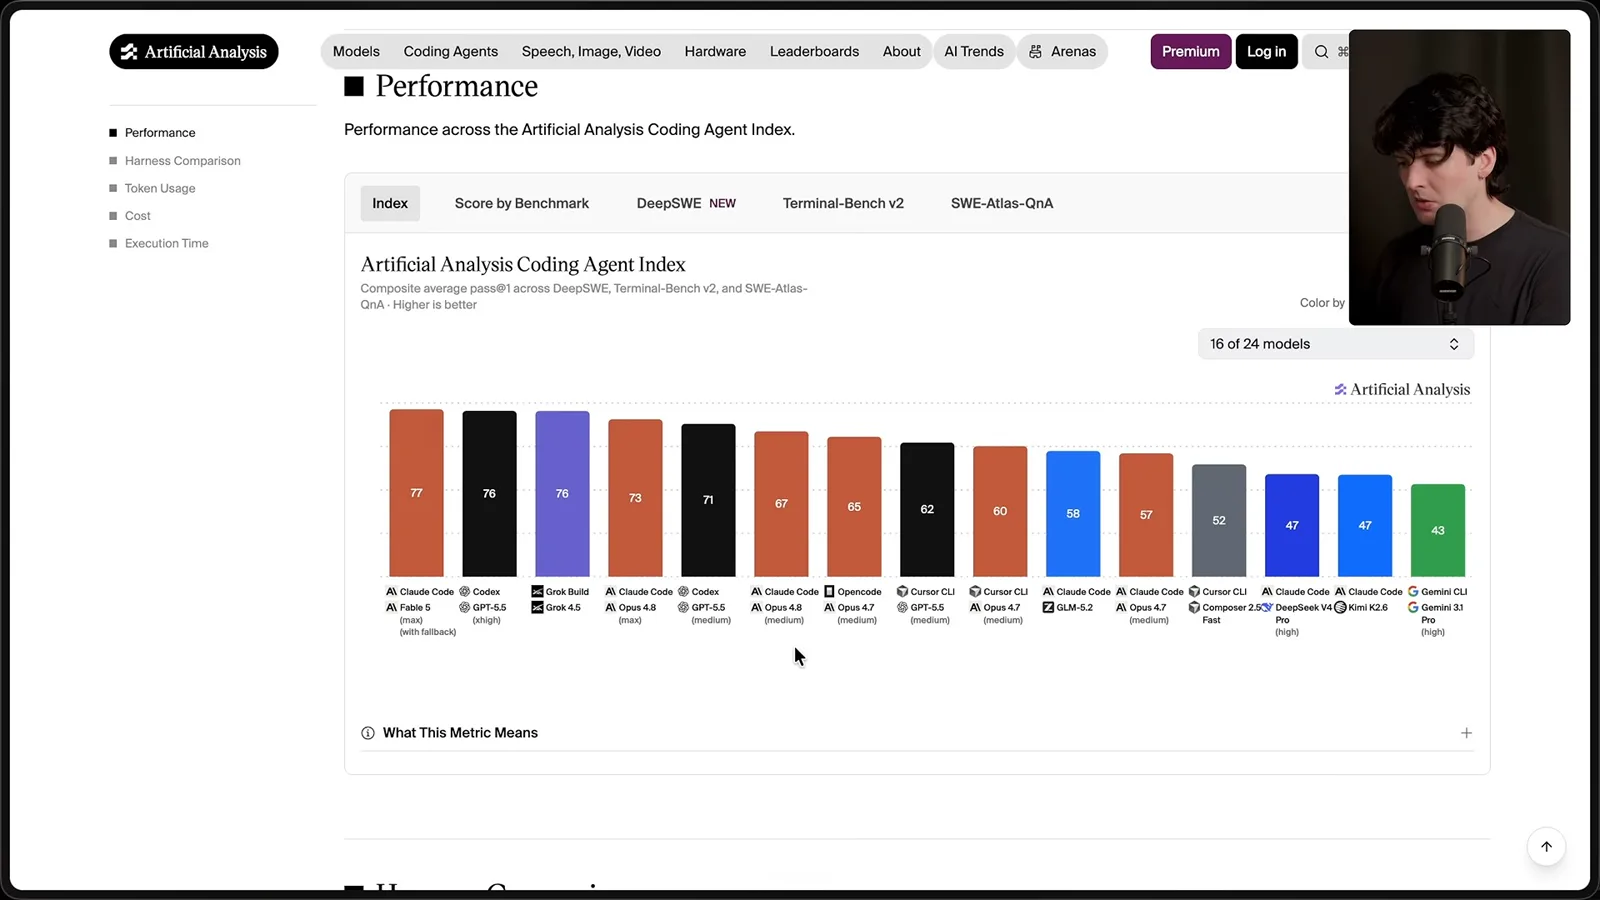
The coding-agent chart also shows strong performance with relatively few tokens for the displayed harness. I find that appealing because fewer tokens and lower rates can make the model feel faster and reduce cost. Different tasks and harnesses can change that tradeoff.
It does not excel on every test. On my Skatebench run it scored 76% and used roughly 2,100 tokens per response, making it relatively expensive in that particular test. A model that is efficient on one benchmark can spend much more effort on another.
Real coding work
Theo walks through a Lakebed audit and follow-up pull requests. He describes both the helpful interaction and remaining limits.
Benchmarks do not fully capture the feel of real work. I used Grok 4.5 to audit Lakebed before an open-source launch, looking for security, maintenance and release issues. It found many of the same concerns as other models and did particularly well when I asked it to start fixing them.
I supplied a pull request and a report and asked which issues were resolved. It answered that the PR closed two hard stops cleanly and one only partially, while most launch gates remained open. I liked that it separated completed work, caveats and remaining tasks instead of treating the report as finished.
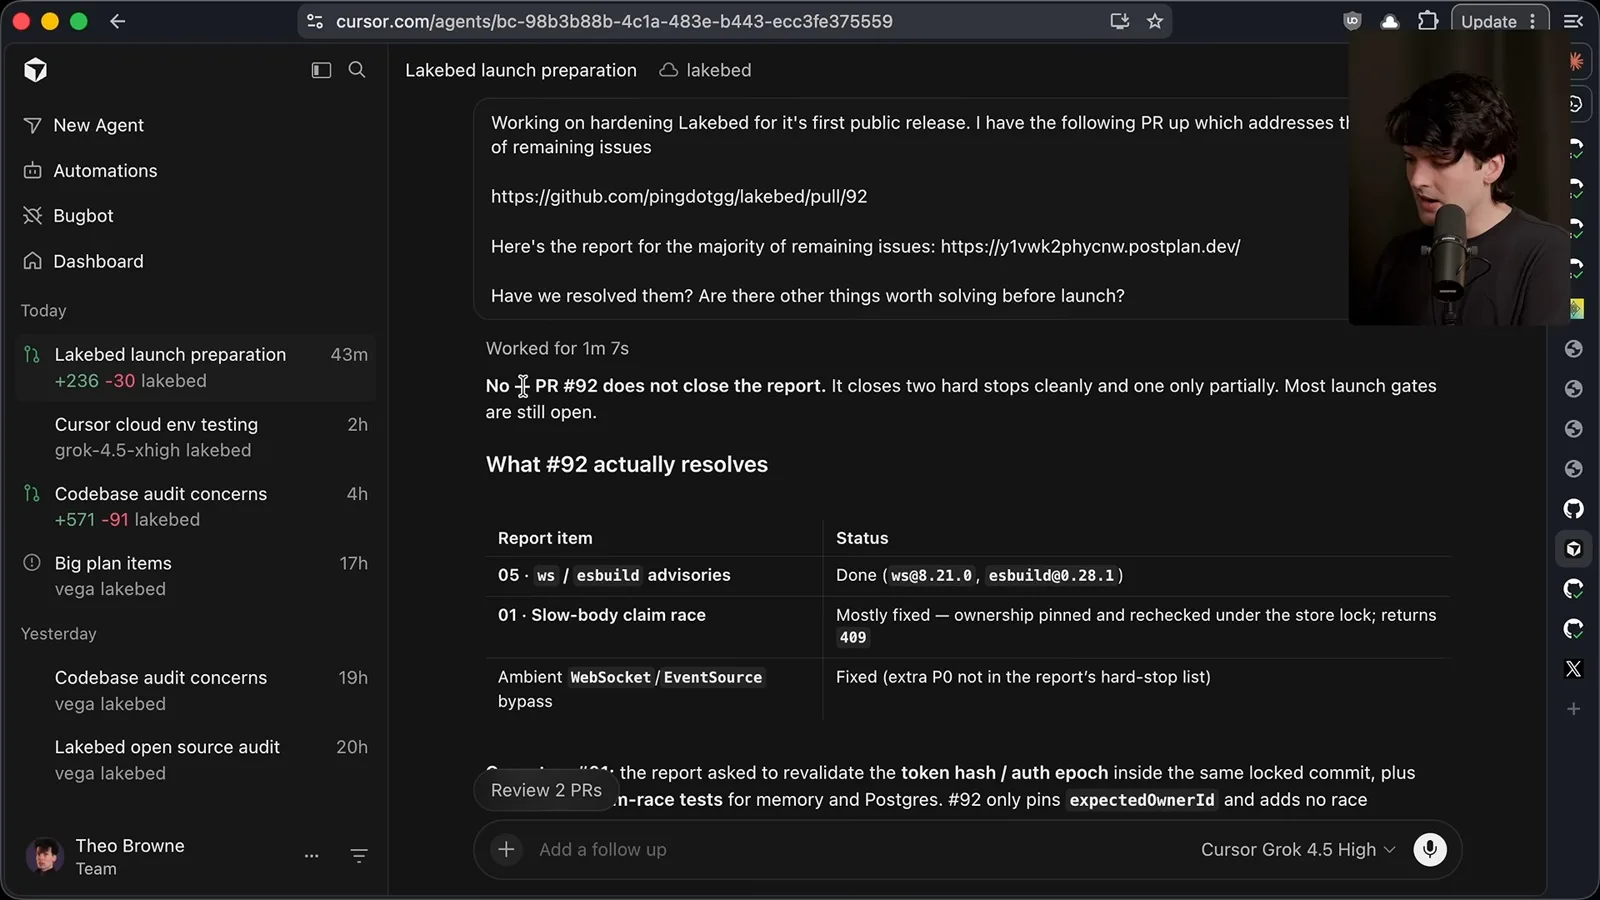
I then asked about specific numbered items in two different lists, giving a short prefix to disambiguate them. It addressed my questions directly, explained release-related concerns and helped prioritize the remaining work. That kind of context handling was pleasant in this session.
I gave it several instructions at once: create separate pull requests for selected issues, investigate another concern and leave other matters for later. It produced two PRs, answered questions and listed work to do before launch. I then asked it to address review comments and used a Cursor monitoring skill to follow the PRs.
Another agent suggested changes, and I passed those suggestions to Grok as a screenshot. It made the requested changes to one PR. My point is not that the output needs no review; it is that this multi-step back-and-forth was unusually smooth for me.
It did not find everything Fable found, and its code was not as thorough as GPT-5.6 in my experience. Still, it handled a large interactive task quickly and at relatively low cost. I see it as a useful coding option, while my comparisons remain based on limited personal testing.
3D and model generations
A game experiment shows both visual progress and usability problems. Theo closes with a tentative comparison of orchestration capabilities.
I pushed it further by asking it to turn my Fish Slop game into 3D. It made an environment, creatures and tank geometry, and I liked some of the 3D assets more than those produced in my other experiments. The initial layout was broken, however, and the result had obvious problems.
The submarine and creature models were rough, and movement controls were reversed or awkward. A follow-up fixed some pointer behavior but not everything. I would not ship the game as it stood, even though the visual progress surprised me.
I think of Fable and GPT-5.6 as a newer generation partly because of their ability to orchestrate subagents and break large jobs into smaller pieces. My attempts at that with Grok 4.5 were limited, but it did not show the same nuance and sometimes got stuck when a process hung.
Some differences may come from the harness and others from the model. My gaming analogy is that Grok 4.5 feels like an exceptionally good product built with an earlier generation of technology, while newer approaches have already arrived. That is a subjective framing, not a measured generation boundary.
I am impressed by how quickly xAI and Cursor have improved the offering. More competition could put pressure on other providers to make models faster, cheaper and more capable. Whether that happens remains to be seen, but I am eager to see what they build next.
Mehr aus diesem Kanal
 38:47EN
 Theo - t3․gg· 28. Okt. 2026Theo’s Long-Running Agent Experiments: Verification, Compute and CostTheo Browne · Ping LabsA skateboard game and two compiler projects show how repeated checks and flexible compute can sustain agent work—and how expensive those loops can become.
 36:07ENTheo - t3․gg· 27. Okt. 2026Theo on Token Costs, Coding Agents, and the Price of AI CapabilityTheo Browne · Ping LabsA viral estimate of Lauren's AI spending prompts a closer look at cache pricing, benchmarks, and the changing work of coding agents.
 30:37ENTheo - t3․gg· 26. Okt. 2026Theo’s Three Skills for Reviewing and Shipping with Coding AgentsTheo Browne · Ping LabsHow sol-loop, full-send and full-stop encode review, verification and different levels of merge authority.
 0:43ENTheo - t3․gg· 23. Okt. 2026Theo Distinguishes Security Vulnerabilities from Active AttacksTheo Browne · Ping LabsA short explanation of why disclosed software flaws and reported attacks are different kinds of security news.
 29:22ENTheo - t3․gg· 22. Okt. 2026Theo on Security Vulnerabilities, Stolen API Keys and AITheo Browne · Ping LabsA look at the gap between vulnerability disclosure and patching, and a speculative account of why stolen inference keys may be valuable.
 31:13ENTheo - t3․gg· 20. Okt. 2026Theo on Why Smarter Models Help More Than DevelopersTheo Browne · Ping LabsFrom game modifications to compiler experiments, Theo revisits his assumptions about who benefits from more capable AI.