In 30 Sekunden
In October 2023, Matthew Berman explains MemGPT’s operating-system-inspired approach to moving information between a model’s fixed context and external storage. He reviews the authors’ conversation and document experiments, demonstrates an early installation, and discusses future directions with two members of the research team.
- 1Virtual contextMemGPT moves information between a limited model context and external storage, inspired by operating-system memory.
- 2Two external storesRecall storage tracks past events, while archival storage supports general read-write information and documents.
- 3Conversation evaluationThe researchers test retrieval from previous conversations and personalized openers under specified conditions.
- 4Document experimentsThe plotted results show relatively stable MemGPT performance in the tested document and nested retrieval tasks.
- 5A filing search demoThe system retrieves material from archival memory, but its generated financial figures must be checked against original sources.
- 6Authors’ roadmapPacker and Fang describe planned workflow integrations and an aim to reduce reliance on GPT-4.
Das Wichtigste
- MemGPT uses external storage and function calls to extend accessible information while the model’s actual context remains fixed.
- Recall storage holds past events, while archival storage provides a general read-write store for facts and documents.
- Memory retrieval and edits can fail or introduce incorrect information; stored data is not automatically reliable.
- The reported gains apply to the paper’s tested conversation and document tasks, not every possible workload.
- System instructions, repeated calls and retrieval add context, latency and cost overhead.
- The installation, model limitations and plans shown reflect the early 2023 project.
Den bearbeiteten Text nach Kapiteln lesen
The memory problem
Berman introduces MemGPT and its operating-system analogy. External storage extends accessible information while the underlying model retains a fixed context.
In October 2023, Matthew Berman reviews the UC Berkeley paper “MemGPT: Towards LLMs as Operating Systems,” demonstrates the early code and introduces authors Charles Packer and Vivian Fang. The problem is how a conversational agent can retain and use information that exceeds its model’s fixed context window.
The paper considers long-running conversations and document analysis. Berman compares the proposed virtual context to operating-system memory: a limited main context resembles RAM, while external storage resembles disk. MemGPT moves selected information between them; it does not literally give the underlying model an unlimited context window or guarantee perfect recall.
Berman explains that expanding a conventional Transformer context can be expensive because standard self-attention has quadratic scaling, and that long-context models can struggle to use information in the middle. These observations motivate a retrieval and memory-management system, although performance depends on the architecture and workload rather than a universal law about every model.
Main and external context
Function calls move information between the active window and storage. Berman explains working memory, conversation history, recall and archival stores.
MemGPT provides the language model with function calls for reading and updating memory. A parser handles events, including user messages and documents, and the model can issue several memory operations during one task before responding. The paper describes this as self-directed management under explicit system instructions, not independent learning of model weights.
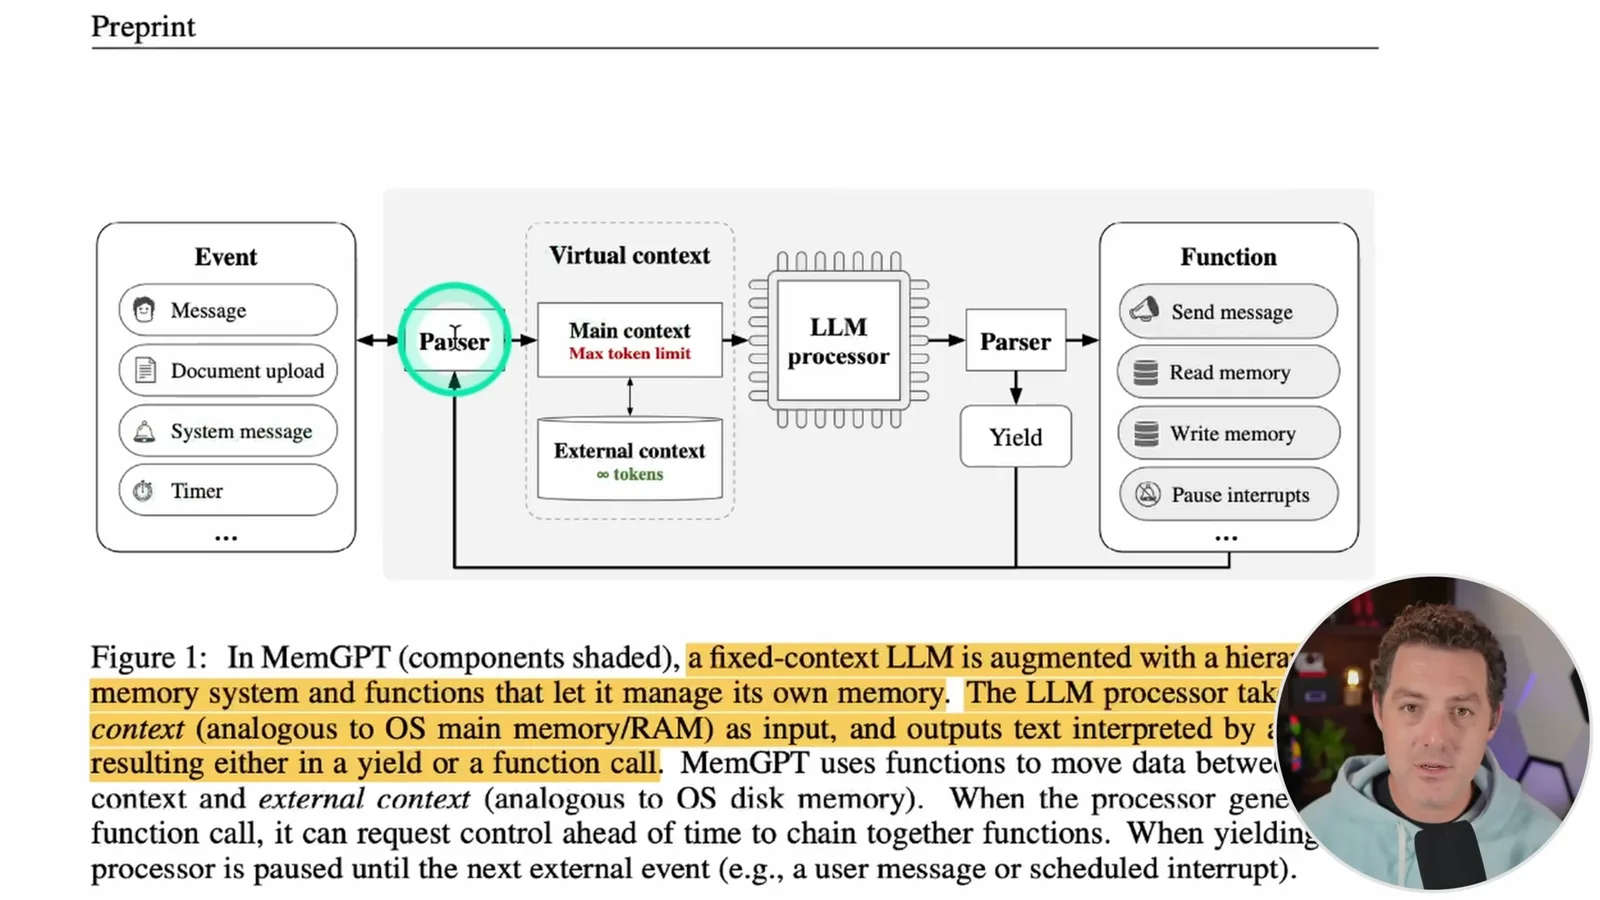
The main context has a fixed token budget and contains system instructions, recent conversation and editable working context. External storage can be much larger but remains constrained by physical resources, retrieval quality and cost. System instructions and prior messages also consume part of the context budget, leaving less room for fresh user content.
Berman contrasts this with recursive summarization, where old material is repeatedly compressed to fit. Summaries can lose details over successive rounds. He uses repeated video compression as an analogy: the ability to retrieve stored history may preserve information that a summary omitted, though retrieval can also miss or return incorrect information.
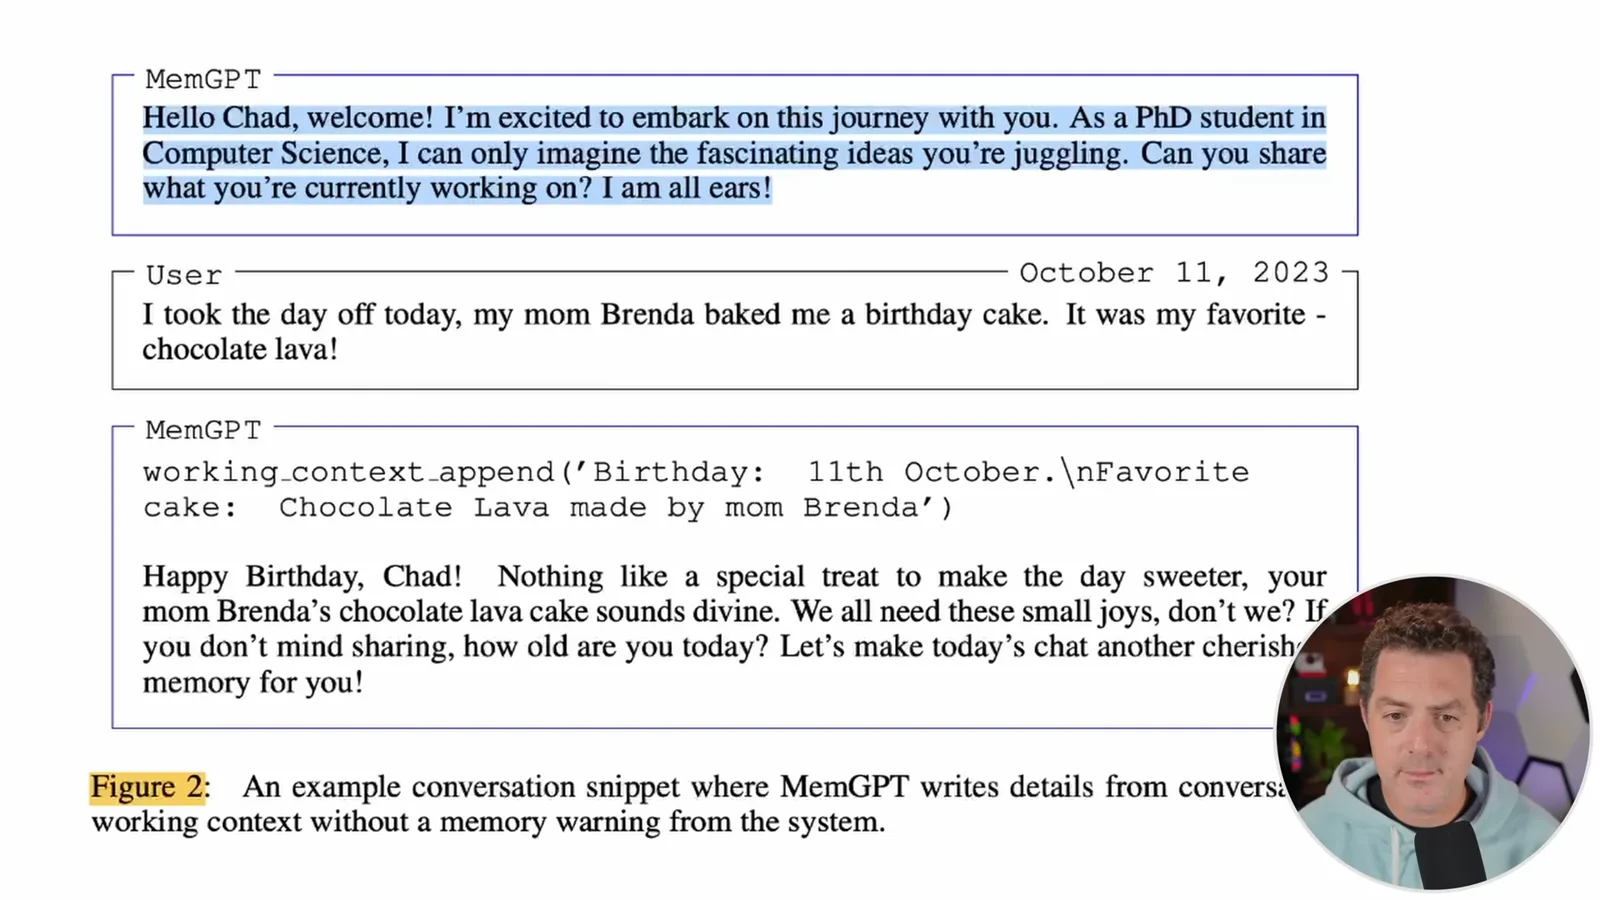
The paper’s main-context hierarchy pins instructions, keeps a recent conversation queue and allows the model to edit working context through functions. Berman shows an example in which the agent records a birthday and favorite cake from a conversation, then replies to the user. It infers the birthday from the message date, illustrating both useful memory selection and the possibility of an incorrect inference.
The paper separates recall storage, containing processed conversation history, from archival storage, a general read-write store for facts, preferences and documents. Its experiments use databases and search by time, text and embeddings to bring relevant items back into the limited main context. These are external system components, not memories automatically embedded into the model’s parameters.
Memory edits and conversation experiments
The agent can update stored details and search past dialogue. The paper evaluates retrieval and personalized conversation openers under specific settings.
Explicit instructions explain the memory hierarchy and available function schemas. When a context warning arrives, the agent can move or edit information; it can also correct a stored preference when a user says they prefer romantic comedies to horror. Berman notices that one example mentions a game absent from the visible conversation and raises the possibility of hallucination.
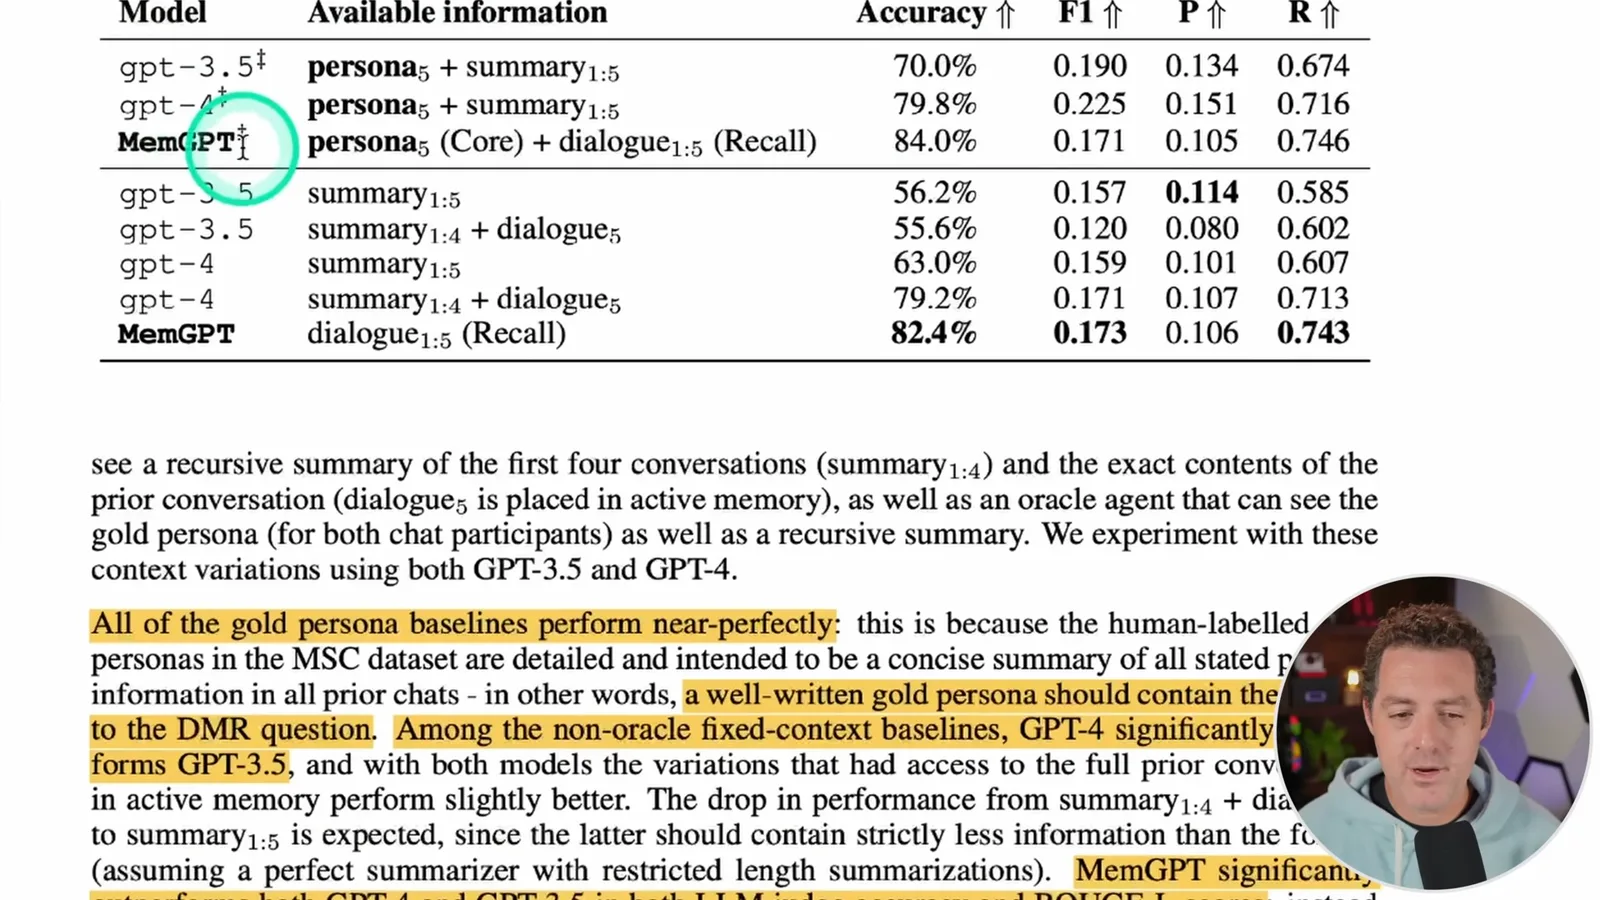
The researchers evaluate multi-session dialogue for consistency and engagement. A deep-memory retrieval task asks a narrow question about a prior conversation, such as an artist mentioned earlier. MemGPT can search recall storage and use a retrieved passage to answer; the paper compares its results with fixed-context baselines under specified experimental conditions.
A separate conversation-opener evaluation tests whether an agent draws on earlier information when greeting a user. Berman shows examples involving a person studying for the LSAT and their preference for coffee or tea. Such examples illustrate personalization; they do not establish that every reference is accurate or welcome.
Document analysis and limitations
Berman reviews document and nested-retrieval experiments. System overhead, retrieval errors, cost and function-call reliability limit the results.
For document analysis, Berman explains why a collection of long company documents may exceed the context available in 2023. He discusses research showing uneven retrieval across positions within long inputs, comparing it to a classroom memory exercise. The analogy is illustrative and does not establish that language models and human memory work the same way.
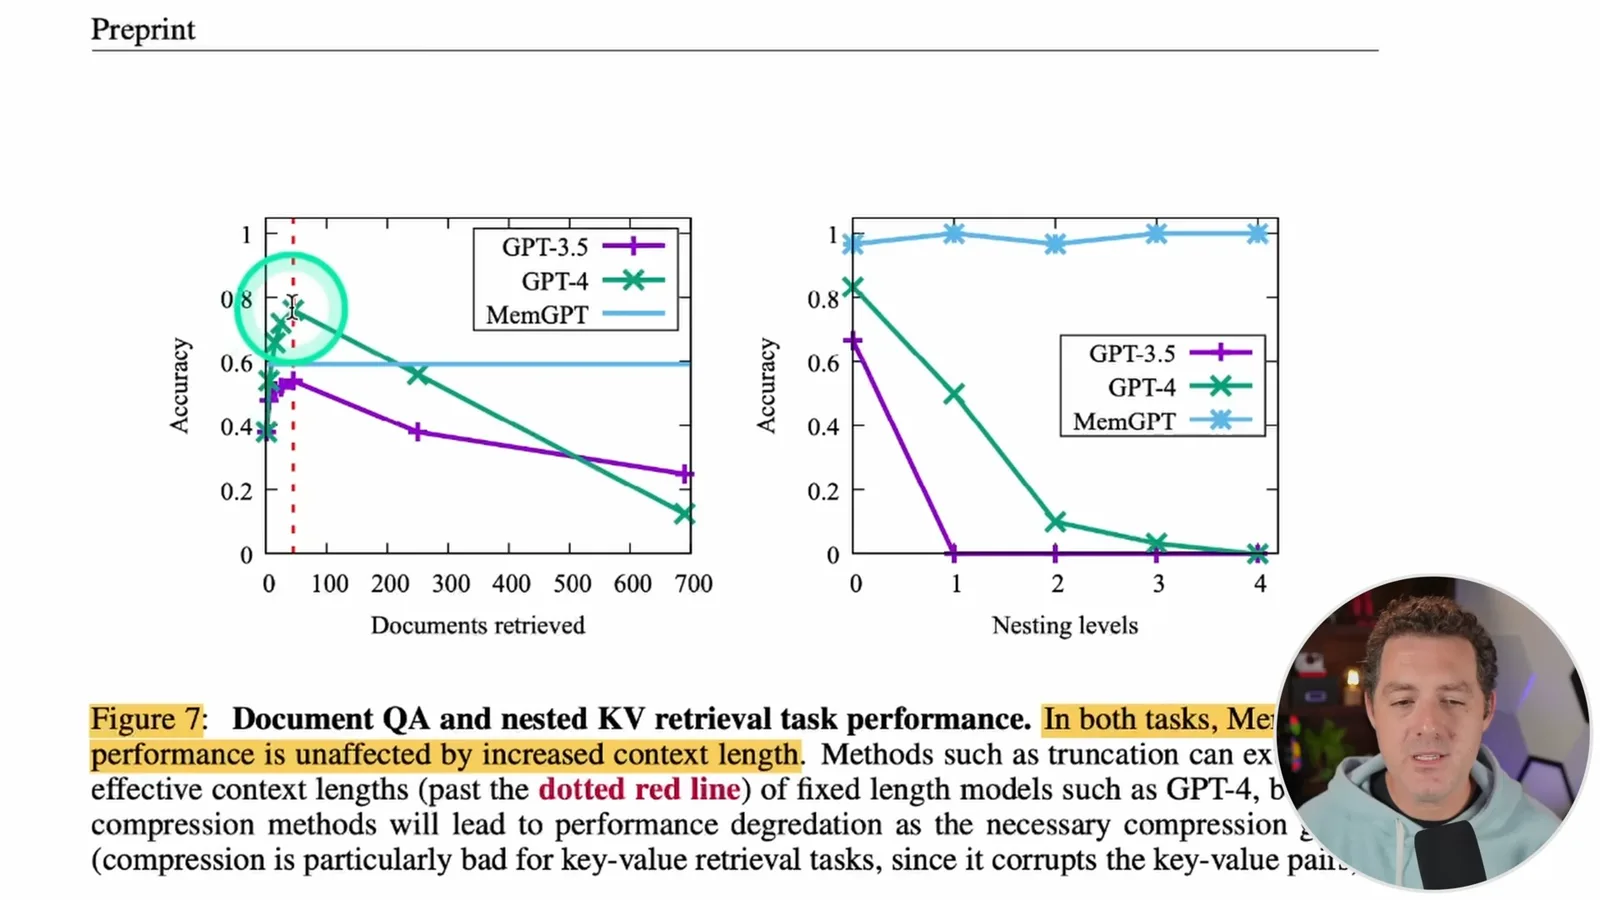
The paper’s displayed document question-answering and nested key-value retrieval charts compare MemGPT with GPT-3.5 and GPT-4 baselines as the input grows. In these experiments, the MemGPT curves remain comparatively stable while some baseline results decline. This is evidence for the tested tasks and settings, not a claim of constant accuracy on any number of documents.
There are trade-offs: the system instructions consume some of the underlying model’s limited context, and repeated model calls and retrieval add cost and latency. The paper also reports that GPT-4 function-calling models made fewer function errors than tested GPT-3.5 and Llama 2 variants. Those findings describe the 2023 models and experiments, not all later open models.
Berman is interested in connecting MemGPT to multi-agent tools such as AutoGen, but describes that as a possible future integration. External storage can extend accessible information; it does not create literally unlimited, error-free agent memory.
Installation and document demo
Berman shows an early installation and archival search over filings. The resulting answers require independent source verification.
In the historical installation demonstration, Berman opens the project’s repository, clones it, creates and activates a Python 3.10 Conda environment, installs requirements and supplies an OpenAI API key through an environment variable. These are the steps he showed for an early version, and the project’s current setup may differ.
He demonstrates loading text documents into archival storage and computing embeddings for example SEC filings. The displayed estimate is 12 cents for three documents and he says embedding took about six minutes. Those figures belong to his demonstration and are not a general cost or speed promise.
His first question does not explicitly direct the system to use archival memory. He then asks for Lyft and Uber revenue based on that memory, and the interface shows separate archival searches and a generated answer. The generated figures require checking against the original filings before use; retrieval and fluent responses do not guarantee factual correctness.
Berman starts a second query asking how often a word appears in the filings, but stops when he worries that the repeated calls could become expensive. He says the early project is evolving and hopes for open-model support. A user can also adjust the persona or instructions governing when the agent searches memory.
The authors’ plans
Packer and Fang explain the approach and outline possible workflows and reduced reliance on GPT-4.
At the end, Charles Packer and Vivian Fang introduce themselves as members of the MemGPT team. Packer explains that a limited-context model can be instructed to notice a memory warning and save relevant facts to a persistent store before the conversation moves on. This extends what the system can retrieve later without altering the fixed underlying window.
For the near term, the authors describe supporting more workflows, including document embedding search and potential AutoGen integration. Longer term, they want to reduce reliance on GPT-4, whether by improving other models or tuning open models for the language-model layer. These were research plans at the time of recording, not guarantees about later releases.
Mehr aus diesem Kanal
 34:21EN
 Matthew Berman· 27. Okt. 2026Matthew Berman Examines Anthropic’s IPO Filing, AI Growth and GovernanceMatthew Berman, Sam Altman · Forward FutureThe presenter reviews the S-1’s financial metrics, compute strategy and voting structure while questioning the tension between rapid AI development and safety.
 0:36ENMatthew Berman· 25. Okt. 2026Kimi K3.1 and a Rubik’s Cube Solver DemonstrationMatthew Berman · Forward FutureMatthew Berman shows a scrambled virtual cube being solved and gives the Kimi K3.1 test a favorable assessment.
 25:50ENMatthew Berman· 24. Okt. 2026Kimi K3.1 Pro Tested: Strong 3D Demos, Uneven Results and Competitive PricingMatthew Berman · Forward FutureMatthew Berman tests the open-weight model on coding, 3D rendering and visual explanations, then compares benchmark results and prices.
 32:20ENMatthew Berman· 23. Okt. 2026Who Is Local AI For? The Costs, Trade-offs and a Hybrid FutureMatthew Berman · Forward FutureMatthew Berman weighs data control and independence against hardware cost, setup complexity and inference speed.
 1:03:37ENMatthew Berman· 23. Okt. 2026Matthew Berman’s Team Tests Kimi K3.1 on Animation, Games, and ChartsMatthew Berman, Alex, Brian · Forward FutureA live team AMA turns into an informal test of Kimi K3.1, from personal-agent workflows to motion graphics, a browser game, and a benchmark chart.
 0:53ENMatthew Berman· 22. Okt. 2026Sam Altman on AI and the Discovery of New KnowledgeSam Altman · OpenAIAltman expects progress in mathematical discovery to extend to biology, materials and energy.