In 30 Sekunden
Matthew Berman discusses the original 2024 Genie research alongside Sora, Gemini, generated audio and AI-driven characters. He imagines personalized immersive worlds and raises the simulation hypothesis, but the demonstrations are separate prototypes and do not establish a complete production-ready or physically accurate system.
- 1Genie’s approachA model generates action-controllable frames from an input image using learned latent actions.
- 2Training dataThe initial collection exceeded 200,000 hours, while the main model used a filtered set of approximately 30,000 hours.
- 3Robotics experimentA separate smaller model was trained on robot videos without action labels.
- 4Long-context code assistanceA Gemini demonstration uses Three.js source and documentation to answer questions and suggest modifications.
- 5Simulation hypothesisA convincing virtual environment would raise philosophical questions but does not prove our universe is simulated.
Das Wichtigste
- The original Genie generates action-conditioned visual frames from an image and was primarily demonstrated on platformer-like environments.
- The principal model used a filtered dataset of roughly 30,000 hours from a larger initial video collection.
- The early system had limited speed, context and physical fidelity; the video does not demonstrate complete AAA game generation.
- A separate robotics-video experiment suggests a research direction rather than a validated general robot controller.
- Combining these tools and the simulation hypothesis are speculative interpretations, not demonstrated conclusions.
Den bearbeiteten Text nach Kapiteln lesen
Video generation and Genie
Berman imagines personalized media and introduces the original Genie research. The early system generates action-conditioned visual frames rather than complete production games.
I imagine a future in which a person describes a game or film and AI creates a personalized experience. That could change how studios work, but the idea that complete AAA games or movies will be generated on demand in the near future is my prediction, not a capability demonstrated in this February 2024 video.
OpenAI's early Sora examples showed impressive text-to-video generation. I described them as demonstrating an understanding of physics and consistent objects, but realistic-looking clips do not establish a complete or reliable physical model. The selected videos are demonstrations, and the system can make visual and physical errors.
Google DeepMind introduced Genie, a research model that generates action-controllable video-like environments from images, including synthetic scenes, photographs and sketches. Rather than constructing a conventional game engine with explicit rules, it predicts visual frames in response to learned latent actions. The original work primarily demonstrates simple platformer-like environments.
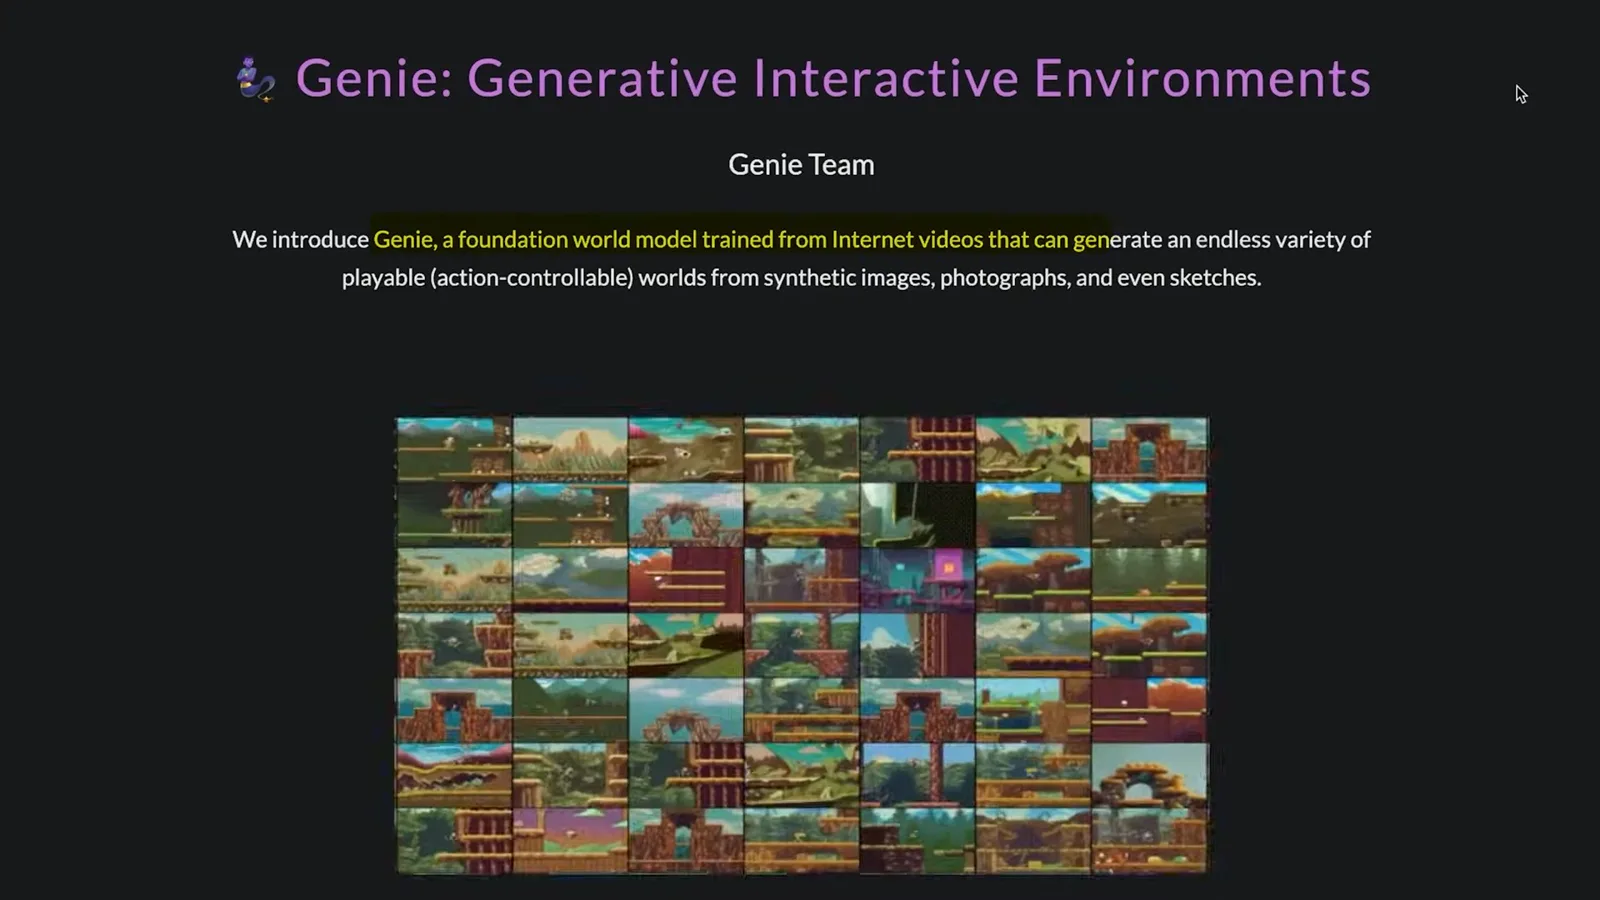
I imagine a Sora-generated scene becoming an interactive game through Genie. This is a proposed future combination, not a demonstrated end-to-end product. The early Genie research does not establish production-ready games, unrestricted 3D interaction or correct physics in every generated environment.
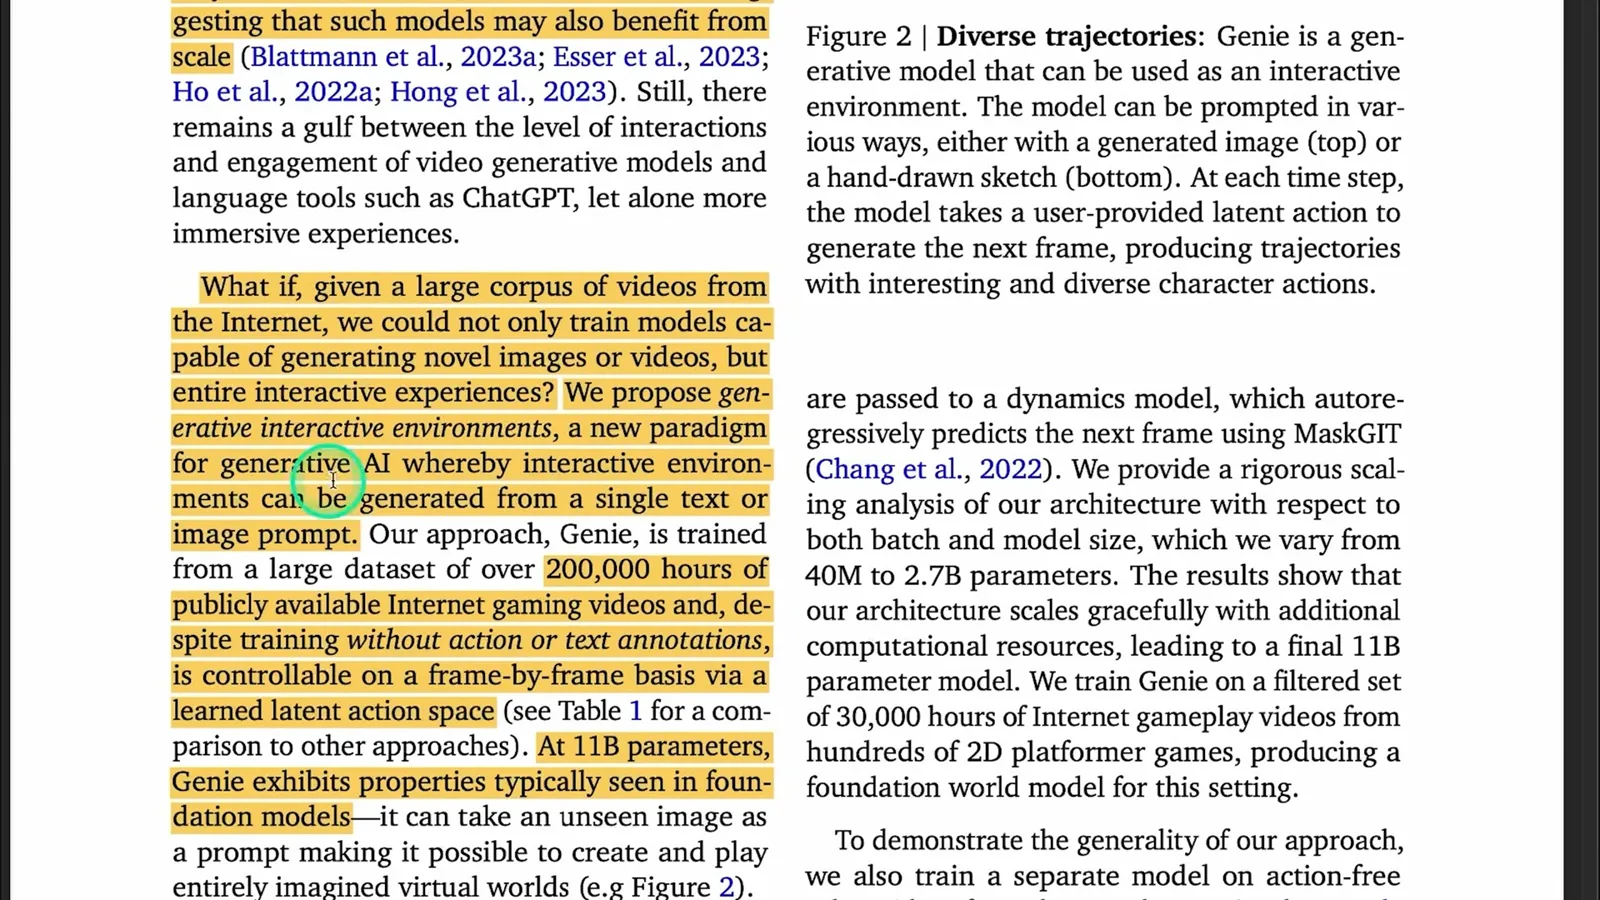
The team learned an action representation from video without ground-truth action labels, allowing the model to respond to actions frame by frame. The paper's original collection exceeded 200,000 hours, but the principal platformer model used a filtered set of roughly 30,000 hours. Unlabeled actions do not mean the system learned without video data or any prior design choices.
Robotics and the research method
The paper explores a separate robot-video model and describes learning latent actions. The 11-billion-parameter platformer model uses a filtered training set and has important speed and fidelity limitations.
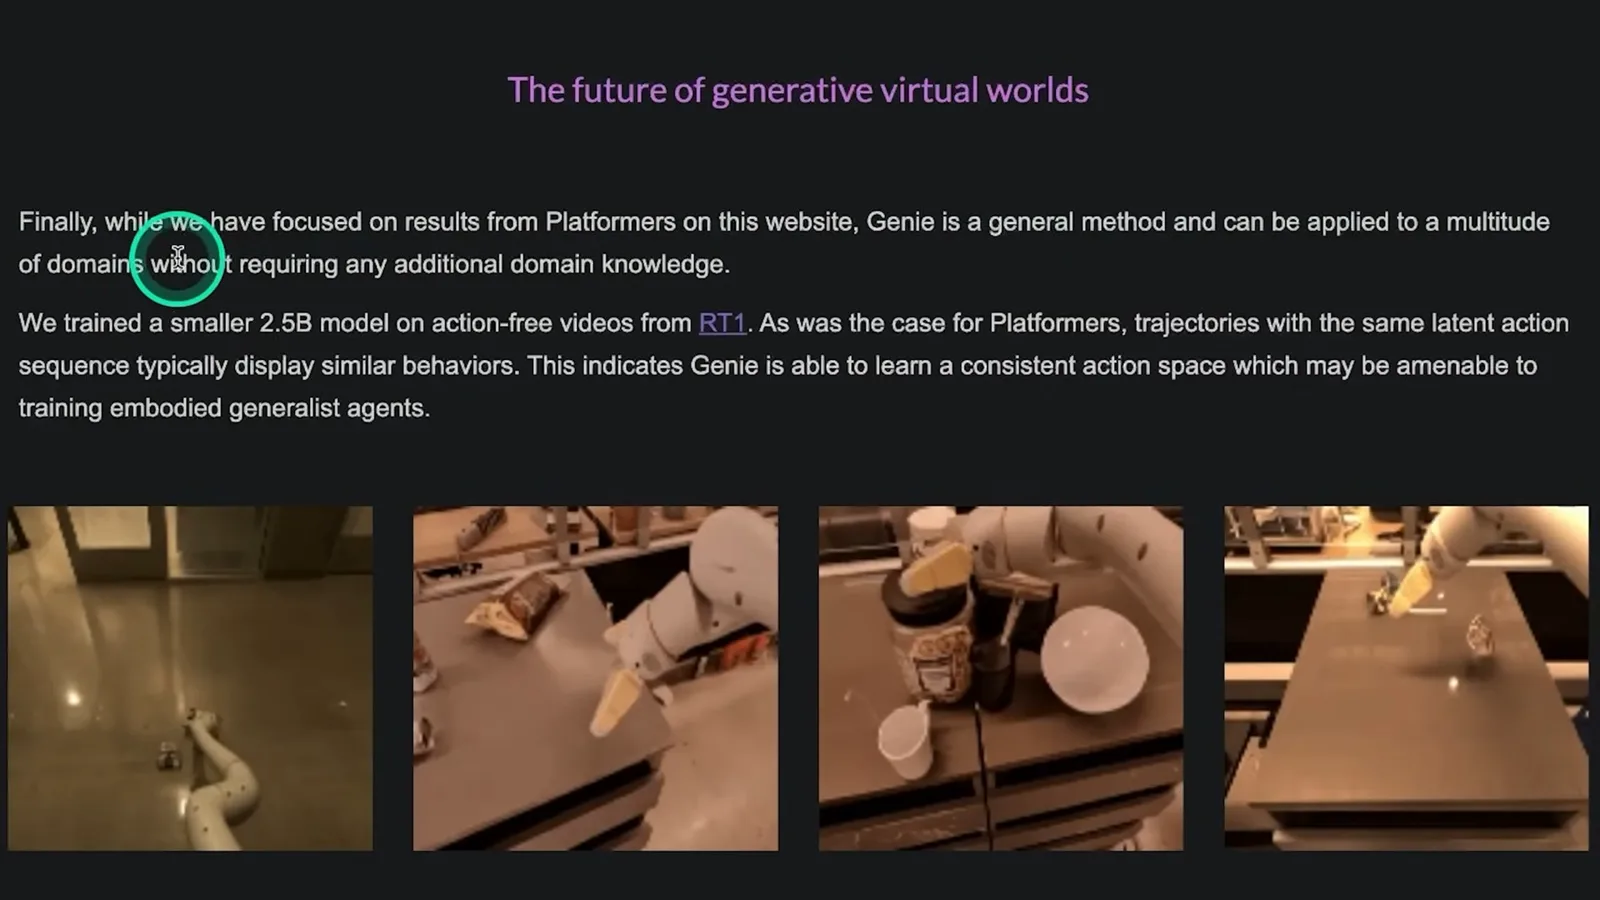
The researchers also trained a smaller 2.5-billion-parameter model on action-free robotics videos, reporting similar responses to corresponding latent actions. That suggests a possible research direction for embodied agents; it does not demonstrate a general robot controller or verified transfer to physical tasks.
The demonstrations include predicted changes in deformable objects. These generated frames can resemble manipulation, but visual plausibility is not proof of physically accurate simulation. I relate the work to synthetic data and robot training, where real-world testing remains important.
The Genie paper describes an 11-billion-parameter model with a video tokenizer, dynamics model and learned latent actions. Its early interactive system operated around one frame per second, with limited context and possible unrealistic continuations. The research result should not be confused with a smooth, finished commercial game.
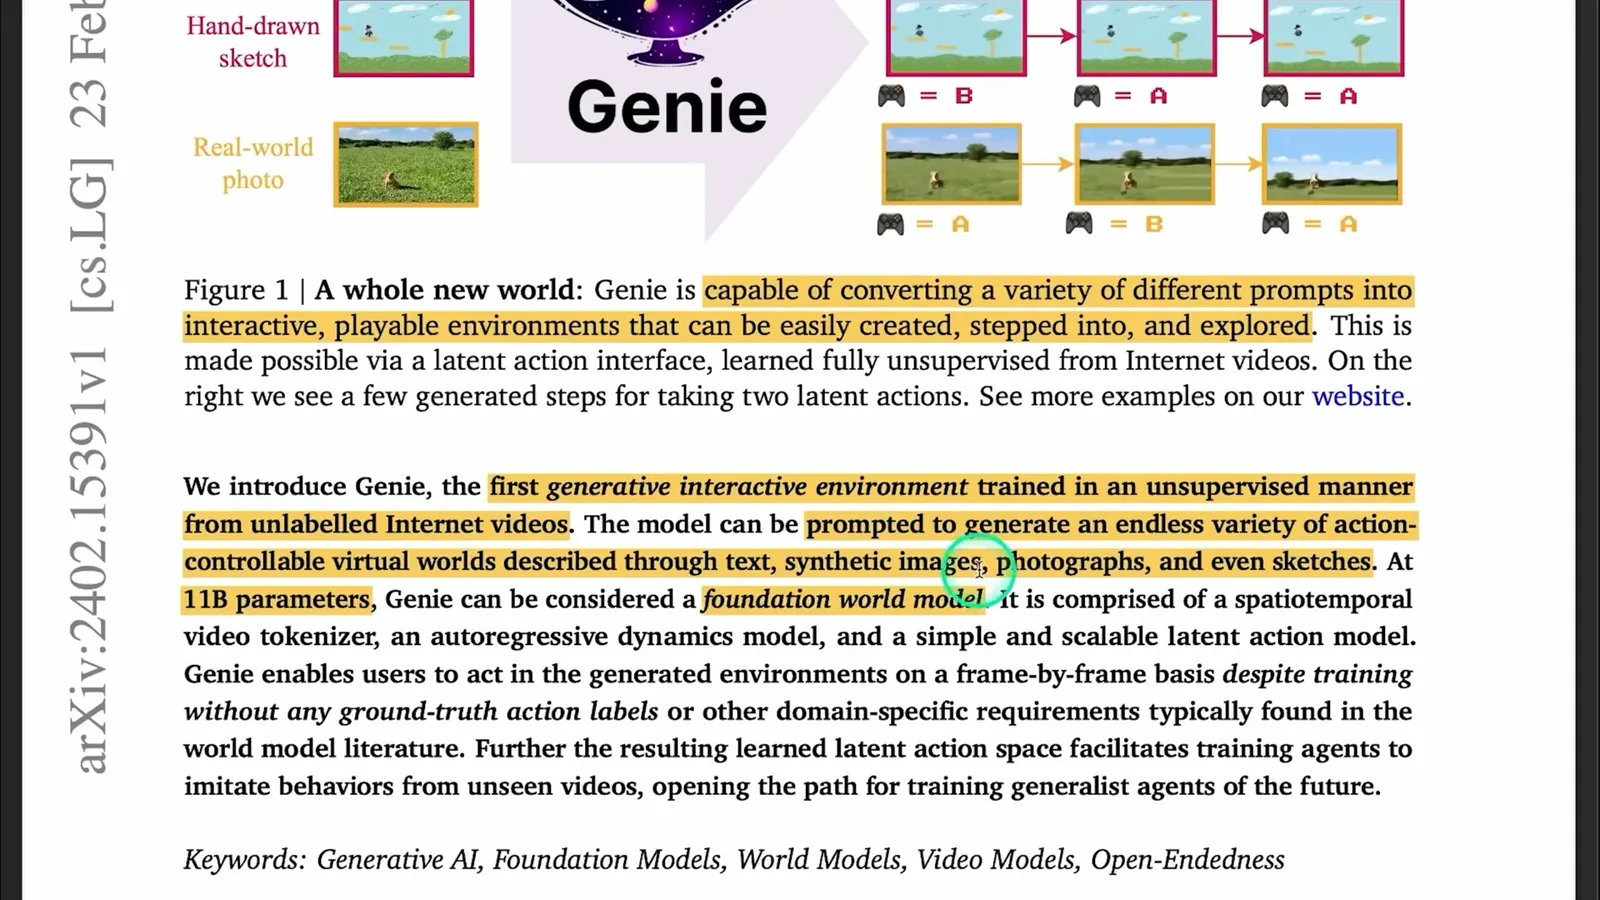
I discuss scaling video models and draw a connection to Sora. Transformer architectures are part of these systems, but shared components alone do not establish that the models work identically or that scaling guarantees a particular outcome.
The authors describe controlling generated frames despite the lack of action or text annotations in training videos. Their results are specific to the tested datasets and demonstrations. Calling the range of possible outputs 'endless' describes generative variety, not a guarantee of coherent, fully interactive worlds for every prompt.
Combining video, sound and production
Berman imagines a future pipeline for generated worlds and discusses a filmmaker’s reaction. These combinations are forecasts, not a demonstrated integrated product.
I imagine combining video generation, Genie-like interaction and simulated agents such as those studied by NVIDIA researchers. That is an envisioned pipeline rather than an integration shown to work in the video. Creating a virtual environment does not establish that our universe is a simulation.
I also show examples in which ElevenLabs added generated sound to Sora clips. Audio and video generation are separate demonstrations in this presentation. They do not establish a single system with synchronized, physically accurate audio, video and interactive controls.
I predict personalized games and movies that could be made quickly for an audience of one, and worry about the effect on large production teams. This is a forecast about future technology and economics, not a result established by the prototypes shown.
Filmmaker Tyler Perry told The Hollywood Reporter that he had put an $800 million studio expansion on hold after seeing Sora demonstrations and expressed concern about jobs. He also described using AI in two productions to avoid lengthy aging makeup. His assessment illustrates an industry's response, not proof that entire films can already be generated reliably.
Long context, agents and simulation
A Gemini and Three.js demonstration precedes a look at a virtual town with AI characters. Berman ends with a philosophical question about simulation, which the demonstrations do not prove.
I then discuss Gemini 1.5 Pro's announced one-million-token context window. A demonstration loaded Three.js code, documentation and examples so the model could answer questions and suggest modifications. A long context can make more material available to a model, but it does not guarantee it will use every part correctly.
In the example, the user asks about an animation and requests code for a slider to adjust its speed. Another image helps identify a demo and suggest terrain changes. These are examples of assistance with an existing software library, not a demonstration that Gemini directly controls any arbitrary generated world.
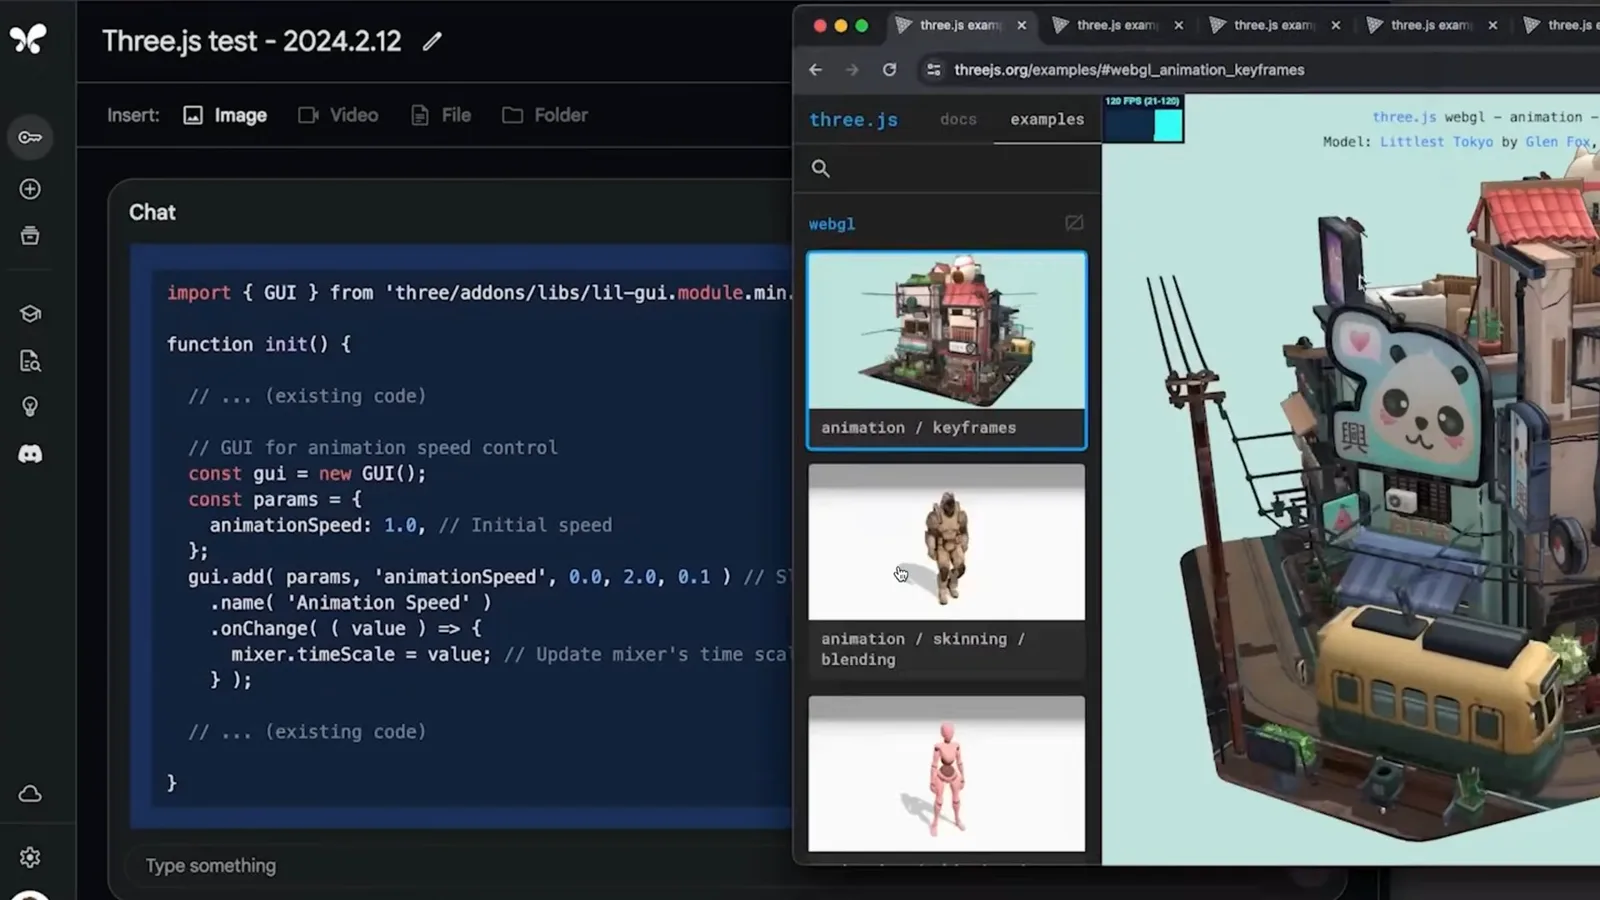
I imagine combining these tools with virtual-reality hardware so people can describe and enter a responsive world. That remains a proposed future experience, with integration, consistency, latency and compute challenges. The demonstrations here do not show a complete system that is indistinguishable from reality.
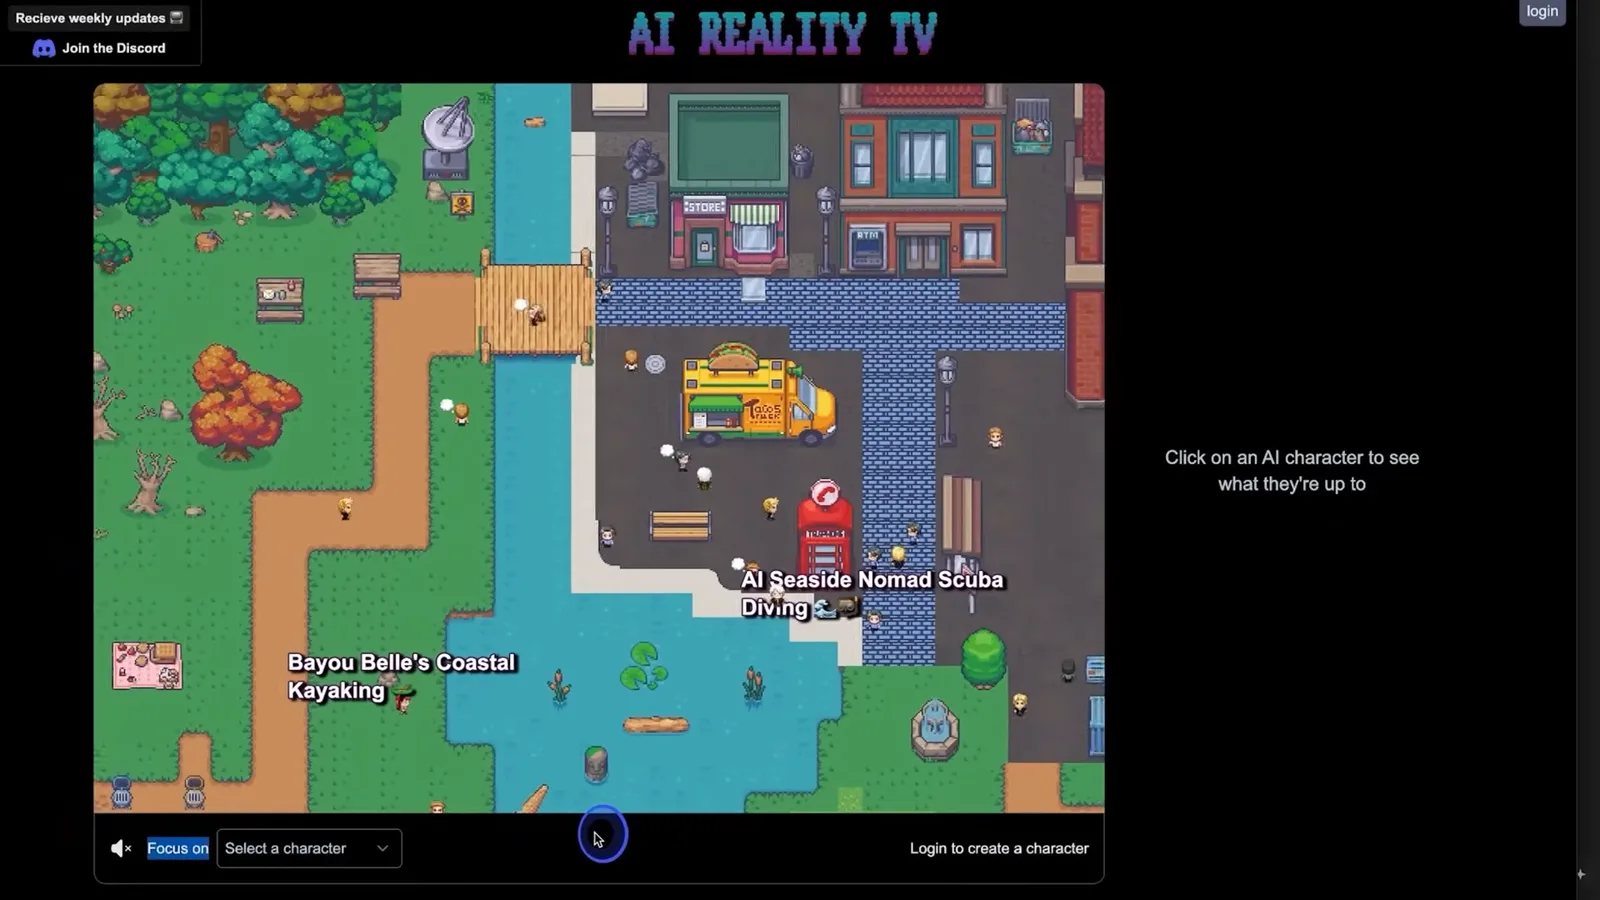
I also describe AI Reality TV, a small virtual town populated by AI-driven characters. I connect it to the earlier Generative Agents research, which placed 25 agents in a sandbox and studied believable individual and social behaviors. Such simulated interactions do not establish that the characters have human experiences or independent lives.
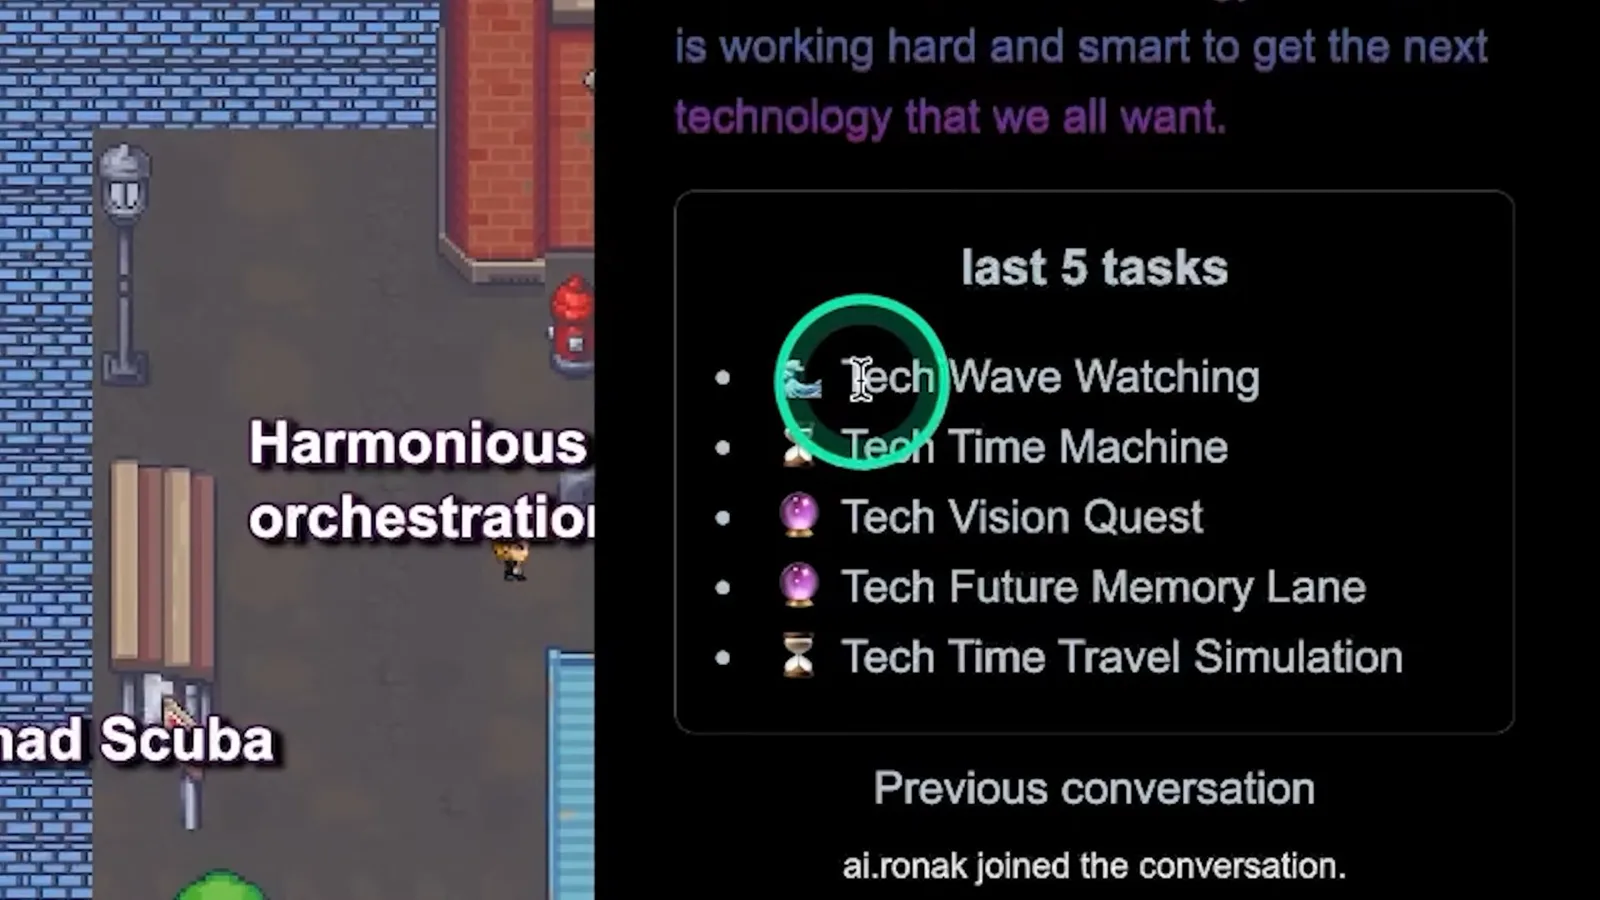
In the displayed project, viewers can inspect characters, recent activities and conversations. I show a character's profile and a conversation between two others. These are the application's displayed outputs; the video does not independently verify uninterrupted operation or the implementation behind each interaction.
I close by combining the ideas of generated scenes, agents and interactive controls, and asking whether a sufficiently convincing virtual world would differ from reality. That is a philosophical question. The demonstrations do not prove the simulation hypothesis or establish that our own world was created by another system.
Mehr aus diesem Kanal
 34:21EN
 Matthew Berman· 27. Okt. 2026Matthew Berman Examines Anthropic’s IPO Filing, AI Growth and GovernanceMatthew Berman, Sam Altman · Forward FutureThe presenter reviews the S-1’s financial metrics, compute strategy and voting structure while questioning the tension between rapid AI development and safety.
 0:36ENMatthew Berman· 25. Okt. 2026Kimi K3.1 and a Rubik’s Cube Solver DemonstrationMatthew Berman · Forward FutureMatthew Berman shows a scrambled virtual cube being solved and gives the Kimi K3.1 test a favorable assessment.
 25:50ENMatthew Berman· 24. Okt. 2026Kimi K3.1 Pro Tested: Strong 3D Demos, Uneven Results and Competitive PricingMatthew Berman · Forward FutureMatthew Berman tests the open-weight model on coding, 3D rendering and visual explanations, then compares benchmark results and prices.
 32:20ENMatthew Berman· 23. Okt. 2026Who Is Local AI For? The Costs, Trade-offs and a Hybrid FutureMatthew Berman · Forward FutureMatthew Berman weighs data control and independence against hardware cost, setup complexity and inference speed.
 1:03:37ENMatthew Berman· 23. Okt. 2026Matthew Berman’s Team Tests Kimi K3.1 on Animation, Games, and ChartsMatthew Berman, Alex, Brian · Forward FutureA live team AMA turns into an informal test of Kimi K3.1, from personal-agent workflows to motion graphics, a browser game, and a benchmark chart.
 0:53ENMatthew Berman· 22. Okt. 2026Sam Altman on AI and the Discovery of New KnowledgeSam Altman · OpenAIAltman expects progress in mathematical discovery to extend to biology, materials and energy.