In 30 Sekunden
In this December 2025 video, Matthew Berman discusses Google’s Gemini 3, OpenAI’s reported internal “code red,” and The Information’s reporting on a model called Garlic. He contrasts researchers’ views on scaling with OpenAI research chief Mark Chen’s confidence in further pretraining, and argues everyday product experience matters more to most users than marginal model improvements.
- 1A contested scaling pictureBerman cites SemiAnalysis on OpenAI’s pretraining and contrasts Ilya Sutskever’s skepticism of simple scaling with Google’s Gemini 3. These are claims and interpretations, not proof of a universal scaling wall.
- 2The reported code redBerman cites reporting that OpenAI would prioritize ChatGPT’s everyday quality, including speed, reliability and personalization.
- 3Mark Chen on pretrainingOpenAI’s research chief says the company has strengthened its pretraining team and sees considerable room for improvement.
- 4Garlic and internal testsThe Information reported that a model code-named Garlic was performing well on OpenAI’s internal coding and reasoning evaluations. Release names and dates discussed by Berman were predictions.
- 5Product experience and retentionBerman argues most users value the overall experience and may not switch products for incremental model improvements.
Das Wichtigste
- Reports in December 2025 said OpenAI was prioritizing ChatGPT improvements and delaying some other initiatives.
- Researchers disagree about how much further pretraining can improve models; Gemini 3’s performance does not settle that debate.
- OpenAI research chief Mark Chen said the company saw substantial room for pretraining and was building stronger models.
- The Information reported on an unreleased model called Garlic and described internal evaluations, which were not independent public benchmarks.
- Berman argues that personalization, speed and reliability are especially important for ordinary users.
Den bearbeiteten Text nach Kapiteln lesen
Google, OpenAI and the pretraining debate
Berman discusses Google’s infrastructure and a report on OpenAI’s pretraining. He contrasts differing views on the value of simply scaling models.
Google has attracted enormous attention for Gemini 3 and its TPU infrastructure. In response, reports say Sam Altman declared a “code red” at OpenAI, while The Information reports a new model in development called Garlic. In December 2025, I see Google as unusually well positioned: it has frontier models, infrastructure, custom chips, substantial revenue, researchers and data.
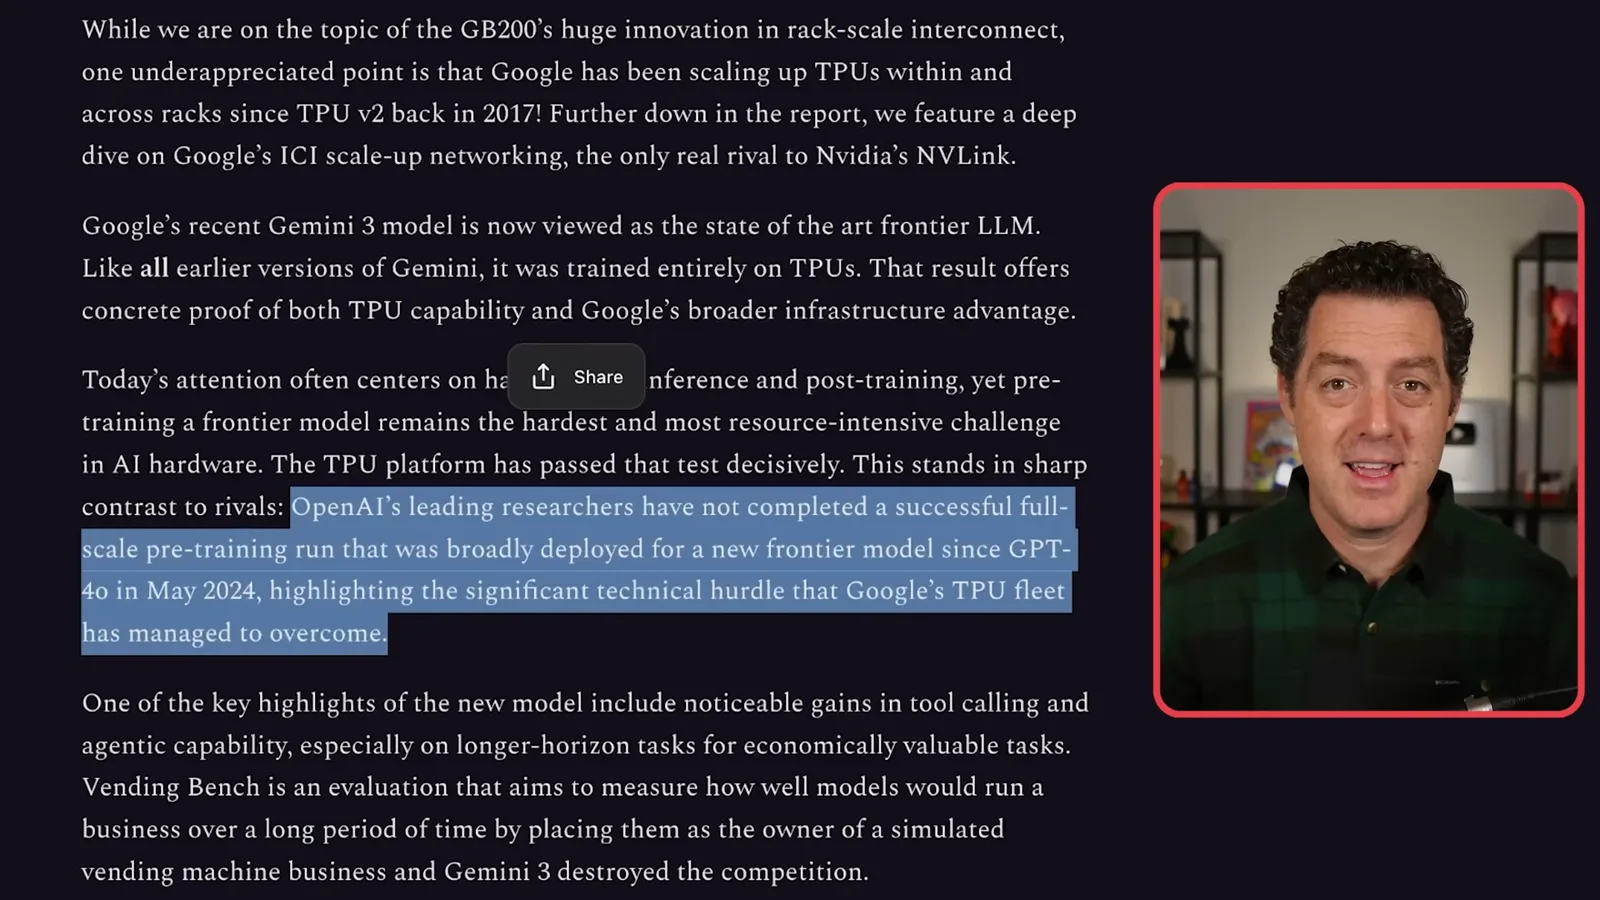
SemiAnalysis argues that OpenAI’s leading researchers had not completed a successful full-scale pretraining run broadly deployed as a new frontier model since GPT-4o in May 2024. That is the publication’s characterization of a complex technical history, not independently established proof that OpenAI stopped improving models. It raises the question of whether simply scaling pretraining has become harder.
OpenAI co-founder Ilya Sutskever, now at Safe Superintelligence, discussed this question with Dwarkesh Patel. In the clip he describes 2012–2020 as an age of research and 2020–2025 as an age of scaling, and questions whether 100 times more scale would transform results. My interpretation is that we need new research ideas and algorithms, not only more of the same computation.
Andrej Karpathy has also raised questions about scaling, and Yann LeCun has long argued that current language models have limitations. The debate even produced a meme contrasting reactions to similar claims from Sutskever and LeCun. These researchers do not necessarily hold identical positions, and the meme is not evidence that either has settled the issue.
Then Google released Gemini 3, which I see as a strong counterexample to the claim that scaling is finished. Perhaps Google’s methods or architecture helped it get past a constraint others encountered; many people point to its TPUs, custom chips developed over several years. The precise reasons for a model’s performance cannot be established from this comparison alone.
The reported ChatGPT code red
News reports describe a shift toward ChatGPT quality. Berman argues speed, personalization and reliability matter to everyday users.
According to The Wall Street Journal, Altman told OpenAI employees to focus urgently on ChatGPT’s everyday experience, including personalization, speed, reliability and the range of questions it can answer. Other reporting said some initiatives would be delayed. I find the emphasis significant: product quality is about more than the model’s raw benchmark performance.
My view is that existing models are already capable enough for the vast majority of ordinary use cases, although I still welcome improvements in intelligence. For most people, the scaffolding around a model and the day-to-day experience matter enormously. My “99%” estimate is a judgment, not a measured figure.
Google has a strong model and growing usage; I cite Gemini’s rise from 450 million to 650 million active users and suggest OpenAI is approaching a billion. Those figures describe the period of the video and should not be assumed to use identical measures. Google also has multiple revenue streams and cash it can draw on while competing with OpenAI and Anthropic.
OpenAI’s pretraining response
A clip of Mark Chen describes renewed pretraining efforts and confidence in stronger models. Berman connects the remarks to reporting about an unreleased model.
In a podcast clip, OpenAI chief research officer Mark Chen says the company has spent the previous half-year strengthening pretraining, including building a strong team and focusing on its important components. He says those efforts have produced artifacts that give him confidence OpenAI can compete with Gemini 3. That is an executive’s assessment, not an independently verified comparison.
Chen also says OpenAI sees considerable room left in pretraining despite claims that scaling is dead, and that its efforts have produced much stronger models. I take this as a sign that OpenAI is renewing attention to pretraining after a period in which reinforcement learning received enormous focus. Whether the reported gains carry through to a released product remains to be seen.
Garlic and product competition
The Information reports on Garlic and separate internal model evaluations. Berman discusses rumored launches, reported project delays and the competitive importance of user experience.
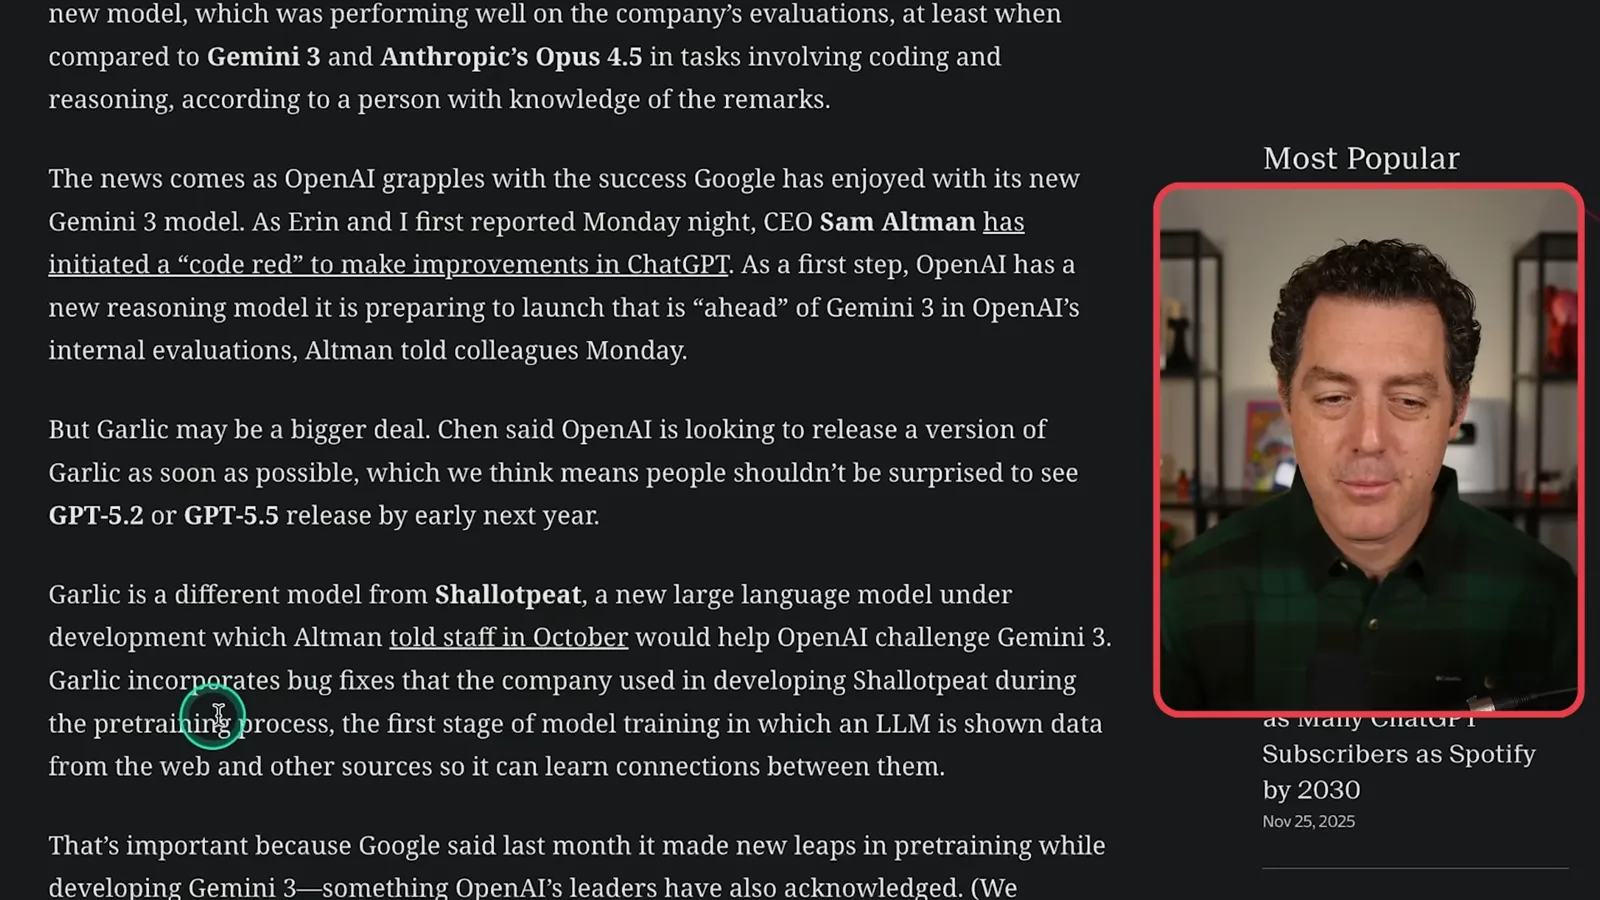
The Information reports that OpenAI is developing a model code-named Garlic to counter Google’s progress. According to its source, Chen told colleagues that Garlic was performing well against Gemini 3 and Claude Opus 4.5 on company evaluations involving coding and reasoning. These are reported internal results, and the article does not establish independent test conditions or final released performance.
The Information also reports that Altman described a separate reasoning model being prepared for launch as ahead of Gemini 3 in OpenAI’s internal evaluations. I wonder whether a year-end release might be called GPT-5.2 or GPT-5.5, but that is speculation. The outlet says Garlic is distinct from another development model called Shallotpeat and incorporates fixes used during its pretraining.
Reports also say OpenAI is delaying work on projects including advertising and shopping-related initiatives to focus on ChatGPT. I welcome a focus on the experience. Some people I know have switched heavily to Gemini, but they and I are not typical users; many people care more about the overall experience than a small increase in a benchmark.
Google can use its distribution through Search to grow Gemini, but ChatGPT was many people’s first exposure to this kind of AI. I think that familiarity and a strong product experience make most users less likely to switch for every incremental improvement, even as power users move to the current leader. OpenAI faces stronger competition, and consumers can benefit from that competition.
Mehr aus diesem Kanal
 34:21EN
 Matthew Berman· 27. Okt. 2026Matthew Berman Examines Anthropic’s IPO Filing, AI Growth and GovernanceMatthew Berman, Sam Altman · Forward FutureThe presenter reviews the S-1’s financial metrics, compute strategy and voting structure while questioning the tension between rapid AI development and safety.
 0:26ENMatthew Berman· 25. Okt. 2026Sam Altman on Human Values and Problem-Solving in an AI WorldSam Altman · OpenAIIn a short interview excerpt, Altman considers the enjoyment of solving hard problems and the human role in interpreting results.
 0:36ENMatthew Berman· 25. Okt. 2026Kimi K3.1 and a Rubik’s Cube Solver DemonstrationMatthew Berman · Forward FutureMatthew Berman shows a scrambled virtual cube being solved and gives the Kimi K3.1 test a favorable assessment.
 0:21ENMatthew Berman· 24. Okt. 2026An AI-Generated Kimi Benchmark Chart Used Invented ScoresMatthew Berman · Forward FutureMatthew Berman asks for a graph of Kimi K3.1 Pro benchmarks, then discovers that the displayed figures are illustrative placeholders.
 25:50ENMatthew Berman· 24. Okt. 2026Kimi K3.1 Pro Tested: Strong 3D Demos, Uneven Results and Competitive PricingMatthew Berman · Forward FutureMatthew Berman tests the open-weight model on coding, 3D rendering and visual explanations, then compares benchmark results and prices.
 32:20ENMatthew Berman· 23. Okt. 2026Who Is Local AI For? The Costs, Trade-offs and a Hybrid FutureMatthew Berman · Forward FutureMatthew Berman weighs data control and independence against hardware cost, setup complexity and inference speed.