In 30 Sekunden
Theo Browne reviews Gemini 4 Argon using design examples, a small 3D game and his own codebase audits. He praises a perfect SkateBench result and some front-end output, but reports many incorrect claims and an unsuccessful SQLite PR in his setup. His benchmarks, cost observations and conclusions are tied to the tests and integration shown in the video.
- 1A perfect narrow scoreArgon achieved a perfect result on completed SkateBench questions in Theo’s run. He cautions that naming skateboard tricks is not representative of every task.
- 2Game mechanics exposed gapsThe first game had a broken feeding loop; a revised version improved it but retained a power-up that expired before it could be useful.
- 3Codebase audit resultsTheo’s TS Rust audit marked 24 of 36 checked Argon claims wrong. This result reflects his particular codebase, integration and evaluation process.
- 4An unsuccessful SQLite PRTheo reports that the generated change failed checks and left the underlying problem unresolved; he closed the PR and used another review.
Das Wichtigste
- Per-token rates alone do not determine task cost; token use and cache hits also matter.
- A perfect score on a narrow benchmark does not prove general coding reliability.
- Theo liked some front-end results but found gameplay and code-review problems in his tests.
- Code-audit findings and generated changes need independent verification.
- Multimodal and other workloads were not comprehensively evaluated in the video.
Den bearbeiteten Text nach Kapiteln lesen
Release, benchmarks and cost
Theo introduces Argon and discusses published prices, cache behavior and external rankings. His cost observations are specific to his setup.
Gemini 4 Argon has arrived after what I count as an eight-month gap since Gemini 3.1 Pro. I had early access and tested its pricing, front-end design, a 3D game and code-review work. There are strengths, but my experience with substantial code tasks has been disappointing.
Friends at Google helped me get early access. Google pays me as a YouTube creator, but not for this Gemini coverage. My assessment is based on the tests and examples I show; others may have different workloads and results.
Google presents Argon as a model for complex, multi-step work across coding and other domains. I look at external rankings but notice a questionable price assigned to another model, which reduces my confidence in that comparison. A benchmark's cost assumptions matter as well as its scores.
On the Artificial Analysis intelligence index, the result I show puts Argon above some models and below Opus 5.5 at certain settings. Its cost per completed benchmark task is not as attractive as its per-token price might suggest. That index is a general indicator, not a complete measure of coding capability.
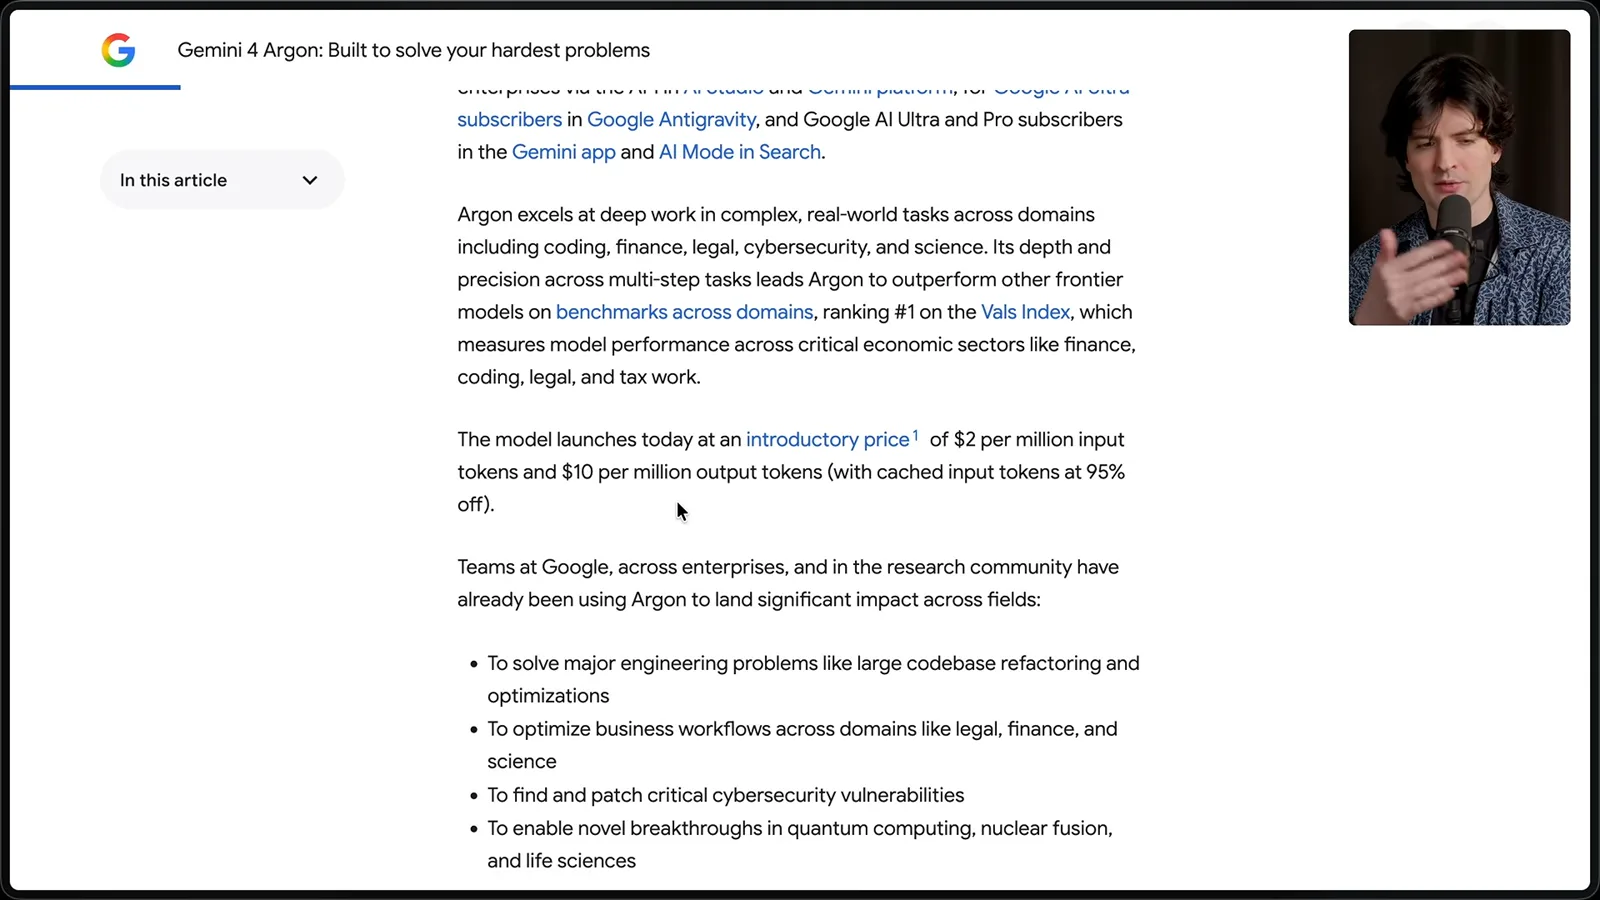
Google's launch material lists an introductory price of $2 per million input tokens and $10 per million output tokens, with a cache-read discount. In my runs, token usage and cache-hit rates made the practical cost less appealing. I observed around 70–80% cache hits, compared with over 99% for some alternatives in my setup.
I cannot tell whether the cache result comes from the model, Antigravity's reporting, or our T3 Code integration. Those are possibilities, not a diagnosis. I also note that Google said the introductory price would rise to $4 input and $20 output per million tokens on December 1; these figures describe the announcement at the time of the video.
Google cites internal examples of increased agentic submissions, fewer rollbacks and a Chrome refactor. Those are Google's own measurements and examples. I want to see what happens in my own tasks, where design, accuracy and the time needed to reach a useful outcome matter.
SkateBench and multimodal work
Argon performs exceptionally on Theo’s narrow skateboarding evaluation. He notes that he did not independently benchmark its visual capabilities.
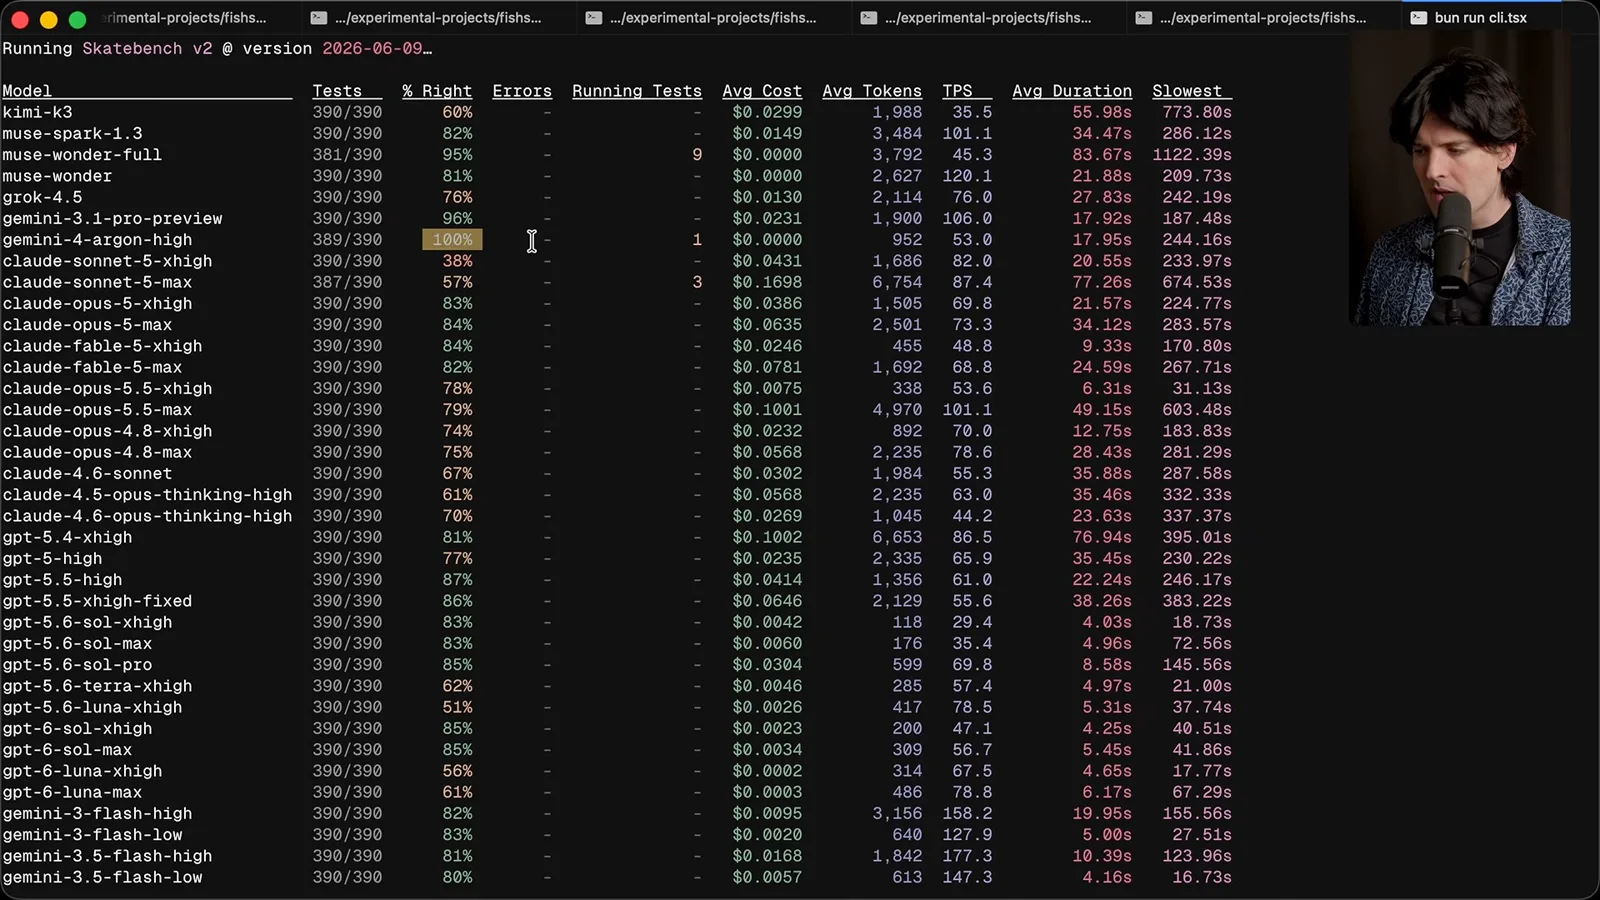
One surprise was SkateBench, my private benchmark for naming skateboard tricks. Argon achieved a perfect score on the completed questions in the run I show, while Opus 5.5 Max scored 79%. The API produced errors during early testing, so I had to adjust the benchmark to cope with instability.
The model was quick and economical in that particular task. But a perfect score on a narrow evaluation does not establish that a model is reliable for every kind of work. A claim of 100% success is meaningful only when you understand the tasks and how they relate to your own needs.
Google highlights multimodal work with documents, video and audio. Historically I have found Gemini models strong at visual tasks, such as labeling components in a photograph. I did not benchmark those capabilities for this video, which focused on code, so I would test them separately for a relevant use case.
The announced introductory price is temporary, and I dislike a pricing structure that raises the rate after people start building on it. Whatever the listed rates, a realistic cost comparison should include output volume, cache behavior and the number of attempts required to finish a task.
Front-end and provider-specific tools
Theo likes some generated design work and discusses iteration, design skills and YouTube integrations.
For front-end design, I have used earlier Gemini models in Lawn, my video-review product. In the examples shown here, Argon produces a homepage I find attractive and an interactive section that works. That is a positive result, even if I would reduce the amount of text.
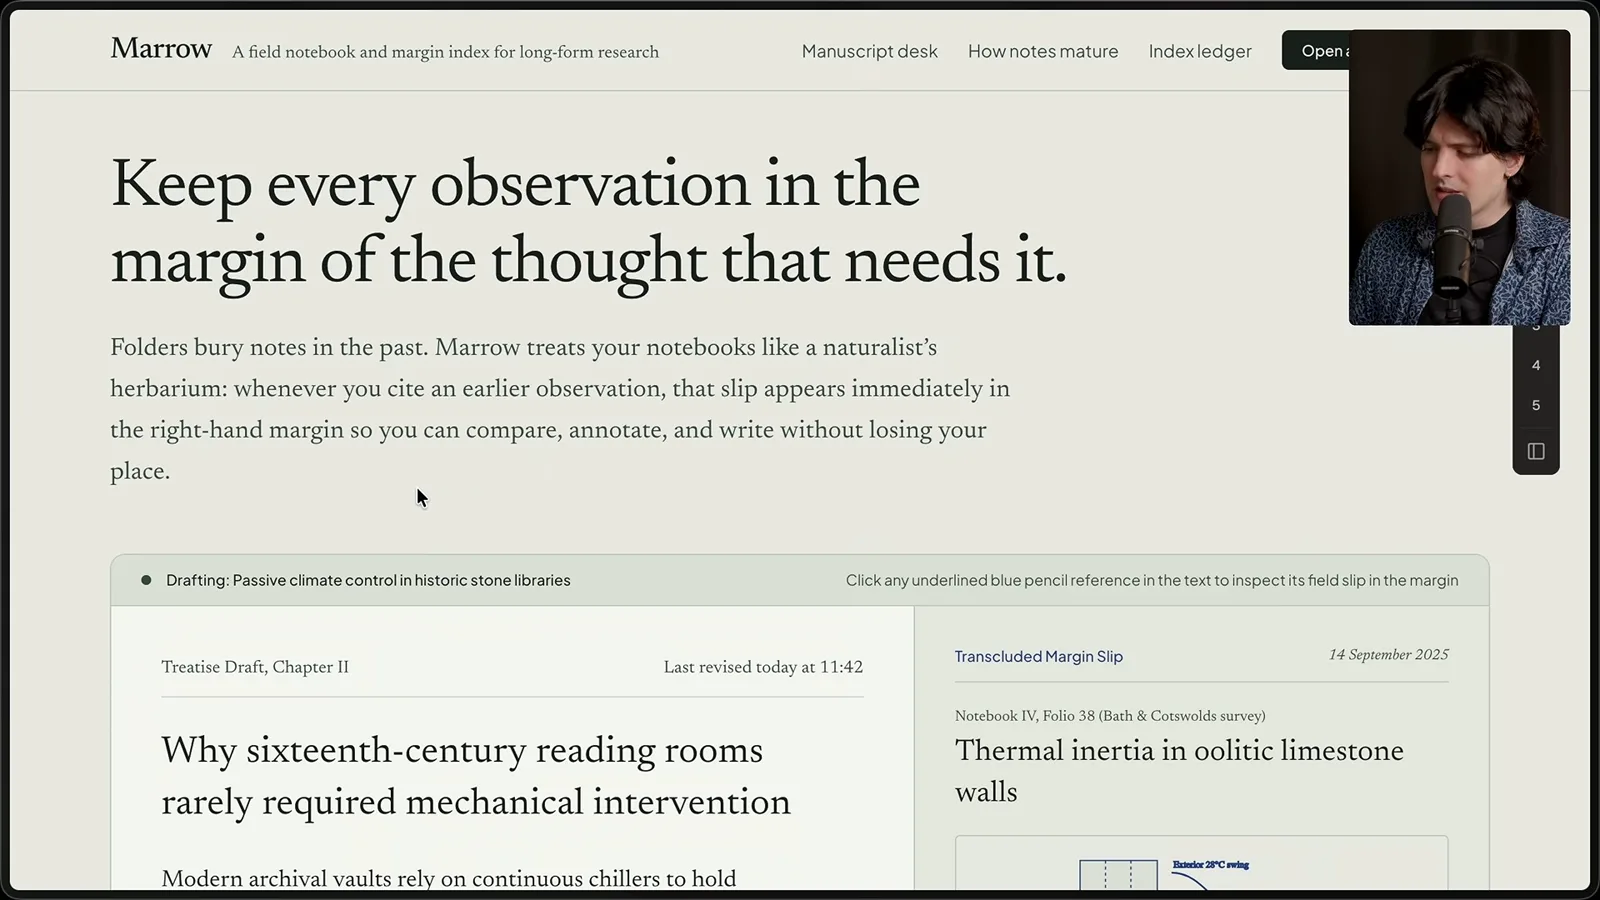
The examples use Anthropic's design skill. In my comparison, disabling it produced more repetitive navigation and layout choices; another taste skill did not work as well for me. These are subjective design judgments and depend on the prompt and tools, not a universal ranking.
I still prefer Fable 5.1 for some marketing-page designs, and for real UX I value fast iteration. A model that generates tokens quickly does not necessarily solve a problem quickly. Being able to go back and forth with it matters more to me than a single impressive first image.
Different providers also give their models access to different tools and data. Gemini has useful YouTube-related capabilities for my work as a creator, including getting information and transcripts. I have had less success with some other Google-service integrations, so I would evaluate the specific task rather than assume every integration is equally good.
I hear that Gemini may have particular strengths in multilingual and localization work, but I have not established that in my own tests. SkateBench shows that it can have an unusual strength that other evaluations miss. It is worth looking for those capabilities without assuming they transfer to every domain.
The 3D game test
The generated game has a working structure but flawed mechanics. Follow-up instructions improve the result, with some design problems remaining.
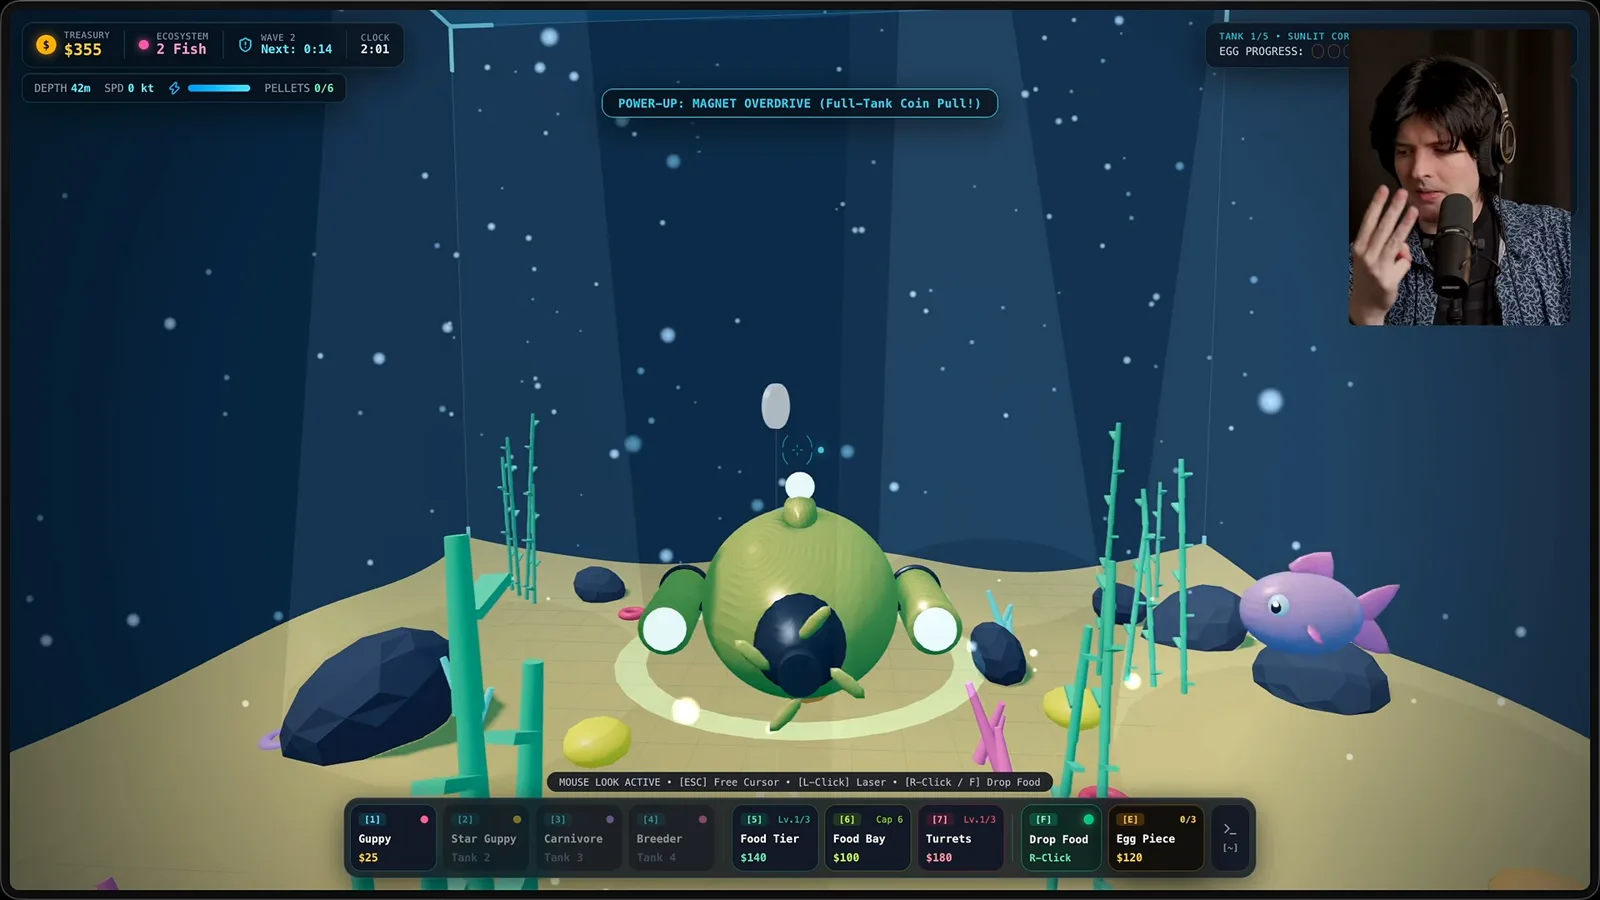
My Fish Slap test asks models to build the same 3D game with the same setup. Argon's version had a complete five-tank loop and some reasonable fish animation, but I found the visuals and submarine model underwhelming. More importantly, the first version had gameplay problems.
Food could fall to the bottom without expiring, while fish could not reach it. The fish would gather around it and eventually die, and the food limit prevented me from simply feeding them more. I asked the model to fix the feeding and water problems and improve the graphics; the next version looked better and fixed much of the feeding behavior.
A remaining example was a damage power-up that expired before the next wave of enemies arrived. The model implemented a plausible feature without reconciling it with the game timing. I call that a failure of system-level judgment, not a hallucination: the power-up existed, but it was not useful in the game as designed.
Hallucination and code audits
Theo contrasts a published hallucination benchmark with his own audits of several codebases. The reported results depend on his test design.
On an Artificial Analysis evaluation, the chart I show reports a low hallucination rate for Argon. That evaluation also accounts for correct answers and refusals, so a low incorrect-answer rate is not the same as a high overall score. My own code work produced many statements I judged wrong, illustrating that benchmark results can vary with the task.
I asked several models to audit TS Rust, my TypeScript compiler rewrite, and validated their claims before using a panel of models to score the reports. In this run, GPT-6.1 Sol's 38 checked claims were all correct and its average score was 8.84. Opus 5.5 scored 8.78 with one wrong claim, taking longer and costing more in the displayed comparison.
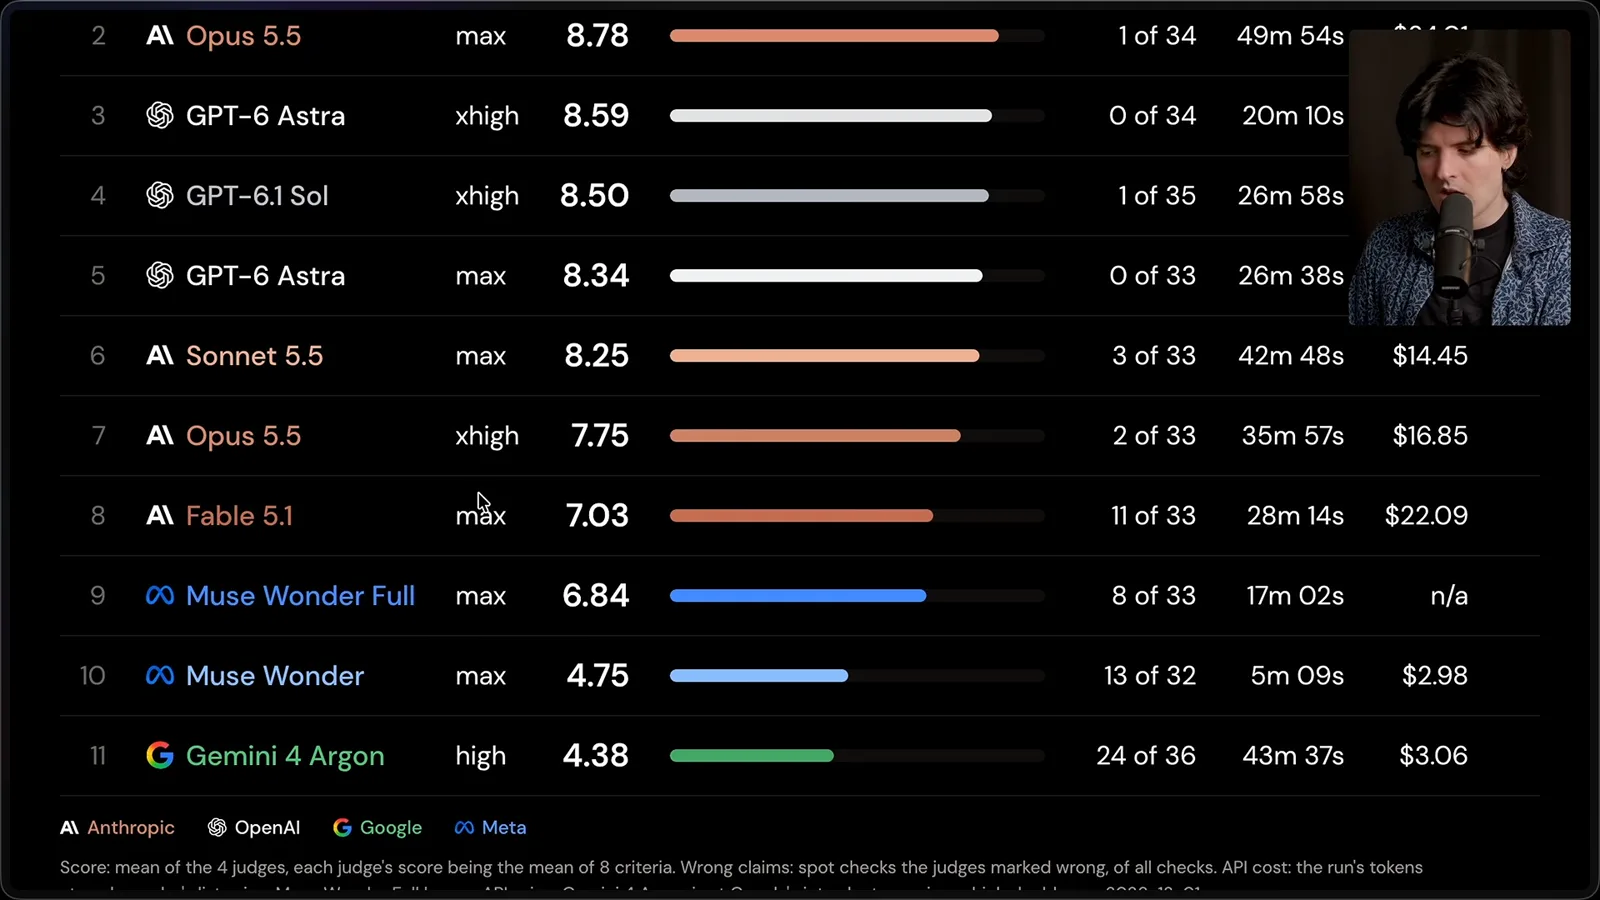
Argon scored 4.38 in that audit, took about 43 minutes and cost about $3 under the test's pricing assumptions. The displayed result marks 24 of 36 checked claims wrong. This is a result from my particular codebase, harness and evaluation method; it is not a measured error rate for all Gemini usage.
In a separate audit of a T3 Code bulk-update problem, Opus scored highest in my comparison but had some wrong claims. Sol missed some serious findings yet made no incorrect claims in that run and was faster and cheaper. These examples are why I prefer comparing accuracy, usefulness, time and cost together.
The Lakebed audit was worse for Argon in my scoring: 2.25 out of 10, with 56 of 78 checked findings marked wrong. In a T3 Code architecture audit, I report 31 true, 14 partly true and 47 false findings. A reviewer could be actively harmful if it confidently sends a team after nonexistent problems, so I would independently check its findings.
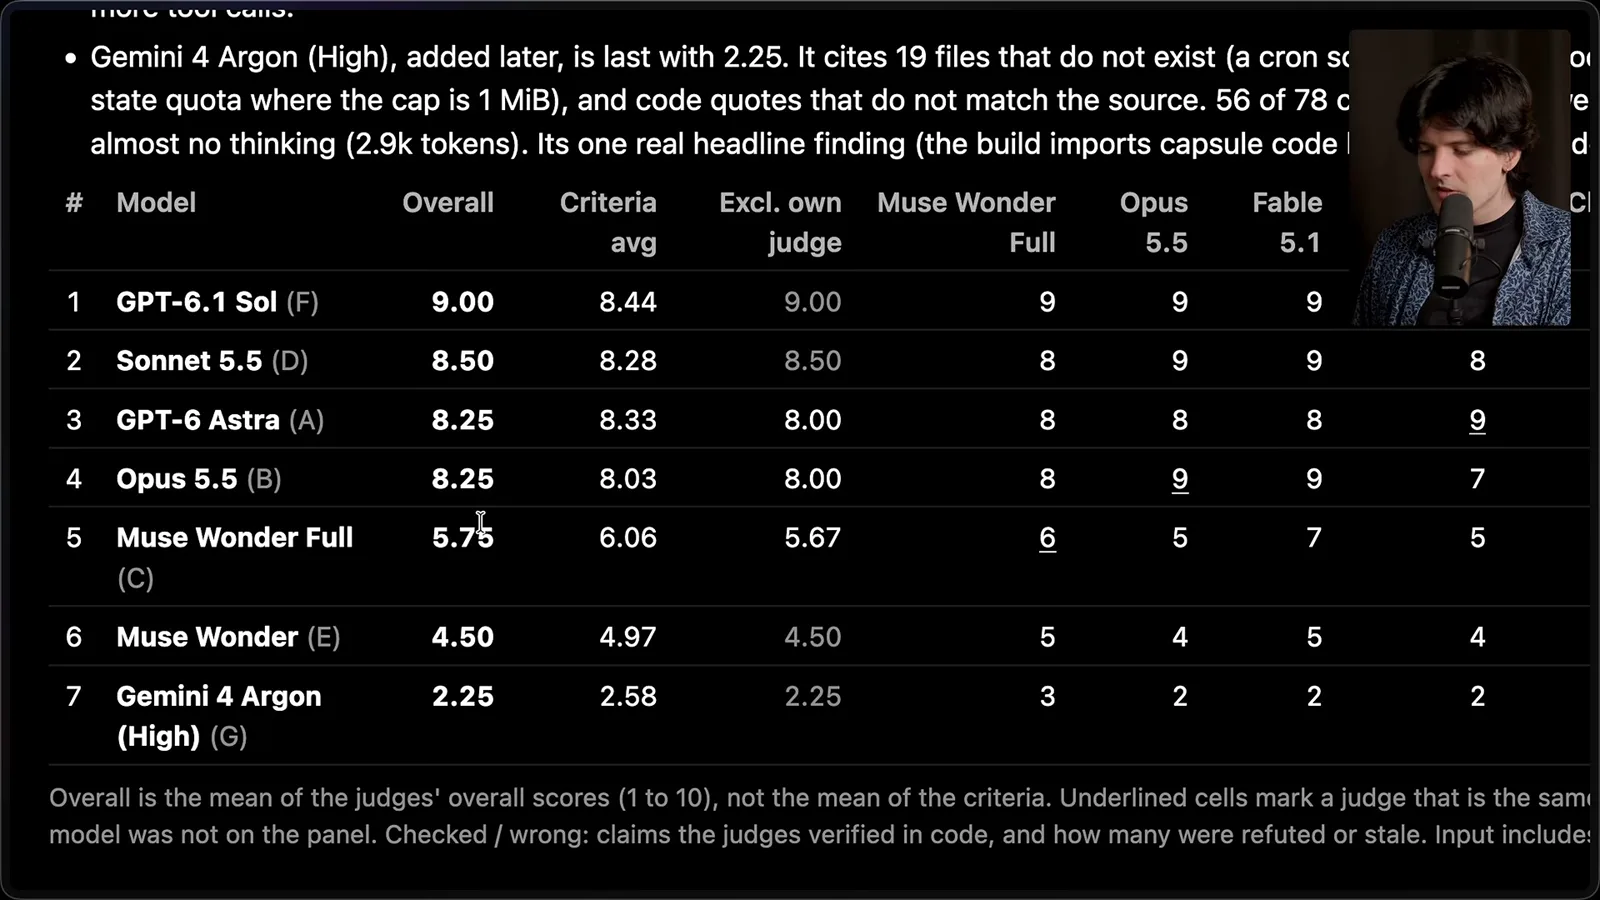
I also found the responses verbose and hard to read. My conclusion is harsh because these results matched repeated frustration in my own work, but the tests are still mine: the projects, prompts, integration, judging process and sample of claims all affect the outcome.
SQLite task and integration experience
He describes a failed PR, a second model’s review and problems in the surrounding tools. He closes with his own limited recommendation.
For a concrete coding task, I asked the model to investigate SQLite connection instability. It identified a read-pool and single-writer direction, then I asked it to implement the first priority. The resulting PR took roughly half an hour, changed more than a thousand lines and failed checks. I closed it rather than merge it.
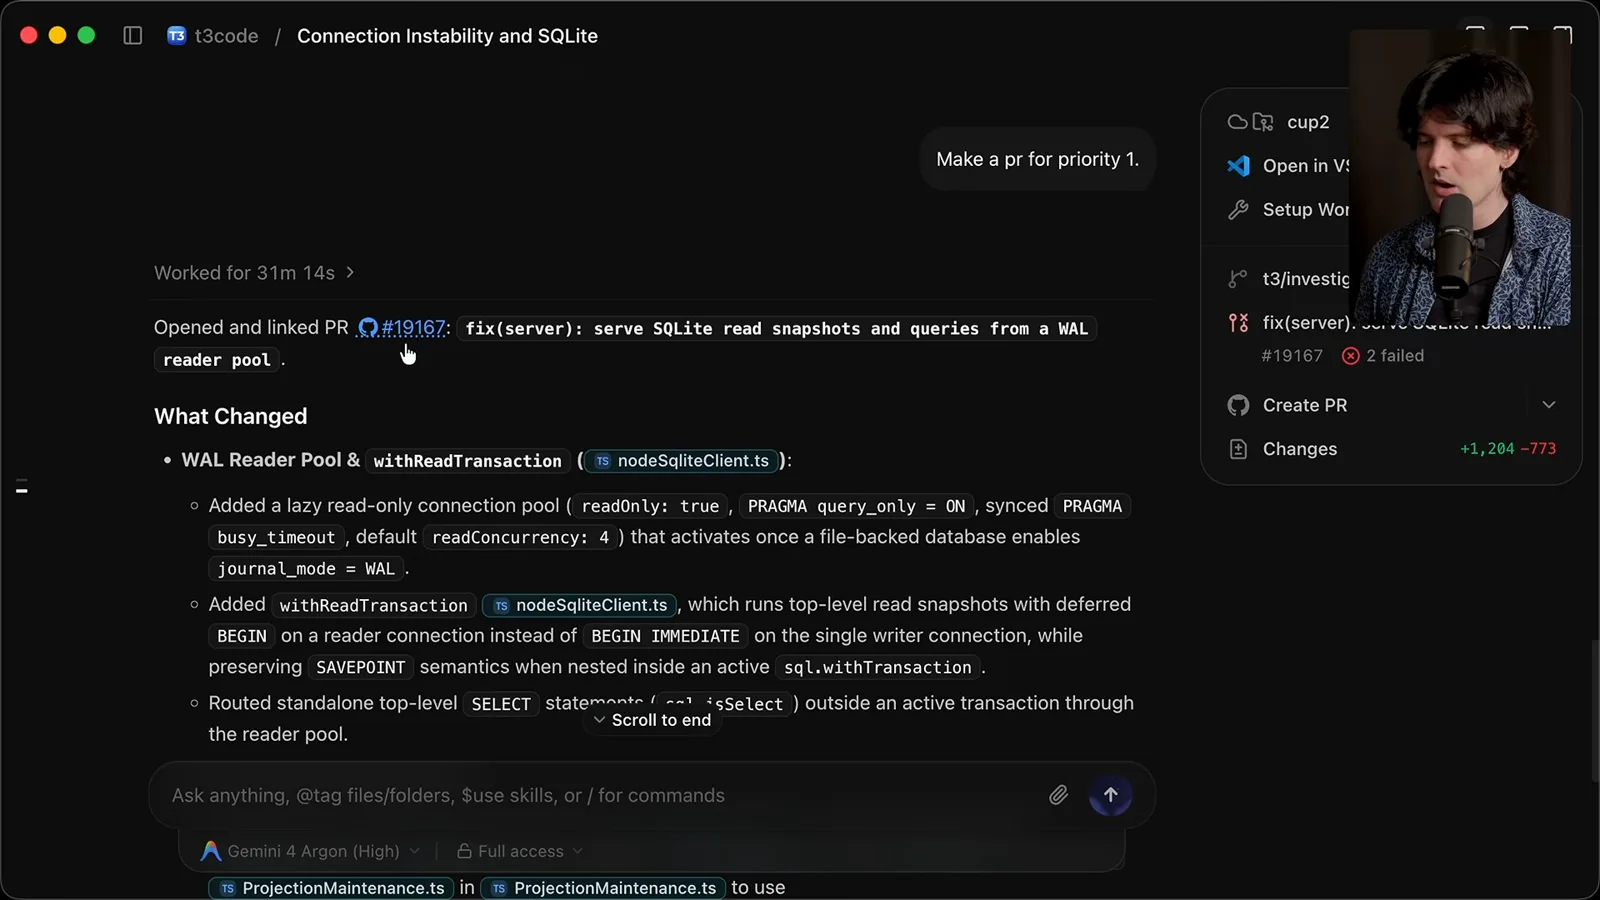
I asked Opus to review the thread and PR. Its assessment was that the initial diagnosis had identified a real mechanism without enough evidence, while the implementation still left blocking work on the main thread. It also noted existing PRs that addressed the issue. In my account, a much smaller subsequent change was merged.
I encountered a gateway failure after another long run and had to restart without the prior thread history. I also found the Antigravity integration awkward, including how model and effort options were exposed. I cannot infer from one failed run which component caused every issue, but the reliability of the surrounding tools affects the user experience.
I worry about account access because my Gemini account is connected to other Google services I depend on. I say Google has promised more limited restrictions, but I have seen reports that make me cautious. That is my assessment of the risk, not a finding that using this particular integration will cause an account ban.
After these tests, I do not plan to use Argon for substantial code work in my own projects. I would still consider Gemini for YouTube data and possibly initial front-end designs. I want feedback and examples from people who get better results; the model may have useful strengths that my tests did not cover.
Mehr aus diesem Kanal
 36:07EN
 Theo - t3․gg· 27. Okt. 2026Theo on Token Costs, Coding Agents, and the Price of AI CapabilityTheo Browne · Ping LabsA viral estimate of Lauren's AI spending prompts a closer look at cache pricing, benchmarks, and the changing work of coding agents.
 30:37ENTheo - t3․gg· 26. Okt. 2026Theo’s Three Skills for Reviewing and Shipping with Coding AgentsTheo Browne · Ping LabsHow sol-loop, full-send and full-stop encode review, verification and different levels of merge authority.
 0:43ENTheo - t3․gg· 23. Okt. 2026Theo Distinguishes Security Vulnerabilities from Active AttacksTheo Browne · Ping LabsA short explanation of why disclosed software flaws and reported attacks are different kinds of security news.
 29:22ENTheo - t3․gg· 22. Okt. 2026Theo on Security Vulnerabilities, Stolen API Keys and AITheo Browne · Ping LabsA look at the gap between vulnerability disclosure and patching, and a speculative account of why stolen inference keys may be valuable.
 31:13ENTheo - t3․gg· 20. Okt. 2026Theo on Why Smarter Models Help More Than DevelopersTheo Browne · Ping LabsFrom game modifications to compiler experiments, Theo revisits his assumptions about who benefits from more capable AI.
 31:47ENTheo - t3․gg· 18. Okt. 2026Theo on Asking Agents for Outcomes and Building the Tools They NeedTheo Browne · Ping LabsA tool-call report, a troubleshooting playbook and connected data show how prompting can reshape product engineering.