In 30 Sekunden
Matthew Berman reviews Microsoft Research’s Visualization-of-Thought prompting, which asks a language model to represent intermediate spatial states. He then examines a separate open-source Windows assistant and its interface-control demonstrations. The paper reports improvements on specific grid-world benchmarks while documenting substantial remaining errors.
- 1A sketchpad for each stepVoT interleaves intermediate reasoning and text-form visualizations to track spatial state.
- 2Three bounded testsThe research covers natural-language navigation, visual navigation and tiling in controlled grid-world settings.
- 3Improvement with limitsRoute-planning success rose from 10.28% without visualization to 14.72% with VoT in the reported comparison.
- 4Windows automation demonstrationThe independent PyWinAssistant project shows actions on desktop interfaces; it is not a physical robotics test.
Das Wichtigste
- VoT asks a model to visualize intermediate states alongside its reasoning steps.
- The paper tests three spatial tasks using structured 2D grid worlds, not physical robot control.
- GPT-4 with VoT led the reported comparisons, but route-planning success was 14.72%.
- PyWinAssistant is a separate open-source Windows automation project that references the research.
- Desktop demonstrations illustrate selected interactions, not universal or guaranteed autonomous operation.
Den bearbeiteten Text nach Kapiteln lesen
Why spatial reasoning matters
Berman introduces a Microsoft Research paper and an independent Windows assistant. He illustrates spatial reasoning with a thought experiment.
An open-source Windows assistant offers a glimpse of controlling applications through natural language, while a Microsoft Research paper explores a related question: can a language model reason more effectively about space? I'll walk through the paper and then look at examples of the assistant acting on a desktop. The assistant, PyWinAssistant, is a separate project, not a Microsoft release as I initially say.
Spatial reasoning means understanding relationships between objects and their movements in two or three dimensions. Yann LeCun has argued that limitations in this area matter for progress toward more general AI. The paper tests whether a particular prompting method can improve performance on spatial problems; its results should be understood within the tasks studied.
Imagine starting at the North Pole, walking 50 yards in one direction, turning left and continuing indefinitely. Could you cross the starting point again? The point of the example is the mental work of tracking a position and direction through space, something people can often do without describing every movement in words.
The researchers call their method Visualization-of-Thought, or VoT. They draw an analogy to a human mind's eye: a person combines information into a mental representation and uses it to guide a decision. For a language model, the practical method is to generate a text-based representation of the state as it reasons, rather than relying on a bare final answer. The analogy does not establish that the model has humanlike mental imagery.
Visualization-of-Thought
VoT interleaves reasoning with representations of intermediate state. The paper evaluates navigation and tiling in two-dimensional grids.
Compare ordinary prompting, which goes from input to output, with chain-of-thought prompting, which asks for intermediate reasoning. VoT adds a visualization after each reasoning step, interleaving the textual trace with a representation of the changing state. This gives subsequent steps an explicit spatial sketchpad to refer back to.
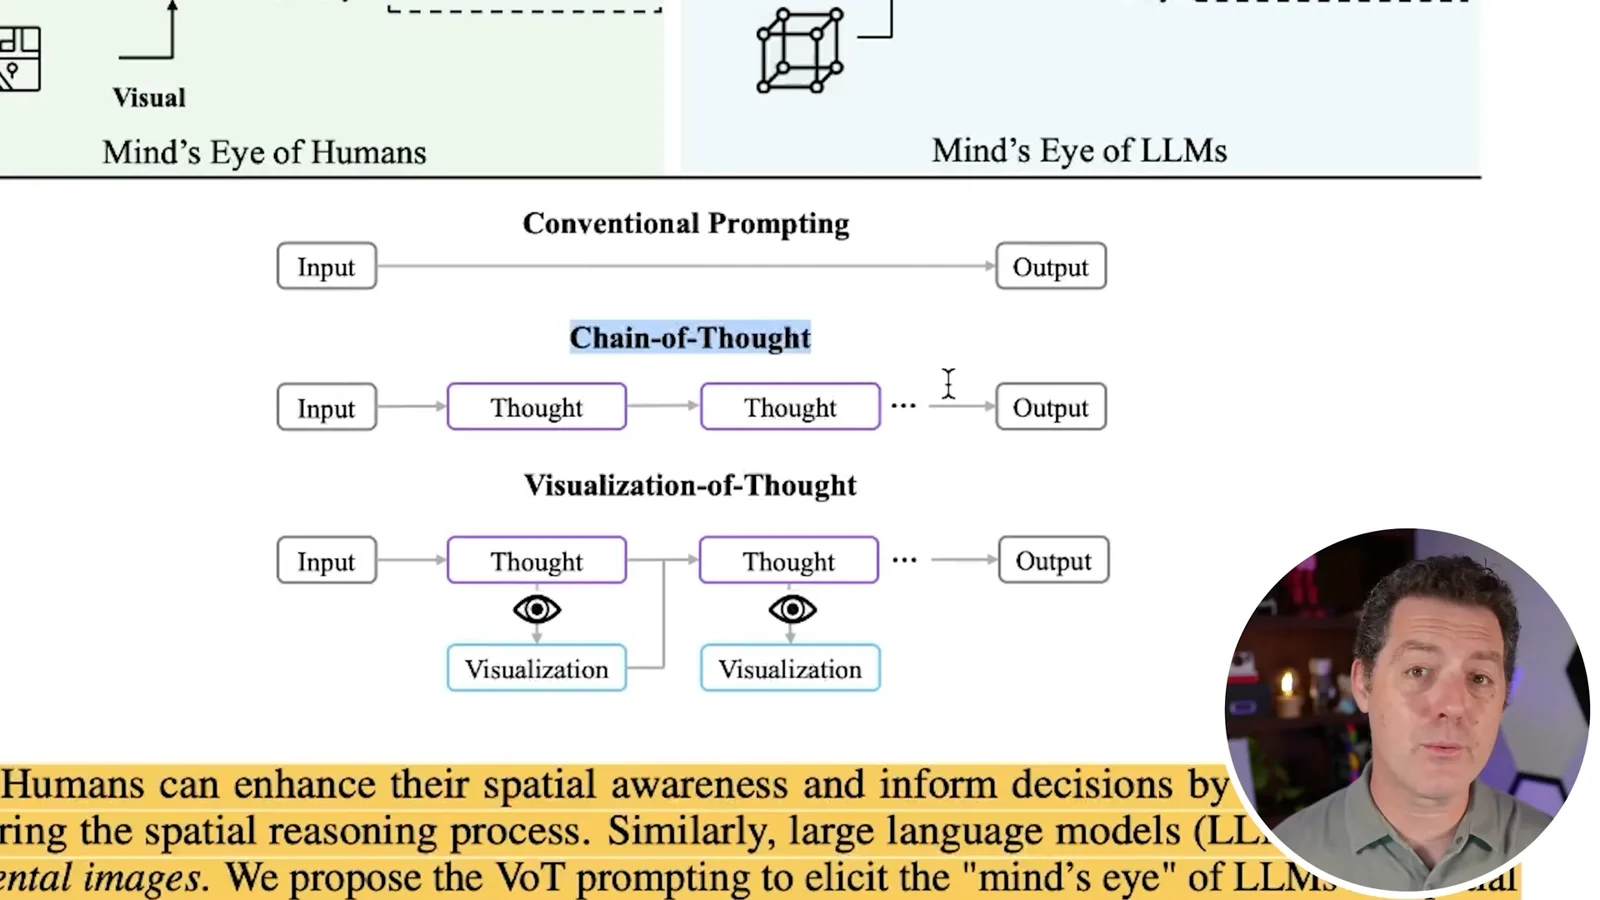
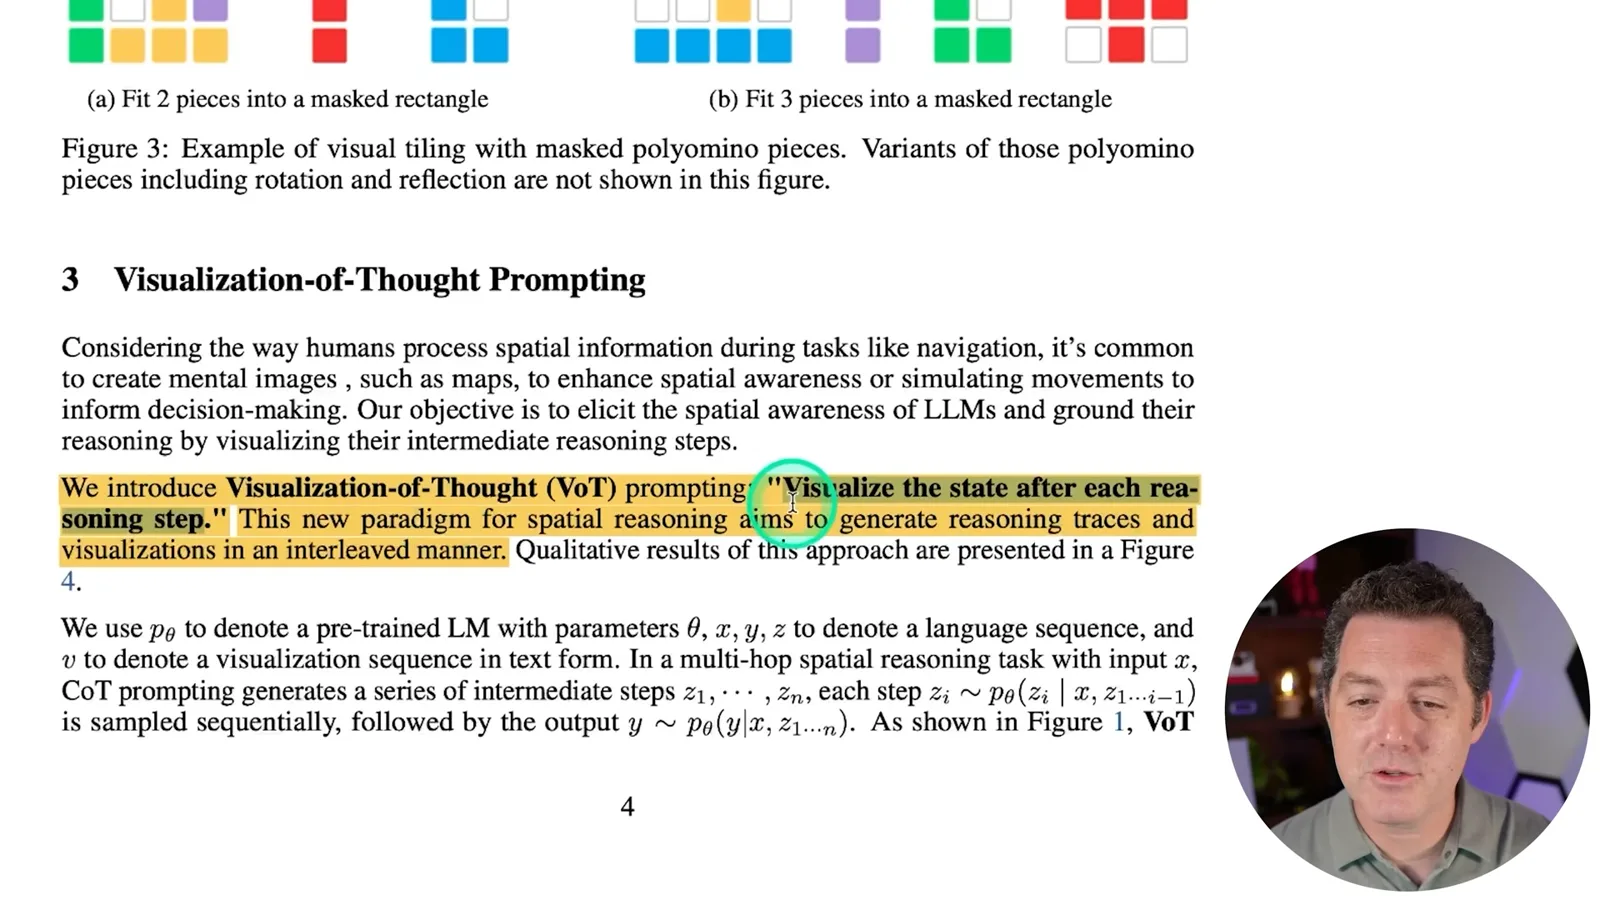
The paper uses a zero-shot instruction, without few-shot examples or a separate text-to-image generator. The researchers evaluate natural-language navigation, visual navigation and visual tiling. For the two visual tasks they represent synthetic two-dimensional grid worlds with special characters, so a text model has a structured way to work with the layout.
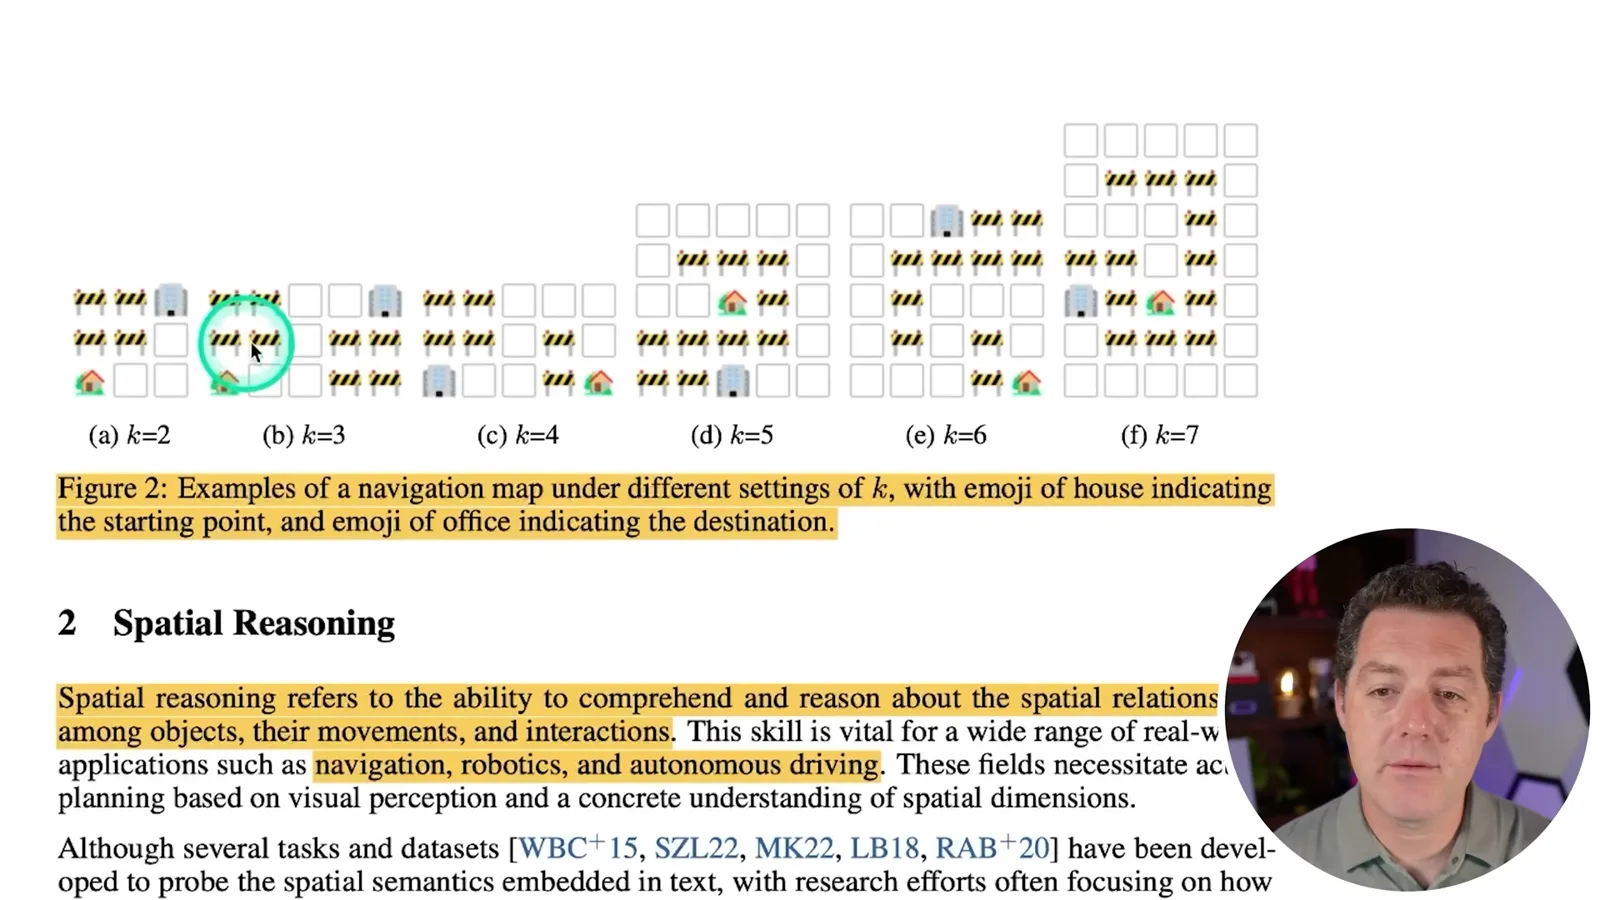
In the navigation examples, the house marks the start, the office the destination, and barriers identify blocked squares. A simple map might be solved by moving right twice and up twice; larger maps make tracking the route more difficult. The researchers vary the grid and obstacles to make the model reason over multiple movements.
The paper connects spatial reasoning to navigation, robotics and autonomous driving, but these experiments themselves are grid-world tests. In visual navigation, the model must move up, down, left or right while avoiding obstacles. The researchers evaluate both complete route planning and prediction of the next step; planning the whole route is the harder test.
The second visual task resembles fitting Tetris pieces into a constrained space. Given a partially filled grid and shapes such as a four-square bar, the model must determine where the pieces can fit. The challenge is to maintain the relationships between shapes and empty cells as each placement changes the available space.
The central instruction is simple: visualize the state after each reasoning step. In a navigation trace the model can record each move and update the map before choosing the next one. In tiling, it can place one piece, represent the updated grid, and then reason about the remaining pieces.
Natural-language navigation works in the other direction: the model receives a described grid and a sequence of steps, then has to report where it ends up or what it finds. The example marks its current location at successive steps, allowing the trace to show how the position changes rather than only giving the final answer.
Results and limitations
The reported GPT-4 VoT comparisons improve across measured tasks, though route-planning success remains low. Berman discusses state tracking and the limitations of harder tasks.
The comparison uses GPT-4 with ordinary chain-of-thought, GPT-4 prompted not to visualize, GPT-4V with chain-of-thought, and GPT-4 with VoT. In the paper's table, VoT leads on each reported metric. For route planning, its success rate is 14.72%, compared with 10.28% for the no-visualization setting: a roughly 43% relative gain, but only 4.44 percentage points and still a low absolute success rate.
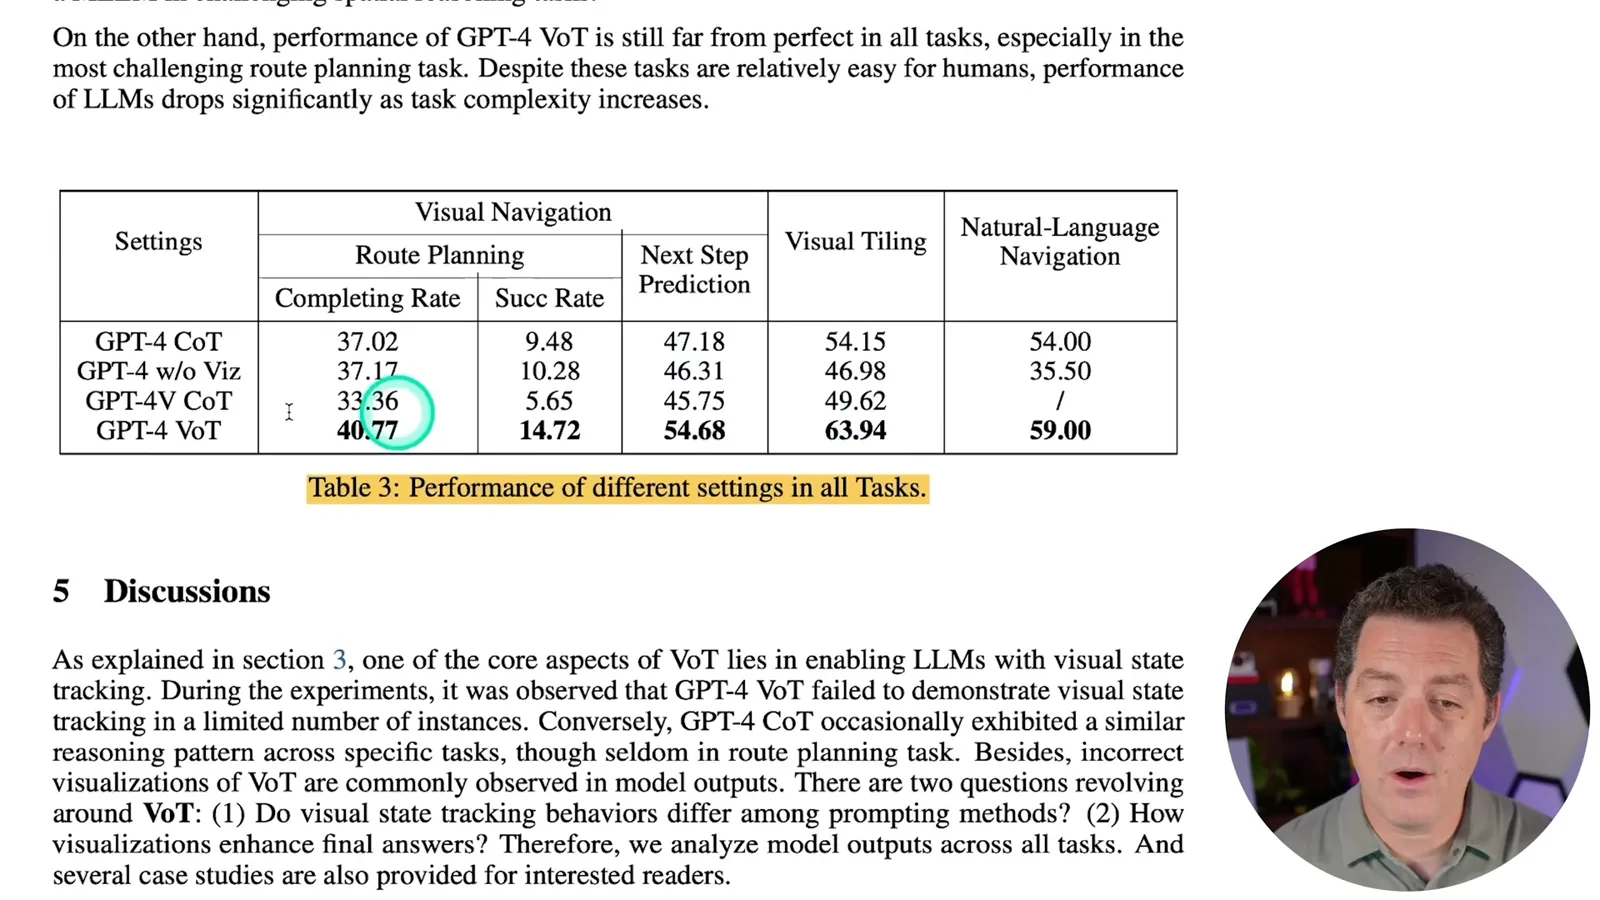
VoT also scores 54.68% on next-step prediction, 63.94% on visual tiling and 59% on natural-language navigation in this evaluation. These are results for the paper's particular models, prompts and datasets, not proof that spatial reasoning is solved generally. The original [research paper](https://arxiv.org/html/2404.03622v1) says performance falls as the tasks become more complex.
The authors also examine whether the models track visual state throughout a solution. Complete tracking means a visualization accompanies each step; partial tracking means at least one is present. Ordinary chain-of-thought sometimes produces tracking without an explicit visualization instruction, while VoT encourages it more consistently in the examples discussed.
There are limitations: this behavior relies on capabilities that may be weaker in less advanced models, and harder problems can still cause deterioration. A generated visualization can also be wrong. Asking a model to record intermediate state makes its process easier to inspect, but it does not guarantee that the state or the answer is correct.
PyWinAssistant demos
Berman reviews examples of a separate open-source Windows assistant operating browser controls and planning a social post. The video closes with additional use cases.
The separate [PyWinAssistant project](https://github.com/a-real-ai/pywinassistant) describes an open-source Windows assistant that takes natural-language instructions and operates interface elements. Its repository references the paper and discusses VoT-style reasoning. The demonstrations show computer-interface actions; they do not demonstrate a physical robot or establish reliable control of every application.
In the first demo, a user gives the assistant a series of commands: open Firefox, choose YouTube, enter a search, select a result and mute playback. The assistant reports the application it selected and the coordinates it chooses for clicks. This is a sequence of observed desktop interactions, with the user supplying the individual goals along the way.
A second example asks for a Twitter post with a greeting. The display shows the assistant analyzing the request, reformulating the goal and recording a current status before producing a plan. It identifies steps such as opening the browser's address bar, navigating to the site and composing the post.
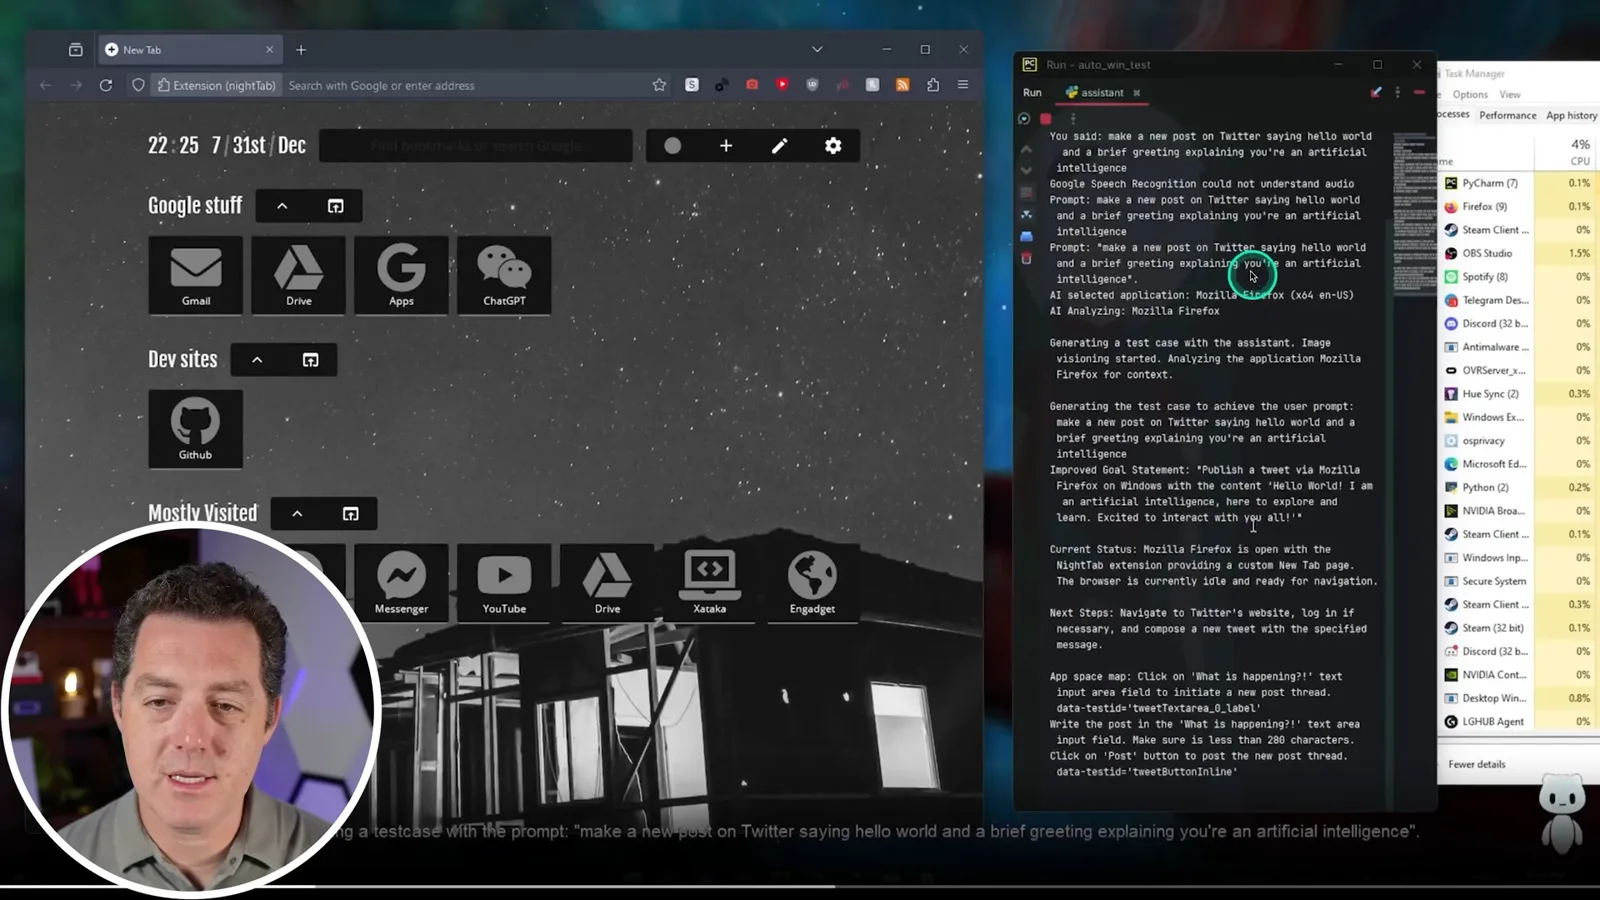
The demo then shows actions including locating the address bar and entering text while the log reports what the assistant is doing. Seeing the generated plan and the individual steps is useful for understanding the proposed workflow, although a demonstration alone does not measure reliability across changing interfaces or establish that every proposed action succeeded.
The project lists further examples, including opening a song in a new tab and interacting with buttons. I find the combination of language instructions and explicit interface actions interesting, and encourage readers to explore both the project and the research paper. The paper's controlled grid experiments and the desktop demonstrations address related ideas at different levels of evidence.
Mehr aus diesem Kanal
 34:21EN
 Matthew Berman· 27. Okt. 2026Matthew Berman Examines Anthropic’s IPO Filing, AI Growth and GovernanceMatthew Berman, Sam Altman · Forward FutureThe presenter reviews the S-1’s financial metrics, compute strategy and voting structure while questioning the tension between rapid AI development and safety.
 0:36ENMatthew Berman· 25. Okt. 2026Kimi K3.1 and a Rubik’s Cube Solver DemonstrationMatthew Berman · Forward FutureMatthew Berman shows a scrambled virtual cube being solved and gives the Kimi K3.1 test a favorable assessment.
 25:50ENMatthew Berman· 24. Okt. 2026Kimi K3.1 Pro Tested: Strong 3D Demos, Uneven Results and Competitive PricingMatthew Berman · Forward FutureMatthew Berman tests the open-weight model on coding, 3D rendering and visual explanations, then compares benchmark results and prices.
 32:20ENMatthew Berman· 23. Okt. 2026Who Is Local AI For? The Costs, Trade-offs and a Hybrid FutureMatthew Berman · Forward FutureMatthew Berman weighs data control and independence against hardware cost, setup complexity and inference speed.
 1:03:37ENMatthew Berman· 23. Okt. 2026Matthew Berman’s Team Tests Kimi K3.1 on Animation, Games, and ChartsMatthew Berman, Alex, Brian · Forward FutureA live team AMA turns into an informal test of Kimi K3.1, from personal-agent workflows to motion graphics, a browser game, and a benchmark chart.
 0:53ENMatthew Berman· 22. Okt. 2026Sam Altman on AI and the Discovery of New KnowledgeSam Altman · OpenAIAltman expects progress in mathematical discovery to extend to biology, materials and energy.