In 30 Sekunden
In August 2024 Matthew Berman tests the SearchGPT prototype, Perplexity and Google Search on viewer-suggested questions. He favors AI-generated answers for some explanatory queries and Google’s structured tools for others, while showing errors and emphasizing source checks. His informal tests and product observations are a snapshot of that time rather than a current ranking.
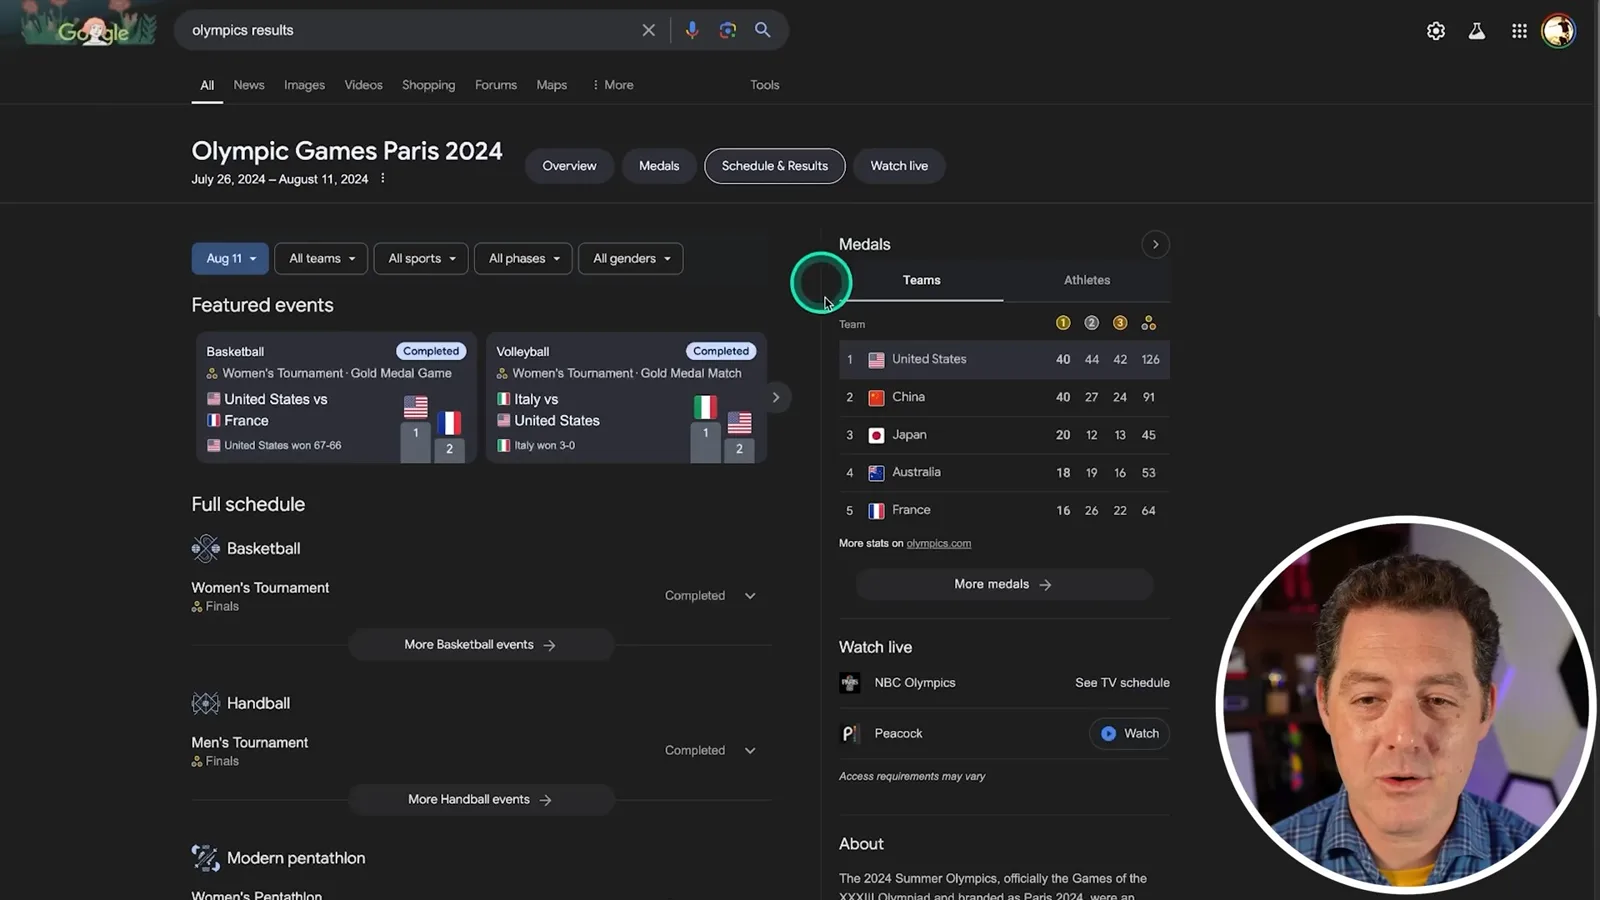
- 1Olympic resultsSearchGPT gives a cited summary; Google shows a structured medal table that Berman prefers for this query.
- 2Linux and Python questionsThe AI systems provide direct explanations, while Google’s result requires more navigation in his tests. The suggested fixes were not all run or independently validated.
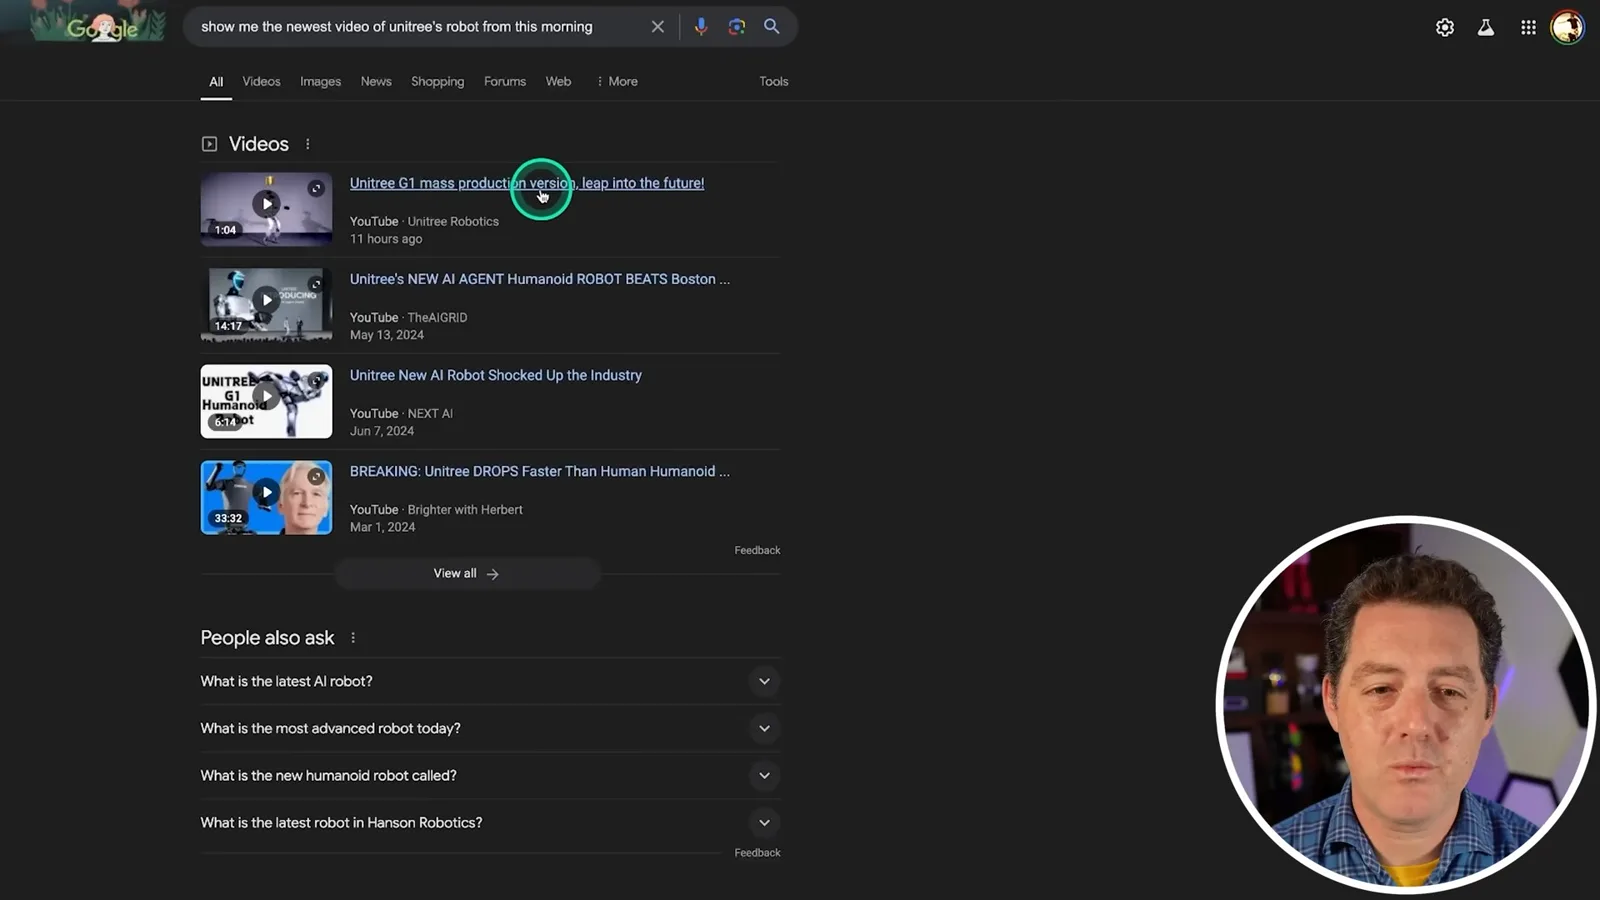
- 3Finding a recent videoGoogle surfaces the official recent Unitree video; the other tools return older or indirect links in this test.
- 4Conference speakersSearchGPT’s list includes names Berman cannot confirm on the event page; Perplexity’s answer is incomplete and offers generic reasons.
- 5Flights and imagesGoogle’s specialized results work better in these examples, particularly after he reformulates the flight query.
- 6Answer engines and search enginesBerman prefers Perplexity overall for his own use in 2024, while acknowledging that the best choice depends on the task.
Das Wichtigste
- SearchGPT and Perplexity provide synthesized answers and citations, but a citation alone does not guarantee an accurate answer.
- For Olympic results and a newly posted robot video, Berman prefers Google’s structured or timely results in his examples.
- AI search helps him with the Linux and Python questions, though he does not independently execute every suggested solution.
- A conference-speaker query illustrates why current primary sources should be checked against generated lists.
- Google’s flight and image tools perform better for his demonstrated navigation and filtering tasks.
- The comparison is informal and sensitive to query wording, location, account settings and changes over time.
Den bearbeiteten Text nach Kapiteln lesen
Comparing the interfaces
Berman introduces SearchGPT, Perplexity and Google using Olympic results. He compares citations, follow-ups and structured results.
I have access to OpenAI’s SearchGPT prototype and want to compare it with Perplexity and Google Search. Viewers suggested a variety of searches, from coding to travel and current events. This is an informal August 2024 comparison: account settings, location, wording and later product changes can all affect the results.
SearchGPT gives a generated answer, images and citations, with a sources panel and follow-up questions. For Olympic results it summarizes medal information. As with any generated answer, fluent text can be wrong, so the links are a starting point for checking rather than a guarantee that every statement is correct.
Perplexity offers a similar conversational experience with sources and follow-ups, plus features such as related searches, collections and file attachments in the interface I see. For the Olympic query, Google’s dedicated result panel is my favorite: it makes medal counts and event tabs easy to scan without reading a long answer.
Technical questions and recent video
The tools answer Linux and Python questions, with different levels of detail. Google finds a recent Unitree video that the other tests miss.
The first suggested technical search asks how to find an IP address using the newer Linux ip command. SearchGPT provides ip addr and an example output, although it also shows images that do not seem helpful. I check a linked article and find that the command and its variants are equivalent; I do not run the command myself in this demonstration.
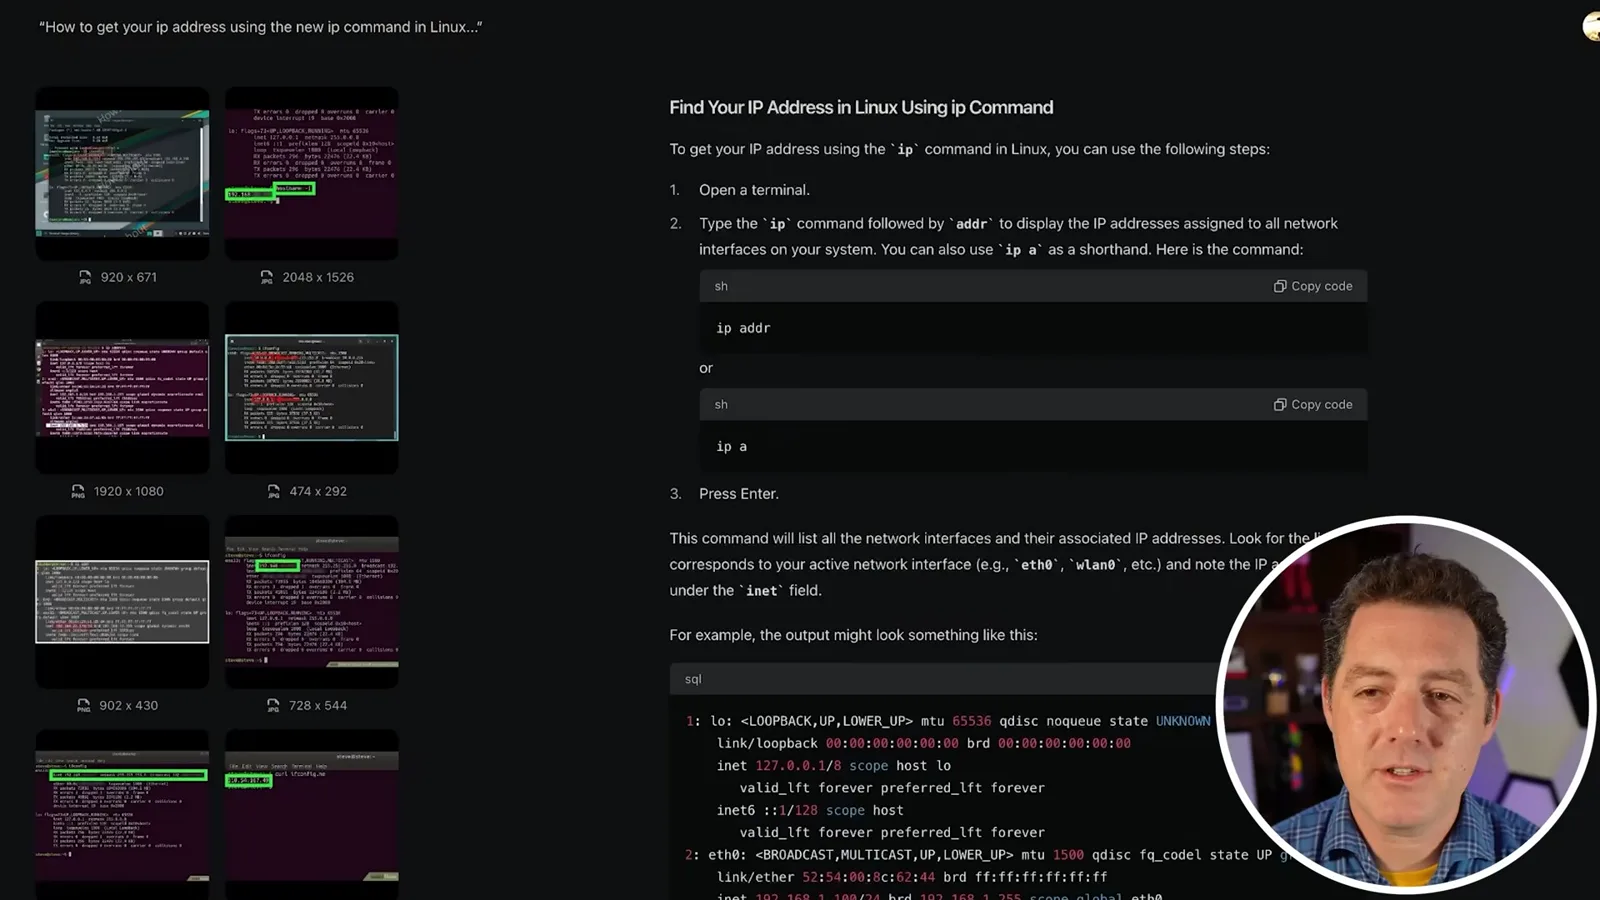
Perplexity provides ip addr show, related searches and sources. In Google, I see an AI overview and conventional links, including results that mention older ifconfig as well as ip. For this question I prefer the direct answers from the two AI tools, while still needing to check a source for correctness.
Next I ask why a Python program cannot find a module that appears to be present. SearchGPT supplies possible explanations; a standard ChatGPT query gives a broadly similar answer. That makes me question whether a web search was necessary for this particular prompt, though a similar answer alone cannot prove which sources were used.
Perplexity suggests checking the environment, package installation and Python path. Google’s AI overview also lists possible causes and links to sources, but I prefer the more actionable code-oriented responses from the other two. These are general troubleshooting suggestions, not a diagnosis of a specific environment, and I do not execute each proposed fix.
For freshness, I look for a Unitree robot video published that morning. SearchGPT surfaces older videos. Perplexity identifies a recent title and date, but the linked video I open is a review rather than the original. Google’s first video result points to the recent official upload, so it wins this individual test.
Events, speakers and local search
Berman compares venue capacity, conference-speaker and cinema queries. The examples show both convenience and possible errors or location mismatches.
A business query asks for Melbourne venues capable of hosting 1,500 delegates. SearchGPT returns a list, but some entries are described as accommodating only 1,400 or 1,200. Perplexity provides a shorter list that appears to meet the requested capacity, while Google primarily gives links; I prefer Perplexity’s presentation in this example.
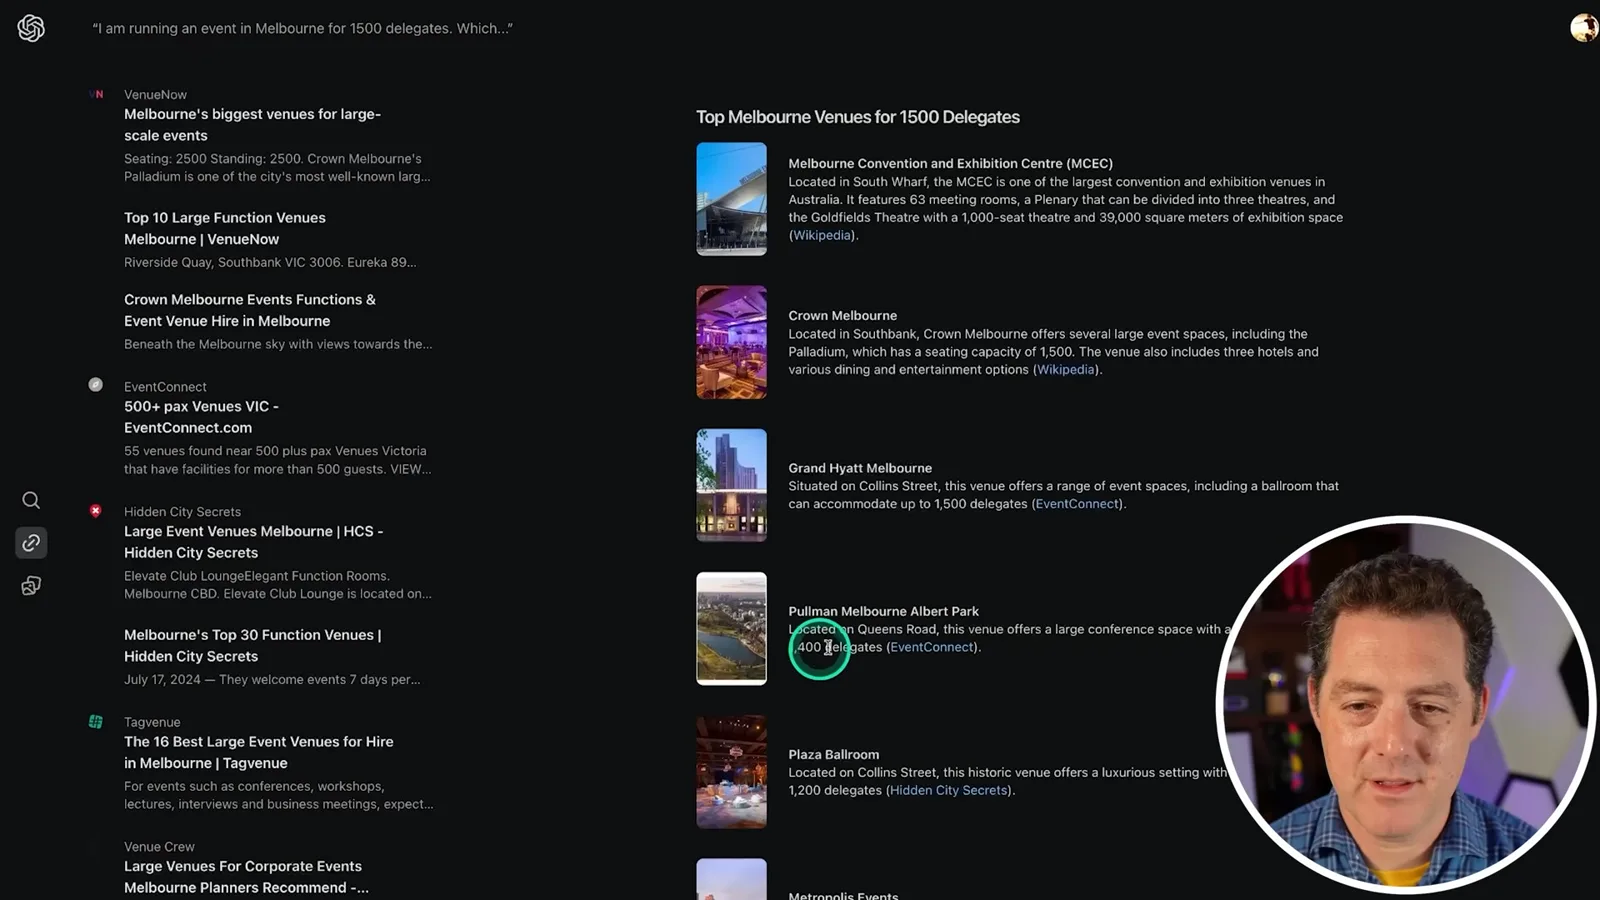
A venue’s true suitability still depends on room layout, availability and the event’s requirements. The video does not independently verify each listed capacity, so the generated list should be treated as a starting point and checked against the venue before planning.
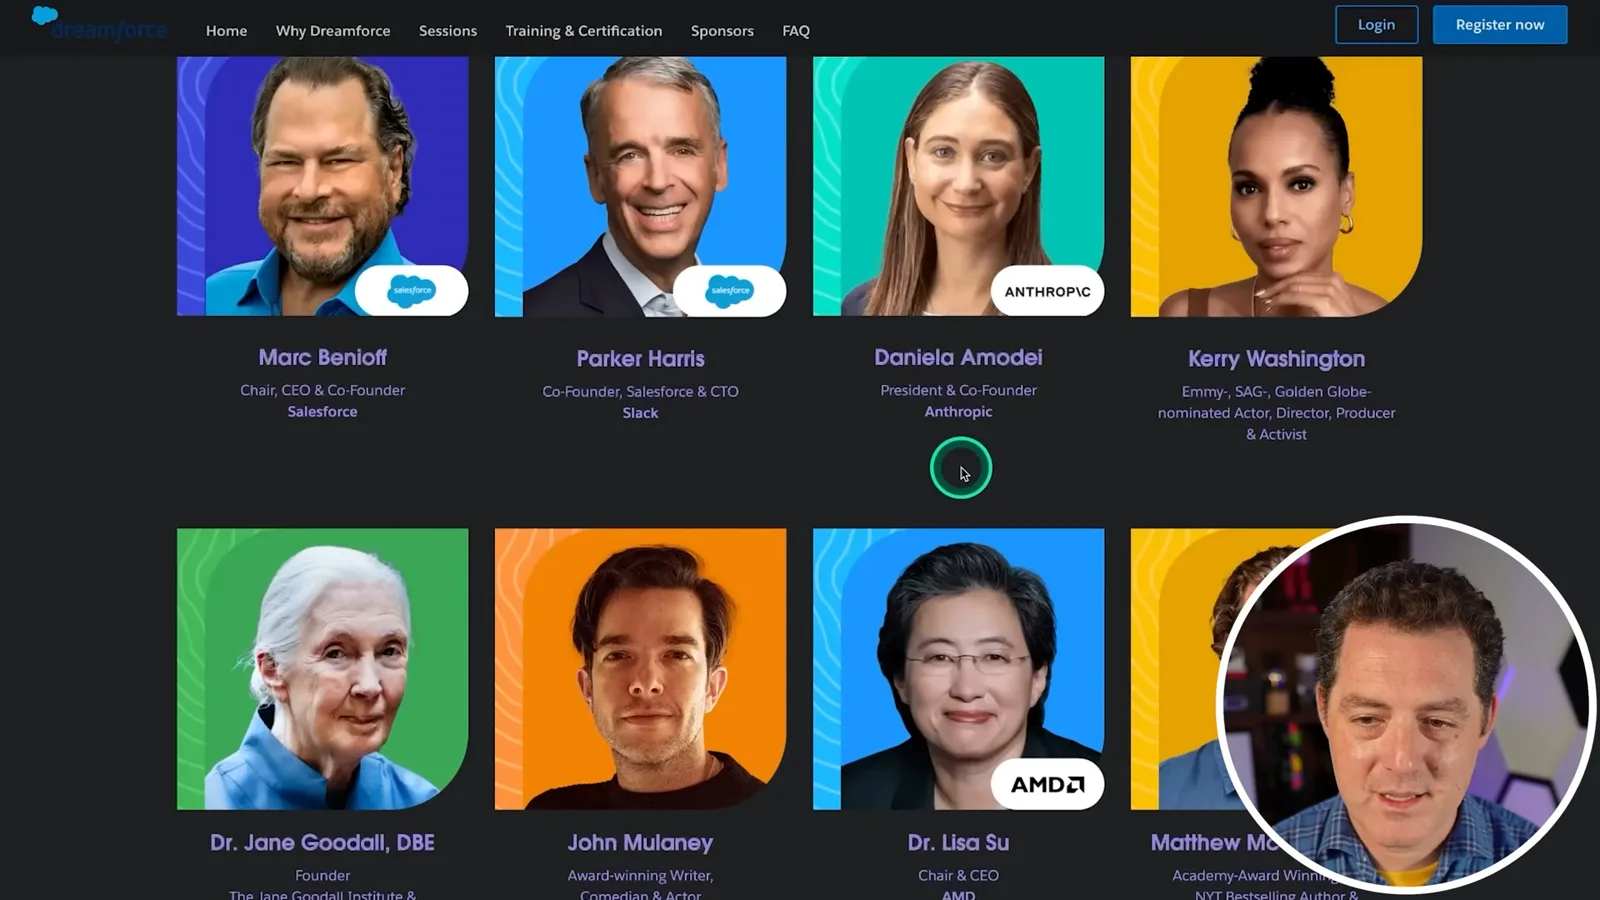
I ask who the main presenters at the upcoming Dreamforce conference are and why they were selected. SearchGPT lists several names and gives a generic explanation; Perplexity produces a different, shorter list with a similarly broad rationale. Neither really explains the reasons for each person’s selection.
I open the event’s speaker page to compare. Some names in SearchGPT’s answer do not appear in the list I inspect, so I suspect it mixed information or hallucinated. Perplexity appears closer but omits a person I expected to see; absence from the portion of a page examined is not by itself definitive proof that someone was never scheduled.
For a local movie-theater query, I hide the results to protect my location. I report that SearchGPT gives relevant local theaters and reasons, while Perplexity assumes an incorrect location and Google’s results also do not fit my current location. Because the results are not shown, viewers cannot independently verify my assessment.
News, health questions and travel
The video tests a political-news query and supplement questions without independently verifying the health answers. Google’s flight results improve after a shorter query.
Viewers also ask about political bias. I search for reporting on the July 2024 attempted assassination of Donald Trump. SearchGPT and Perplexity provide summaries with sources, while Google shows news and web links. I find the summaries easier to read, but this single query does not establish whether a search engine is unbiased or whether every generated detail is accurate.
A question about collagen and creatine by age produces general answers from the AI tools. Neither gives the detailed breakdown I wanted, and I say explicitly that I do not know whether the recommendations are accurate. The Google results also do not directly answer the question in my test; the video does not establish safe dosages.
For locating a specific website or a video whose source I cannot remember, I find conventional Google Search useful because it prioritizes links. Synthesized answers can be convenient, but sometimes the primary destination itself is the thing I want.
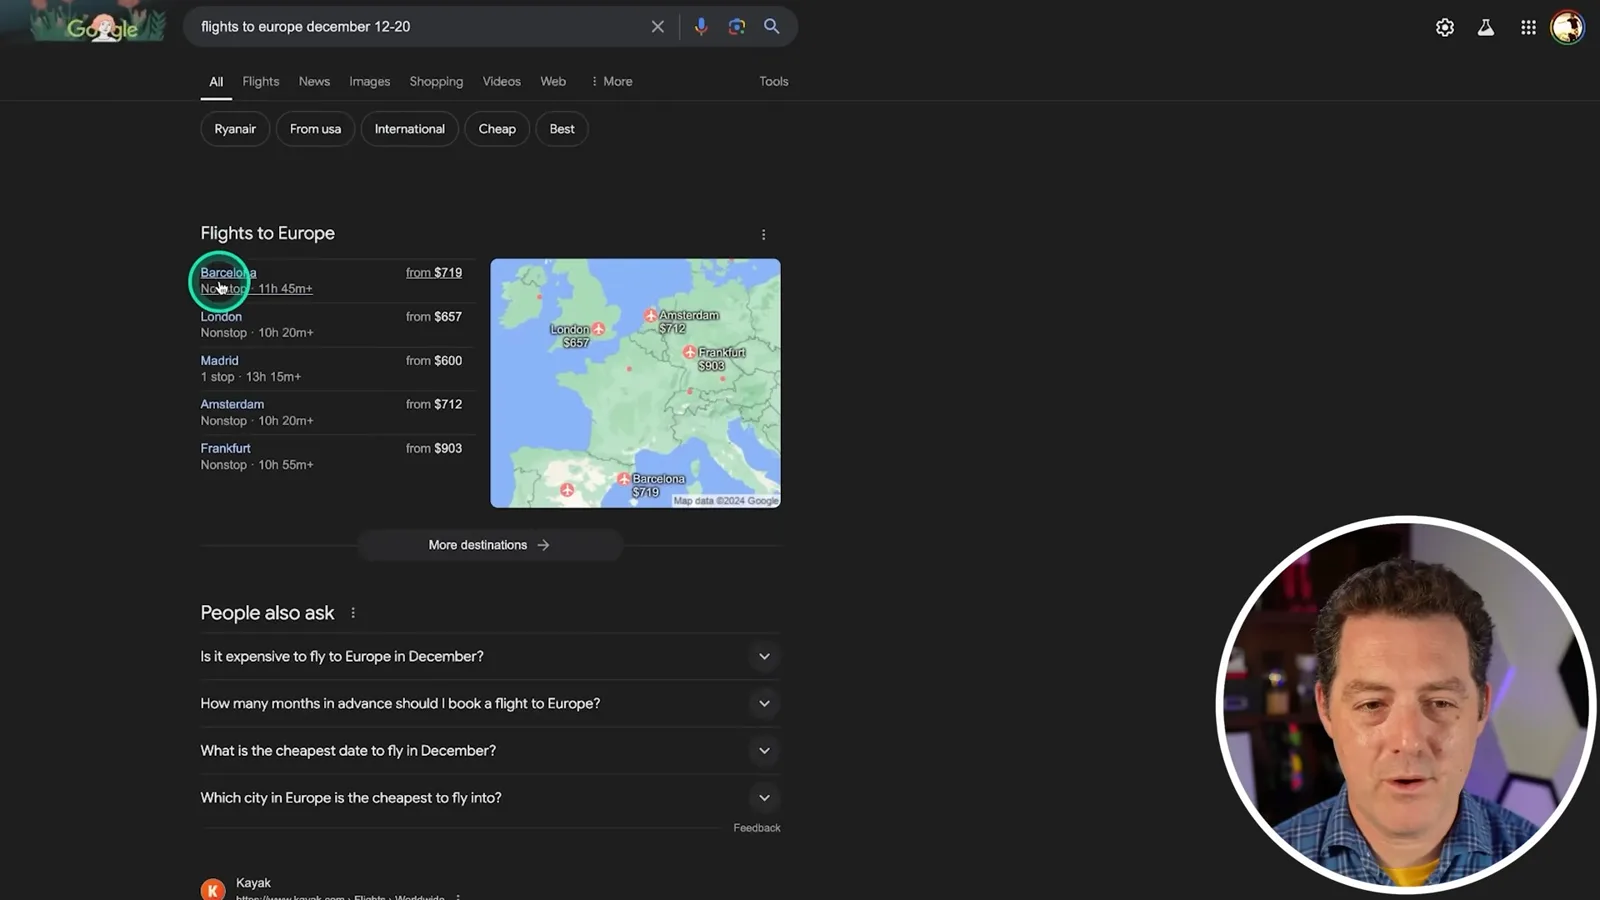
I try a hypothetical flight search for two adults and two children traveling to Europe in business class during December. SearchGPT gives airline information without the specific flights I want; Perplexity offers advice and points me toward flight-search tools. Neither result in this test supplies a complete itinerary matching the request.
Google initially returns ordinary links for the long question. After I shorten the query, it displays destinations and prices, which I find more useful. The reformulated query omits some original details, so the panel does not demonstrate that every option satisfies the original dates, passenger counts and business-class requirement.
Images and final judgment
Google offers more image-search filtering in the demonstration. Berman weighs answer synthesis against speed, links and specialized tools.
Finally, I search for robot images. SearchGPT returns a limited set with little filtering in the prototype I am using; Perplexity interprets the term broadly and offers information. Google’s image tab supplies a larger collection and filters for different kinds of images, making it my preferred tool for this example.
My overall view is that AI search works like an answer engine: it synthesizes a response, links to sources and allows follow-up questions. Google is useful for finding a destination, searching images or using integrated tools, and it feels faster in these tests. The distinction is useful, though Google also has an AI overview and the products continue to change.
I find Perplexity’s interface and feature set more complete than the early SearchGPT prototype, and I would choose Perplexity if forced to use just one based on this experience. That is a personal preference from a small set of 2024 queries, not a controlled accuracy study; the best choice depends on the question and on checking important answers.
Mehr aus diesem Kanal
 34:21EN
 Matthew Berman· 27. Okt. 2026Matthew Berman Examines Anthropic’s IPO Filing, AI Growth and GovernanceMatthew Berman, Sam Altman · Forward FutureThe presenter reviews the S-1’s financial metrics, compute strategy and voting structure while questioning the tension between rapid AI development and safety.
 25:50ENMatthew Berman· 24. Okt. 2026Kimi K3.1 Pro Tested: Strong 3D Demos, Uneven Results and Competitive PricingMatthew Berman · Forward FutureMatthew Berman tests the open-weight model on coding, 3D rendering and visual explanations, then compares benchmark results and prices.
 32:20ENMatthew Berman· 23. Okt. 2026Who Is Local AI For? The Costs, Trade-offs and a Hybrid FutureMatthew Berman · Forward FutureMatthew Berman weighs data control and independence against hardware cost, setup complexity and inference speed.
 1:03:37ENMatthew Berman· 23. Okt. 2026Matthew Berman’s Team Tests Kimi K3.1 on Animation, Games, and ChartsMatthew Berman, Alex, Brian · Forward FutureA live team AMA turns into an informal test of Kimi K3.1, from personal-agent workflows to motion graphics, a browser game, and a benchmark chart.
 0:53ENMatthew Berman· 22. Okt. 2026Sam Altman on AI and the Discovery of New KnowledgeSam Altman · OpenAIAltman expects progress in mathematical discovery to extend to biology, materials and energy.
 0:22ENMatthew Berman· 21. Okt. 2026A Robot Bodyguard Video Shows Dramatic Rescue ScenariosMatthew Berman · Forward FutureMatthew Berman reacts to a short robot demonstration depicting fighting and vehicle-rescue scenarios.