In 30 Sekunden
Theo Browne examines Anthropic’s Sonnet 5.5 and finds it more useful than he expected, especially for scoped codebase research delegated by another agent. He questions whether its lower token prices translate into lower overall costs, compares reasoning settings, and demonstrates a generated game. His benchmark results and explanations of model behavior are observations and hypotheses, not universal guarantees.
- 1Cache-read pricingTheo cites $0.20 per million cached input tokens for both Sonnet 5.5 and Opus 5.5, despite other Sonnet prices being lower.
- 2Reasoning effortHe warns that max effort was expensive in some comparisons and offers an unverified explanation for why it behaves that way.
- 3Delegated researchHis Orchestrator V2 audit scored Sonnet slightly above Opus at roughly half the cost in that particular test.
- 4Game comparisonThe Sonnet game impressed him, but the Opus run included a Fable subagent, complicating the comparison.
Das Wichtigste
- A cheaper token price does not guarantee a cheaper task when token consumption and cache pricing differ.
- Reasoning settings affect cost and quality, so compare them on the work you actually do.
- In Theo’s audit, Sonnet was a relatively fast and inexpensive way to analyze a large codebase.
- Fast token generation does not necessarily mean a shorter task if the model generates more tokens.
- A generated game can reveal different strengths from a benchmark or a website design demo.
Den bearbeiteten Text nach Kapiteln lesen
An unexpected Sonnet release
Theo introduces Sonnet 5.5 and the claims in Anthropic’s announcement. He explains why its role surprised him.
I did not expect to care much about Claude Sonnet 5.5. Opus 5.5 had already become my default, and the previous Sonnet release had disappointed me. Yet this new model has impressed me in a specific role, even if headline benchmarks do not make the case obvious.
I see the release as a cheaper Anthropic option aimed at work for which people might otherwise consider OpenAI’s GPT-6 Sol. That positioning is my interpretation. I am not arguing that Sonnet should automatically replace Opus for every developer.
Anthropic describes Sonnet 5.5 as a clearer, faster model for well-scoped everyday tasks, complementing Opus on harder work. It says the new model is over 30% faster than Sonnet 5 and can cost up to 30% less per task in its testing. Those are comparisons with the previous Sonnet, not proof it is always cheaper than Opus.
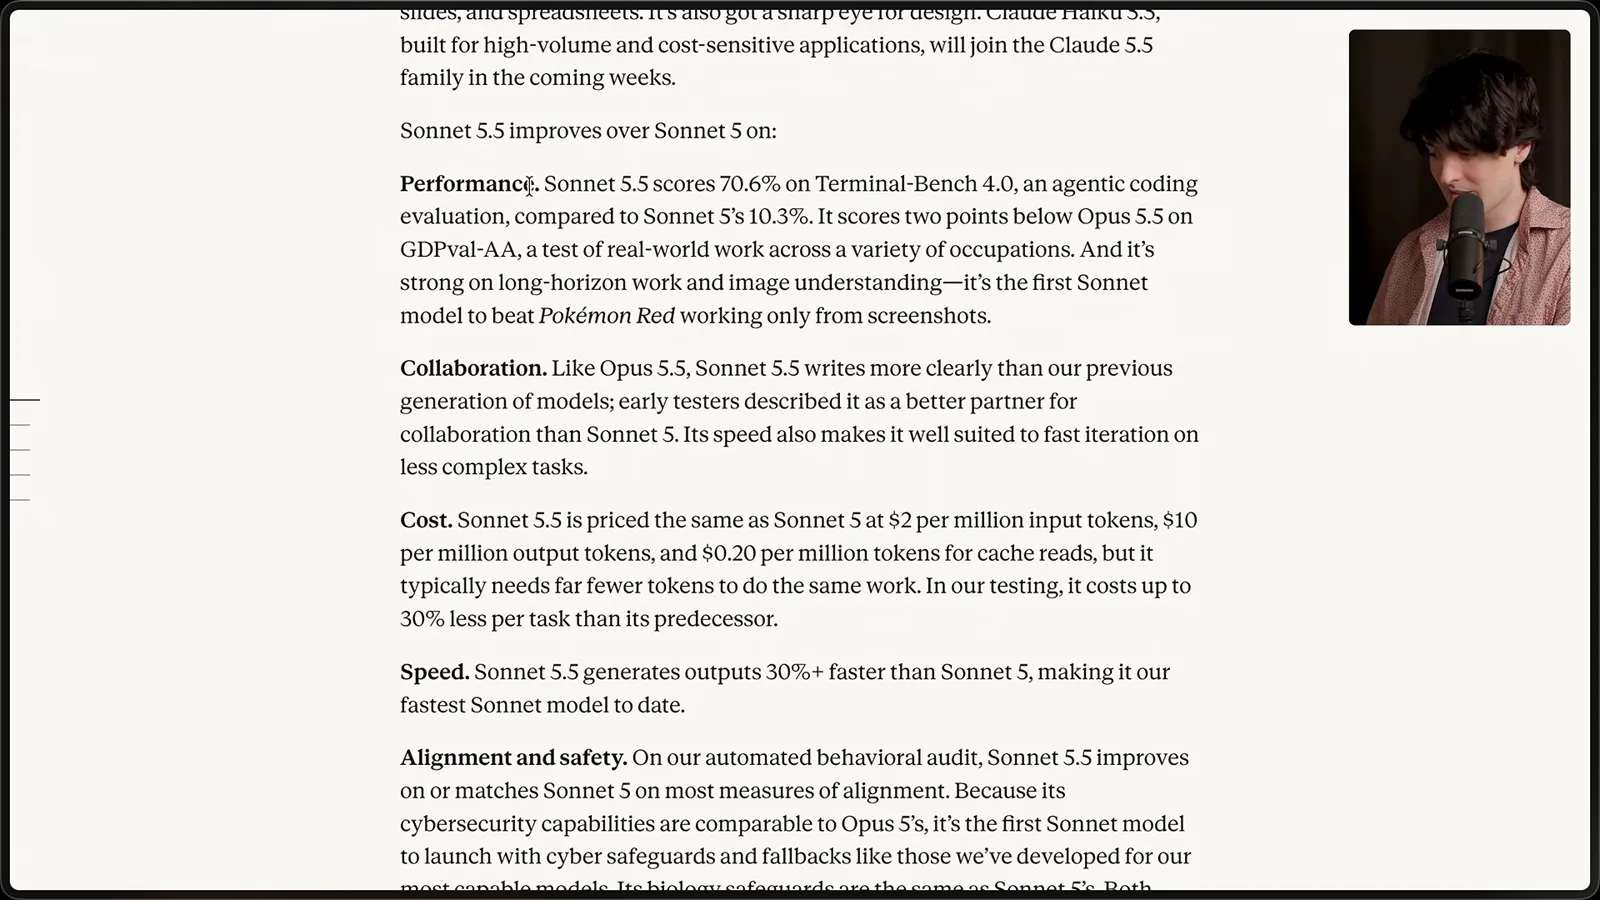
The announcement reports 70.6% on Terminal-Bench 4.0, compared with 10.3% for Sonnet 5, and says it completed Pokémon Red using screenshots. Those are striking results, but I remain skeptical of reducing a model’s practical abilities to a single benchmark.
Subjectively, the new smaller model feels more like a faster, less capable version of Anthropic’s larger models than its predecessor did. I speculate about changes to training, but cannot establish the cause. It also writes more clearly and feels easier to collaborate with than Sonnet 5.
Pricing and reasoning effort
He compares input, output and cache prices and discusses the cost of different reasoning settings. His account of their internal mechanisms is conjecture.
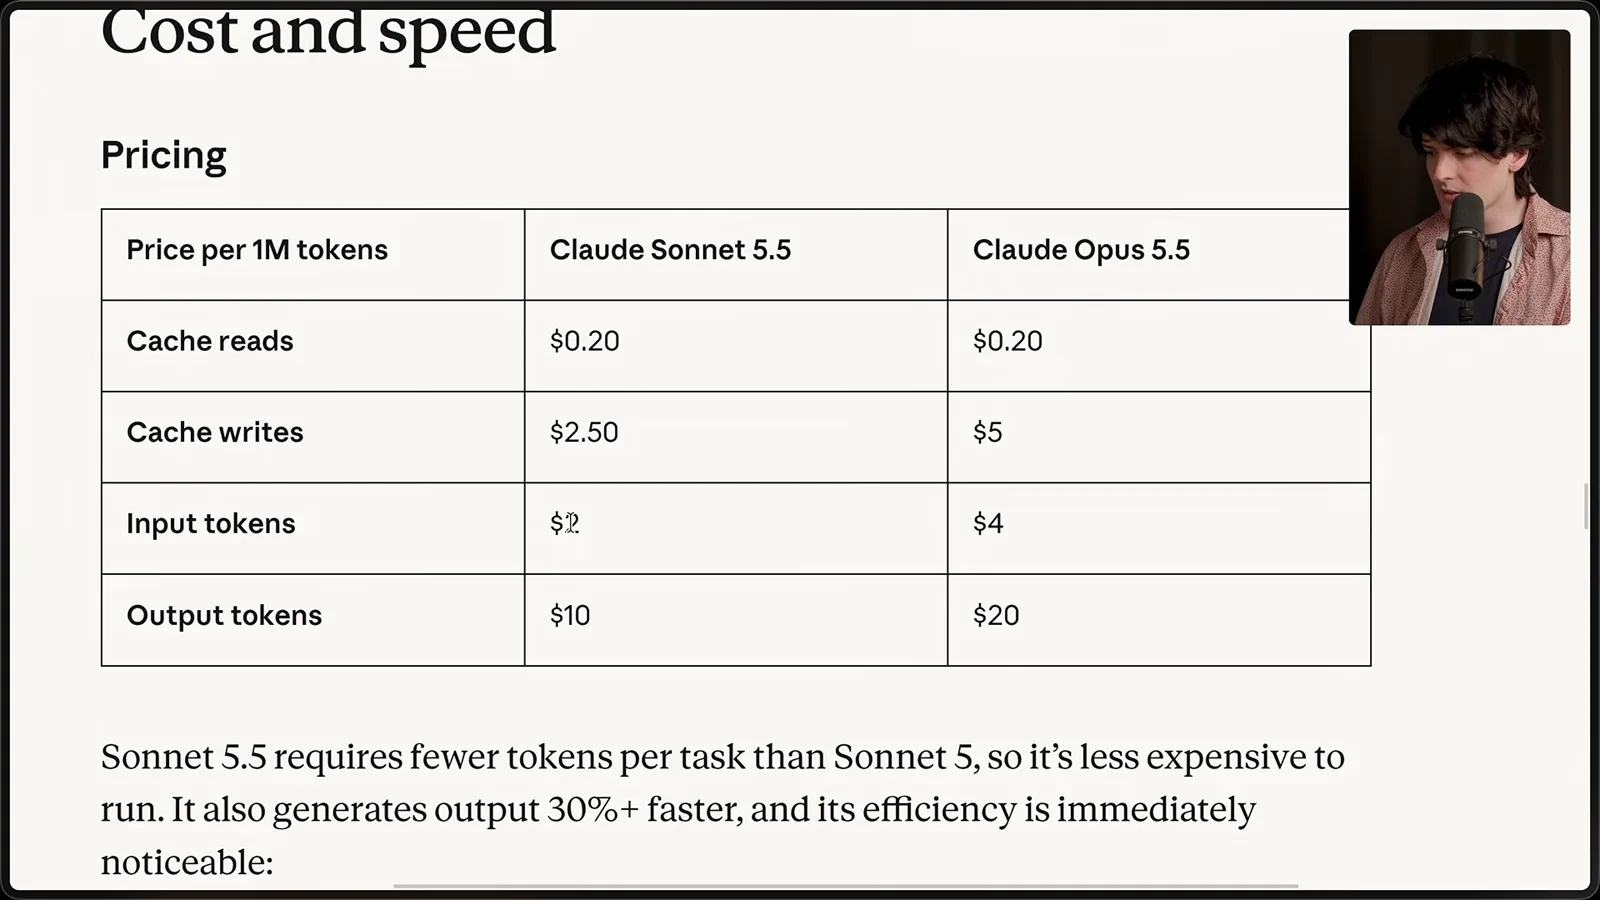
Anthropic lists Sonnet 5.5 at $2 per million input tokens, $10 per million output tokens and $0.20 per million cached input tokens. It says fewer tokens are typically needed than with Sonnet 5. The prices are those shown at release; actual task cost depends on the workload.
The cache-read price complicates comparisons with Opus 5.5. On the displayed table Sonnet’s ordinary input, output and cache writes are about half Opus’s price, but both models charge $0.20 per million cache reads. Repeated reads can be a substantial part of an agent workload.
I compare those figures with Fable 5.1, whose other token prices are higher but whose quoted cache reads cost $0.25 per million. In my own examples, cache reads make up a much larger share of Sonnet’s bill than Fable’s. The share changes with the pattern of requests and caching.
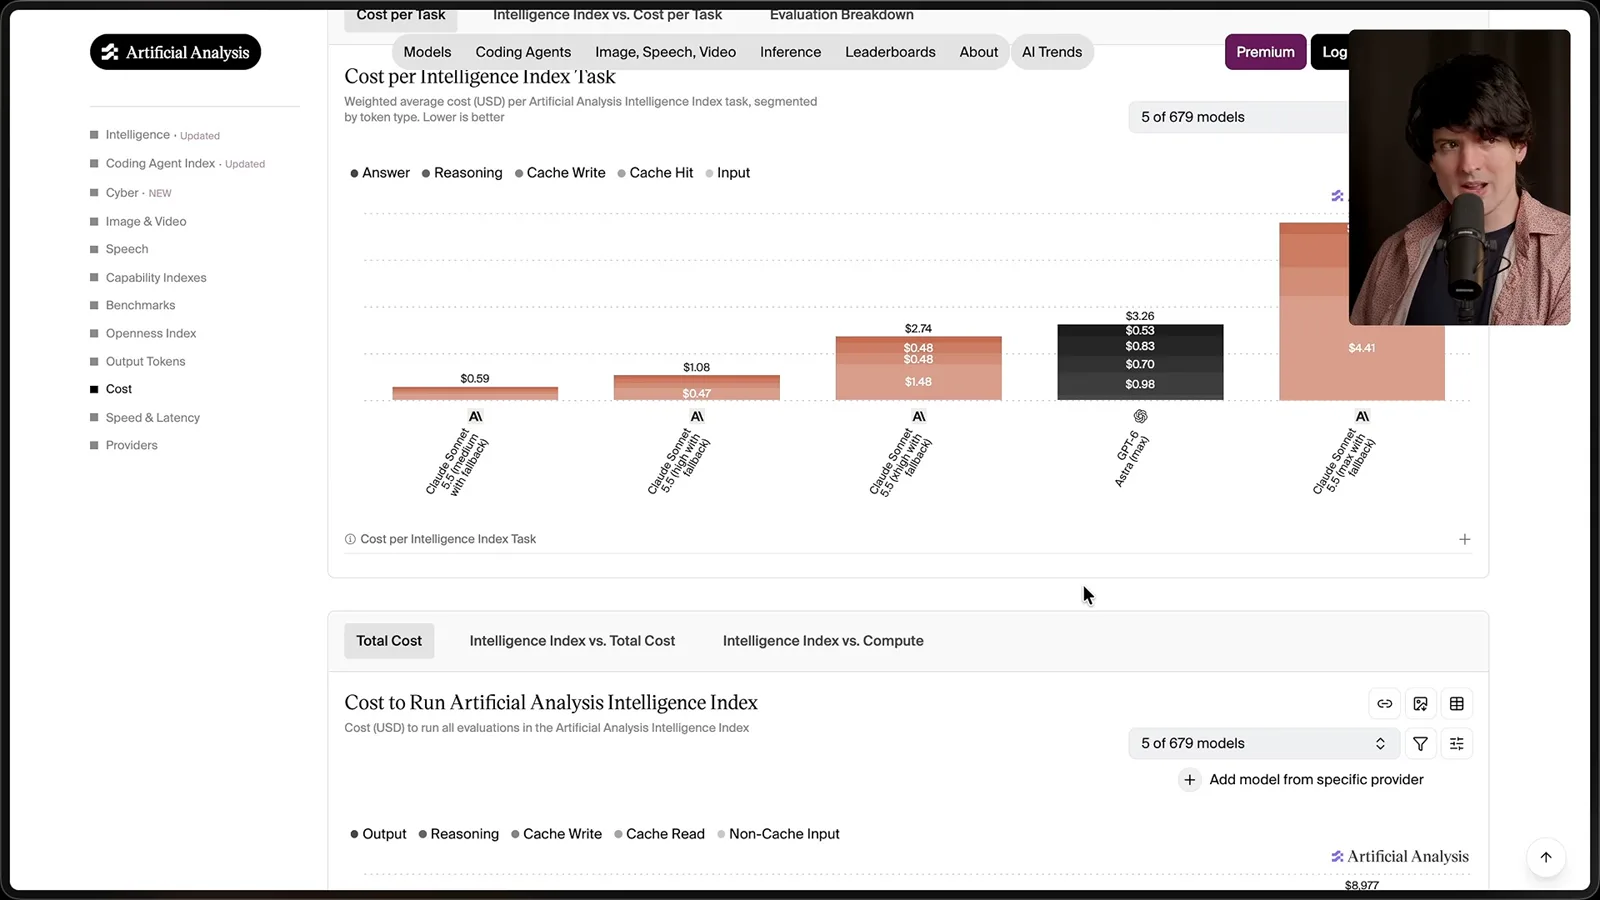
Because of that, I have seen comparable coding tasks where Sonnet costs as much as or more than Opus. The Artificial Analysis index also shows an expensive Sonnet run at max effort. Neither comparison establishes that Sonnet is always more expensive; it shows why the task-level bill matters.
I am particularly wary of max reasoning effort. I think of the lower settings as allowing different reasoning budgets, and I hypothesize that max pushes the model to spend much longer thinking even on easy work. The exact internal mechanism is not established by the examples I show.
In some of my benchmarks, the jump to max used far more tokens than the difference between low and x-high, and sometimes performance fell. I suspect excessive deliberation can lead to second-guessing. That is an observation and interpretation of these tests, not a rule that max is always worse.
The displayed Artificial Analysis comparison puts Sonnet max at $7.60 per index task and Astra max at $3.26. Sonnet’s lower effort settings are cheaper. My practical advice is to measure quality and cost at the settings relevant to your tasks rather than assuming the highest effort is best.
Benchmarks, speed and design
He compares benchmark curves, output speed and token use. Website design examples do not impress him as much as his preferred models.
Other benchmark curves show x-high beating max in some cases. I also advise against low effort for these Anthropic models based on the large drops I see, while finding medium more acceptable for Opus than Sonnet. These are preferences drawn from selected benchmarks, not a universal setting for every workload.
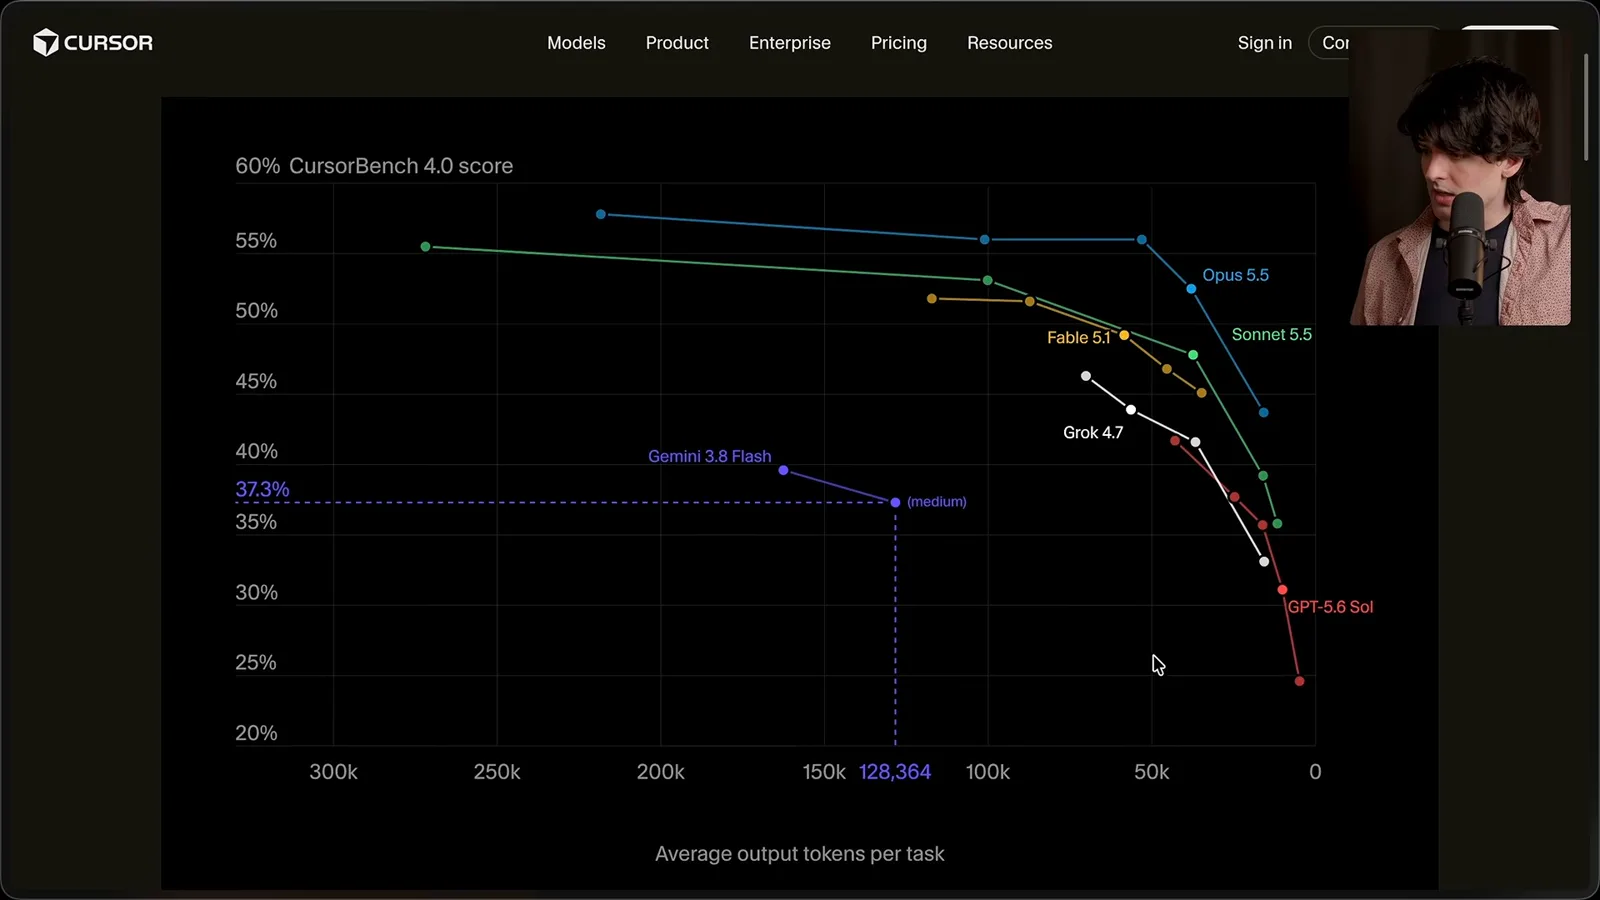
CursorBench presents another angle: Sonnet uses many output tokens in the displayed comparison. A cheap rate per token can be offset by generating more tokens. I want to look at total token use as well as the score-to-cost curves.
OpenRouter reports roughly 94 output tokens per second for Sonnet and 70 for Opus, while I observed about 150 and 100 respectively using subscriptions. Yet in my fish-game run Sonnet took 43 minutes and Opus 36, because throughput per second and the total amount generated are different things.
I look through front-end examples on the Which AI showcase. One turns a page into a simulated app, but other examples have readability, hierarchy or animation choices I dislike. I have not explored Sonnet’s design limits exhaustively; these examples are a subjective, narrow sample.
For visual design I still prefer Fable 5.1 overall, with Opus more steerable when given instructions. For similar work, Opus can also end up around the same price in my experience. So why am I excited about Sonnet at all?
Sonnet as a research subagent
A large codebase audit suggests a useful role in analysis delegated by a larger model. The test uses an automated judging panel and is not a controlled universal ranking.
I do not expect Sonnet to be my main model for general coding. Instead, I think a larger model could call it as a subagent for bounded research: investigating a codebase, confirming behavior or preparing information for a plan. The useful unit of comparison is the delegated task.
To explore that role I asked models to examine a very large Orchestrator V2 pull request in T3 Code and propose how to break the changes into smaller pieces. The task is analytical: it tests understanding and planning rather than simply writing a patch.
My automated judging panel ranked Astra’s plan highest. Sonnet scored 7.81 at $1.24, slightly above Opus at 7.71 and $2.40 in the displayed comparison. Sonnet was run four days later on a larger version of the pull request and scored separately, so this is not a perfectly controlled head-to-head test.
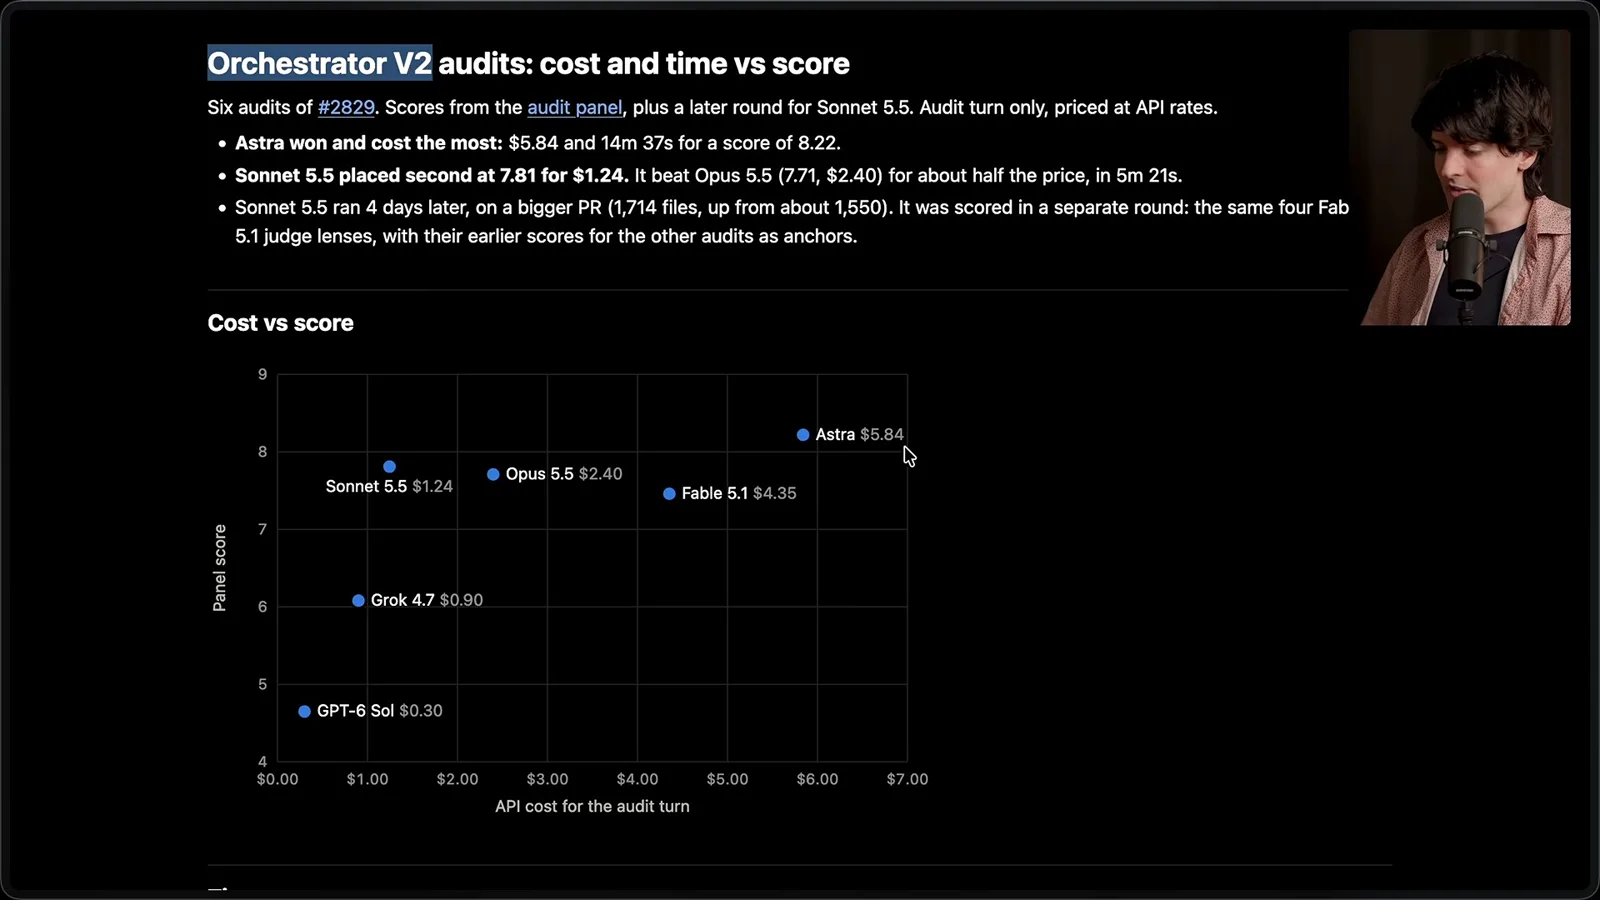
Sonnet completed the audit in about five minutes, while Opus took almost twice as long and Astra nearly three times as long in this example. That makes it promising for a larger agent that needs a quick investigation before continuing. It remains one test judged by my own panel.
A 3D game and the final assessment
He discusses a task-context mistake and demonstrates a generated fish game. He concludes that Sonnet is most interesting as a tool for other agents.
I have also been experimenting with a TypeScript compiler rewrite in Rust. Opus helped unblock the project but left a large amount of older generated code behind, so I asked for cleanup. In a monitoring thread I was briefly puzzled that Sonnet did not report deleted code.
The mistake was mine: I had opened the wrong thread, one whose prior context was about numbers. In that context, the response was more reasonable than I first thought. Asking the specific question showed that roughly 1.6 million lines had been deleted since I started filming.
For the fish-game comparison, Sonnet’s initial build cost about $16.15 versus $17.07 for the Opus run. But the Opus run also used a Fable 5.1 subagent, so that is not a clean comparison of two single models. Sonnet used over three times as many input tokens in this example.
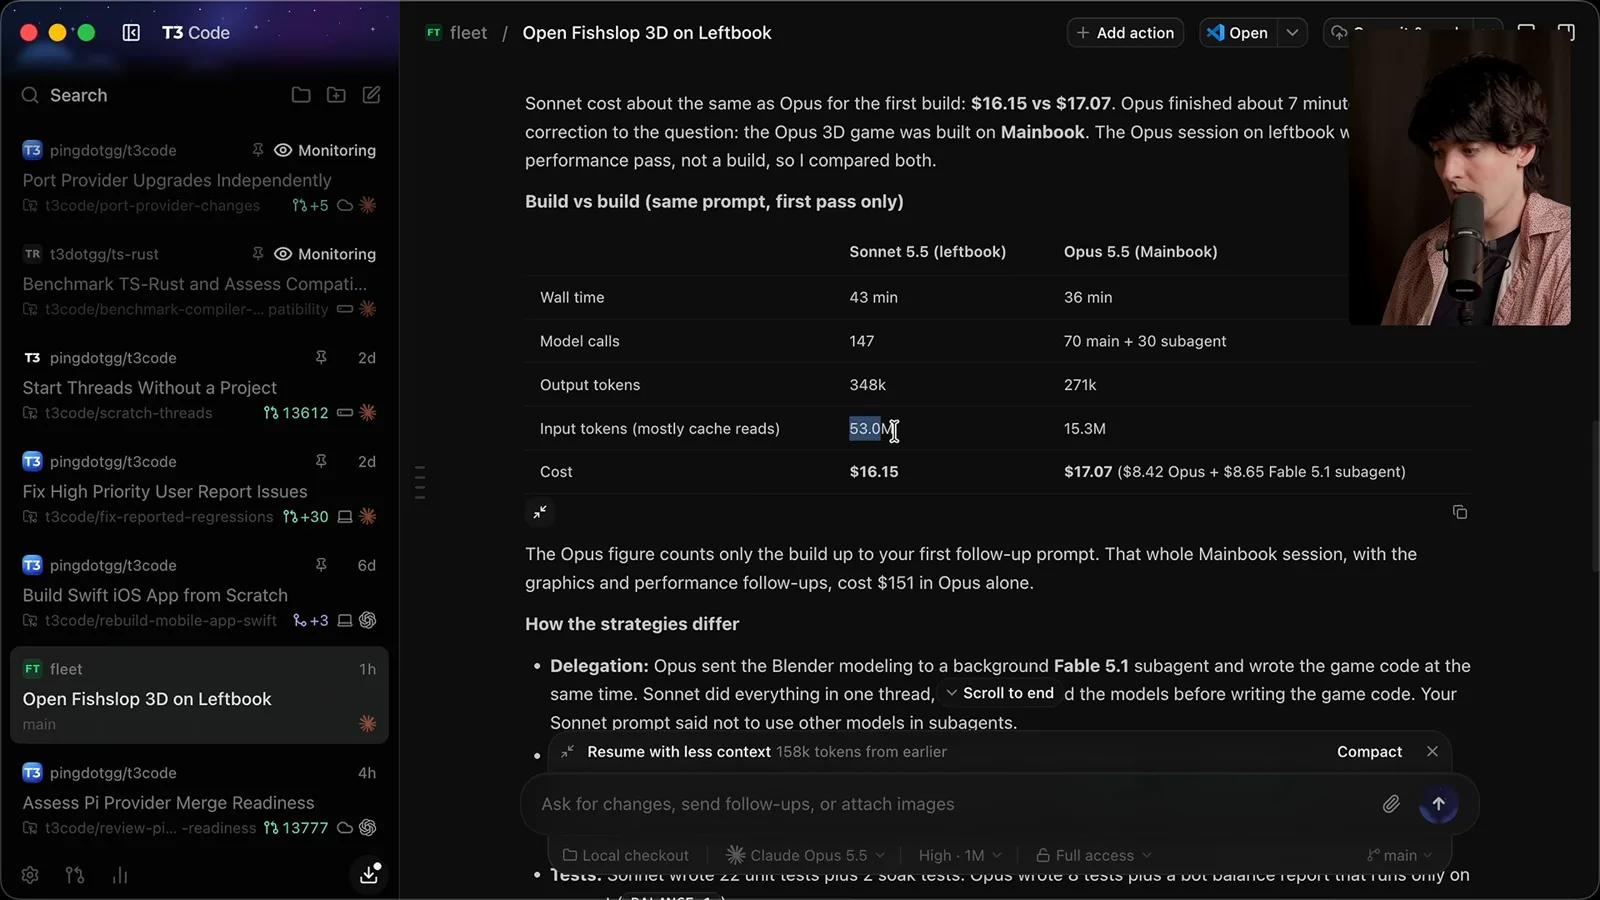
The result itself is one of the best fish-game demos I have seen. Some individual 3D models are weaker than Opus’s, but the fish, coral and seaweed are recognizable and appealing. The game’s movement and mechanics also feel good to me.
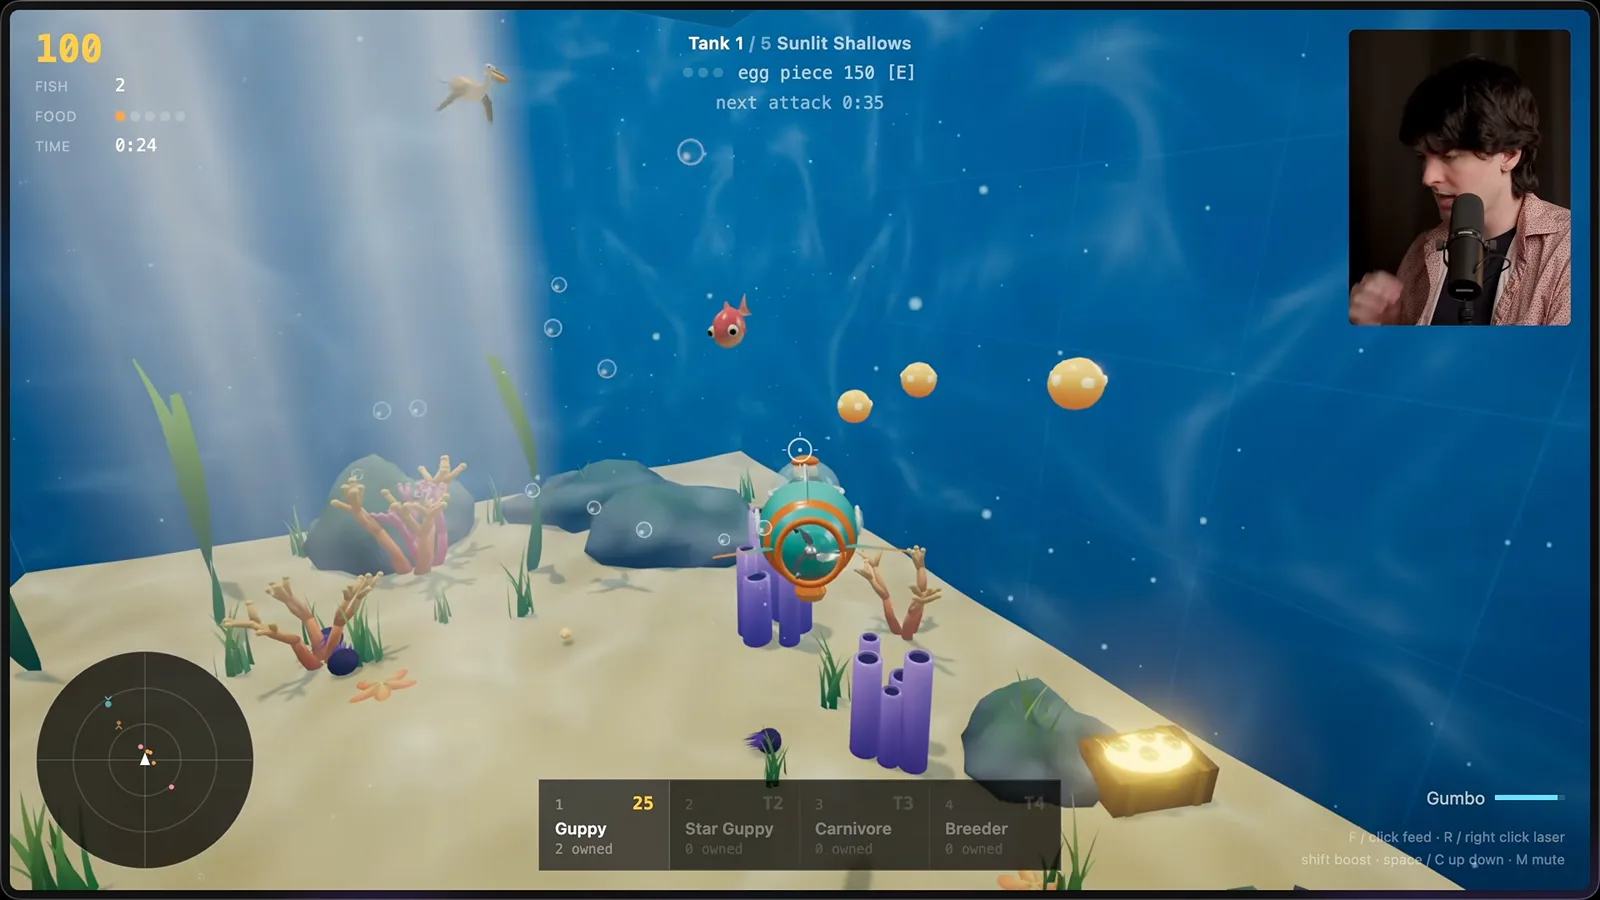
I report that the game ran at about 120 frames per second on my laptop, although the video itself cannot convey that full frame rate. I especially like the animated fish and the alien opponent. A single demonstration is not a comprehensive assessment of either model’s game-development ability.
The model produced the game in roughly 40 minutes. At API prices I estimate about $16 for the initial run; my subscription cost is different. Those figures describe this attempt, not a promise about what it will cost to reproduce elsewhere.
I estimate about $2,300 per week of API-equivalent usage from my own $200 Claude subscription accounts, or nearly $10,000 over 30 days. That is a personal usage comparison, not cash, a guaranteed allowance or a general subscription entitlement; limits can vary.
For direct day-to-day coding, I still prefer Opus. For targeted investigation, however, a Sonnet subagent can be fast and economical in my tests. I expect to experiment with having Opus delegate codebase research and validation to it, then review the results.
My closing view is that this gives Anthropic a useful tool across model tiers and puts pressure on OpenAI, as I saw the market at the time of filming. The competitive picture and prices can change quickly; the durable lesson is to compare models on the specific work and total cost that matter to you.
Mehr aus diesem Kanal
 36:07EN
 Theo - t3․gg· 27. Okt. 2026Theo on Token Costs, Coding Agents, and the Price of AI CapabilityTheo Browne · Ping LabsA viral estimate of Lauren's AI spending prompts a closer look at cache pricing, benchmarks, and the changing work of coding agents.
 30:37ENTheo - t3․gg· 26. Okt. 2026Theo’s Three Skills for Reviewing and Shipping with Coding AgentsTheo Browne · Ping LabsHow sol-loop, full-send and full-stop encode review, verification and different levels of merge authority.
 0:43ENTheo - t3․gg· 23. Okt. 2026Theo Distinguishes Security Vulnerabilities from Active AttacksTheo Browne · Ping LabsA short explanation of why disclosed software flaws and reported attacks are different kinds of security news.
 29:22ENTheo - t3․gg· 22. Okt. 2026Theo on Security Vulnerabilities, Stolen API Keys and AITheo Browne · Ping LabsA look at the gap between vulnerability disclosure and patching, and a speculative account of why stolen inference keys may be valuable.
 31:13ENTheo - t3․gg· 20. Okt. 2026Theo on Why Smarter Models Help More Than DevelopersTheo Browne · Ping LabsFrom game modifications to compiler experiments, Theo revisits his assumptions about who benefits from more capable AI.
 31:47ENTheo - t3․gg· 18. Okt. 2026Theo on Asking Agents for Outcomes and Building the Tools They NeedTheo Browne · Ping LabsA tool-call report, a troubleshooting playbook and connected data show how prompting can reshape product engineering.