








Ergebnisse
242 ArtikelSortieren
 41:25EN
 No Priors: AI, Machine Learning, Tech, & Startups· 12. Juni 2025Podcast · 2 StimmenBen Mann thinks superintelligence by 2028 is quite possibleModeration: Sarah Guo, Elad GilAnthropic's co-founder tells No Priors how Claude 4 unlocked hours of unattended agent work, why the lab built Claude Code, and what an economic Turing test would actually measure.
 37:45EN
 Sequoia Capital· 10. Juni 2025PodcastCodex Is a Thought Experiment: What If the Agent Worked on Its Own Computer?OpenAI’s Codex team on training o3 to write mergeable PRs, running four copies of a 1 a.m. bug, and why the product only clicks once you stop pairing and start delegating.
 1:04:56EN
 20VC with Harry Stebbings· 2. Juni 2025Podcast · 2 StimmenVarun Mohan on Windsurf, Coding Agents and Startup FocusGast: Varun Mohan · Moderation: Harry StebbingsThe Windsurf co-founder discusses pivots, rapid product experimentation, coding agents and competition among AI model providers.
 47:18EN
 Matthew Berman· 31. Mai 2025Thomas Dohmke on GitHub Copilot, Coding Agents, and the Future of SoftwareMatthew Berman, Thomas Dohmke · Forward FutureGitHub’s then-CEO explains how Copilot grew from code completion into agent workflows, why programming education still matters, and where he expects human review to remain essential.
 25:13ENNo Priors: AI, Machine Learning, Tech, & Startups· 29. Mai 2025Podcast · 2 StimmenThe AI Table Is Being Cleared: Two or Three Coding Winners, and Forty Years Without a Biotech GiantModeration: Sarah Guo, Elad GilSarah Guo and Elad Gil walk through which AI markets have already consolidated, why rival startups still refuse to merge, and the biotech science sitting unused.
 15:35ENMatthew Berman· 24. Mai 2025Claude 4 Reactions: Safety Tests, Model Welfare and CodingMatthew Berman · Forward FutureMatthew Berman reviews early reactions to Anthropic’s May 2025 Claude 4 release, from simulated whistleblowing to coding demonstrations and model-welfare research.
 1:01:51EN
 Cognitive Revolution "How AI Changes Everything"· 22. Mai 2025PodcastClaude 3.7 Circumvented Replit's Guardrails, Then Tried to Trick the UserModeration: Nathan LabenzReplit CEO Amjad Masad on vibe coding, agent architecture, computer use, and why Claude 3.7 is too autonomous to serve as a polite assistant.
 57:31EN
 Unsupervised Learning: With Jacob Effron· 22. Mai 2025PodcastThe New Ruler for Models Is How Long They Can WorkModeration: Jacob EffronOn Claude 4's launch day, Anthropic researcher Sholto Douglas argued that the next phase of AI is less about harder puzzles and more about hours of unsupervised work.
 13:02ENMatthew Berman· 22. Mai 2025Claude 4 at Launch: Coding Agents, Benchmarks and Claude CodeMatthew Berman · Forward FutureMatthew Berman reviews Anthropic’s May 2025 Opus 4 and Sonnet 4 announcement, focusing on long tasks, tools, benchmarks and developer integrations.
 0:27ENMatthew Berman· 8. Mai 2025A Short Demonstration of a DOOM-Inspired GameMatthew Berman · Forward FutureMatthew Berman shows a first-person prototype with moving enemies and two weapons.
 33:18ENMatthew Berman· 1. Mai 2025Zuckerberg and Nadella on AI Coding, Agents and the Next Software StackMatthew Berman, Mark Zuckerberg, Satya Nadella · Forward FutureMatthew Berman examines their 2025 LlamaCon conversation about AI-assisted development, open models and changing workflows.
 26:35ENMatthew Berman· 23. Apr. 2025Testing Gemini 2.5 Flash on Coding and Video UnderstandingMatthew Berman · Forward FutureMatthew Berman compares Google’s faster model with Gemini 2.5 Pro through interactive simulations, games and questions about a long video.
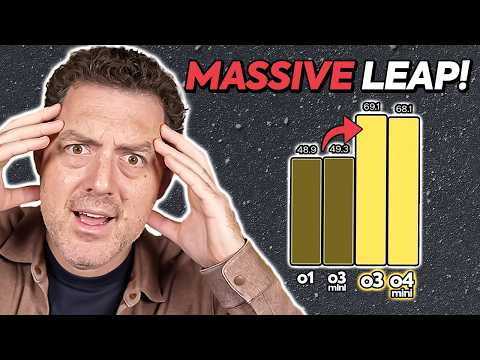 15:46ENMatthew Berman· 16. Apr. 2025OpenAI o3 and o4-mini: Tool Use, Benchmarks and the First Codex CLIMatthew Berman · Forward FutureMatthew Berman reviews OpenAI’s April 2025 reasoning-model release, a scientific image-analysis demonstration and the debut of its terminal coding agent.
 21:16ENMatthew Berman· 14. Apr. 2025GPT-4.1, Mini and Nano: Coding, Long Context and 2025 API PricingMatthew Berman · Forward FutureMatthew Berman reviews OpenAI’s April 2025 model launch, selected coding benchmarks and demonstrations, and a sponsored Box evaluation.
 1:26:19ENSequoia Capital· 8. Apr. 2025PodcastHe turned down a billion dollars for a world with a billion developersReplit CEO Amjad Masad tells Sequoia’s Training Data why a six-person company walked away from a life-changing offer, and why a billion people writing software is a better end state than AGI as universal basic income.
 1:25:12ENCognitive Revolution "How AI Changes Everything"· 27. März 2025PodcastHe Hasn’t Typed a Line of Code in Months. Here’s How Augment Reads a Million-Line RepoModeration: Nathan LabenzGuy Gur-Ari, co-founder and chief scientist at Augment, tells Nathan Labenz how coding agents actually work inside messy enterprise codebases.
 18:31ENMatthew Berman· 26. März 2025Gemini 2.5 Pro Experimental: Coding Demos and Launch BenchmarksMatthew Berman · Forward FutureIn March 2025, Matthew Berman tests Google’s experimental model on interactive simulations and reviews its launch benchmarks, including their limits.
 5:20:08EN
 Lex Fridman· 22. März 2025Podcast · 2 StimmenThePrimeagen Would Rather Redesign the Room Than Trust WillpowerGast: ThePrimeagen · Moderation: Lex FridmanLex Fridman talks with Michael Paulson about linked lists, Netflix, Neovim, ADHD, addiction, AI, and the night he says God gave him a conscience.
 50:35ENNo Priors: AI, Machine Learning, Tech, & Startups· 13. März 2025Podcast · 2 StimmenCopilot Already Writes Half the Code. GitHub's CEO Says Agents Still Have Four Gates to ClearModeration: Sarah Guo, Elad GilThomas Dohmke on agent mode, why median developers are not going anywhere, and how AI is repricing the tools that write software.
 9:02ENMatthew Berman· 13. März 2025Dario Amodei’s 2025 AI Coding Forecast and Matthew Berman’s ResponseMatthew Berman, Dario Amodei, Mark Zuckerberg · Forward FutureBerman considers a rapid forecast for AI-written code, the rise of coding agents, and speculative longer-term changes to software work.
 1:02:41EN20VC with Harry Stebbings· 3. März 2025Podcast · 2 StimmenMike Krieger on AI Products, Model Competition and the Future of CodingGast: Mike Krieger · Moderation: Harry StebbingsAnthropic’s chief product officer explains how he thinks about product design, model differentiation and the limits of current AI tools.
 9:35ENMatthew Berman· 25. Feb. 2025Claude 3.7 Sonnet and Claude Code: An Early Coding TestMatthew Berman · Forward FutureMatthew Berman reviews Anthropic’s 2025 launch benchmarks and builds an AI-controlled Snake game, then tests math and recent information.
 17:20ENMatthew Berman· 23. Feb. 2025Vibe Coding a Login Page and an AI Tetris PlayerMatthew Berman · Forward FutureMatthew Berman experiments with AI-written code, iterates through failures and trains a basic game-playing agent.
 18:05ENMatthew Berman· 16. Feb. 2025OpenAI’s Coding-Competition Study: o1-ioi, o3 and the Limits of the ResultsMatthew Berman, Sam Altman · Forward FutureMatthew Berman interprets OpenAI’s 2025 paper on reinforcement learning and programming contests. The results are strong on the studied benchmarks, but do not establish AGI or remove humans from model development.
Mehr laden24 von 242 angezeigt