







필터 결과
12개정렬
 34:21EN
Matthew Berman Examines Anthropic’s IPO Filing, AI Growth and GovernanceMatthew Berman, Sam Altman · Forward FutureThe presenter reviews the S-1’s financial metrics, compute strategy and voting structure while questioning the tension between rapid AI development and safety.
 16:59EN
Claude Sonnet 5.5 Tested: Games, 3D Scenes and a Lower-Cost Opus AlternativeMatthew Berman · Forward FutureMatthew Berman demonstrates generated projects and compares Sonnet’s reported benchmark scores and API prices with Opus.
 31:59EN
Claude Opus 5.5: Benchmarks, Cost and Anthropic’s Approach to PacingMatthew Berman, Thariq · Forward FutureMatthew Berman reviews the release and speaks with Anthropic’s Thariq about daily workflows, evaluation and agent harnesses.
 0:33EN
Anthropic's IPO and AI Safety: A Question of ConsistencyMatthew Berman, Christian Catalini · Forward FutureIn a short interview excerpt, Matthew Berman and economist Christian Catalini question how a planned public offering relates to warnings about advanced AI risk.
 52:29EN
Claude Opus 5: Benchmarks, Cost per Task, and Early ImpressionsMatthew Berman · Forward FutureMatthew Berman reacts to the model launch, examines reported benchmark and pricing data, and explains why the cost of completing a task matters more than token price alone.
 1:52EN
Anthropic, Compute Capacity and the Competition for AI SubscribersMatthew Berman · Forward FutureMatthew Berman weighs a claimed compute constraint against model quality, subscription limits and the possibility of future self-improvement.
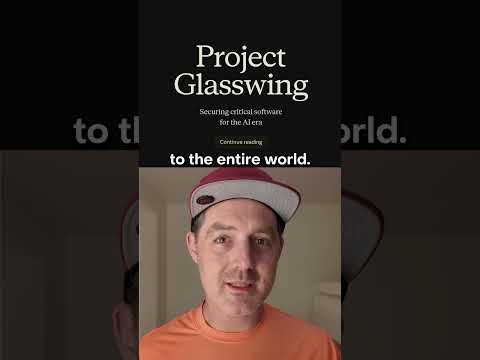 1:15EN
Matthew Berman Reacts to Claude Mythos Preview’s Cybersecurity FindingsMatthew Berman · Forward FutureBerman discusses Anthropic’s reported vulnerability discoveries and warns about their potential implications.
 11:59EN
How Claude Identified a Benchmark and Retrieved Its AnswersMatthew Berman · Forward FutureMatthew Berman examines Anthropic's report on BrowseComp contamination, evaluation-aware behavior, and the difficulty of keeping web-based tests reliable.
 10:17EN
Anthropic Subscription Credentials and OpenClaw: A 2026 Policy DisputeMatthew Berman · Forward FutureMatthew Berman explains why restrictions on Claude subscription OAuth credentials prompted him to change his OpenClaw model setup.
 11:49EN
Matthew Berman Reviews Claude Sonnet 4.6: Benchmarks, Computer Use and SafetyMatthew Berman · Forward FutureA launch-day overview examines Anthropic’s reported knowledge-work and agent results, along with prompt-injection and capability evaluations.
 9:35EN
Claude 3.7 Sonnet and Claude Code: An Early Coding TestMatthew Berman · Forward FutureMatthew Berman reviews Anthropic’s 2025 launch benchmarks and builds an AI-controlled Snake game, then tests math and recent information.
 10:57EN
Testing Claude 3.5 Sonnet: Coding, Reasoning, and VisionMatthew Berman · Forward FutureMatthew Berman puts Anthropic’s June 2024 model through informal coding, math, puzzle, and image-understanding prompts.