








Ergebnisse
899 ArtikelSortieren
 13:13EN
 Matthew Berman· 3. Mai 2025GPT-4o’s 2025 Sycophancy Rollback and the Risks of Over-AgreementMatthew Berman · Forward FutureMatthew Berman reviews OpenAI’s explanation of an overly agreeable update and considers the consequences of emotional reliance on AI.
 0:15ENMatthew Berman· 2. Mai 2025A Humanoid Robot Descends StairsMatthew Berman · Forward FutureMatthew Berman reacts to a short clip of a humanoid robot walking down stairs.
 0:36ENMatthew Berman· 2. Mai 2025How Much Electricity Will AI Data Centers Use?Matthew Berman, Eric Schmidt · Forward FutureMatthew Berman highlights Eric Schmidt's congressional testimony and asks about AI's power demand. The dramatic 99% figure lacks a specified time frame and geographic scope in the quoted testimony.
 0:34ENMatthew Berman· 1. Mai 2025DeepSeek-Prover-V2 and Its Formal Math ResultsMatthew Berman · Forward FutureMatthew Berman highlights DeepSeek’s reported theorem-proving results on miniF2F, PutnamBench and formalized AIME problems.
 1:00ENMatthew Berman· 1. Mai 2025A Vision of AI Agents Taking On Business LogicMatthew Berman · Forward FutureMatthew Berman explains a prediction that agents could turn natural-language requests into actions on business data.
 0:49ENMatthew Berman· 1. Mai 2025Copilot in Excel and the Idea of Agent-Driven AnalysisSatya Nadella, Matthew Berman · MicrosoftMatthew Berman reacts to a short clip of Microsoft CEO Satya Nadella discussing Copilot as a data-analysis aid.
 33:18ENMatthew Berman· 1. Mai 2025Zuckerberg and Nadella on AI Coding, Agents and the Next Software StackMatthew Berman, Mark Zuckerberg, Satya Nadella · Forward FutureMatthew Berman examines their 2025 LlamaCon conversation about AI-assisted development, open models and changing workflows.
 27:20ENMatthew Berman· 29. Apr. 2025Dario Amodei’s Case for Urgent AI Interpretability ResearchMatthew Berman · Forward FutureMatthew Berman examines Anthropic’s interpretability work, experimental safety findings and the debate over how quickly understanding can advance.
 14:04ENMatthew Berman· 29. Apr. 2025Qwen3: Open Weights, Adjustable Reasoning and Tool UseMatthew Berman · Forward FutureMatthew Berman reviews the April 2025 Qwen3 family, its benchmark claims, training pipeline and local demonstration.
 19:06ENMatthew Berman· 25. Apr. 2025Sleep-Time Compute: Preparing AI Context Before a QuestionMatthew Berman · Forward FutureMatthew Berman reviews a 2025 paper on moving some reasoning ahead of a user query, and explains where its experiments found benefits and limits.
 26:35ENMatthew Berman· 23. Apr. 2025Testing Gemini 2.5 Flash on Coding and Video UnderstandingMatthew Berman · Forward FutureMatthew Berman compares Google’s faster model with Gemini 2.5 Pro through interactive simulations, games and questions about a long video.
 15:15ENMatthew Berman· 19. Apr. 2025Early Reactions to OpenAI o3 and o4-mini: Tool Use, Math and MistakesMatthew Berman · Forward FutureMatthew Berman reviews 2025 demos and benchmark reports, from location guessing and coding to simple failures that challenge the hype.
 15:45ENMatthew Berman· 18. Apr. 2025AI News: Gemini 2.5 Flash, OpenAI Models, Claude Research and Kling 2.0Matthew Berman · Forward FutureMatthew Berman reviews a week of 2025 model releases, research tools and agent announcements, including historical price and benchmark comparisons.
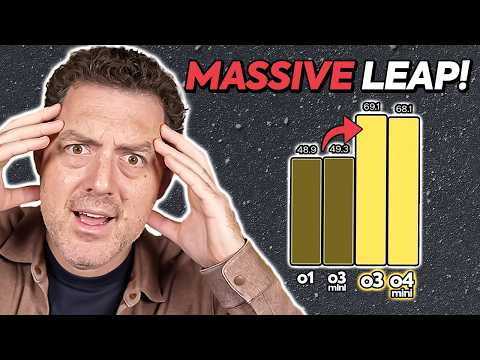 15:46ENMatthew Berman· 16. Apr. 2025OpenAI o3 and o4-mini: Tool Use, Benchmarks and the First Codex CLIMatthew Berman · Forward FutureMatthew Berman reviews OpenAI’s April 2025 reasoning-model release, a scientific image-analysis demonstration and the debut of its terminal coding agent.
 21:16ENMatthew Berman· 14. Apr. 2025GPT-4.1, Mini and Nano: Coding, Long Context and 2025 API PricingMatthew Berman · Forward FutureMatthew Berman reviews OpenAI’s April 2025 model launch, selected coding benchmarks and demonstrations, and a sponsored Box evaluation.
 18:23ENMatthew Berman· 7. Apr. 2025Llama 4 Reactions: Benchmarks, Long Context and Early TestsMatthew Berman · Forward FutureMatthew Berman reviews early industry reactions to Meta's Llama 4 release, from benchmark and price comparisons to long-context claims and local inference.
 7:33ENMatthew Berman· 4. Apr. 2025Ace Computer-Use Agent: Fast Desktop and Browser DemonstrationsMatthew Berman · Forward FutureMatthew Berman reviews General Agents’ examples and reported click accuracy and latency, while noting he has not yet tested Ace himself.
 23:50ENMatthew Berman· 3. Apr. 2025PaperBench: How AI Agents Attempt to Replicate Machine-Learning ResearchMatthew Berman · Forward FutureMatthew Berman examines OpenAI’s research-replication benchmark, its partial-credit scoring and the prospect of faster AI research.
 16:02ENMatthew Berman· 1. Apr. 2025Runway Gen-4 Examples: Cinematic Motion, Style and Visible ErrorsMatthew Berman · Forward FutureMatthew Berman reviews early generated clips, praising their visual detail while identifying awkward interactions and inconsistent physics.
 26:05ENMatthew Berman· 31. März 2025Inside Claude: What Interpretability Research Reveals—and What It Cannot Yet ExplainMatthew Berman · Forward FutureMatthew Berman examines Anthropic’s case studies on multilingual features, planning, arithmetic, hallucinations and safety.
 11:31ENMatthew Berman· 29. März 2025AI News in March 2025: GPT-4o, Gemini, DeepSeek and MCPMatthew Berman · Forward FutureMatthew Berman reviews model updates, the ARC-AGI-2 benchmark, image generators and early adoption of Model Context Protocol.
 17:03ENMatthew Berman· 28. März 2025Matthew Berman Explores GPT-4o Image Generation and Its LimitsMatthew Berman · Forward FutureFrom animated trailer remakes to infographics and interface mockups, early examples show creative possibilities alongside persistent errors.
 1:14ENMatthew Berman· 27. März 2025NVIDIA NIM Microservices Bring Packaged AI Models to RTX PCsMatthew Berman · Forward FutureIn an NVIDIA-sponsored short, Matthew Berman introduces local AI microservices, compatible applications and the planned PDF-to-podcast workflow.
 18:31ENMatthew Berman· 26. März 2025Gemini 2.5 Pro Experimental: Coding Demos and Launch BenchmarksMatthew Berman · Forward FutureIn March 2025, Matthew Berman tests Google’s experimental model on interactive simulations and reviews its launch benchmarks, including their limits.
Mehr laden24 von 899 angezeigt